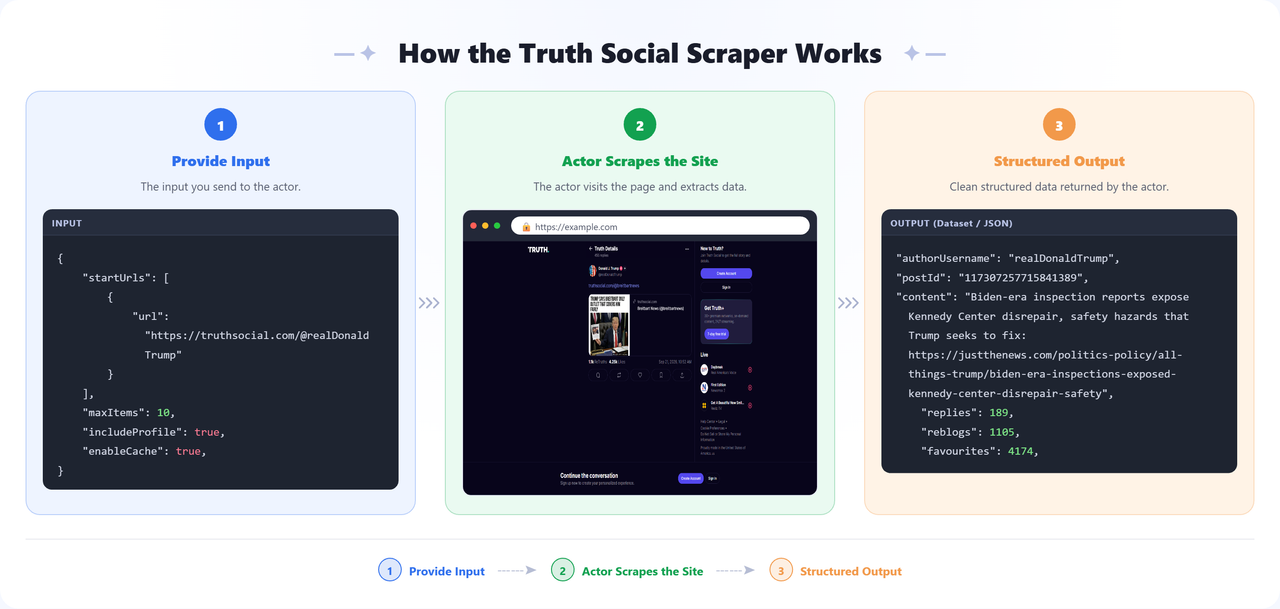
 ### Features
- **Post extraction** - text, replies, re-Truths, favourites, timestamp, language, media attachments, hashtags, and mentions
- **Author profile fields on every post** - display name, bio, follower and following counts, total posts, and verified status, flattened onto each post row
- **Flexible input** - profile URLs, bare handles (`realDonaldTrump`, `@realDonaldTrump`), or single post URLs
- **Pagination support** - walks back through an account's timeline until Max Items is reached
- **Replies filter** - replies to other accounts are excluded by default, so you get the account's own posts
- **Per-project caching** - set a project name and the Actor remembers what it already returned for that project, skipping it next time. Each project keeps its own history, so different projects never interfere.
- **Cloudflare-resilient** - loads through a real Firefox browser to get past Truth Social's bot protection, so it keeps working where plain HTTP requests get blocked
- **No proxy needed** - the Actor works without a proxy; enable one for large runs
- **Both plain text and HTML** - `content` is readable text, `contentHtml` keeps the original markup
### Input Configuration
| Field | Type | Required | Default | Description |
|-------|------|----------|---------|-------------|
| Profiles or posts | array | Yes | `https://truthsocial.com/@realDonaldTrump` | Truth Social profile URLs, bare handles, or single post URLs. Any other URL is discarded. |
| Max posts per profile | integer | - | 20 | Maximum posts to scrape for each profile. A single post URL always returns exactly one item. |
| Include replies | boolean | - | false | Include posts that are replies to other accounts. |
| Project name (enables caching) | string | - | — | Set a project name to enable cross-run caching, for example "social". The Actor remembers the posts it returned under that project and skips them in later runs of the same project. Each project keeps its own separate history, so using a different name starts fresh. Leave empty to scrape everything every time. |
| Proxy configuration | object | - | No proxy | Proxy settings used for all requests. |
### Output
The dataset has a single **Posts** view. Every row is a post, with the author's profile fields (bio, avatar, follower/following counts, verified status, etc.) flattened onto it, so there's one consistent record shape across the whole dataset.
**Sample output:**
```json
[
{
"itemType": "post",
"postId": "117243065120671432",
"url": "https://truthsocial.com/@realDonaldTrump/posts/117243065120671432",
"content": "RT @realDonaldTrump The Failing New York Times...",
"contentHtml": "
RT ...
", "createdAt": "2026-09-09T20:53:19.718Z", "replies": 1467, "reblogs": 3359, "favourites": 11515, "language": "en", "isReply": false, "inReplyToId": null, "isReblog": false, "authorAccountId": "107780257626128497", "authorUsername": "realDonaldTrump", "authorDisplayName": "Donald J. Trump", "authorBio": "45th & 47th President of the United States", "authorProfileUrl": "https://truthsocial.com/@realDonaldTrump", "authorAvatarUrl": "https://static-assets-1.truthsocial.com/.../avatar.jpg", "authorFollowers": 13043723, "authorFollowing": 82, "authorPostsCount": 36524, "authorVerified": true, "authorCreatedAt": "2022-02-11T18:04:34.552Z", "hashtags": [], "mentions": ["realDonaldTrump"], "media": [ { "type": "video", "url": "https://static-assets-1.truthsocial.com/.../video.mp4", "previewUrl": "https://.../preview.jpg", "description": null } ], "cardUrl": null, "cardTitle": null, "scrapedAt": "2026-09-10T13:33:02.204Z" } ] ``` ### Uses of This Data - Track posting activity and engagement for public figures and organisations - Monitor a set of accounts for new posts on a schedule, returning only what is new - Build datasets for media monitoring, political research, and academic study - Analyse hashtag and mention networks across accounts - Archive an account's public post history with full engagement metrics ### How to Use This Truth Social Scraper 1. [Sign up](https://apify.com/sign-up) for a free Apify account - includes **$5 monthly credit**. 2. Open the Actor page and click **Try for free**. 3. Enter a handle, profile URL, or post URL. 4. Click **Start** and wait for the run to complete. 5. Download results from the **Output** tab in JSON, CSV, or Excel format. You can also run this actor via the [Apify API](https://docs.apify.com/api/v2) or integrate it directly into your workflows using [Zapier](https://zapier.com/apps/apify), [Make](https://www.make.com/), or [n8n](https://n8n.io/). ### Limitations & Known Issues - **Public accounts only** - private or suspended accounts are not accessible. - **Media-only posts have empty text** - a post that is just an image or video genuinely carries no text, so `content` is `null` for those. The media URLs are still returned in the `media` array. - **Engagement counts are a snapshot** - counts are read at scrape time and keep changing afterwards. - **Search is not available** - the platform requires a logged-in account for keyword search, so this Actor works from handles and URLs rather than search terms. ### Notes - **No proxy required** - the Actor runs fine without one. For high-volume runs, enable the Apify Proxy to spread requests across IPs. - **API integration** - This actor can be called as an API from any automation platform (Zapier, Make, n8n, custom scripts). - **Both text formats are returned** - use `content` for analysis and `contentHtml` when you need the original links and formatting. ### 🔗 Other Actors from Parsedom Inc | Category | Actor | What it does | |----------|-------|--------------| | 📸 Social Media | [Instagram Reels Audio Scraper](https://apify.com/kinaesthetic_millionaire/instagram-reels-audio-scraper) | Extracts detailed data from Instagram Reels that use a given audio track. | | 💼 Company Data & Leads | [LinkedIn Company Detail And Email Scraper](https://apify.com/kinaesthetic_millionaire/linkedin-company-detail-email-scraper) | Scrapes LinkedIn company profiles by name or URL and finds business emails, industry, size, and headquarters. | | 🏢 Company Data & Leads | [Kununu Company and Leads Scraper](https://apify.com/kinaesthetic_millionaire/kununu-company-and-leads-scraper) | Scrapes company profile data from kununu.com, including ratings, industry, headquarters location, and recommendation rate. | | 🟢 Monitoring | [Website Uptime Checker](https://apify.com/kinaesthetic_millionaire/website-uptime-checker) | Monitors websites and APIs for availability, response time, SSL certificate expiry, and expected content, sending email or webhook alerts when something goes wrong. | | 📈 SEO | [Ahref Website Authority Checker](https://apify.com/kinaesthetic_millionaire/ahref-website-authority-checker) | Extracts website authority metrics from Ahrefs including Domain Rating (DR), backlinks, and referring domains - useful for competitor analysis and link building. | | 💇 Lead Generation | [Booksy Leads Scraper](https://apify.com/kinaesthetic_millionaire/booksy-leads-scraper) | Extracts business profiles from Booksy including names, addresses, phone numbers, emails, social media, and ratings. Built for beauty and wellness lead generation. | | 🎬 Facebook | [Facebook Reels Scraper and Video Downloader](https://apify.com/kinaesthetic_millionaire/facebook-reels-scraper) | Scrapes reels from public Facebook pages, including captions, views, reactions, and optionally downloads the video. | ### FAQ **Is this Truth Social scraper legal to use?** Yes. It only reads publicly available profile and post data, the same information anyone can see without logging in. No login credentials are used and no private or protected content is accessed. Always check the target platform's terms of service and applicable laws before scraping. **Do I need a Truth Social account or API key to use this Actor?** No. The Actor calls Truth Social's public data endpoints directly and does not require an account, login, or API key. **Can I scrape a single post instead of a whole profile?** Yes. Paste a post URL (e.g. `https://truthsocial.com/@realDonaldTrump/posts/123456789`) into the same input field used for profile URLs and handles - the Actor detects it automatically and returns exactly one item. **Can I scrape private or suspended accounts?** No. Only public accounts are accessible. Private or suspended accounts return no data. **How many posts can I scrape per account?** Set the **Max posts per profile** input to any number you need. The Actor paginates through the account's timeline until that limit is reached or there are no more posts. **How do I avoid scraping the same posts twice across multiple runs?** Set a **Project name** in the input. The Actor remembers which posts it already returned for that project and skips them on the next run, so scheduled runs only return new posts. **What format is the output in?** JSON by default, with one-click export to CSV, Excel, HTML table, or XML from the Apify platform's **Output** tab. ### Support & Contact If extraction quality drops or you want a custom apify actor then you can: - Email us at