# China Hot Search 热搜榜 · Weibo, Baidu, Douyin, Zhihu Trends (`memo23/china-hot-search-scraper`) Actor
Real-time Chinese hot search lists in one dataset: Weibo 微博热搜, Baidu 百度热搜, Douyin 抖音热榜, Kuaishou, Zhihu, Toutiao, Bilibili, Tieba, Tencent, Sina and 16 more, with rank, heat and link. Groups the same story across platforms; keyword filter and new-only mode for alerts. No login.
- **URL**: https://apify.com/memo23/china-hot-search-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Stats:** 2 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $0.30 / 1,000 hot topics
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## China Hot Search 热搜榜: Weibo, Baidu, Douyin, Zhihu Trends in One Dataset
Read what China is talking about right now. This Actor reads 26 Chinese hot lists in one run (Weibo 微博热搜, Baidu 百度热搜, Douyin 抖音热榜, Kuaishou 快手, Zhihu 知乎, Toutiao 今日头条, Bilibili, Tieba, Tencent News, Sina and more) and returns one row per topic with rank, heat, label, link and an English translation of the title. Topics that tell the same story on several platforms are matched, so you can see at a glance which stories the whole country is following. No login, no cookies, no proxy to set up.
### Why use it
- **One run, every list.** All 26 lists in about 20 seconds, with the same columns for each, so one spreadsheet covers Weibo, Douyin and Baidu side by side.
- **The same story across platforms.** Each topic carries `platformsCount` and `alsoOn`. A story that is on Weibo, Douyin, Baidu and Toutiao at once is a national story; one that is only on Bilibili is a niche one.
- **English titles.** `titleEn` holds a machine translation of every title, so you can read the lists without knowing Chinese.
- **Alerts without repeats.** Turn on "Return only topics not seen before" and schedule the Actor hourly: each run returns only what is new since the last.
- **Keyword watch.** Keep only topics that mention your brand, product or competitor (华为, 小米, Tesla, 比亚迪…).
### Hot lists
| List | `platforms` value | Typical size |
|------|-------------------|--------------|
| Weibo hot search 微博热搜 | `weibo` | 50 |
| Baidu hot search 百度热搜 | `baidu` | 50 |
| Douyin hot list 抖音热榜 | `douyin` | 50 |
| Kuaishou hot list 快手热榜 | `kuaishou` | 50 |
| Zhihu hot list 知乎热榜 | `zhihu` | 30 |
| Toutiao hot board 今日头条热榜 | `toutiao` | 50 |
| Bilibili hot search B站热搜 | `bilibili` | 50 |
| Bilibili popular videos B站热门 | `bilibili_popular` | 50 |
| Baidu Tieba topics 贴吧热议 | `tieba` | 30 |
| 360 Search hot list 360热搜 | `so360` | 50 |
| The Paper hot news 澎湃热榜 | `thepaper` | 20 |
| Tencent News hot list 腾讯新闻 | `tencent` | 50 |
| NetEase News hot 网易新闻 | `netease` | 100 |
| Sina hot search 新浪热榜 | `sina` | 45 |
| Wallstreetcn 华尔街见闻 | `wallstreetcn` | 10 |
| Juejin 稀土掘金 (developer articles) | `juejin` | 50 |
| Sspai 少数派 (tech and apps) | `sspai` | 40 |
| AcFun daily ranking A站日榜 | `acfun` | 30 |
| WeChat Read rising books 微信读书飙升榜 | `weread` | 20 |
| Douban trending movies 豆瓣实时热门电影 | `douban_movie` | 10 |
| Baidu novels 百度小说榜 | `baidu_novel` | 30 |
| Baidu movies 百度电影榜 | `baidu_movie` | 10 |
| Baidu TV series 百度电视剧榜 | `baidu_tv` | 10 |
| Baidu cars 百度汽车榜 | `baidu_car` | 30 |
| Baidu games 百度游戏榜 | `baidu_game` | 30 |
| V2EX hot topics | `v2ex` | 10 |
The default is the 12 main social and news lists: Weibo, Baidu, Douyin, Kuaishou, Zhihu, Toutiao, Bilibili, Tieba, 360, The Paper, Tencent and Sina.
### Use cases
- **Brand and crisis monitoring:** an hourly run with your brand names as keywords tells you when you reach a Chinese hot list, and on how many platforms.
- **China market research:** a daily archive of what Chinese consumers search for and discuss, by platform.
- **Newsrooms and analysts:** stories ranked by how many platforms carry them, with English titles.
- **Content and marketing teams:** see which topics are rising on Douyin, Kuaishou and Bilibili before planning posts.
- **Entertainment and media:** Baidu's novel, movie, TV and game boards plus Douban's trending movies and WeChat Read's rising books.
### How it works
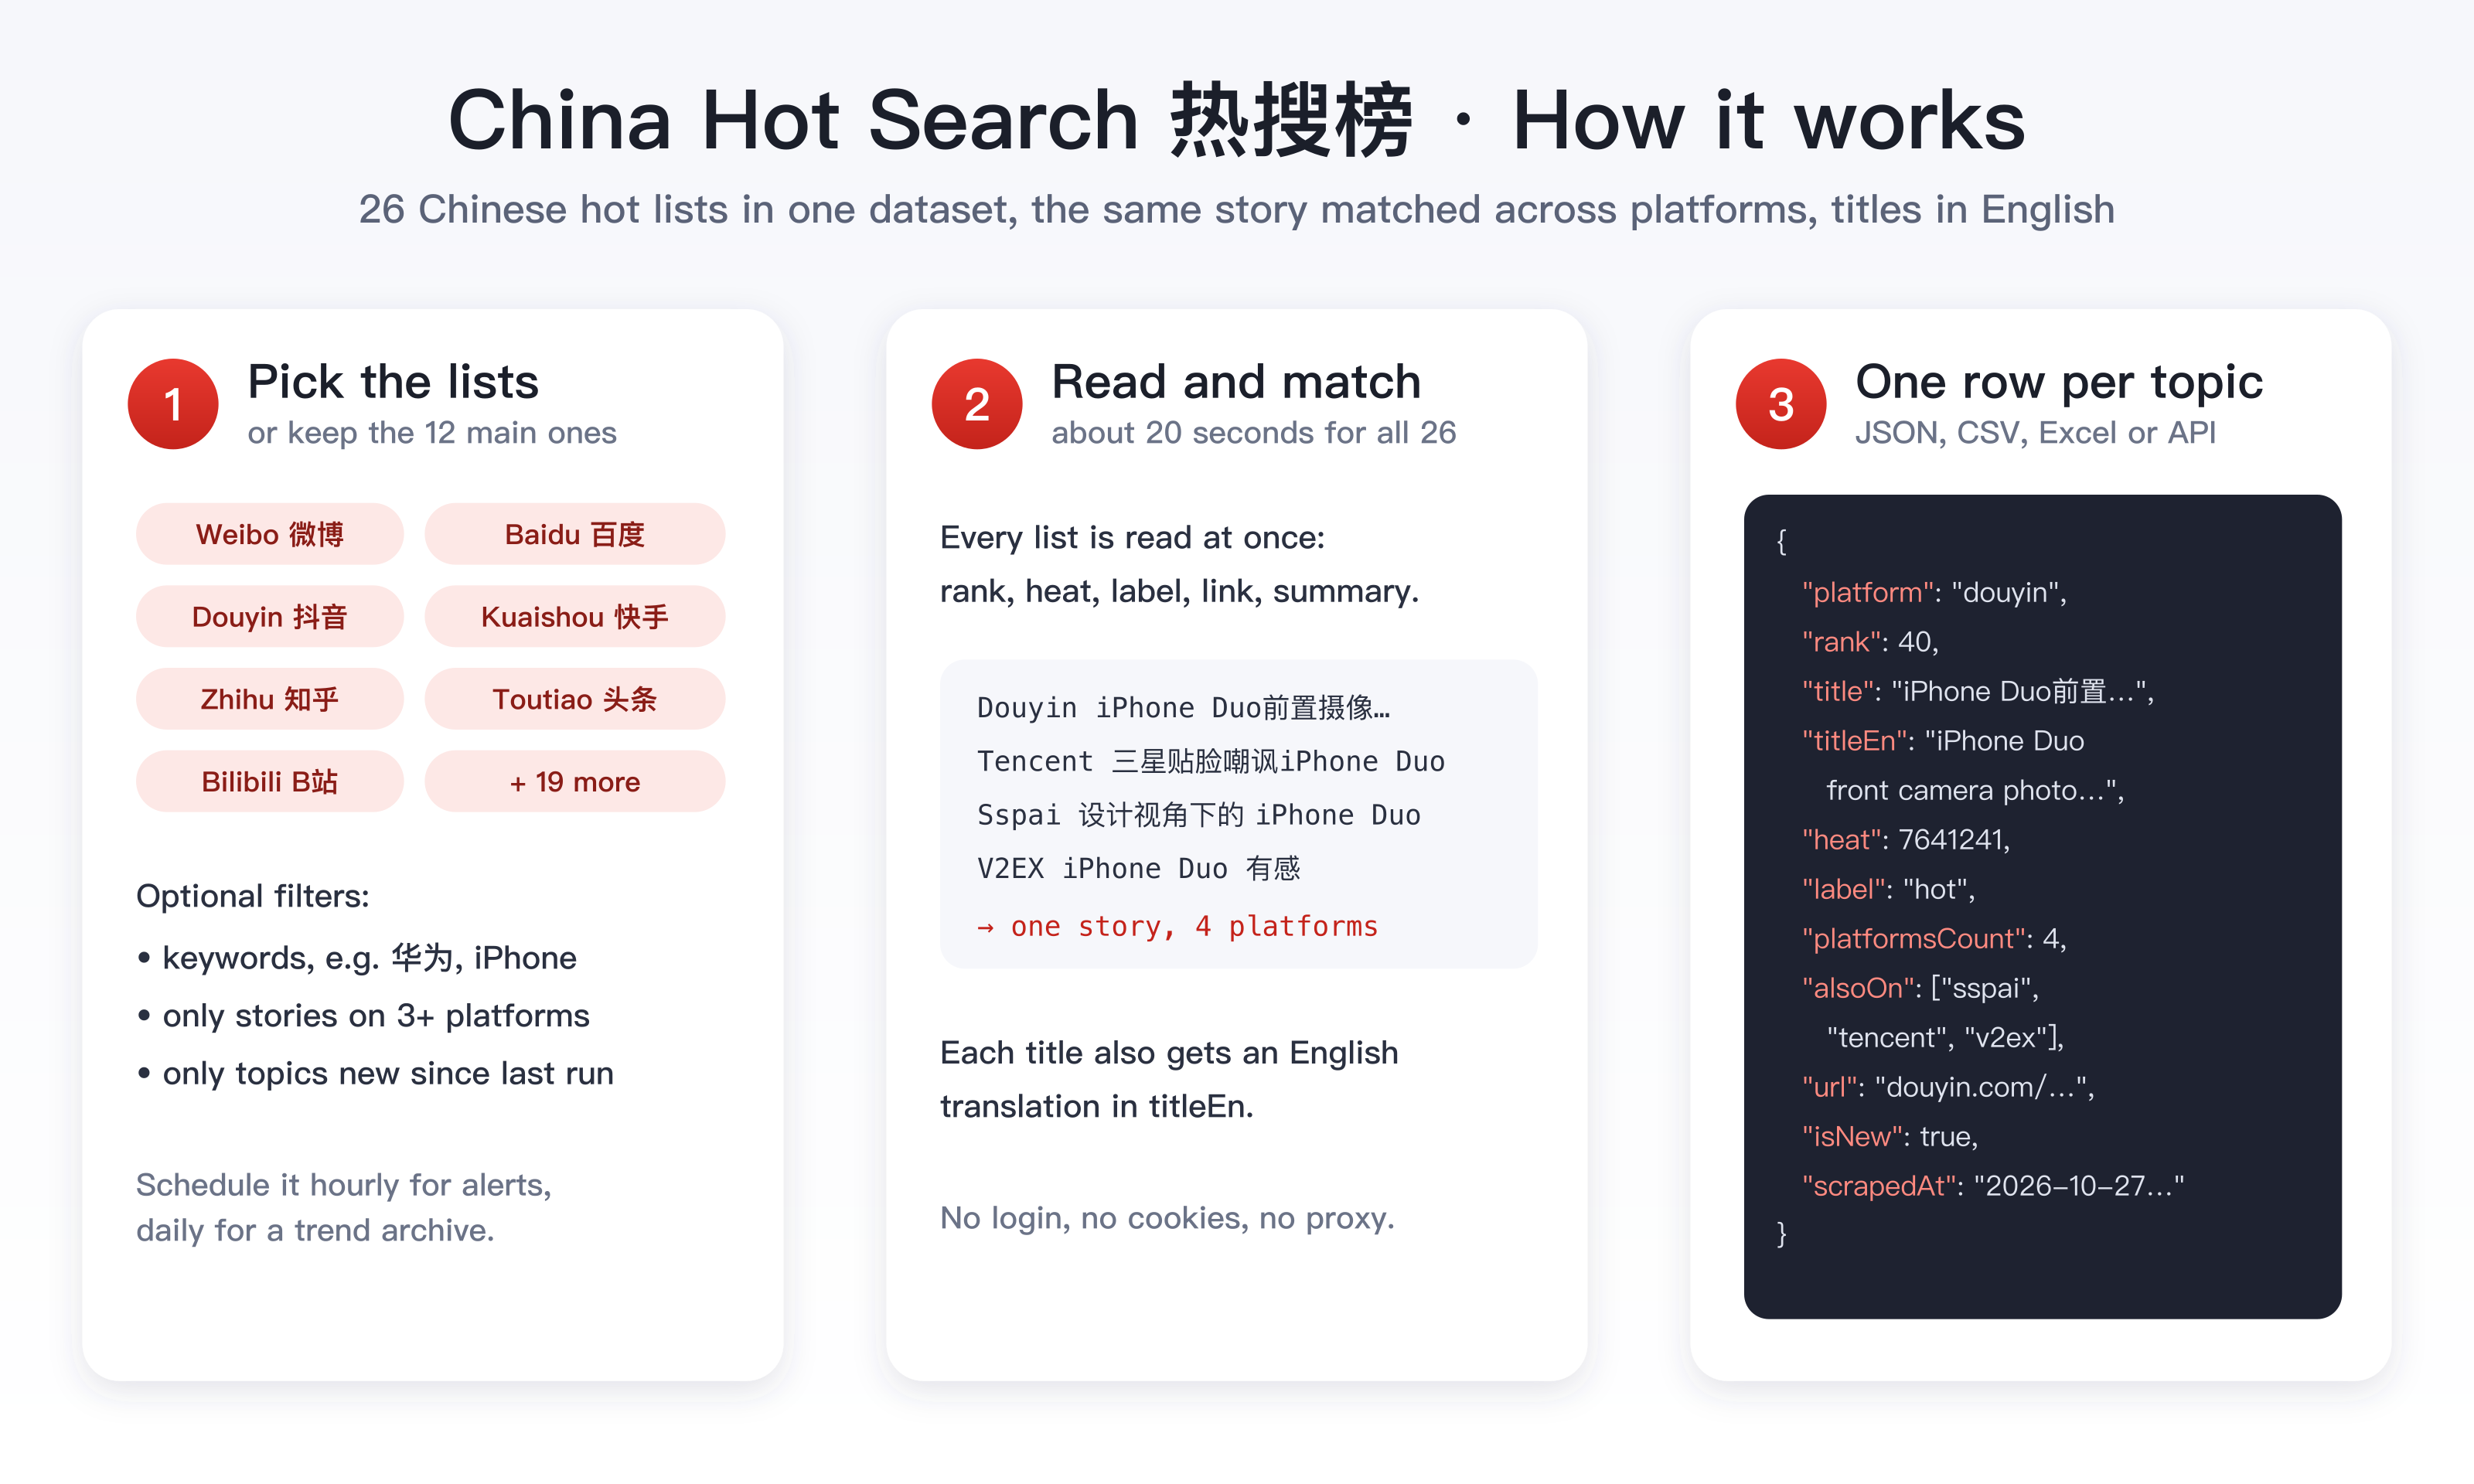
1. Pick the lists, or keep the default 12.
2. The Actor reads every list at once and matches topics that tell the same story on different platforms.
3. You get one row per topic, in list order, with an English title.
### Input
| Field | Type | Description |
|-------|------|-------------|
| `platforms` | `string[]` | Lists to read, from the table above. Default: the 12 main lists. |
| `maxTopicsPerPlatform` | integer | Most topics to keep from each list, counted from the top. Default 50, up to 100. |
| `keywords` | `string[]` | Keep only topics whose title or summary contains one of these words. |
| `minPlatforms` | integer | Keep only topics whose story is on at least this many of the lists read. Default 1 (everything). |
| `translateTitles` | boolean | Add `titleEn`, an English machine translation of each title. Default on. |
| `skipSeenTopics` | boolean | Return only topics that an earlier run with the same history name has not returned. |
| `historyHours` | integer | How long a returned topic counts as seen. Default 24. |
| `historyName` | string | Runs with the same name share one history. Default `default`. |
#### Example: stories on at least three platforms
```json
{
"platforms": ["weibo", "baidu", "douyin", "kuaishou", "zhihu", "toutiao", "bilibili", "tencent"],
"minPlatforms": 3
}
```
#### Example: hourly brand alert
```json
{
"keywords": ["华为", "Huawei", "鸿蒙"],
"skipSeenTopics": true,
"historyName": "huawei-watch"
}
```
### Output
One row per topic. Lists that do not carry a field leave it `null`, so every row has the same columns.
```json
{
"platform": "douyin",
"platformName": "Douyin hot list 抖音热榜",
"board": "hot",
"rank": 40,
"title": "iPhone Duo前置摄像拍照效果",
"titleEn": "iPhone Duo front camera photo effects",
"isPinned": false,
"heat": 7641241,
"heatText": "7641241",
"label": "hot",
"summary": null,
"category": null,
"url": "https://www.douyin.com/search/iPhone%20Duo%E5%89%8D%E7%BD%AE%E6%91%84%E5%83%8F%E6%8B%8D%E7%85%A7%E6%95%88%E6%9E%9C",
"publishedAt": "2026-10-27T06:02:52.000Z",
"stats": { "videos": 1 },
"author": null,
"storyGroup": 137,
"platformsCount": 4,
"alsoOn": ["sspai", "tencent", "v2ex"],
"firstSeenAt": "2026-10-27T22:16:03.028Z",
"isNew": true,
"scrapedAt": "2026-10-27T22:16:03.028Z"
}
```
A video list row (Bilibili popular) carries the video's counts in `stats`:
```json
{
"platform": "bilibili_popular",
"rank": 1,
"heat": 602506,
"url": "https://www.bilibili.com/video/BV1mdxN68E7F",
"stats": { "views": 602506, "likes": 138302, "coins": 46031, "favorites": 16055, "comments": 3707, "danmaku": 2877, "shares": 3517 },
"author": "温柔JUNZ",
"publishedAt": "2026-10-27T09:00:00.000Z"
}
```
### Key output fields
| Field | Meaning |
|-------|---------|
| `platform` / `platformName` | The list the topic came from. |
| `rank` | Position on the list. `0` with `isPinned: true` is the entry pinned above the ranking. |
| `title` / `titleEn` | The topic as the platform shows it, and its English translation. |
| `heat` / `heatText` | The platform's own heat score as a number, and as shown (e.g. `2339 万热度`). Scores are not comparable between platforms. |
| `label` | The platform's badge: `hot`, `new`, `boiling`, `first`… |
| `summary` | The short description, when the list has one (Baidu, Zhihu, Tieba, 360, Tencent). |
| `url` | The topic's page, or the platform's search for it. |
| `stats` | List-specific counts: views, likes, answers, readers, rating… |
| `storyGroup` | Rows with the same number tell the same story. |
| `platformsCount` / `alsoOn` | How many platforms in this run carry the story, and which others. |
| `firstSeenAt` / `isNew` | When the topic was first returned under this history name. |
### Pricing
Pay per event. You pay only for topics returned.
| Event | When | Price |
|-------|------|-------|
| Actor start | Once per run | $0.001 |
| Hot topic | Each topic returned | $0.0003 |
All 12 default lists (about 525 topics) cost about $0.16. Topics left out by keywords, `minPlatforms` or `skipSeenTopics` are not charged, and a list that cannot be read costs nothing. Free-plan runs return up to 20 topics per list.
### FAQ
**Do I need accounts, cookies or a proxy?**
No. The Actor reads the lists the way a visitor's browser does.
**How often do the lists change?**
Weibo, Baidu, Douyin and Toutiao update every few minutes; Zhihu and Bilibili every 10 to 30 minutes. An hourly schedule catches nearly every topic that reaches a list.
**How does the story matching work?**
Titles from different platforms are compared word by word after removing punctuation and hashtags. Titles that share most of their wording, such as "外交部回应姆巴佩发表不当言论" and "外交部回应姆巴佩涉华不当言论", get the same `storyGroup`. Two topics from the same list are never grouped.
**How good is the English translation?**
It is a machine translation, good enough to follow the news. Names of people, products and car models are sometimes translated literally.
**Why does a list return fewer than 50 topics?**
Some lists are short by design: The Paper shows 20, Douban 10, Wallstreetcn 10.
**What happens if one site is down?**
The run continues with the other lists and the status message names the list that could not be read. The run fails only when no list could be read.
**Can I get the posts or videos behind a topic?**
Use the topic `url`, or pass the `title` as a keyword to our Weibo, Douyin, Kuaishou, Zhihu or Bilibili scrapers.
### Support
Found a problem or need another list? Open an issue on the Actor's Issues tab and include the run ID.
### Explore more scrapers
- [Douyin Trends 抖音热点榜](https://apify.com/memo23/douyin-trends-scraper): Douyin's video, topic, search and account rankings with history.
- [Weibo Scraper](https://apify.com/memo23/weibo-scraper): posts, comments and profiles.
- [Zhihu Scraper](https://apify.com/memo23/zhihu-scraper): questions, answers and comments.
- [Kuaishou Scraper](https://apify.com/memo23/kuaishou-scraper): videos, comments, creators and rankings.
### 🤖 For AI Agents & LLM Apps
**Purpose:** Chinese hot search lists from 26 platforms as structured JSON, with English titles and cross-platform story matching.
**Minimal input:** `{}` (reads the 12 main lists) or `{"platforms": ["weibo", "douyin"], "maxTopicsPerPlatform": 20}`.
**Output:** one row per topic with `platform`, `rank`, `title`, `titleEn`, `heat`, `label`, `url`, `summary`, `stats`, `storyGroup`, `platformsCount`, `alsoOn`, `isNew`, `scrapedAt`.
**Behaviors to know:** `heat` scales differ by platform; compare ranks, not heat, across platforms. `minPlatforms` and `keywords` filter after matching, so `alsoOn` still lists every platform carrying the story. `skipSeenTopics` keeps history in a named key-value store in your account.
### ⚠️ Disclaimer
This Actor collects publicly available hot list data only. It is not affiliated with, endorsed by, or sponsored by Weibo, Baidu, ByteDance, Kuaishou, Zhihu, Bilibili, Tencent, Sina or any other platform listed. Translations are machine-generated. You are responsible for using the data in line with applicable laws and each platform's terms.
### SEO Keywords
china trending topics, china hot search, weibo hot search, 微博热搜, baidu hot search, 百度热搜, douyin hot list, 抖音热榜, zhihu hot list, 知乎热榜, toutiao hot board, 今日头条热榜, kuaishou hot list, bilibili trending, china social media trends, chinese trending news in english, 热搜榜, china trend monitoring, chinese brand monitoring
# Actor input Schema
## `platforms` (type: `array`):
Which hot lists to read. Each list is read once per run, about 10 to 100 topics each. Leave the default for the 12 main social and news lists.
## `maxTopicsPerPlatform` (type: `integer`):
Most topics to keep from each list, counted from the top. Most lists hold 30 to 50. Free-plan runs keep up to 20.
## `keywords` (type: `array`):
Optional. Keep a topic only when its title or summary contains one of these words, in Chinese or English (e.g. 华为, iPhone, 新能源). Leave empty to keep every topic.
## `minPlatforms` (type: `integer`):
Optional. Keep only topics whose story is trending on at least this many of the lists read in this run. 1 keeps everything; 3 or more leaves the stories the whole country is talking about.
## `translateTitles` (type: `boolean`):
Adds titleEn, a machine translation of each topic's title into English. Turn off to keep only the original Chinese titles.
## `skipSeenTopics` (type: `boolean`):
For scheduled runs: leave out topics that an earlier run with the same history name already returned. Each run then gives only what is new since the last one, which suits hourly alerts.
## `historyHours` (type: `integer`):
How long a returned topic counts as seen. After that it can come back if it is still on the list.
## `historyName` (type: `string`):
Runs that share this name share one history. Use a different name for each schedule or task, e.g. 'brand-watch'.
## Actor input object example
```json
{
"platforms": [
"weibo",
"baidu",
"douyin",
"kuaishou",
"zhihu",
"toutiao",
"bilibili",
"tieba",
"so360",
"thepaper",
"tencent",
"sina"
],
"maxTopicsPerPlatform": 50,
"keywords": [],
"minPlatforms": 1,
"translateTitles": true,
"skipSeenTopics": false,
"historyHours": 24,
"historyName": "default"
}
```
# Actor output Schema
## `topics` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"platforms": [
"weibo",
"baidu",
"douyin",
"kuaishou",
"zhihu",
"toutiao",
"bilibili",
"tieba",
"so360",
"thepaper",
"tencent",
"sina"
],
"keywords": []
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/china-hot-search-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"platforms": [
"weibo",
"baidu",
"douyin",
"kuaishou",
"zhihu",
"toutiao",
"bilibili",
"tieba",
"so360",
"thepaper",
"tencent",
"sina",
],
"keywords": [],
}
# Run the Actor and wait for it to finish
run = client.actor("memo23/china-hot-search-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"platforms": [
"weibo",
"baidu",
"douyin",
"kuaishou",
"zhihu",
"toutiao",
"bilibili",
"tieba",
"so360",
"thepaper",
"tencent",
"sina"
],
"keywords": []
}' |
apify call memo23/china-hot-search-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/china-hot-search-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/fJF9YPXq1YTEt6Jkq/builds/YCR3pTP5Qh9QcLnNw/openapi.json