# Dice.fm Events Scraper — Concerts, Tours & Live Music Tickets (`memo23/dice-events-scraper`) Actor
Scrape live music events and concerts from dice.fm — artist lineup, venue, address, coordinates, date, price and ticket links. Works with any browse URL or direct event URL. JSON or CSV out.
- **URL**: https://apify.com/memo23/dice-events-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Social media
- **Stats:** 2 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $10.00 / 1,000 scraped items
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## Dice.fm Events Scraper — Concerts, Tours & Live Music Tickets
Scrape live music events and concerts from **dice.fm** — artist lineup, venue, address, coordinates, date, price, and ticket links for every event. Works with browse pages or direct event URLs. One row per event, clean JSON out.
***
### Why use this scraper
- **Full event detail.** Artist lineup with profile links and images; venue name, address, city, country and lat/lng coordinates; start/end dates; ticket price range and currency; event description.
- **Browse or direct URLs.** Paste a browse URL (`/browse`) to get upcoming events, or individual event URLs (`/event/{id}`) — both are auto-classified.
- **No login, no API key.** Reads the same data the website renders, no credentials needed.
- **Structured output.** Clean schema.org `MusicEvent` JSON-LD parsed into flat rows — ready for spreadsheets, databases, or LLM pipelines.
***
### Overview
Dice.fm is a ticketing platform for live music events and concerts. This actor scrapes browse pages and event pages, returning structured data: who's playing, where, when, what it costs, and where to buy tickets.
Each output row is a single event with the artist lineup (name, profile URL, image), the venue (name, address, geo coordinates), the timing (start/end dates), and ticket offers (price range, currency, availability).
***
### Supported inputs
- **Browse URLs** — list upcoming events:
- `https://dice.fm/browse`
- `https://dice.fm/browse/{city-slug}`
- **Event URLs** — single event:
- `https://dice.fm/event/6aabcf21cab2840001444771`
Leave `startUrls` empty to use the default browse page.
***
### Use cases
- **Concert database** — build a directory of live music events.
- **Venue research** — collect venue names, addresses, and coordinates.
- **Tour tracking** — monitor an artist's upcoming shows.
- **Ticket monitoring** — track ticket prices and availability.
- **Music-industry leads** — event organizers, promoters, and venues for outreach.
***
### How it works
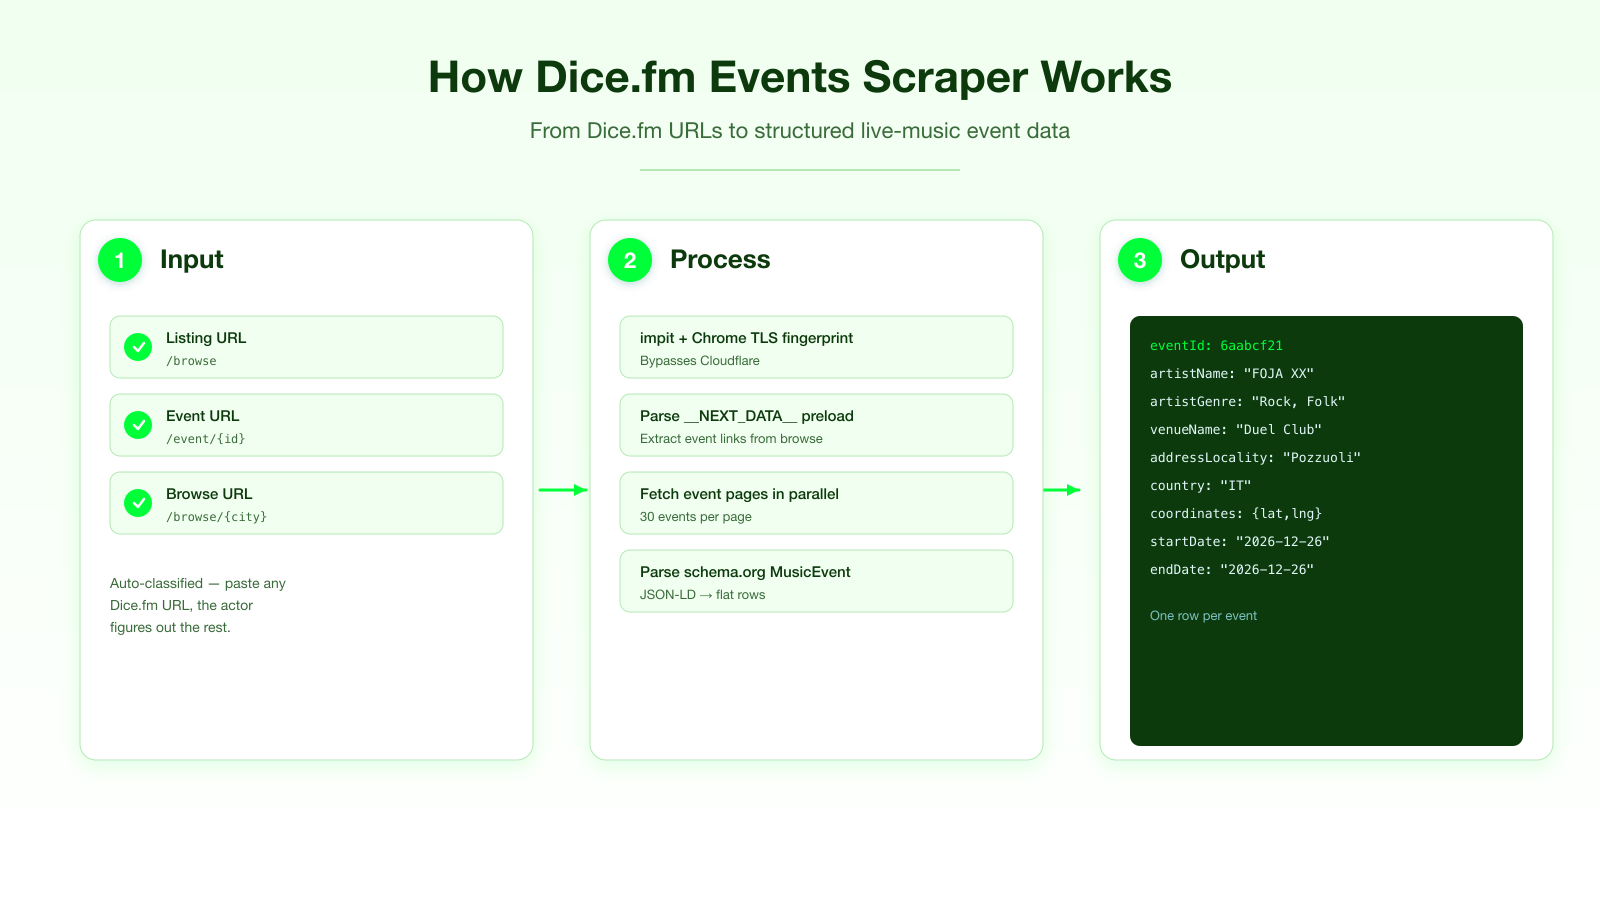
1. You provide a browse URL (or direct event URLs).
2. The actor fetches the browse page and extracts event links from the `__NEXT_DATA__` preload.
3. It fetches each event detail page in parallel and parses the schema.org `MusicEvent` JSON-LD.
4. Each event becomes one clean row in the dataset.
***
### Input
| Field | Type | Default | Notes |
|---|---|---|---|
| `startUrls` | array | `/browse` | Dice.fm URLs to scrape. Browse and event URLs are auto-classified. |
| `maxItems` | integer | 1000 | Maximum events to scrape. |
| `maxConcurrency` | integer | 10 | How many event pages to fetch in parallel. |
| `proxy` | object | Apify proxy | Proxy configuration. |
```json
{
"startUrls": [{ "url": "https://dice.fm/browse" }],
"maxItems": 100
}
```
***
### Output
One row per event:
```json
{
"type": "event",
"eventId": "6aabcf21cab2840001444771",
"eventUrl": "https://dice.fm/event/6aabcf21cab2840001444771",
"title": "FOJA XX - UNICA DATA",
"description": "Dopo due anni di pausa dai concerti, tornano a calcare le scene...",
"artists": [
{
"name": "Foja",
"url": "https://dice.fm/artist/foja-kxy9p",
"image": "https://dice-i-scdn-co.imgix.net/image/..."
}
],
"venueName": "Duel Club",
"venueUrl": "https://dice.fm/venue/duel-club-kegq",
"streetAddress": "Via Antiniana, 2a, 80078 Pozzuoli NA, Italy",
"addressLocality": "Pozzuoli",
"country": "IT",
"coordinates": { "latitude": 40.8280367, "longitude": 14.1555514 },
"startDate": "2026-12-26T21:30:00+01:00",
"endDate": "2026-12-27T01:30:00+01:00",
"lowPrice": 28,
"highPrice": 28,
"priceCurrency": "EUR"
}
```
#### Key output fields
- **`eventId`** — Dice.fm event ID, stable across runs.
- **`artists`** — array of `{ name, url, image }` for each performer.
- **`venueName` / `streetAddress` / `addressLocality` / `country` / `coordinates`** — full venue details.
- **`startDate` / `endDate`** — ISO 8601 date/time.
- **`lowPrice` / `highPrice` / `priceCurrency`** — ticket price range.
- **`description`** — event description/bio.
***
### FAQ
**Do I need a Dice.fm account?**
No. The scraper reads the public website data.
**How many events does a browse page return?**
\~30 events per browse page. For more events, use multiple city-specific browse URLs or pass direct event URLs.
**Why did one event fail?**
Some event pages may not have JSON-LD (e.g. removed events, festivals with a different page structure). The actor logs a warning and skips them.
***
### ⚠️ Disclaimer
This Actor scrapes publicly available event data from dice.fm. It does not access authenticated or private content, and collects no personal data. You are responsible for using the output in line with Dice.fm's terms and any applicable law in your jurisdiction. This Actor is not affiliated with, endorsed by, or sponsored by Dice.fm.
***
### SEO Keywords
dice.fm scraper, dice events scraper, concert scraper, live music events api, dice.fm api, concert data feed, music event scraper, tour dates scraper, venue scraper, live music database, concert listing scraper, dice.fm events export, music industry leads, concert venue data, artist tour scraper, gig scraper, show scraper, music event data, dice.fm data extraction, concert calendar api, live music api, ticket price scraper, concert coordinates, dice.fm csv export
# Actor input Schema
## `startUrls` (type: `array`):
Dice.fm URLs to scrape. Browse URLs (https://dice.fm/browse) list upcoming events; direct event URLs (https://dice.fm/event/{id}) are parsed directly.
## `maxItems` (type: `integer`):
Maximum number of events to scrape.
## `maxConcurrency` (type: `integer`):
How many event detail pages to fetch in parallel.
## `proxy` (type: `object`):
Apify proxy to use.
## Actor input object example
```json
{
"startUrls": [
{
"url": "https://dice.fm/browse"
}
],
"maxItems": 1000,
"maxConcurrency": 10,
"proxy": {
"useApifyProxy": true
}
}
```
# Actor output Schema
## `results` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"startUrls": [
{
"url": "https://dice.fm/browse"
}
]
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/dice-events-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = { "startUrls": [{ "url": "https://dice.fm/browse" }] }
# Run the Actor and wait for it to finish
run = client.actor("memo23/dice-events-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"startUrls": [
{
"url": "https://dice.fm/browse"
}
]
}' |
apify call memo23/dice-events-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/dice-events-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/sy9yDZavaMC4uqvpA/builds/eriXYYPJaFm2yudUH/openapi.json