# Hirist Jobs Scraper — India Tech Jobs, Recruiter & Salary Data (`memo23/hirist-jobs-scraper`) Actor
Scrape tech jobs from hirist.tech — India's IT job board. Get the employer and its own web domain, the named recruiter, salary band, experience range, mandatory vs optional skills, plus apply and view counts. Search by keyword, city and experience across 95 locations. No login, no proxy.
- **URL**: https://apify.com/memo23/hirist-jobs-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Stats:** 1 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $2.00 / 1,000 jobs
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## Hirist Jobs Scraper — India Tech Jobs, Recruiter & Salary Data
Scrape tech job postings from **hirist.tech** (India's IT/tech job board) straight off its own JSON API — no login, no cookies, no proxy, no browser. Search by keyword, city, experience band and freshness, and get back **61 structured fields per job**: employer and its web domain, the named recruiter and their job title, the full skill-tag list split into mandatory vs optional, salary band, experience range, application and view counts, diversity-hiring flags, and the complete job description in both HTML and clean plain text.
### Why Use This Scraper?
- **The recruiter is a real person, not a black box.** Every posting carries `recruiterName` and `recruiterDesignation` — the actual talent-acquisition contact, straight from hirist's own payload.
- **The employer's own domain, on every row.** `companyDomain` / `companyWebsite` come from the posting itself, so you can join to your CRM or run contact enrichment without guessing a domain from a company name.
- **Mandatory vs optional skills, separated.** hirist tags each skill with whether it is required. `mandatorySkills` is the subset that actually gates an application — the field most job feeds flatten away.
- **Real demand signals.** `applyCount` and `viewCount` show how contested a posting is, which is the difference between a job feed and hiring-market intelligence.
- **93 locations, resolved by name.** Type `Bangalore` or `Gurugram`; the actor maps it to hirist's internal id for you. Multi-city postings report the city *you searched for* as the primary `location`.
- **No proxy needed.** hirist's API answers 200 to a direct request, so runs are fast and you are not burning proxy budget.
### Overview
hirist.tech is India's dedicated technology job board — Java, DevOps, data, product, QA and the rest of the IT stack, across ~90 Indian cities plus an overseas tail (Dubai, Singapore, London, Canada, Germany).
This actor talks to hirist's own JSON service rather than parsing HTML, which means the output is structurally stable and there is nothing to break when the site restyles. A single keyword like `java` typically matches several thousand live postings.
Supply one or more keywords, optionally narrow by city, experience band and how recently the job was posted, and the actor pages through the results, de-duplicates, and writes one clean row per job.
### Supported Inputs
| Input type | Pattern | Example |
|---|---|---|
| **Keyword** | any job title, skill or technology | `java`, `devops`, `data engineer` |
| **Location** | hirist's own label, either half of a slash-alias, or the numeric id | `Bangalore`, `Gurugram`, `Remote`, `3` |
| Search URL | `https://www.hirist.tech/search/{keyword}-jobs` | `https://www.hirist.tech/search/python-jobs` |
| Direct job URL | `https://www.hirist.tech/j/{slug}-{id}` | `https://www.hirist.tech/j/digital-harbor-lead-java-developer-spring-boot-1667426` |
### Use Cases
- **Recruitment intelligence** — track which companies are hiring which stacks, at what experience level, and how much competition each posting attracts.
- **Lead generation for staffing firms** — every row carries a named recruiter and the employer's own domain.
- **Salary and skills benchmarking** — `experienceMin`/`experienceMax` paired with `mandatorySkills` across thousands of postings.
- **Candidate-facing job feeds** — daily monitoring runs with `postedWithinDays: 1`, filtered server-side so you don't pay for yesterday's jobs.
- **Market research on India's tech hiring** — which cities, which stacks, which employers, over time.
### How It Works
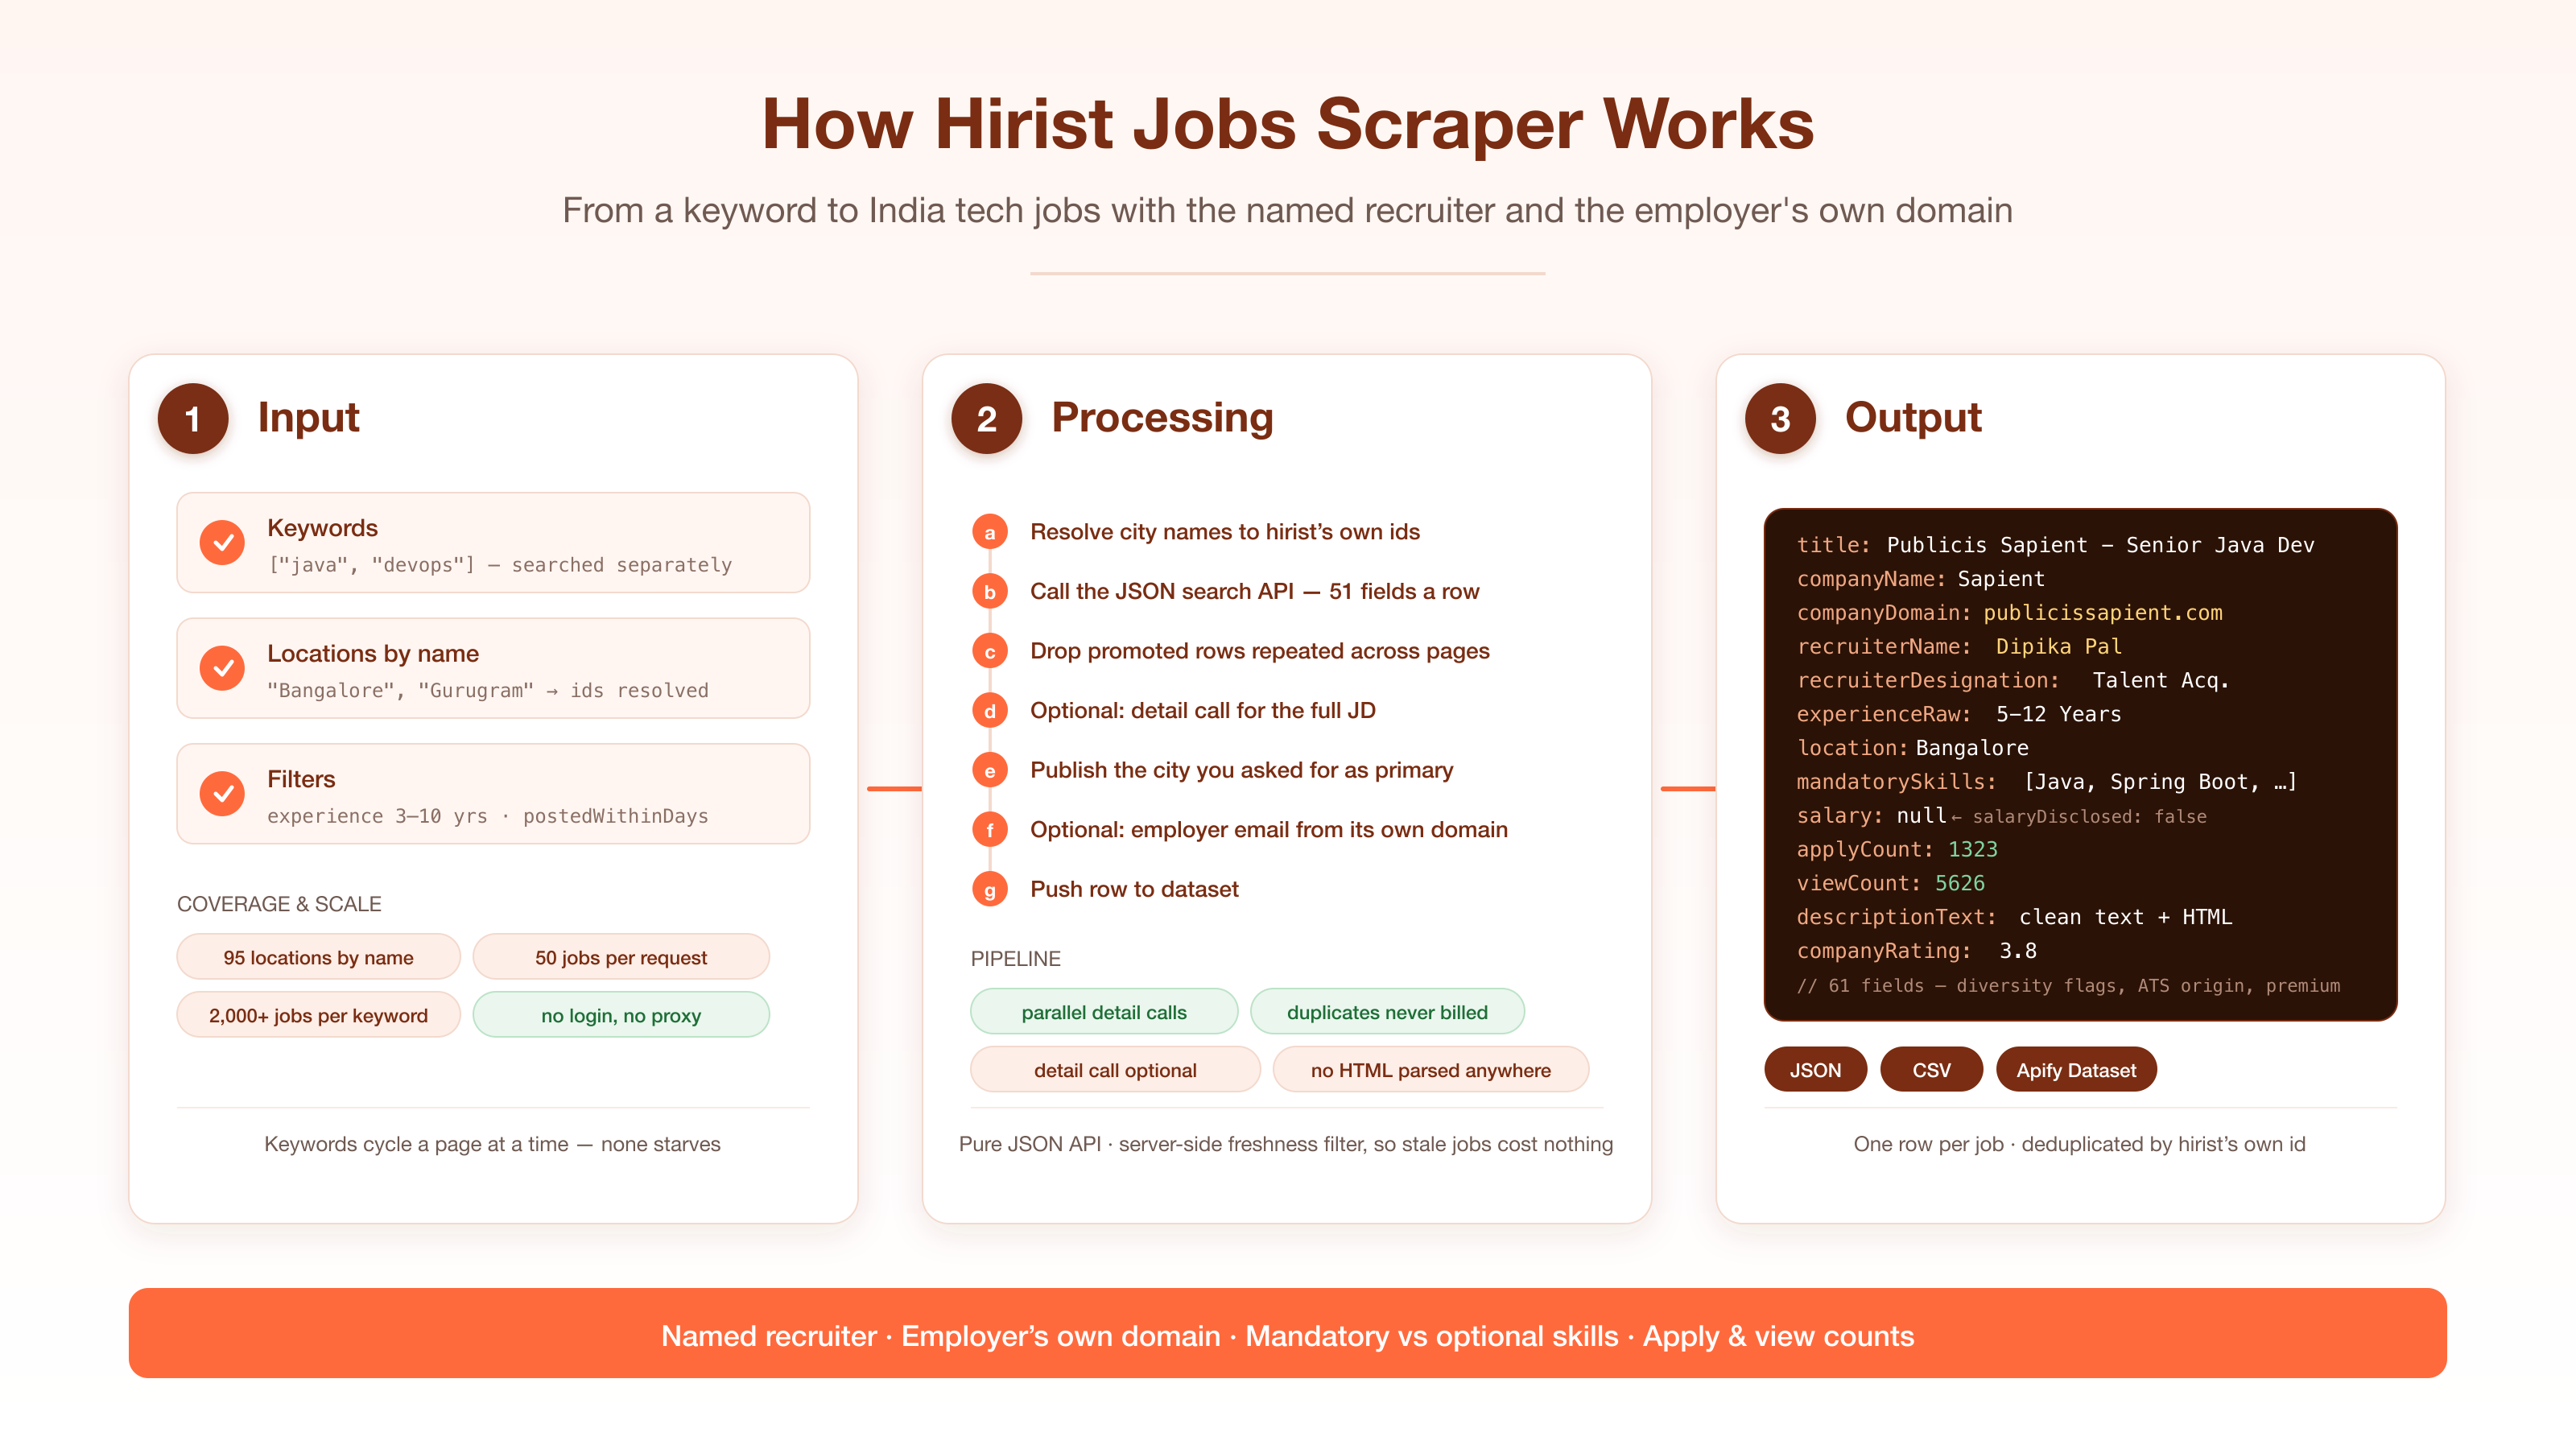
1. **Input** — give keywords (and optionally cities, an experience band, and a freshness window)
2. **Resolve** — city names are mapped to hirist's internal location ids; unknown names are reported rather than silently ignored
3. **Search** — the actor pages `GET /job/search`, cycling between your keywords a page at a time so one broad term can't use up the whole item budget
4. **De-duplicate** — hirist repeats promoted postings across pages, so rows are keyed by job id before anything is fetched or billed
5. **Fetch detail** — optionally calls `GET /job/detail` per job for the full description and application count
6. **Output** — one row per job, as JSON or CSV
### Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
| `searchKeywords` | `string[]` | one of | Job titles, skills or technologies. Each is searched separately and results are interleaved. |
| `locations` | `string[]` | no | City/state/country. Accepts hirist's label, either half of a slash-alias (`Gurugram` for `Gurgaon/Gurugram`), or the numeric id. Several act as OR. |
| `experienceMinYears` / `experienceMaxYears` | `integer` | no | Years. hirist matches on **overlap**, not containment — see the FAQ. |
| `postedWithinDays` | `integer` | no | Server-side freshness. Stale postings are never fetched, so they cost nothing. |
| `startUrls` | `string[]` | one of | hirist search URLs (contribute their keyword) and/or direct job URLs. Crawled in addition to the keywords. |
| `fetchDescriptions` | `boolean` | no | Fetch each job's detail endpoint for `description`, `descriptionText` and `applyCount`. Turn off for a roughly **2× faster run**. Default `true`. Also accepts the portfolio-wide alias `fetchDetails`. |
| `postedWithinHours` | `integer` | no | Stricter client-side recency cut, re-checked on each row's own posted date. |
| `enrichEmails` | `boolean` | no | Experimental. Reads the employer's own site (from `companyDomain`) for a contact email. Billed only when an email is found. Default `false`. |
| `maxItems` | `integer` | no | Hard cap on rows. Default `1000`. Free-tier runs are capped at `100`. |
| `maxConcurrency` | `integer` | no | Parallel detail requests. Default `10`. |
| `proxy` | object | no | **Not needed.** Off by default — hirist answers directly. |
#### Example input
```json
{
"searchKeywords": ["java", "devops"],
"locations": ["Bangalore", "Gurugram"],
"experienceMinYears": 3,
"experienceMaxYears": 10,
"postedWithinDays": 30,
"fetchDescriptions": true,
"maxItems": 1000
}
```
### Output Overview
One row per job posting. 61 fields, all flat except `salary`, `locations`, `skills` and `mandatorySkills`.
#### Output Sample
```json
{
"type": "job",
"source": "hirist",
"jobId": "1667426",
"title": "Digital Harbor - Lead Java Developer - Spring Boot",
"designation": "Lead Java Developer",
"jobUrl": "https://www.hirist.tech/j/digital-harbor-lead-java-developer-spring-boot-1667426",
"companyName": "DIGITAL HARBOR, Inc.",
"companyDomain": "dharbor.com",
"companyWebsite": "https://dharbor.com",
"companyRating": 3.8,
"isConfidential": false,
"recruiterName": "Debjani Roy",
"recruiterDesignation": "Talent Acquisition Specialist",
"location": "Bangalore",
"locations": ["Bangalore"],
"remote": false,
"salary": null,
"salaryDisclosed": false,
"experienceMin": 5,
"experienceMax": 10,
"experienceRaw": "5-10 Years",
"skills": ["Java", "Spring Boot", "Microservices Architecture", "J2EE", "Spring Frameworks", "Javascript"],
"mandatorySkills": ["Java", "Spring Boot", "Microservices Architecture", "Spring Frameworks"],
"postedDate": "2026-09-01T04:41:37.215Z",
"applyCount": 156,
"viewCount": 328,
"isFromAts": false,
"isPremium": true,
"hasExpired": false,
"diversityFemale": false,
"diversityDifferentlyAbled": false,
"diversityExDefence": false,
"diversityWomenReturning": false,
"applyUrl": "https://www.hirist.tech/j/digital-harbor-lead-java-developer-spring-boot-1667426",
"description": "Job Role : Lead Java Developer
…
",
"descriptionText": "Role : Lead Java Developer\n\nInterview Mode : Face to face\n\nJob Location : Bangalore\n\n…",
"scrapedAt": "2026-09-08T20:31:51.830Z"
}
```
### Key Output Fields
| Field | Type | Notes |
|---|---|---|
| `jobId` | string | hirist's own numeric id. Unique across the whole site — safe as a dedup key on its own. |
| `companyDomain` / `companyWebsite` | string | null | The employer's **own** domain, from the posting. `null` on confidential postings. |
| `recruiterName` / `recruiterDesignation` | string | null | The named talent-acquisition contact and their job title. |
| `salary` | object | null | `{ currency, min, max }`. **`null` when undisclosed** — hirist writes `0-0` plus a `hideSal` flag for "not disclosed", and that is deliberately not published as a real ₹0 band. Check `salaryDisclosed` to tell "hidden" from "missing". |
| `experienceMin` / `experienceMax` | number | null | Years. `null` when unspecified — again, hirist's `0–0` marker is not published as a real entry-level band. |
| `skills` / `mandatorySkills` | string\[] | Every tag, and the subset hirist marks as required. |
| `location` / `locations` | string / string\[] | Many postings list several cities. `location` is the one **you searched for** when the job matches it; `locations` is always the full set. |
| `applyCount` / `viewCount` | number | null | How many candidates applied and viewed — a live contest signal. |
| `isFromAts` / `isCrawled` | boolean | Whether hirist ingested the posting from an employer ATS feed or its own crawler rather than it being posted natively. |
| `diversity*` | boolean | hirist's own diversity-hiring flags: women, differently-abled, ex-defence, women returning to work. |
### FAQ
**Do I need a login, cookie or proxy?**
No. hirist's JSON API answers a direct request with nothing but a browser user-agent and a hirist referer. The proxy input exists only for callers who need a specific egress IP.
**Why does an experience filter of 3–10 years return a job advertised as 8–18?**
Because hirist matches on **overlap**, not containment: a posting is returned when its band intersects yours. That is hirist's own behaviour, not a filter bug. Use `experienceMin`/`experienceMax` on the output rows if you need strict containment.
**Why is `salary` null on most rows?**
Because most hirist employers hide it. The API returns `0-0` with `hideSal: 1`, which this actor reports as `salary: null` + `salaryDisclosed: false` rather than inventing a ₹0 band.
**A job I searched for in Bangalore shows other cities too — is that wrong?**
No. hirist tags many postings with several cities and returns them when *any* city matches. The `location` field shows the city you asked for; `locations` lists all of them.
**How do I get only today's jobs?**
Set `postedWithinDays: 1` so hirist filters server-side and you aren't billed for older postings. Add `postedWithinHours: 24` if you want a second, stricter cut.
**Can I search by industry or functional area?**
Not yet as an input. Both come back on every row (`industry`, `functionalArea`, `categoryId`) so you can filter after the run.
**Is the job description HTML or text?**
Both. `description` keeps the original HTML; `descriptionText` is the cleaned plain-text version with paragraph structure preserved.
### Support
Found a bug or need a field that isn't here? Open an issue on the actor's Issues tab.
### Additional Services
Need this data pushed somewhere specific, or a different India job board covered? Get in touch through the Apify Console.
### Explore More Scrapers
Other India job boards in this family: Naukri, Foundit (Monster India), Internshala, CutShort, Instahyre, Shine.
### 🤖 For AI Agents & LLM Apps
This actor is MCP-friendly and returns flat, self-describing rows. For retrieval and embedding pipelines use `descriptionText` rather than `description` — it is already stripped of markup with paragraph structure intact. Deduplicate on `jobId`, which is globally unique on hirist. `mandatorySkills` is the highest-signal field for matching a candidate to a role, and `applyCount` is the best available proxy for how contested a posting is. Note that `salary` is `null` far more often than it is populated; branch on `salaryDisclosed` rather than treating `null` as zero.
### ⚠️ Disclaimer
This actor collects only publicly available job-posting data from hirist.tech. It does not log in, bypass authentication, or access any private or personal candidate data. Use the output in line with hirist's terms of service and applicable data-protection law in your jurisdiction. You are responsible for how you use the scraped data, including any outreach to the recruiters named in it.
### SEO Keywords
hirist scraper, hirist.tech scraper, hirist jobs api, india tech jobs scraper, IT jobs india scraper, java jobs scraper india, devops jobs scraper, bangalore tech jobs scraper, indian job board scraper, tech recruitment data india, naukri alternative scraper, job posting api india, recruiter contact scraper, hiring data india, tech hiring intelligence, software jobs scraper, india developer jobs feed, job listings scraper india, ATS job feed india, tech salary data india
# Actor input Schema
## `searchKeywords` (type: `array`):
Job titles, skills or technologies, one per line — e.g. `java`, `devops`, `data engineer`. hirist matches these against the job title and its skill tags.
## `locations` (type: `array`):
Cities, states or countries to filter on. Several act as OR. hirist tags many postings with **more than one** city; a job is returned when *any* of its cities matches, and the `location` field then shows the one you asked for (the full set is always in `locations`).
## `experienceMinYears` (type: `integer`):
Only jobs whose experience band reaches at least this many years. hirist matches on **overlap**, not containment — asking for 3–10 also returns a job advertised as 8–18, because the bands overlap.
## `experienceMaxYears` (type: `integer`):
Upper end of the experience band. See the overlap note above.
## `postedWithinDays` (type: `integer`):
Filtered by hirist before results are returned, so you are **not billed** for stale postings — a 968-result sample dropped to 126 at 7 days. Leave empty for everything.
## `startUrls` (type: `array`):
Search URLs (`https://www.hirist.tech/search/java-jobs`) contribute their keyword and still obey the filters above. Direct job URLs (`https://www.hirist.tech/j/{slug}-{id}`) are fetched individually.
## `fetchDescriptions` (type: `boolean`):
When enabled, each job additionally fetches its detail endpoint to add `description` (HTML), `descriptionText` (clean plain text) and `applyCount`. Turn this off for a roughly 2x faster run when the listing fields are enough.
## `postedWithinHours` (type: `integer`):
Re-checked against each job's own posted date. Set 24 for the last day, 72 for the last 3 days. Leave empty (or 0) to keep everything.
## `enrichEmails` (type: `boolean`):
hirist publishes the employer's own web domain on most postings, so this reads that company's real site rather than guessing a domain from its name. Adds contactEmail + contactWebsite columns plus a detailed emailEnrichment object. Best-effort, billed per contact email found; never charged for misses.
## `maxItems` (type: `integer`):
Hard cap on the number of jobs collected across every keyword. Use this to limit billing.
## `maxConcurrency` (type: `integer`):
Maximum number of job detail API calls processed in parallel.
## `maxRequestRetries` (type: `integer`):
Number of retries before a failed request is given up.
## `proxy` (type: `object`):
Optional and off by default. hirist's API answers directly without any anti-bot challenge, so a proxy adds latency and cost for no benefit. Only enable this if you need traffic to leave from a specific IP or country.
## Actor input object example
```json
{
"searchKeywords": [
"java"
],
"locations": [],
"fetchDescriptions": true,
"enrichEmails": false,
"maxItems": 1000,
"maxConcurrency": 10,
"maxRequestRetries": 4
}
```
# Actor output Schema
## `jobs` (type: `string`):
One row per job with title, employer and its web domain, recruiter, location list, salary band, experience range, mandatory vs optional skill tags, the full job description in HTML and plain text, and diversity-hiring flags.
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"searchKeywords": [
"java"
],
"locations": []
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/hirist-jobs-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"searchKeywords": ["java"],
"locations": [],
}
# Run the Actor and wait for it to finish
run = client.actor("memo23/hirist-jobs-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"searchKeywords": [
"java"
],
"locations": []
}' |
apify call memo23/hirist-jobs-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/hirist-jobs-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/Ovt9rigu38Fdp6Aqt/builds/ta37KBrdapuuRtWAV/openapi.json