# PanoramaFirm.pl Scraper (`memo23/panoramafirm-scraper`) Actor
Scrape panoramafirm.pl (Poland business directory) into structured company rows: name, phone, email when listed, website, address, NIP, hours, rating. Keyword plus city, nationwide category, or a Panorama Firm search or profile URL. HTTP only. JSON or CSV out. $5 per 1,000 listings.
- **URL**: https://apify.com/memo23/panoramafirm-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Lead generation, Business
- **Stats:** 2 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $5.00 / 1,000 listings
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## PanoramaFirm.pl Scraper
Turn a Panorama Firm search into structured Polish company rows: name, phone, email when listed, website, address, NIP, hours, rating, and profile link.
Keyword + city, nationwide category, or a panoramafirm.pl URL. JSON or CSV out.
This is **panoramafirm.pl** (WeNet / Panorama Firm). It is not [PagineGialle](https://apify.com/memo23/paginegialle-scraper), [PaginasAmarillas.es](https://apify.com/memo23/paginasamarillas-es-scraper), or [Herold.at](https://apify.com/memo23/herold-at-scraper).
### Why Use This Scraper?
- Phone and email on many search cards (JSON-LD)
- Profile pass for NIP, weekday hours, website, and reviews
- Pagination via `?page=2` on `/szukaj`
- HTTP only. No browser
### Overview
Built for sales teams, agencies, and researchers who need Polish **company** leads from Panorama Firm.
Every start type becomes **one dataset row per listing**. A keyword search and a profile URL emit the same flat shape. Rows are de-duplicated by profile slug.
### Supported Inputs
#### Search terms and locations
| Field | Example |
| --- | --- |
| `searchTerms` | `["restauracja"]`, `["hydraulik", "fryzjer"]` |
| `locations` | `["Warszawa"]`, `["Kraków"]`, `["pomorskie"]` |
Every term is searched in every location. Leave `locations` empty for a nationwide category search.
#### URL types
| URL type | Pattern | Example |
| --- | --- | --- |
| Search | `/szukaj?what=&where=` | `https://panoramafirm.pl/szukaj?what=restauracja&where=Warszawa` |
| Pretty search | `/{what}/{region},,{city}` | `https://panoramafirm.pl/restauracja/mazowieckie,,warszawa` |
| Search page | `/szukaj?...&page=N` or `/firmy,N.html` | `https://panoramafirm.pl/restauracja/mazowieckie,,warszawa/firmy,2.html` |
| Profile | `/{address-slug}/{company-slug}.html` | `https://panoramafirm.pl/mazowieckie,,warszawa,mokotów,postępu,14/wenet_sp._z_o.o.-sjdkw_aka.html` |
Search URLs paginate automatically.
**Unsupported:** firma.panoramafirm.pl account pages, Panorama Danych data-sales pages, article URLs under `/artykuly/`.
### Use Cases
| Audience | What they take from a run |
| --- | --- |
| Sales and outreach | Phone + email (when listed) + website by trade and city |
| Agencies | Cross-joined term × city lists in one dataset |
| Local SEO | Category, rating, and the Panorama Firm profile URL |
| Researchers | NIP, hours, and reviews for a trade in a city |
### How It Works
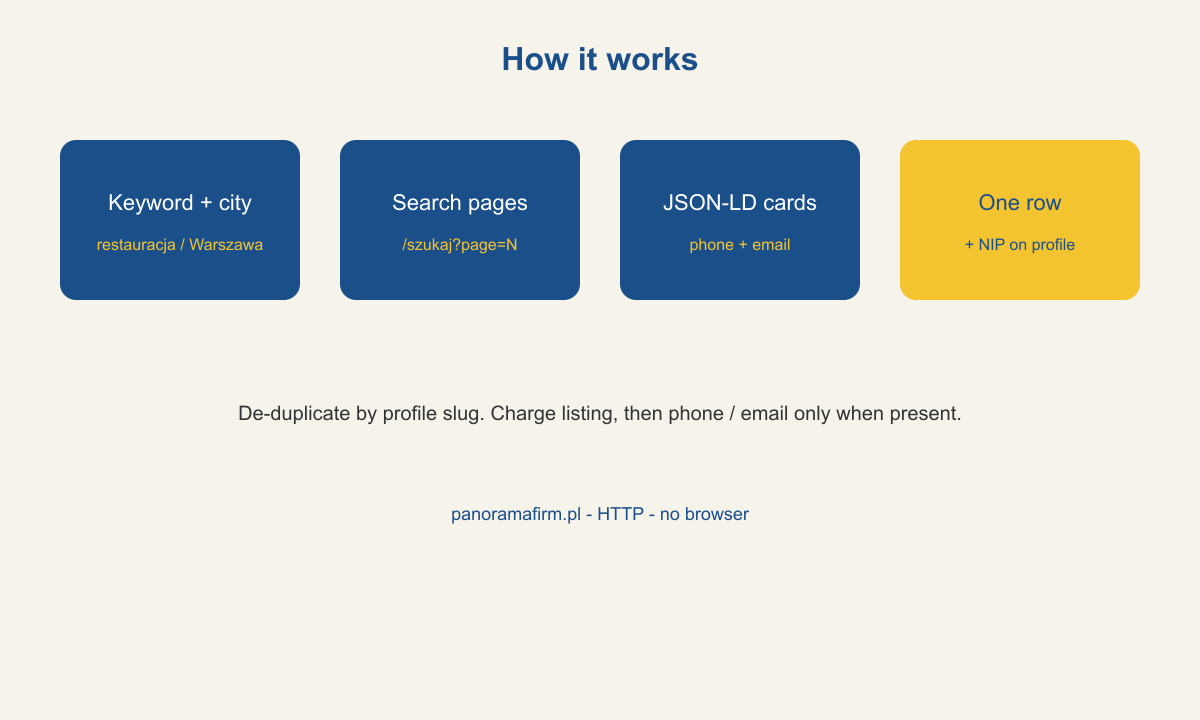
1. Cross-join `searchTerms` × `locations` (or nationwide if no city), plus any panoramafirm.pl URLs.
2. Fetch the search page.
3. Page with `?page=N` in parallel, stopping at `maxItems` or `maxPages`.
4. Read name, phone, email, and address from the search JSON-LD.
5. Optionally open the profile for NIP, hours, website, and reviews.
6. De-duplicate by listing id and push one row per company.
### Input Configuration
| Field | Type | Required | Notes |
| --- | --- | --- | --- |
| `searchTerms` | array | one of the start types | What you would type into Panorama Firm |
| `locations` | array | no | Polish city / region. Empty = nationwide |
| `startUrls` | array | one of the start types | Search or profile URL |
| `maxItems` | integer | no | Default 50. Free users capped at 50. |
| `scrapeDetails` | boolean | no | Default true. NIP, hours, website, reviews. |
| `maxPages` | integer | no | Default 20. |
| `maxConcurrency` | integer | no | Default 5. |
| `proxy` | object | no | Default is Apify datacenter. |
#### Example input
```json
{
"searchTerms": ["restauracja"],
"locations": ["Warszawa"],
"maxItems": 50
}
```
### Output Overview
One flat row per company. Contact and address fields sit at the top level. `searchTerm` tells you which input produced the row. Email is present when Panorama Firm publishes one on the card or the profile.
### Output Samples
Search: restauracja in Warszawa, with profile enrich.
```json
{
"listingId": "al_mar_aleksandra_wisniewska-sgnstf_roe",
"name": "Al-Mar Aleksandra Wiśniewska",
"phone": "500187522",
"email": "szkutnia@onet.pl",
"street": "ul. Kobiałka",
"postalCode": "03-044",
"city": "Warszawa",
"country": "PL",
"panoramaFirmUrl": "https://panoramafirm.pl/mazowieckie,,warszawa,białołęka,kobiałka,48a/al_mar_aleksandra_wisniewska-sgnstf_roe.html"
}
```
### Key Output Fields
**Identity:** `listingId`, `slug`, `name`, `panoramaFirmUrl`
**Contact:** `phone`, `phones`, `email`, `website`, `social`
**Place:** `address`, `street`, `postalCode`, `city`, `region`, `country`, `latitude`, `longitude`
**Company:** `taxId` (NIP)
**Directory:** `category`, `categories`, `rating`, `reviewCount`, `hours`, `description`, `images`, `logo`, `reviews`
**Provenance:** `searchTerm`, `scrapedAt`
### Pricing
| Event | When | Rate |
| --- | --- | --- |
| Actor start | Once per run, per GB of memory | $0.005 |
| Listing | Each unique company in the dataset | $0.005 ($5 / 1k) |
| Contact phone | Row has a phone | $0.002 |
| Contact email | Row has an email | $0.05 |
Phone and email are billed only when Panorama Firm publishes that field. A miss is free. Many cards already include both, so `scrapeDetails` is for NIP, hours, and website.
### FAQ
**Will every row have an email?** No. Phone is common. Inbox is on a large share of search cards, not all. Phone and email are billed as extra events only when the field is present.
**What does scrapeDetails add?** NIP, weekday hours, website, and reviews. Phone and email are already on many search cards.
**Do I need a proxy?** Datacenter is the default and is enough on a normal day. Switch to residential if a run comes back empty.
**Is there an official Android app?** No live Play listing. Leads come from the website.
### Support
- Issues: [Actor Issues](https://console.apify.com/actors/panoramafirm-scraper/issues)
- Author site:
- Email:
### Additional Services
Bulk województwo sweeps, scheduled refreshes, or a private API wrapper:
### Explore More Scrapers
Directory cousins: [PaginasAmarillas.es](https://apify.com/memo23/paginasamarillas-es-scraper), [Herold.at](https://apify.com/memo23/herold-at-scraper), [PagineGialle](https://apify.com/memo23/paginegialle-scraper), [local.ch](https://apify.com/memo23/local-ch-scraper), [Gelbe Seiten](https://apify.com/memo23/gelbeseiten-scraper), [Yellow Pages US](https://apify.com/memo23/yellow-pages-us-scraper), [Yellow Pages Canada](https://apify.com/memo23/yellowpages-ca-scraper), [Canada411](https://apify.com/memo23/canada411-scraper), and [PagesJaunes.fr](https://apify.com/memo23/pagesjaunes-scraper-cheerio). More actors on [memo23](https://apify.com/memo23) and [didovic](https://apify.com/didovic).
### 🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the [Apify MCP server](https://mcp.apify.com) or the Apify API (actor: `memo23/panoramafirm-scraper`).
**Purpose:** Extract PanoramaFirm.pl company listings (name, phone, email when listed, website, NIP, split address, hours) by keyword + city or URL.
**Minimal input:**
```json
{
"searchTerms": ["restauracja"],
"locations": ["Warszawa"],
"maxItems": 10
}
```
**Output:** one dataset row per company — `listingId`, `slug`, `name`, `phone`, `phones`, `email`, `website`, `taxId`, `social`, `address`, `street`, `postalCode`, `city`, `region`, `country`, `latitude`, `longitude`, `category`, `categories`, `rating`, `reviewCount`, `hours`, `description`, `images`, `logo`, `reviews`, `panoramaFirmUrl`, `searchTerm`, `scrapedAt`.
**Behaviors an agent should know:**
- Always set `maxItems`. Free users are capped at 50.
- `searchTerms` without `locations` runs a nationwide category search.
- `startUrls` work on their own (panoramafirm.pl only).
- Email is often already on the search card. Keep `scrapeDetails` true for NIP and hours.
- Each listing is $0.005. A phone on the row is $0.002. An email is $0.05. Start is $0.005 per GB.
- Poland company directory only.
### ⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Panorama Firm Sp. z o.o., WeNet, or panoramafirm.pl. All trademarks mentioned are the property of their respective owners.
The scraper reads publicly listed Polish company data from panoramafirm.pl. Users are responsible for ensuring their use complies with Panorama Firm Terms of Service, applicable data-protection law (GDPR / RODO), and any contractual obligations of their own organization.
### SEO Keywords
panoramafirm scraper, panoramafirm.pl scraper, scrape panoramafirm.pl, Polish business directory scraper, Poland yellow pages scraper, panorama firm API, Polish company listings scraper, Poland phone email scraper, Warszawa leads scraper, Apify panoramafirm, Polish restaurant leads, Kraków business scraper, NIP scraper, Polish directory scraper
# Actor input Schema
## `searchTerms` (type: `array`):
What you would type into Panorama Firm, e.g. restauracja, hydraulik, fryzjer. One row per term. Every term is searched in every city below. Leave cities empty for a nationwide category.
## `locations` (type: `array`):
Polish city or region, e.g. Warszawa, Kraków, pomorskie. Empty = nationwide.
## `maxItems` (type: `integer`):
Stop after this many unique companies across the whole run. Free plan is capped at 50.
## `startUrls` (type: `array`):
Examples: https://panoramafirm.pl/szukaj?what=restauracja\&where=Warszawa or https://panoramafirm.pl/mazowieckie,,warszawa,mokotów,postępu,14/wenet\_sp.\_z\_o.o.-sjdkw\_aka.html.
## `scrapeDetails` (type: `boolean`):
Opens the profile for NIP, weekday hours, website, and extra reviews. Phone and email are already on many search cards. Turn off to skip the extra profile requests.
## `maxPages` (type: `integer`):
Page N is ?page=N on /szukaj, or /firmy,N.html on a pretty URL.
## `maxConcurrency` (type: `integer`):
How many pages and profiles to load at the same time.
## `proxy` (type: `object`):
On by default (datacenter). Panorama Firm has no hard WAF; turn residential on only if a run starts getting empty pages.
## Actor input object example
```json
{
"searchTerms": [
"restauracja"
],
"locations": [
"Warszawa"
],
"maxItems": 50,
"scrapeDetails": true,
"maxPages": 20,
"maxConcurrency": 5,
"proxy": {
"useApifyProxy": true
}
}
```
# Actor output Schema
## `overview` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"searchTerms": [
"restauracja"
],
"locations": [
"Warszawa"
],
"proxy": {
"useApifyProxy": true
}
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/panoramafirm-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"searchTerms": ["restauracja"],
"locations": ["Warszawa"],
"proxy": { "useApifyProxy": True },
}
# Run the Actor and wait for it to finish
run = client.actor("memo23/panoramafirm-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"searchTerms": [
"restauracja"
],
"locations": [
"Warszawa"
],
"proxy": {
"useApifyProxy": true
}
}' |
apify call memo23/panoramafirm-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/panoramafirm-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/sFLseYdzjmEYuVqIi/builds/j7fv1d5lddH7Xt5w1/openapi.json