# Reddit Scraper — Search, Subreddits, Comments & Users (`memo23/reddit-search-comments-scraper`) Actor
Reddit scraper with no login or API key: search posts with Reddit's search syntax, read any subreddit's posts, full comment threads with replies, user profiles with their posts and comments, subreddit stats and trending searches. Scores, upvote ratio and media links.
- **URL**: https://apify.com/memo23/reddit-search-comments-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Social media, Lead generation
- **Stats:** 2 total users, 2 monthly users, 97.4% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $2.00 / 1,000 posts
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## Reddit Scraper — Search, Subreddits, Comments & Users
Get structured data from **Reddit** without an account or an API key: posts by search query with Reddit's own search syntax, any subreddit's posts, full comment threads with replies, user profiles with their posts and comments, subreddit stats and trending searches.
### What it does
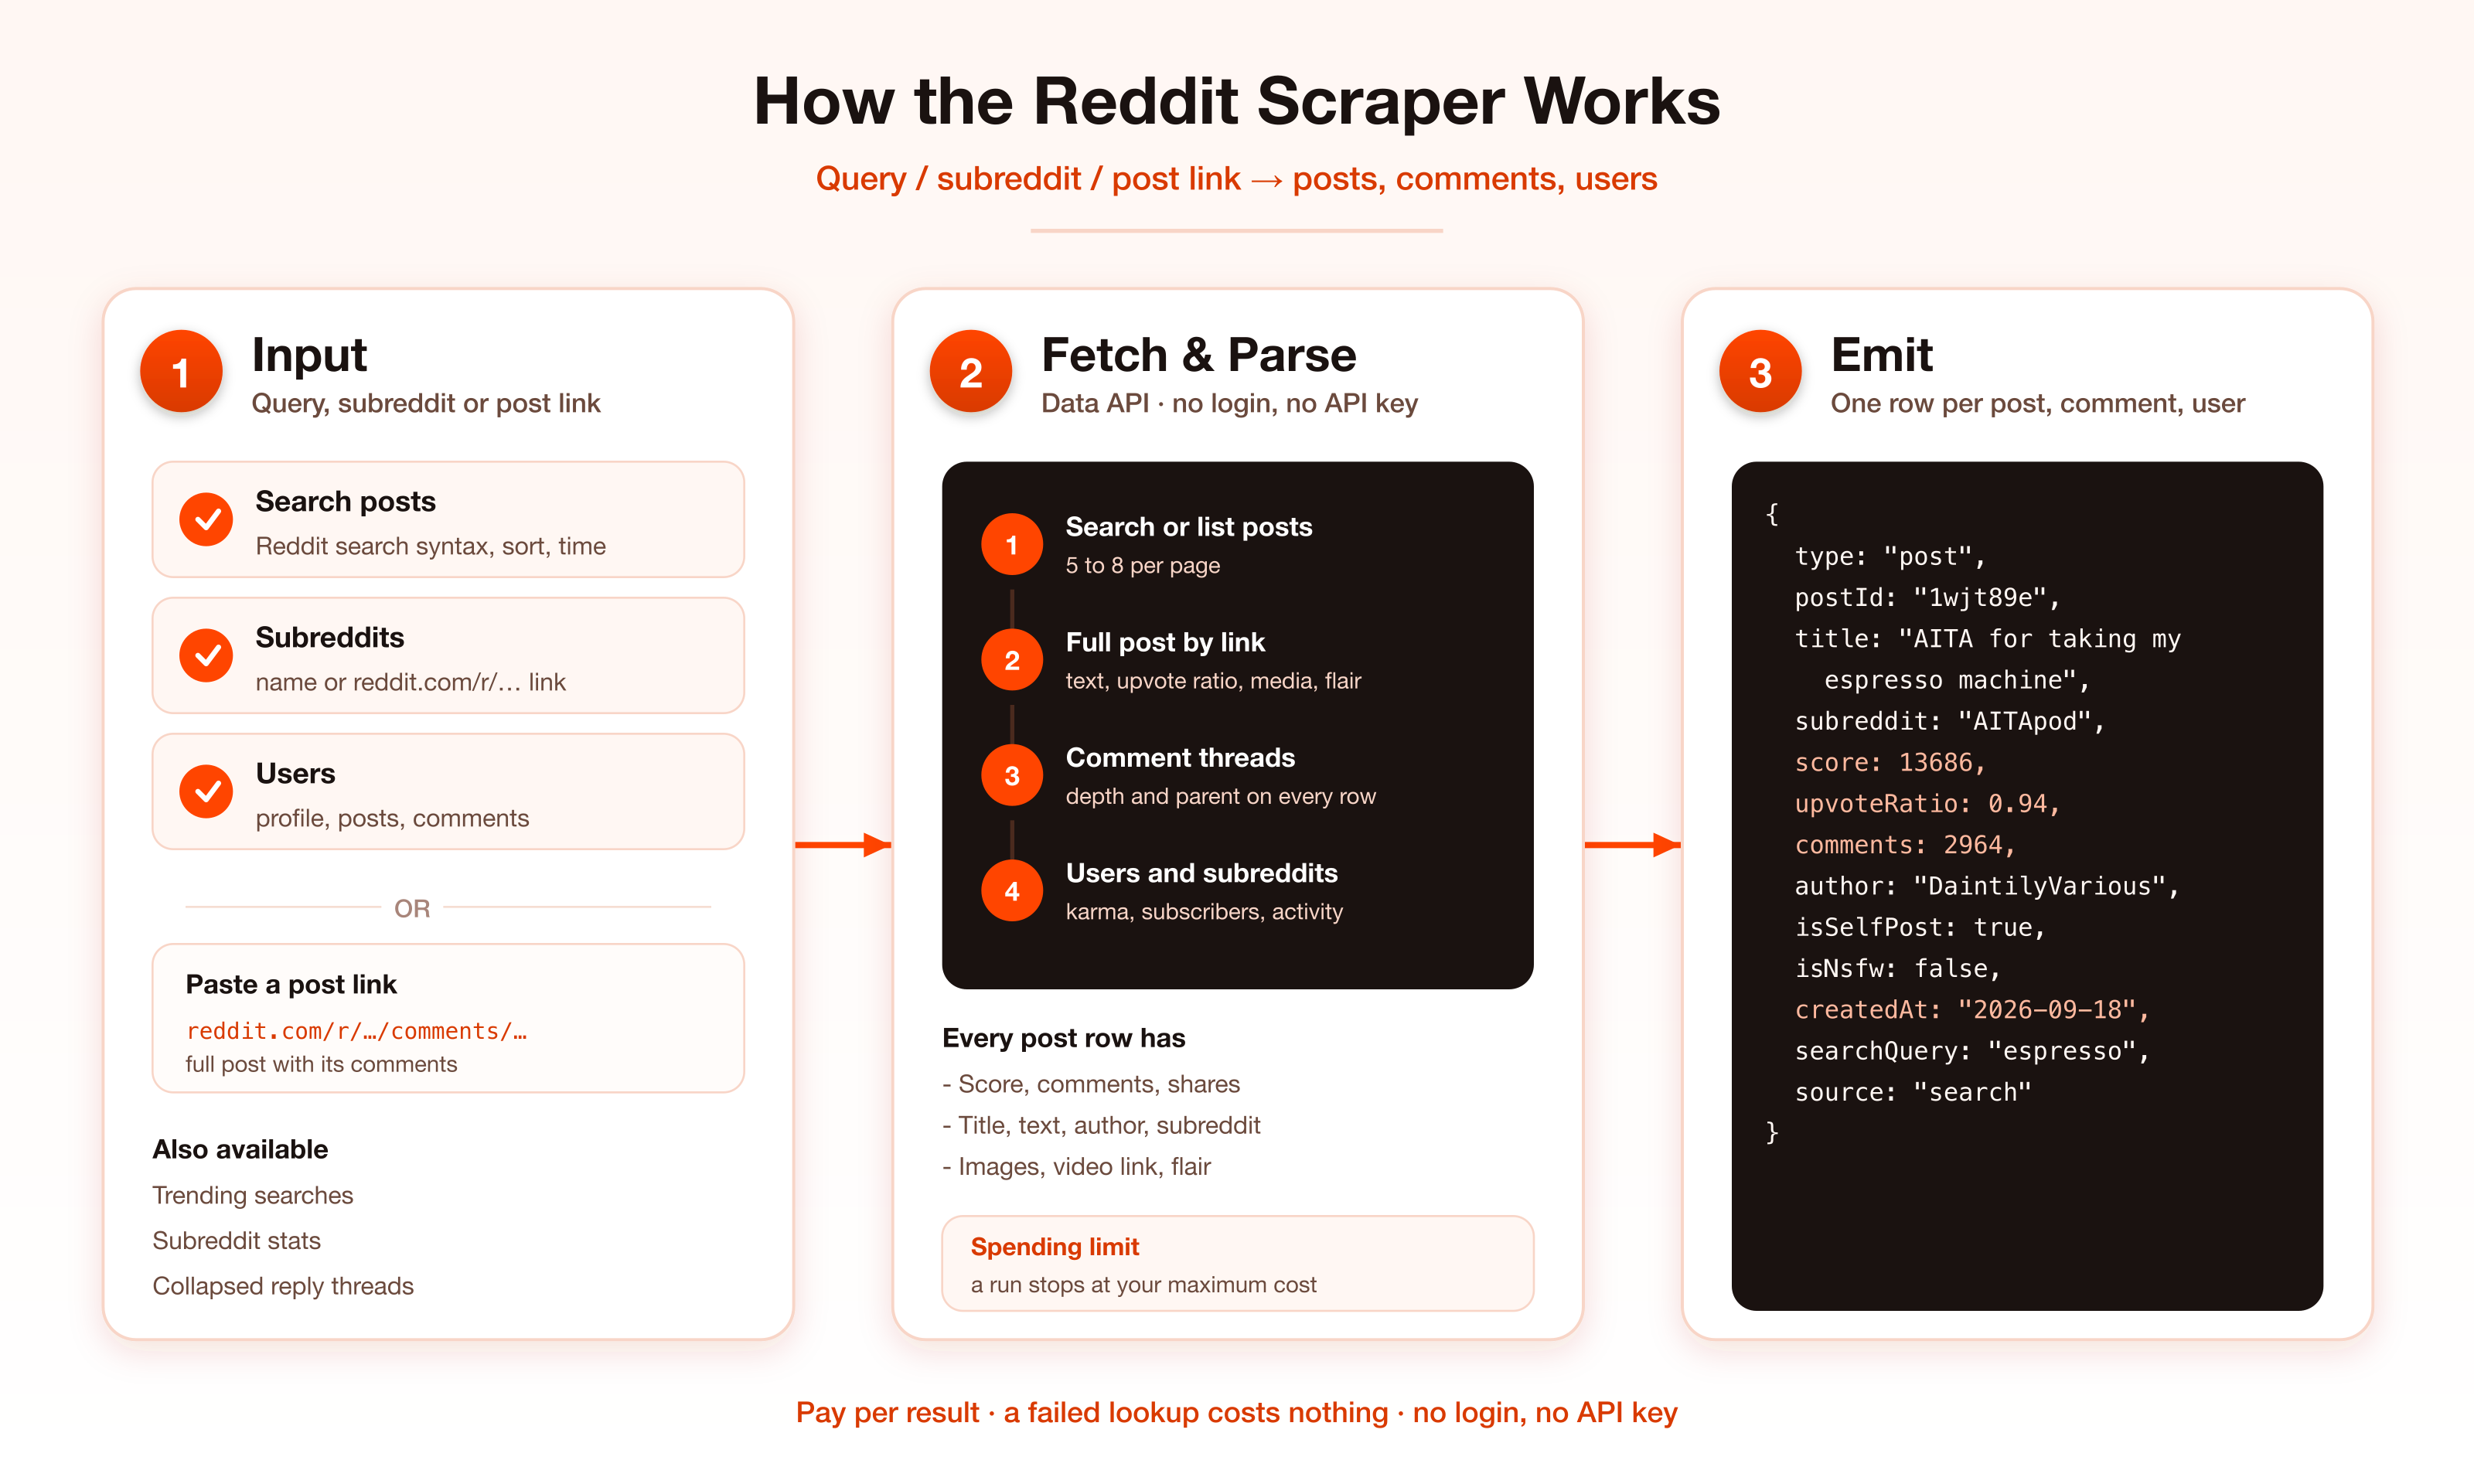
| Input | You get | Row type |
|-------|---------|----------|
| Search query | Posts matching it, sorted by relevance, hot, top, new or comment count, within a time range | `post` |
| Subreddit name or link | The subreddit's posts (hot, new, top, rising, best, controversial) | `post` |
| `includeSubredditInfo` | Subscribers, weekly active users and contributions, description, creation date | `subreddit` |
| `feeds` | Reddit's site-wide Popular, News and Games feeds | `post` |
| Post link or ID | The full post: text, score, upvote ratio, media, flair | `post` |
| `includeComments` | The comment thread of every post in the run, with depth and parent | `comment` |
| `expandReplies` | The reply chains Reddit folds behind "more replies" | `comment` |
| Username or profile link | Karma, post and comment counts, account age | `user` |
| `includeUserPosts` / `includeUserComments` | What the user posted and commented, newest first | `post`, `comment` |
| `includeTrendingSearches` | The searches trending on Reddit right now | `trending-search` |
The dataset has **Posts**, **Comments** and **Subreddits, users, trending** views.
### How It Works
### Why this one
- **No login, no API key, no proxy.** Nothing to register with Reddit and nothing to rotate.
- **Search with Reddit's syntax.** `subreddit:coffee`, `author:name`, `title:word`, `flair:name`, `"exact phrase"`, `AND`, `OR`, `NOT`, plus sort and time range.
- **Threads you can rebuild.** Every comment row has its `depth` and `parentCommentId`.
- **Folded replies on request.** Chains hidden behind "more replies" are opened when you ask.
- **Numbers that matter.** Score, upvote ratio, comment and share counts on posts; karma and activity on users; weekly activity on subreddits.
### Input
| Field | Type | Description |
|-------|------|-------------|
| `searchQueries` | `string[]` | Search queries. Reddit search syntax works inside the query. |
| `searchSort` | string | `RELEVANCE` (default), `HOT`, `TOP`, `NEW`, `COMMENTS`. |
| `searchTime` | string | `all` (default), `year`, `month`, `week`, `day`, `hour`. |
| `includeNsfw` | boolean | Also return NSFW posts in search. |
| `maxPostsPerQuery` | integer | Default 25, minimum 5. |
| `subreddits` | `string[]` | Names (`coffee`, `r/coffee`) or links. |
| `subredditSort` | string | `HOT` (default), `NEW`, `TOP`, `RISING`, `BEST`, `CONTROVERSIAL`. |
| `maxPostsPerSubreddit` | integer | Default 25, minimum 5. |
| `includeSubredditInfo` | boolean | One `subreddit` row per subreddit. |
| `feeds` / `feedSort` / `feedTime` / `maxPostsPerFeed` | `string[]` / string / string / integer | Site-wide feeds: `popular`, `news`, `games`. Sort and time range apply to Popular and Games. Default 25 posts per feed. |
| `postUrls` | `string[]` | Post links, `redd.it` short links or post IDs (billed `post-detail`). |
| `includeComments` / `maxCommentsPerPost` | boolean / integer | Comment rows for every post in the run. Default 30 per post. |
| `commentSort` | string | `CONFIDENCE` (best, default), `TOP`, `NEW`, `HOT`, `CONTROVERSIAL`, `OLD`. |
| `expandReplies` | boolean | Open folded reply chains that hide 3 or more replies. |
| `users` | `string[]` | Usernames (`spez`, `u/spez`) or profile links. |
| `includeUserProfile` | boolean | The profile row. On by default. |
| `includeUserPosts` / `includeUserComments` | boolean | The user's posts and comments. |
| `maxItemsPerUser` | integer | Default 25, minimum 5, for each of the two lists. |
| `includeTrendingSearches` | boolean | Trending searches. |
| `maxItems` | integer | Cap on post rows per run. Default 1,000. |
#### Example: search with comments
```json
{
"searchQueries": ["espresso machine", "subreddit:coffee grinder"],
"searchSort": "TOP",
"searchTime": "month",
"maxPostsPerQuery": 50,
"includeComments": true,
"maxCommentsPerPost": 40
}
```
#### Example: a subreddit
```json
{
"subreddits": ["https://www.reddit.com/r/coffee/"],
"subredditSort": "NEW",
"maxPostsPerSubreddit": 100,
"includeSubredditInfo": true
}
```
#### Example: what Reddit is upvoting today
```json
{
"feeds": ["popular", "news"],
"feedSort": "TOP",
"feedTime": "DAY",
"maxPostsPerFeed": 100
}
```
#### Example: one thread in full
```json
{
"postUrls": ["https://www.reddit.com/r/AskReddit/comments/1x355ez/"],
"includeComments": true,
"maxCommentsPerPost": 500,
"expandReplies": true
}
```
### Output
Post:
```json
{
"type": "post",
"postId": "1wjt89e",
"url": "https://www.reddit.com/r/AITApod/comments/1wjt89e/",
"title": "AITA for taking my espresso machine home after my coworker kept using it?",
"text": "I work in a pretty small office and the coffee there…",
"subreddit": "AITApod",
"subredditSubscribers": 41604,
"author": "DaintilyVarious",
"score": 13686,
"upvoteRatio": 0.94,
"comments": 2964,
"createdAt": "2026-09-18T15:24:33.710Z",
"isSelfPost": true,
"isNsfw": false,
"source": "search",
"searchQuery": "espresso machine"
}
```
Post rows also carry `linkUrl` (for link posts), `domain`, `flair`, `shares`, `images[]`, `videoUrl`, `thumbnailUrl`, `editedAt` and the flags `isSpoiler`, `isStickied`, `isLocked`, `isArchived`. Posts read from a subreddit listing carry title, text preview, author, score, comment and share counts, flair and media; give the post's link in `postUrls` for the upvote ratio and the full text.
Comment:
```json
{
"type": "comment",
"commentId": "pal8h5t",
"postId": "1wjt89e",
"postTitle": "AITA for taking my espresso machine home…",
"subreddit": "AITApod",
"parentCommentId": null,
"depth": 0,
"text": "He should get his own machine.",
"author": "patientpartner09",
"score": 1255,
"createdAt": "2026-09-18T15:27:46.166Z"
}
```
A `user` row has `username`, `karma`, `postKarma`, `commentKarma`, `posts`, `comments`, `createdAt`, `isVerified`. A `subreddit` row has `subreddit`, `title`, `description`, `subscribers`, `weeklyActiveUsers`, `weeklyContributions`, `createdAt`, `visibility`.
### Pricing
Pay per event. You pay for rows you receive; a lookup that returns nothing costs nothing.
| Event | When | Price |
|-------|------|-------|
| Actor start | Once per run | $0.005 |
| Post | Each post from search, a subreddit or a user | $0.002 |
| Comment | Each comment row | $0.002 |
| Post detail | Each post given by link | $0.003 |
| Subreddit | Each subreddit info row | $0.003 |
| User profile | Each user profile row | $0.003 |
| Trending search | Each trending search | $0.002 |
1,000 posts cost $2. Set a maximum cost per run in the run options and the Actor stops there with what it has.
### FAQ
**Do I need a Reddit account, an API key or a proxy?**
No.
**Why did I get 7 posts when I asked for 10?**
Posts arrive in pages of 5 to 8. A further page is read only when at least 5 more are wanted, so small remainders are dropped.
**Why do some posts have no comment rows?**
Comments are read for posts with at least 5 comments.
**How do I rebuild a thread?**
Top-level comments have `depth` 0 and no `parentCommentId`. Every reply points at its parent through `parentCommentId`.
**How far back does a subreddit listing go?**
As far as Reddit pages it: about 1,000 posts for a listing. Use search with `subreddit:name` and a time range to reach older posts.
**Are removed or private posts returned?**
No. They are reported in the log and not charged.
### 🤖 For AI Agents & LLM Apps
**Purpose:** Reddit posts, comments, users, subreddit stats and trending searches as structured JSON, with no login or API key.
**Minimal input:** `{"searchQueries": ["espresso machine"], "maxPostsPerQuery": 10}`
**Output:** rows with `type` = `post` | `comment` | `subreddit` | `user` | `trending-search`. Posts: postId, url, title, text, subreddit, author, score, upvoteRatio, comments, createdAt, linkUrl, images, videoUrl. Comments: commentId, postId, parentCommentId, depth, text, author, score, createdAt.
**Behaviors to know:** `maxItems` caps post rows only. Per-source minimums are 5. Search syntax goes inside the query string. Free-plan runs return up to 100 posts.
### ⚠️ Disclaimer
This Actor collects publicly available data only. It is not affiliated with, endorsed by, or sponsored by Reddit, Inc. You are responsible for using the data in line with applicable laws and Reddit's terms, including rules on personal data.
### SEO Keywords
reddit scraper, reddit search scraper, subreddit scraper, reddit comments scraper, reddit posts scraper, reddit user scraper, reddit api alternative, reddit no login scraper, reddit thread scraper, reddit replies, subreddit stats, reddit trending searches, reddit data export, reddit sentiment data, reddit brand monitoring
# Actor input Schema
## `searchQueries` (type: `array`):
Search Reddit posts by keyword. Reddit search syntax works: subreddit:coffee, author:name, title:word, flair:name, "exact phrase", AND, OR, NOT. A page holds about 7 posts.
## `searchSort` (type: `string`):
Order of the search results.
## `searchTime` (type: `string`):
Limit the search to a time range.
## `includeNsfw` (type: `boolean`):
Also return posts marked NSFW in search.
## `maxPostsPerQuery` (type: `integer`):
Posts to return for each query (minimum 5).
## `subreddits` (type: `array`):
Subreddit names (coffee, r/coffee) or links (https://www.reddit.com/r/coffee/). Each returns the subreddit's posts.
## `subredditSort` (type: `string`):
Which listing of the subreddit to read.
## `maxPostsPerSubreddit` (type: `integer`):
Posts to return for each subreddit (minimum 5). A page holds 5 to 8.
## `includeSubredditInfo` (type: `boolean`):
Add one row per subreddit: subscribers, weekly active users and contributions, description, creation date, visibility.
## `feeds` (type: `array`):
Reddit's own feeds across all subreddits: Popular is what the whole site is upvoting, News is current-affairs posts, Games is gaming posts.
## `feedSort` (type: `string`):
Order of the Popular and Games feeds. The News feed has one order.
## `feedTime` (type: `string`):
Time range for the Popular and Games feeds when sorted by Top or Controversial.
## `maxPostsPerFeed` (type: `integer`):
Upper limit of posts for each feed (minimum 5). A page holds 7 to 9.
## `postUrls` (type: `array`):
Reddit post links (https://www.reddit.com/r/…/comments/abc123/…), redd.it short links or post IDs. Each returns the full post: text, score, upvote ratio, media, flair.
## `includeComments` (type: `boolean`):
Return the comments of every post in the run as separate rows, with depth and parent so the thread can be rebuilt. Posts with fewer than 5 comments are skipped.
## `maxCommentsPerPost` (type: `integer`):
Comments to return for each post (minimum 5). A page holds about 8.
## `commentSort` (type: `string`):
Order of the comments.
## `expandReplies` (type: `boolean`):
Reddit folds long reply chains behind "more replies". Turn this on to open the folded chains that hide 3 or more replies.
## `users` (type: `array`):
Reddit usernames (spez, u/spez) or profile links. Each returns the profile: karma, post and comment counts, account age.
## `includeUserProfile` (type: `boolean`):
Return the profile row.
## `includeUserPosts` (type: `boolean`):
Return the user's posts, newest first.
## `includeUserComments` (type: `boolean`):
Return the user's comments, newest first, each with the post it was written under.
## `maxItemsPerUser` (type: `integer`):
Posts and comments to return for each user, for each of the two lists (minimum 5).
## `includeTrendingSearches` (type: `boolean`):
Return the searches trending on Reddit right now.
## `maxItems` (type: `integer`):
Upper limit on post rows across the whole run (minimum 5). Free-plan accounts get up to 100.
## Actor input object example
```json
{
"searchQueries": [
"espresso machine"
],
"searchSort": "RELEVANCE",
"searchTime": "all",
"includeNsfw": false,
"maxPostsPerQuery": 25,
"subredditSort": "HOT",
"maxPostsPerSubreddit": 25,
"includeSubredditInfo": false,
"feedSort": "HOT",
"feedTime": "DAY",
"maxPostsPerFeed": 25,
"includeComments": false,
"maxCommentsPerPost": 30,
"commentSort": "CONFIDENCE",
"expandReplies": false,
"includeUserProfile": true,
"includeUserPosts": false,
"includeUserComments": false,
"maxItemsPerUser": 25,
"includeTrendingSearches": false,
"maxItems": 1000
}
```
# Actor output Schema
## `results` (type: `string`):
Rows told apart by `type`: `post`, `comment`, `subreddit`, `user` and `trending-search`.
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"searchQueries": [
"espresso machine"
]
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/reddit-search-comments-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = { "searchQueries": ["espresso machine"] }
# Run the Actor and wait for it to finish
run = client.actor("memo23/reddit-search-comments-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"searchQueries": [
"espresso machine"
]
}' |
apify call memo23/reddit-search-comments-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/reddit-search-comments-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/yxZoaalur65mLzyhG/builds/dlUftOwbfiFZCfDnw/openapi.json