# Upwork Search Job(s) Scraper (No Cookies) (Richest output) (`memo23/upwork-jobs-scraper`) Actor
Extract detailed Upwork job listings with our scraper. Get job descriptions, budgets, required skills, client history, and engagement terms in a structured format. Perfect for market research and competitive analysis.
- **URL**: https://apify.com/memo23/upwork-jobs-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Jobs, Automation, Lead generation
- **Stats:** 144 total users, 34 monthly users, 100.0% runs succeeded, 6 bookmarks
- **User rating**: 4.57 out of 5 stars
## Pricing
from $2.00 / 1,000 results
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
## Upwork Jobs Scraper — 130K+ Instant Database, Fresh Every 6h
The only Upwork job scraper backed by its **own 130,000+ job database** — search by keyword and filters and get results **instantly**, uncapped, with nothing to get blocked. The database is refreshed every 6 hours, so you get today's jobs without ever hammering Upwork yourself. Need a filter we don't cover yet? It automatically falls back to a fresh live scrape, so you always get data.
| You give it | You get back |
|---|---|
| A keyword (e.g. `python scraper`) + optional filters | Every matching job from the 130k+ database, newest first |
| A public Upwork search URL | The same jobs that URL would show, fully structured |
| `minFixedBudget`, `experienceLevel`, `jobType`, `clientLocation`, `maxAgeDays`, `publishedAfter` | Precisely filtered results — budgets, client country, skills, activity all included |
> Pure HTTP + a pre-harvested database. No browser, no third-party CAPTCHA-bypass service, no per-search 250-job cap.
### Why use this instead of a live-only scraper
- **Instant & uncapped.** Live Upwork scrapers re-fetch every run, get rate-limited, and stop around Upwork's ~50–250 results per search. This one serves from a cumulative database — ask for 5,000 python jobs and get 5,000.
- **Always fresh.** A background worker refreshes the mirror every 6 hours and ages out jobs older than 45 days, so results are current without you paying for a live crawl each time.
- **Budgets & client data included.** ~40% of jobs carry an explicit fixed budget and ~100% carry client country — the fields that make Upwork data actually useful for demand analysis.
- **Nothing to get blocked.** Because the common case is served from the database, there's no live request to detect or ban.
- **Two ways in, one clean schema.** Paste a search URL or use structured filters — either returns the identical, fully-nested job object.
### Overview
Upwork is the largest open marketplace of paid freelance work — every job post is a business holding out a budget to solve a problem. That makes it the richest public signal of **what services are in demand and what people will pay for them**. This actor turns that stream into structured data you can filter, export, and analyze:
- **Recruiters & agencies** — find live projects in your niche and the clients posting them.
- **Lead generation** — surface businesses actively hiring for a service you sell.
- **Freelancers** — monitor new gigs matching your skills, filtered by budget and client quality.
- **Market & startup-idea research** — cluster recurring paid tasks to find automation opportunities and validate demand with real budgets, not guesses.
### Supported inputs
| Input | Example | Emits |
|---|---|---|
| Search keywords + filters | `searchQuery: "web scraping"`, `minFixedBudget: 200` | All matching jobs from the database |
| Upwork search URL | `https://www.upwork.com/nx/search/jobs/?q=python&sort=recency` | The jobs that URL resolves to |
| Individual job URL | `https://www.upwork.com/jobs/~021936702637394960044` | That single job, fully structured |
### How it works
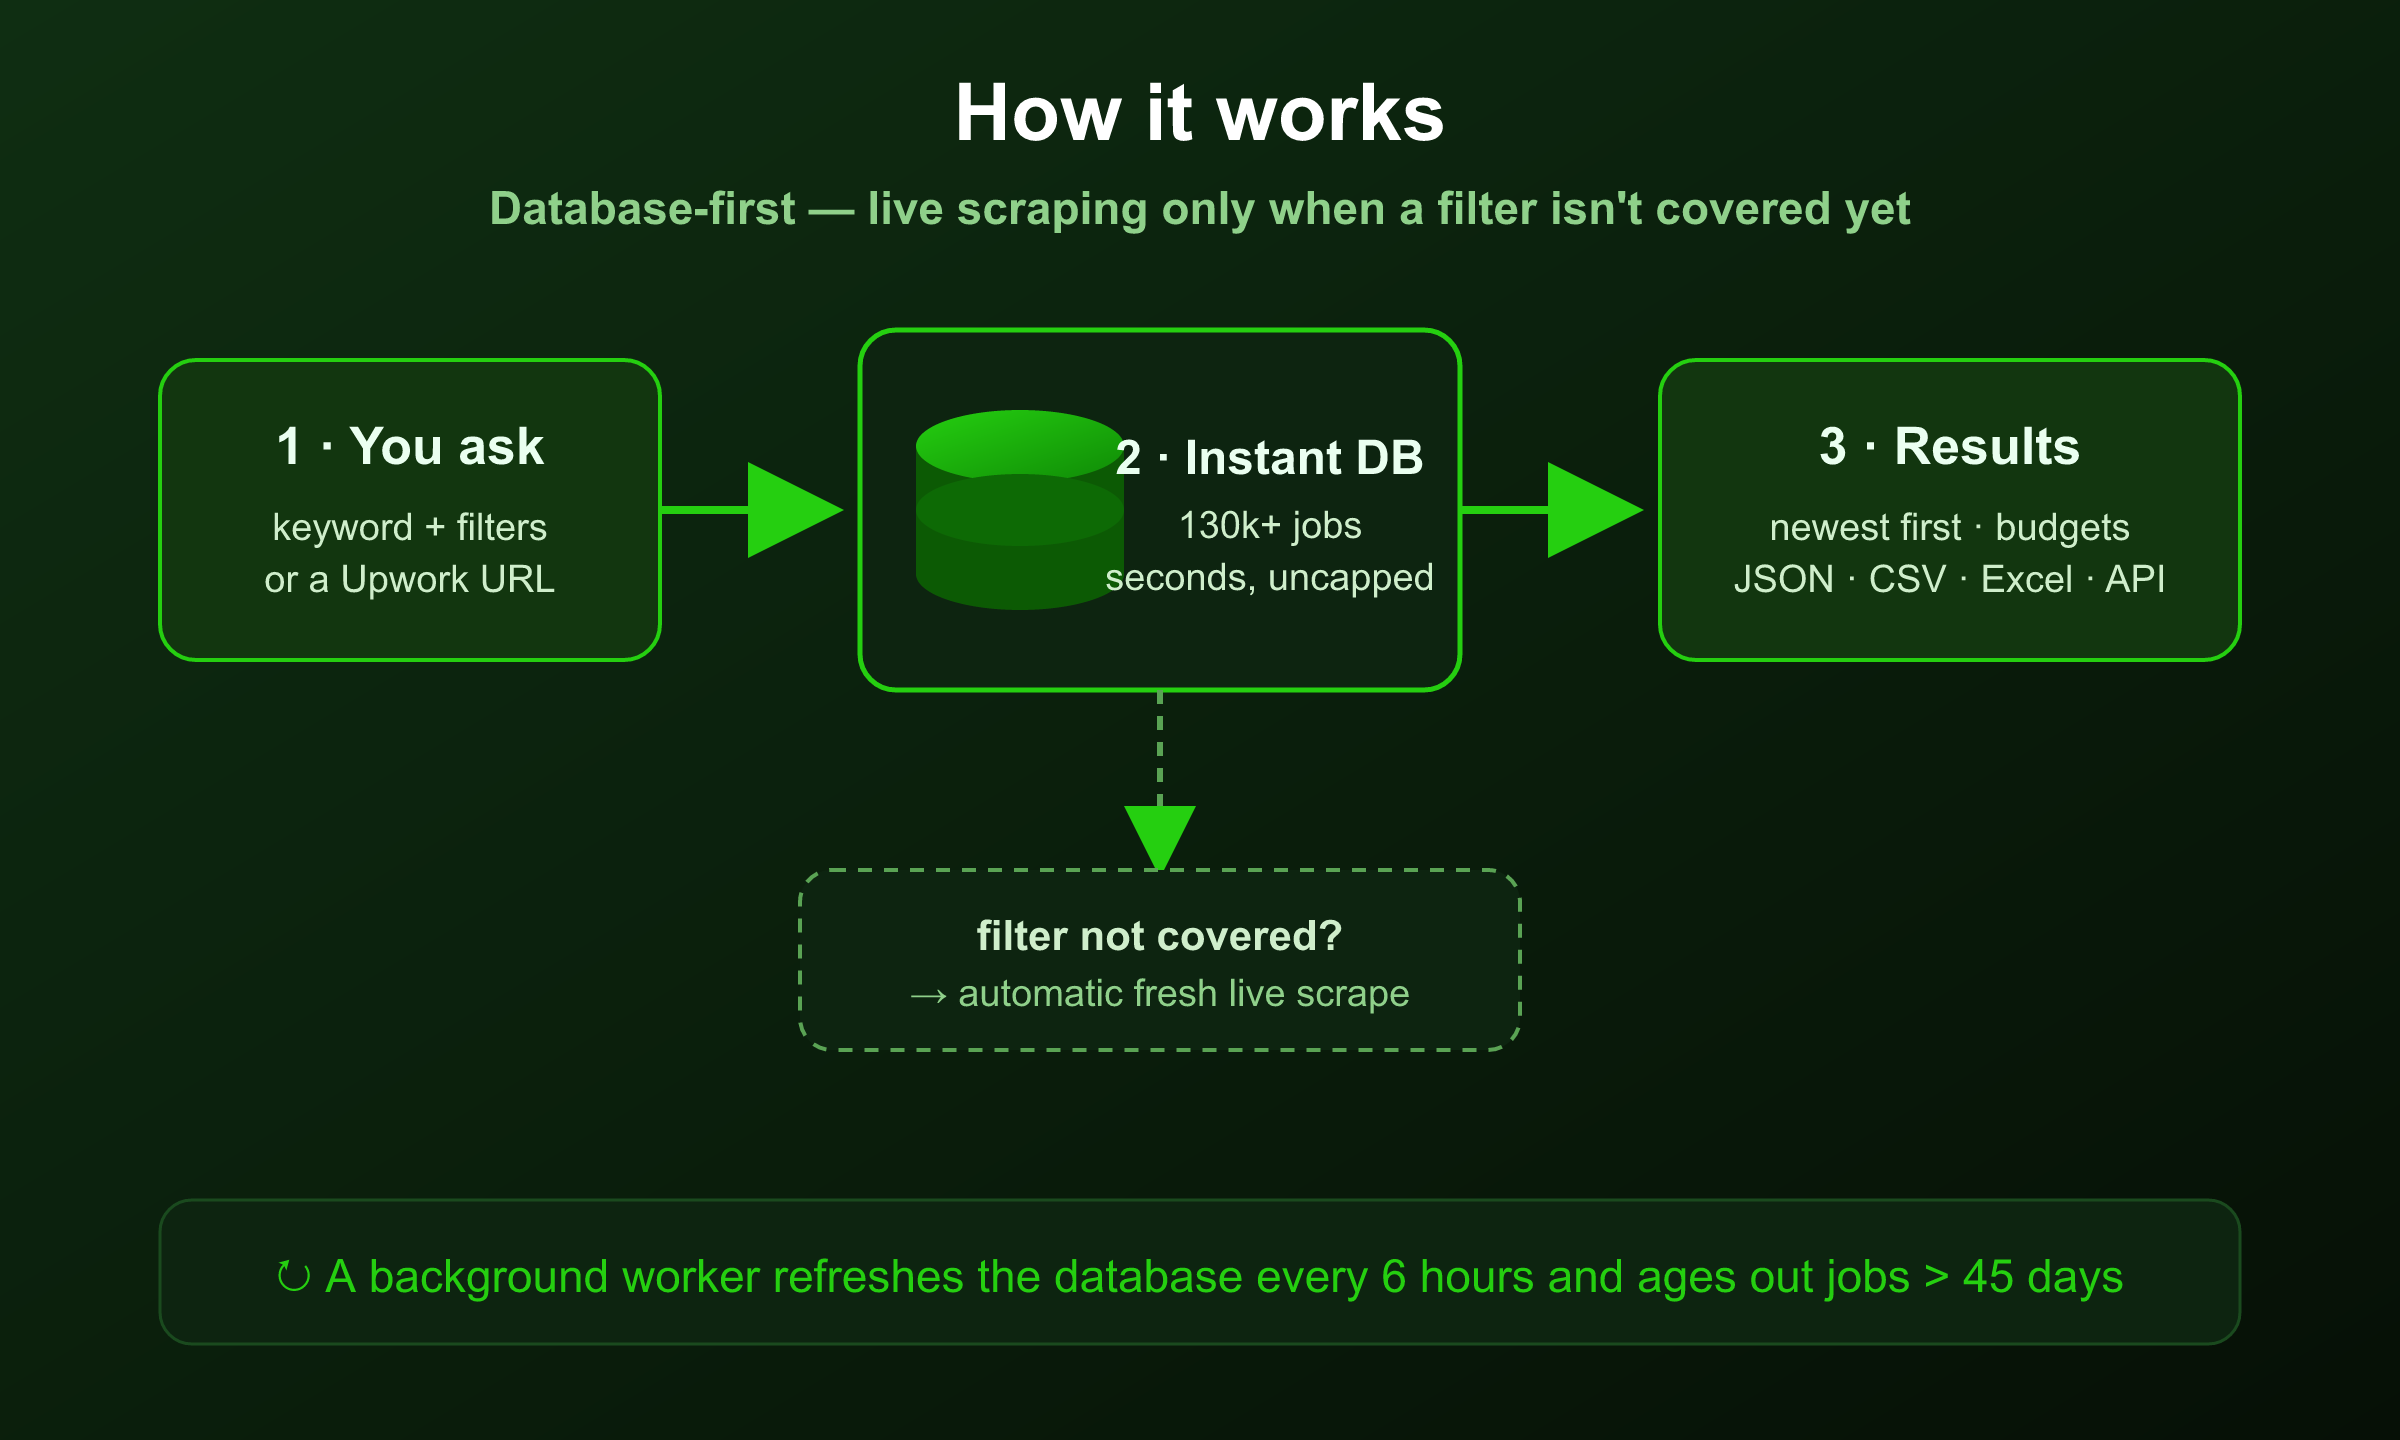
1. **You submit** a keyword + filters (or a URL).
2. **The Instant Database** is queried first — a cumulative Turso store of 130k+ Upwork jobs, indexed for full-text keyword search and filtered by budget, experience, job type, client location and publish date. Results come back in seconds, newest first.
3. **Automatic live fallback** — if a filter combination isn't yet covered in the database, the actor transparently runs a fresh scrape so you still get data.
4. **A background worker** refreshes the database every 6 hours and ages out stale jobs, keeping results current.
5. **You export** to JSON, CSV or Excel, or pull via the Apify API.
### Input configuration
| Field | Type | Required | Notes |
|---|---|---|---|
| `startUrls` | array | one of URL / keywords | Public Upwork search or job URLs. Filters in the URL are honored. |
| `searchQuery` | string | one of URL / keywords | Keywords matched against job title + description. |
| `jobType` | array | no | `hourly`, `fixed`. |
| `experienceLevel` | array | no | `entry`, `intermediate`, `expert`. |
| `minFixedBudget` | number | no | Only fixed-price jobs with budget ≥ this (USD). |
| `clientLocation` | array | no | Client country name(s), substring match. |
| `maxAgeDays` | number | no | Only jobs published in the last N days. |
| `publishedAfter` | string | no | Only jobs published at/after this ISO date (e.g. `2026-07-01`). |
| `monitorMode` | boolean | no | 🔔 Return only jobs new since the previous run for this exact search. Put the Actor on a Schedule for a clean, duplicate-free feed of new gigs. |
| `maxItems` | number | no | Cap on jobs returned per search. |
| `proxy` | object | no | Optional proxy override (only used on live fallback). |
#### Example input
```json
{
"searchQuery": "web scraping",
"jobType": ["fixed"],
"experienceLevel": ["intermediate", "expert"],
"minFixedBudget": 200,
"maxAgeDays": 7,
"maxItems": 500
}
```
### Output
Each row is one job, returned in Upwork's own nested shape so nothing is lost. Abridged sample:
```jsonc
{
"opening": {
"job": {
"status": "ACTIVE",
"publishTime": "2026-07-08T08:27:46.991Z",
"contractorTier": "INTERMEDIATE",
"info": {
"ciphertext": "~021936702637394960044",
"type": "FIXED",
"title": "Social Media Manager for Airbnb & Hotels"
},
"category": { "name": "Digital Marketing", "urlSlug": "digital-marketing" },
"categoryGroup": { "name": "Sales & Marketing" },
"budget": { "amount": 300, "currencyCode": "USD" },
"engagementDuration": { "label": "1 to 3 months", "weeks": 9 },
"sandsData": {
"occupation": { "prefLabel": "Social Media Marketing" },
"additionalSkills": [{ "prefLabel": "Instagram" }, { "prefLabel": "Facebook" }]
},
"clientActivity": { "totalApplicants": 20, "totalHired": 0 }
}
},
"buyer": {
"isPaymentMethodVerified": false,
"info": {
"location": { "country": "Seychelles", "city": null },
"stats": { "totalAssignments": 0, "feedbackCount": 0, "score": 0 },
"company": { "profile": { "industry": "Travel & Hospitality", "size": 1 } }
}
}
}
```
#### Key output fields
| Field | Meaning |
|---|---|
| `opening.job.info.title` / `.type` | Job title and payment type (FIXED / HOURLY) |
| `opening.job.budget.amount` | Fixed-price budget in USD |
| `opening.job.contractorTier` | Required experience level |
| `opening.job.category` / `categoryGroup` | Upwork category taxonomy |
| `opening.job.sandsData.*Skills` | Occupation + skill tags |
| `opening.job.publishTime` | When the job was posted (sort/monitor on this) |
| `opening.job.clientActivity.totalApplicants` / `totalHired` | Competition + hiring signal |
| `buyer.info.location.country` | Client country |
| `buyer.info.stats.*` | Client history — assignments, spend, feedback score |
| `buyer.isPaymentMethodVerified` | Whether the client's payment method is verified |
### Pricing
Pay-per-event. You're charged per job returned plus a small run-start fee — the same whether a result is served instantly from the database or live-scraped.
| Event | When | Notes |
|---|---|---|
| Actor start | Per run | Standard platform start fee |
| Job result | Per job returned | The bulk of the cost |
### 🔔 Monitoring mode — a live feed of new gigs
Turn on **`monitorMode`** and put the Actor on a **Schedule** (Apify Console → Schedules, e.g. hourly or daily). Each run then returns **only jobs posted since the previous run** for that exact keyword + filter combination — a clean, duplicate-free feed you can wire to a webhook, Slack, or email integration.
- The **first** run seeds the cursor and returns the current matches.
- **Every run after** returns only what's new (often zero — that's a valid "nothing new yet" result, not an error).
- Each distinct search (different keywords/filters) is tracked **separately**, so you can run several monitors in parallel.
Typical setup: `searchQuery: "shopify developer"`, `minFixedBudget: 200`, `monitorMode: true`, scheduled hourly → you get pinged only when a new matching gig appears.
### Common use cases
- **"Show me every fixed-budget web-scraping job over $200 posted this week."** — recurring manual tasks people pay for = automation opportunities.
- **"Alert me the moment a new Shopify-developer gig is posted."** — `monitorMode: true` on an hourly schedule (see above).
- **"Which clients in the US are hiring for lead generation right now?"** — filter by keyword + `clientLocation` for a warm B2B lead list.
- **"What are people paying freelancers to do that I could turn into a product?"** — export a category and cluster the recurring pain points with budgets attached.
### FAQ
**How fresh is the database?** Refreshed every 6 hours; jobs older than 45 days are aged out.
**What if my exact filter isn't in the database?** The actor automatically falls back to a live scrape for that query, so you still get results.
**Is there a per-search cap like on Upwork itself?** No. Upwork limits a search to a few hundred results; the database serves as many matches as exist, up to your `maxItems`.
**Do I get client budgets?** Yes where Upwork exposes them — roughly 40% of jobs carry an explicit fixed budget, and nearly all carry client country and activity stats.
**Can I scrape a single job page?** Yes — pass the job URL in `startUrls`.
### Support
Questions, custom fields, or bulk/enterprise needs: **muhameddidovic@gmail.com**. More tools: Upwork Reviews Scraper · Fiverr Scraper · Indeed Scraper.
### 🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the [Apify MCP server](https://mcp.apify.com) or the Apify API (actor: `memo23/upwork-jobs-scraper-ppe`).
**Purpose:** Return structured Upwork job postings (title, type, budget, skills, category, client country/stats) served instantly from a cumulative 130k+ job database refreshed every 6 hours, with automatic live-scrape fallback for uncovered filters.
**Minimal input:**
```json
{ "searchQuery": "web scraping", "maxItems": 25 }
```
Instead of `searchQuery`, pass `startUrls` with a public Upwork search or single-job URL (e.g. `https://www.upwork.com/nx/search/jobs/?q=python&sort=recency`); URL filters are honoured. Optional filters: `jobType` (hourly/fixed), `experienceLevel` (entry/intermediate/expert), `sortBy` (relevance/recent), `categories`, `subcategories`, `hoursPerWeek`, `projectLength`, `contractToHire`, `maxAgeDays`, `publishedAfter` (YYYY-MM-DD), `minFixedBudget`, `clientHires`, `clientLocation`, `clientTimezone`, `monitorMode`, `maxConcurrency`, `minConcurrency`, `maxRequestRetries`, `proxy`.
**Output:** one dataset row per job in Upwork's nested shape — opening.job.info (ciphertext, type, title), opening.job.status, opening.job.publishTime, opening.job.contractorTier, opening.job.budget (amount, currencyCode), opening.job.category / categoryGroup, opening.job.engagementDuration, opening.job.sandsData (occupation, additionalSkills), opening.job.clientActivity (totalApplicants, totalHired), buyer.info.location.country, buyer.info.stats (totalAssignments, feedbackCount, score), buyer.info.company.profile, buyer.isPaymentMethodVerified.
**Behaviors an agent should know:**
- Always set `maxItems` (default 100); unlike live Upwork (capped ~50–250 per search), the database serves as many matches as exist up to the cap.
- Provide exactly one of `searchQuery` or `startUrls`; a URL's own filters take priority.
- Queried against the Instant Database first (newest-first); uncovered filter combos transparently fall through to a live scrape. Jobs older than 45 days are aged out.
- `monitorMode: true` on a Schedule returns only jobs new since the previous run for that exact keyword/filter set; first run seeds the cursor, later runs may return zero (valid, not an error).
- \~40% of jobs carry an explicit fixed budget; nearly all carry client country and activity stats.
- Pay-per-event: charged per job returned plus a small run-start fee, the same whether served from the database or live-scraped.
### ⚠️ Disclaimer
This actor collects only **publicly available** job-posting data from Upwork and performs no login, paywall circumvention, or access to private/personal account data. You are responsible for using the output in compliance with Upwork's Terms of Service, applicable laws, and data-protection regulations (including GDPR/CCPA where relevant). This tool is provided for legitimate research, recruiting, and market-analysis purposes. It is not affiliated with, endorsed by, or sponsored by Upwork Global Inc. "Upwork" is a trademark of its respective owner.
### SEO Keywords
Upwork scraper, Upwork jobs scraper, Upwork job data, Upwork API alternative, scrape Upwork jobs, Upwork freelance jobs, freelance job data, Upwork market research, freelance demand data, Upwork lead generation, Upwork recruiting tool, gig economy data, freelance market analysis, Upwork jobs database, Upwork job monitoring, startup idea validation, SaaS idea research, pain point research, automation opportunity finder, Upwork budget data, freelance job feed, Upwork jobs by keyword, Upwork jobs by budget.
# Actor input Schema
## `startUrls` (type: `array`):
Public Upwork search URLs to scrape (e.g. https://www.upwork.com/nx/search/jobs/?q=python+developer\&sort=recency). Any filters already in the URL are honored. Leave empty to use the structured filters below instead.
## `searchQuery` (type: `string`):
What to search for in job titles and descriptions. Served instantly from our 130k+ job database; falls back to live scraping only for filters not yet covered.
## `jobType` (type: `array`):
Restrict to hourly and/or fixed-price jobs.
## `experienceLevel` (type: `array`):
Restrict to one or more required experience levels.
## `sortBy` (type: `string`):
Order results by best match or newest first.
## `categories` (type: `array`):
Restrict to one or more Upwork job categories.
## `subcategories` (type: `array`):
One or more Upwork subcategory UIDs (advanced). Tick a subcategory on Upwork's search page and copy the numeric `subcategory2_uid` value from the resulting URL, e.g. 531770282589356032.
## `hoursPerWeek` (type: `array`):
Restrict to part-time or full-time engagements.
## `projectLength` (type: `array`):
Restrict to one or more expected project lengths.
## `contractToHire` (type: `boolean`):
Show only roles that can convert into a full-time position.
## `maxAgeDays` (type: `integer`):
Only return jobs published within the last N days (e.g. 1 = today, 7 = this week). Results are always newest-first. Applies to the Instant Database.
## `publishedAfter` (type: `string`):
Only return jobs published on/after this date (YYYY-MM-DD). Handy for pulling everything new since your last run. Applies to the Instant Database.
## `monitorMode` (type: `boolean`):
Turn this on and put the Actor on a Schedule (e.g. hourly): each run returns only jobs posted since the previous run for this exact search, so you get a clean feed of new gigs with no duplicates. The first run seeds the cursor (returns current matches), every run after that returns only what's new. Each distinct keyword/filter combination is tracked separately. Legacy option — prefer ♻️ Incremental mode below (change tracking with UPDATED/EXPIRED detection); when both are enabled, Incremental mode takes precedence for the run.
## `minFixedBudget` (type: `integer`):
Only fixed-price jobs with a budget at or above this amount.
## `clientHires` (type: `array`):
Restrict by how many freelancers the client has previously hired.
## `clientLocation` (type: `array`):
One or more client locations. Accepts country names (e.g. "United States", "India") or Upwork region groups (e.g. "Americas", "Europe").
## `clientTimezone` (type: `array`):
One or more client time zones as IANA zone names (e.g. "America/New_York", "Europe/London").
## `includeKeywords` (type: `array`):
Only keep jobs whose title, company or description contains at least one of these (case-insensitive). Filtered rows are never charged.
## `excludeKeywords` (type: `array`):
Drop jobs whose title, company or description contains any of these (case-insensitive).
## `fromDate` (type: `string`):
Only keep jobs posted on or after this date (ISO 8601, e.g. 2026-08-01).
## `toDate` (type: `string`):
Only keep jobs posted on or before this date (ISO 8601). A date-only value means through the end of that day.
## `maxAgeMinutes` (type: `integer`):
Only keep jobs posted within the last N minutes. Empty or 0 = no age limit. Ideal for tight scheduled runs.
## `incrementalMode` (type: `boolean`):
Compare against the previous run and only emit jobs that are NEW, UPDATED, or REAPPEARED — you are only charged for what changed. The first run seeds the baseline. Each emitted row carries `changeType` and `firstSeenAt`.
## `stateKey` (type: `string`):
Optional stable name for this tracked search (e.g. "nurse-toronto"). Leave empty to auto-derive one from the search inputs — same inputs, same baseline.
## `emitUnchanged` (type: `boolean`):
When incremental, also emit rows whose content did not change (charged as normal results).
## `emitExpired` (type: `boolean`):
When incremental, emit a small `changeType: EXPIRED` row for every previously-tracked job that vanished from the source.
## `skipReposts` (type: `boolean`):
When incremental, skip jobs whose content matches a previously-expired posting (employer re-listed the same ad under a new id).
## `resetIncrementalState` (type: `boolean`):
One-shot: drop the stored baseline for this state key at the start of the run.
## `compact` (type: `boolean`):
Emit only the core fields — small payloads for AI-agent / MCP / LLM pipelines.
## `excludeEmptyFields` (type: `boolean`):
Drop null / empty-string / empty-array fields from each record.
## `descriptionMaxLength` (type: `integer`):
Truncate description fields to this many characters (0 = full text). Controls LLM prompt cost and dataset size.
## `telegramBotToken` (type: `string`):
Your bot's token from @BotFather. With Chat ID set, a summary of new jobs is sent after each run.
## `telegramChatId` (type: `string`):
Chat or channel id the bot posts to (e.g. "-1001234567890").
## `slackWebhookUrl` (type: `string`):
Slack incoming-webhook URL (api.slack.com/messaging/webhooks).
## `discordWebhookUrl` (type: `string`):
Discord incoming-webhook URL (Server Settings → Integrations → Webhooks).
## `whatsappAccessToken` (type: `string`):
WhatsApp Cloud API token (Meta Business system user). The recipient must have messaged your business number within the last 24h — Cloud API rule.
## `whatsappPhoneNumberId` (type: `string`):
Your WhatsApp Business phone-number id (numeric, from the Meta dashboard).
## `whatsappTo` (type: `string`):
Recipient phone in E.164 without + (e.g. "14165551234").
## `webhookUrl` (type: `string`):
Receives one JSON POST with { metadata, items } after the run — the universal escape hatch for n8n / Make / Zapier / custom backends.
## `webhookHeaders` (type: `object`):
Optional custom headers for the generic webhook (e.g. {"Authorization": "Bearer …"}).
## `notificationLimit` (type: `integer`):
How many job lines each chat notification includes (1–20). The rest are summarised as a count.
## `notifyOnlyChanges` (type: `boolean`):
With Incremental mode on, notify only about NEW / UPDATED / REAPPEARED jobs.
## `maxItems` (type: `integer`):
Maximum number of jobs to scrape per search.
## `maxConcurrency` (type: `integer`):
Maximum number of pages that can be processed at the same time.
## `minConcurrency` (type: `integer`):
Minimum number of pages that will be processed at the same time.
## `maxRequestRetries` (type: `integer`):
Number of times the crawler will retry a failed request before giving up.
## `proxy` (type: `object`):
Leave empty — the actor already routes all traffic through its own built-in residential proxy at no extra cost to you. Only set this if you want to use your own proxies.
## Actor input object example
```json
{
"startUrls": [
{
"url": "https://www.upwork.com/nx/search/jobs/?q=python+developer&sort=recency"
}
],
"searchQuery": "Software Developer",
"sortBy": "relevance",
"contractToHire": false,
"maxAgeDays": 7,
"publishedAfter": "2026-07-01",
"monitorMode": false,
"incrementalMode": false,
"emitUnchanged": false,
"emitExpired": false,
"skipReposts": false,
"resetIncrementalState": false,
"compact": false,
"excludeEmptyFields": false,
"notificationLimit": 5,
"notifyOnlyChanges": false,
"maxItems": 100,
"maxConcurrency": 10,
"minConcurrency": 1,
"maxRequestRetries": 100
}
```
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"startUrls": [
{
"url": "https://www.upwork.com/nx/search/jobs/?q=python+developer&sort=recency"
}
]
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/upwork-jobs-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = { "startUrls": [{ "url": "https://www.upwork.com/nx/search/jobs/?q=python+developer&sort=recency" }] }
# Run the Actor and wait for it to finish
run = client.actor("memo23/upwork-jobs-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"startUrls": [
{
"url": "https://www.upwork.com/nx/search/jobs/?q=python+developer&sort=recency"
}
]
}' |
apify call memo23/upwork-jobs-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/upwork-jobs-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/ctt9I7mcOMd3d9Pkc/builds/IDgg1asi1SOmmQdX2/openapi.json