# WeChat Official Account Scraper — Articles & Search (`memo23/wechat-official-account-scraper`) Actor
WeChat Official Account (公众号) scraper for China: search public articles by keyword on Sogou, or paste mp.weixin.qq.com links for full text, account id, biz, cover and publish time. Schedule only-new monitoring so repeats are not billed. No WeChat login, no browser. JSON or CSV. $0.003/article.
- **URL**: https://apify.com/memo23/wechat-official-account-scraper.md
- **Developed by:** [Muhamed Didovic](https://apify.com/memo23) (community)
- **Categories:** Social media, News
- **Stats:** 2 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $3.00 / 1,000 article rows
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
Actors are web data automations that power AI and operations. They run on the Apify platform to scrape websites, process data, connect APIs, and automate workflows.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Actors are written with capital "A".
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
The best way to integrate Actors is as follows.
- **AI agents and MCP clients** — the [Apify MCP server](https://docs.apify.com/integrations/mcp.md) at `https://mcp.apify.com` (remote, streamable HTTP, OAuth on first use).
- **Agentic workflows and local Actor development** — [Agent Skills](https://apify.com/.well-known/agent-skills/index.json) with the [Apify CLI](https://docs.apify.com/cli/docs.md): `npm install -g apify-cli`, then `apify login`.
- **JavaScript/TypeScript projects** — the official [JS/TS client](https://docs.apify.com/api/client/js/docs.md): `npm install apify-client`.
- **Python projects** — the official [Python client](https://docs.apify.com/api/client/python/docs.md): `pip install apify-client`.
- **Any other language** — the [REST API](https://docs.apify.com/api/v2.md).
For usage examples, see the [API](#api) section below.
For more details, see Apify documentation as [Markdown index](https://docs.apify.com/llms.txt) and [Markdown full-text](https://docs.apify.com/llms-full.txt).
# README
## WeChat Official Account Scraper — Articles & Search
Search public **WeChat Official Account** articles by keyword, or paste an `mp.weixin.qq.com` link and get the full text. No WeChat login, no browser.
Keyword search goes through Sogou's public WeChat index (`weixin.sogou.com`). Pasted article URLs are read from WeChat's own HTML (`#js_content` plus the account vars on the page).
| Input | Row(s) emitted |
|---|---|
| Keyword (`人工智能`, `Tesla`) | ~10 Sogou cards per page |
| Sogou listing URL (`weixin.sogou.com/weixin?type=2&query=…`) | Same cards |
| Article URL (`mp.weixin.qq.com/s/…`) | One full-text row |
> Pure HTTP. No browser, no WeChat account, no third-party captcha service.
### Why Use This Scraper?
- **Keyword search that returns a usable card.** Title, Official Account name, date, snippet and cover, about 10 results per Sogou page.
- **Full text when you already have the link.** A public `mp.weixin.qq.com/s/…` URL returns body text, `gh_` account id, `__biz`, cover and publish time.
- **Only-new monitoring.** Schedule a watch; IDs already delivered to this account are skipped and not billed.
- **Named watches.** Several schedules can keep separate seen-ID lists via `monitorStateName`.
- **No login.** Public pages only.
### Overview
This actor is for people who need a structured stream of **public Official Account articles** — brand mentions, China news, competitor posts — without a WeChat account.
Every row is article-shaped. A keyword or a Sogou listing URL produces **search cards** (`source: "sogou"`). A pasted `mp.weixin.qq.com` URL produces a **full article** (`source: "wechat"`) with `contentText`. Those two shapes share title / account / date / cover; only the pasted-URL path has body text and `gh_` / `biz`.
Sogou does not put the real `mp.weixin.qq.com` URL on the listing. Following their `/link?url=` hop hits an anti-spider page, so search rows stay cards. Full text needs a real article URL.
This is the public-index actor. It does not return read counts, likes, comments, WeChat Index, or account registration data. Those live behind a paid WeChat data API (sian.agency sells them at $0.04–$1.50 a hit).
### Supported Inputs
| Input | Pattern | Example |
|---|---|---|
| Keyword | any Chinese or English topic | `人工智能`, `Tesla` |
| Sogou listing | `https://weixin.sogou.com/weixin?type=2&query=…` | article search, page `N` |
| Article URL | `https://mp.weixin.qq.com/s/{id}` | full text |
**Not supported**
- WeChat Channels / 视频号
- Official Account *profile* search (`type=1` on Sogou — the public HTML is empty)
- Private chats, Moments, login-gated articles
- Following a Sogou `/link?url=` hop (captcha)
- Read / like / comment counts
### Use Cases
| Who | What they do with the rows |
|---|---|
| Brand / comms | Watch a keyword daily and catch new Official Account mentions |
| China news / research | Pull titles, accounts and dates for a topic without a WeChat login |
| Competitor intel | Track what a known account is publishing, by pasting article URLs |
| Agencies | Feed a monitoring dashboard; only-new mode keeps the bill on fresh posts |
| LLM / RAG pipelines | Ingest `contentText` from pasted URLs, or titles + snippets from search |
### How It Works
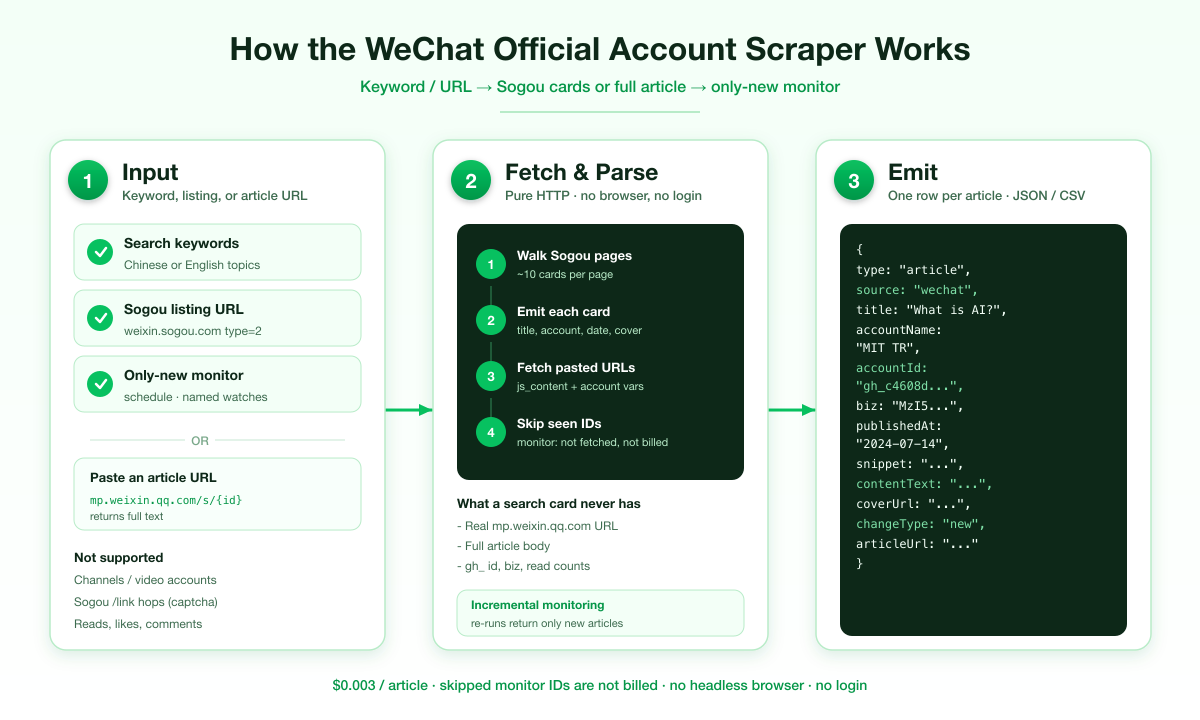
1. Keywords become Sogou `type=2` listing pages (`?page=N`, about 10 cards each).
2. Each card is written as a row: title, account, date, snippet, cover, Sogou link.
3. Pasted `mp.weixin.qq.com` URLs are fetched and parsed from the article page (`og:title`, `nickname`, `user_name`, `biz`, `#js_content`).
4. Optional monitor skips IDs already delivered to this account.
5. Output is one row per article, JSON or CSV.
### Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
| `keywords` | `string[]` | no | Sogou article search. Example: `人工智能`. |
| `articleUrls` | `string[]` | no | Direct WeChat article pages. Full text. |
| `searchUrls` | `string[]` | no | Pasted Sogou listing URLs (`type=2`). |
| `maxItems` | integer | no | Hard cap on emitted rows. Default `50`. Free-tier runs cap at `100`. |
| `maxPages` | integer | no | Sogou pages per keyword. Default `3`, max `10`. |
| `monitorMode` | boolean | no | Only-new. Skipped IDs are not billed. Default `false`. |
| `monitorStateName` | string | no | Name a watch so several schedules keep separate seen-ID lists. |
| `emitBaseline` | boolean | no | First monitoring run: `true` (default) emits current matches; `false` seeds silently. |
| `includeUnchanged` | boolean | no | Also re-emit already-seen rows, tagged `changeType`. Billed. Default `false`. |
| `resetMonitoringState` | boolean | no | Clear the seen-ID list at the start of this run. |
| `proxy` | object | no | Off by default. Sogou and public article pages answered direct in recon. |
#### Example input
Keyword search plus one full article:
```json
{
"keywords": ["人工智能"],
"articleUrls": ["https://mp.weixin.qq.com/s/urnBmheAWXNCDM5A8tAFYg"],
"maxItems": 20,
"maxPages": 2
}
```
Only-new daily watch:
```json
{
"keywords": ["Tesla"],
"monitorMode": true,
"monitorStateName": "tesla-daily",
"maxItems": 50,
"maxPages": 3
}
```
### Output Overview
One dataset row per article. Search cards have `source: "sogou"` and a `sogouUrl`. Pasted pages have `source: "wechat"`, `articleUrl`, `accountId`, `biz` and `contentText`. Monitoring adds `changeType` (`new` / `unchanged`).
### Output Samples
Search card (`source: "sogou"`), from a live run:
```json
{
"type": "article",
"source": "sogou",
"title": "解读人工智能安全治理框架3.0",
"accountName": "极客爱折腾",
"snippet": "2026年9月14日,全国网络安全标准化技术委员会发布《人工智能安全治理框架3.0》…",
"publishedAt": "2026-09-14T13:41:54.000Z",
"coverUrl": "https://mmbiz.qpic.cn/…",
"sogouUrl": "https://weixin.sogou.com/link?url=…"
}
```
Pasted article (`source: "wechat"`), from a live run:
```json
{
"type": "article",
"source": "wechat",
"title": "《麻省理工科技评论》万字长文:什么是人工智能?",
"accountName": "麻省理工科技评论APP",
"accountId": "gh_c4608d233c81",
"biz": "MzI5MTcxMTA3Mw==",
"authorName": "Will•D•Heaven",
"publishedAt": "2024-07-14T14:03:50.000Z",
"articleUrl": "https://mp.weixin.qq.com/s/urnBmheAWXNCDM5A8tAFYg",
"contentText": "…"
}
```
### Key Output Fields
| Group | Fields |
|---|---|
| Identity | `type`, `source`, `title`, `accountName` |
| Account (pasted URL only) | `accountId` (`gh_…`), `biz`, `authorName`, `avatarUrl` |
| When | `publishedAt`, `publishedTs` |
| Body | `snippet` (always when present), `contentText` / `contentHtml` (pasted URL only) |
| Media | `coverUrl` |
| Links | `articleUrl` (pasted URL), `sogouUrl` (search card) |
| Monitor | `changeType`, `scrapedAt` |
### FAQ
**Do I need a WeChat login?**
No. Public Sogou listings and public article pages only.
**Why don't search rows have full text?**
Sogou hides the real article URL behind `/link?url=`, and that hop returns a captcha. Paste the `mp.weixin.qq.com` link when you have it.
**Does this return read counts, likes or comments?**
No. Those are not on the public page. sian.agency sells them via a paid WeChat data API.
**Can I search by Official Account name and get that account's archive?**
Not from the public Sogou `type=1` HTML — it comes back empty. If you already have article URLs from that account, paste them.
**Does this scrape WeChat Channels / 视频号?**
No. Official Account articles only. Channels would be a different actor.
**Does monitoring charge for articles I already have?**
No. In `monitorMode` an ID already in your baseline is skipped and not billed. `maxItems` counts only rows that land in the dataset. The first run after you turn monitoring on returns the current matches and builds that baseline (set `emitBaseline` to `false` if you want the first run silent).
**Can I run two watches from one account?**
Yes. Give each schedule its own `monitorStateName` so their seen-ID lists stay separate.
**Do I need a proxy?**
Usually not. Enable one only if your IP is blocked.
### Pricing
| Event | When | Price |
|---|---|---|
| Actor start | Once per run | $0.005 |
| Article row | Each card or full article written | $0.003 |
Skipped monitor IDs are not billed.
### What this has that the other WeChat actors do not
| | This actor | sian.agency | zen-studio | haketa / Sogou-only |
|---|---|---|---|---|
| Keyword cards (title, account, date, snippet, cover) | Yes | Paid API | Yes | Yes |
| Full text from a pasted `mp.weixin.qq.com` URL | Yes | Yes | Yes | Mixed |
| Only-new monitor + named watches | Yes — skipped IDs not billed | No | No | No |
| Price per row | $0.003 | $0.04 search / $0.14 detail, up to $1.50/account | ~$0.006 | $0.000055–$0.01 |
| Reads, likes, comments, WeChat Index | No | Yes (wxid-native API) | Mixed | No |
If you need read counts, comments or account registration, use sian. That is a different product.
### Support
Found a bug or need a field that isn't here? Open a ticket on the [Issues](https://apify.com/memo23/wechat-official-account-scraper/issues) tab.
### Additional Services
Need this data pushed somewhere specific, or another China social surface covered? Get in touch through the Apify Console.
### Explore More Scrapers
China social in this family: [Douyin](https://apify.com/memo23/douyin-scraper), [RedNote / Xiaohongshu](https://apify.com/memo23/rednote-scraper), [RedNote search](https://apify.com/memo23/rednote-search-scraper). Full list at [apify.com/memo23](https://apify.com/memo23).
### 🤖 For AI Agents & LLM Apps
Compact reference for agents calling this actor via the [Apify MCP server](https://mcp.apify.com) or the Apify API (actor: `memo23/wechat-official-account-scraper`).
**Purpose:** public WeChat Official Account articles — Sogou keyword cards, or full text from pasted `mp.weixin.qq.com` URLs.
**Minimal input:**
```json
{ "keywords": ["人工智能"], "maxItems": 10, "maxPages": 1 }
```
or
```json
{ "articleUrls": ["https://mp.weixin.qq.com/s/urnBmheAWXNCDM5A8tAFYg"] }
```
**Output:** one dataset row per article — `type`, `source`, `title`, `accountName`, `accountId`, `biz`, `authorName`, `snippet`, `publishedAt`, `publishedTs`, `coverUrl`, `avatarUrl`, `articleUrl`, `sogouUrl`, `contentText`, `contentHtml`, `scrapedAt`, `changeType`.
**Behaviors an agent should know:**
- Always set `maxItems`. Default is 50; free-tier runs cap at 100.
- Search rows have no `contentText` and no `articleUrl`. Deduplicate on `sogouUrl` (cards) or `articleUrl` (pasted pages).
- `monitorMode` skips already-delivered IDs and does not bill them. Use `monitorStateName` for separate watches.
- Billing: $0.005 start + $0.003 per emitted row. Skipped monitor IDs are free.
- Unsupported: Channels / 视频号, Sogou account search (`type=1`), `/link` hops, reads/likes/comments.
### ⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Tencent Holdings Limited (WeChat / Weixin / 微信), Sogou Inc., or any of their subsidiaries. All trademarks mentioned are the property of their respective owners.
The scraper accesses only publicly indexed Official Account articles and Sogou's public WeChat search pages — no authenticated endpoints, paid WeChat data APIs, private chats, Moments, or content behind a login wall. It does not follow Sogou `/link` hops that return an anti-spider page. Users are responsible for ensuring their use complies with WeChat and Sogou terms of service, applicable data-protection law (GDPR, CCPA, and PRC personal-information rules), and any contractual obligations of their own organization.
### SEO Keywords
wechat scraper, weixin scraper, wechat official account scraper, 公众号 scraper, 微信公众号, sogou wechat, mp.weixin.qq.com scraper, wechat article api, wechat article search, weixin article scraper, china social scraper, wechat brand monitoring, wechat news scraper, official account monitor, china content intelligence, wechat competitor research, sogou weixin search, wechat public account api, 微信文章 scraper, wechat media monitoring
# Actor input Schema
## `keywords` (type: `array`):
Topics or brand names in Chinese or English. Each keyword is searched on Sogou's public WeChat article index (`weixin.sogou.com`, type=2). Example: `人工智能`. Default: empty.
## `articleUrls` (type: `array`):
Public article links, e.g. `https://mp.weixin.qq.com/s/urnBmheAWXNCDM5A8tAFYg`. These are fetched directly and return full text. Default: empty.
## `searchUrls` (type: `array`):
Paste a Sogou listing such as `https://weixin.sogou.com/weixin?type=2&query=tesla`. Used in addition to keywords. Default: empty.
## `maxItems` (type: `integer`):
Hard cap on emitted rows (search cards + article pages). Default 50. Free-tier runs are capped at 100.
## `maxPages` (type: `integer`):
Sogou serves about 10 articles per page and paginates with `?page=N`. Example: `2`. Default 3, maximum 10.
## `monitorMode` (type: `boolean`):
Skip articles already delivered to this account — they are not billed. First run builds the baseline. Default: false.
## `monitorStateName` (type: `string`):
Name this watch so several schedules keep separate seen-ID lists. Example: `ai-daily`. Only used when monitoring is on. Default: empty (one shared list).
## `resetMonitoringState` (type: `boolean`):
Clear the seen-ID list at the start of this run. Default: false.
## `emitBaseline` (type: `boolean`):
ON (default): first monitoring run returns current matches. OFF: first run seeds silently. Default: true.
## `includeUnchanged` (type: `boolean`):
Also re-emit already-seen rows tagged `changeType`. Billed. Default: false.
## `proxy` (type: `object`):
Optional. Sogou article search and public mp.weixin.qq.com pages answer direct in recon. Enable a proxy only if your IP is blocked.
## Actor input object example
```json
{
"keywords": [
"人工智能"
],
"maxItems": 50,
"maxPages": 3,
"monitorMode": false,
"resetMonitoringState": false,
"emitBaseline": true,
"includeUnchanged": false
}
```
# Actor output Schema
## `articles` (type: `string`):
One row per article: title, Official Account, date, snippet, cover, and full text when a direct article URL was given.
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"keywords": [
"人工智能"
]
};
// Run the Actor and wait for it to finish
const run = await client.actor("memo23/wechat-official-account-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = { "keywords": ["人工智能"] }
# Run the Actor and wait for it to finish
run = client.actor("memo23/wechat-official-account-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"keywords": [
"人工智能"
]
}' |
apify call memo23/wechat-official-account-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,memo23/wechat-official-account-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/md9KpVd0PpHzcQ6sb/builds/0V0VIsIRmOzTqTXDs/openapi.json