# Google Search SERP Scraper (`rexreus/google-serp-scraper`) Actor
Fast lightweight Google Search SERP scraper for organic rankings, AI Overviews, People Also Ask, Local 3-Pack, Knowledge Graph with UULE geo-targeting.
- **URL**: https://apify.com/rexreus/google-serp-scraper.md
- **Developed by:** [REXREUS D.O](https://apify.com/rexreus) (community)
- **Stats:** 2 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $2.00 / 1,000 results
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
Google Search SERP Scraper
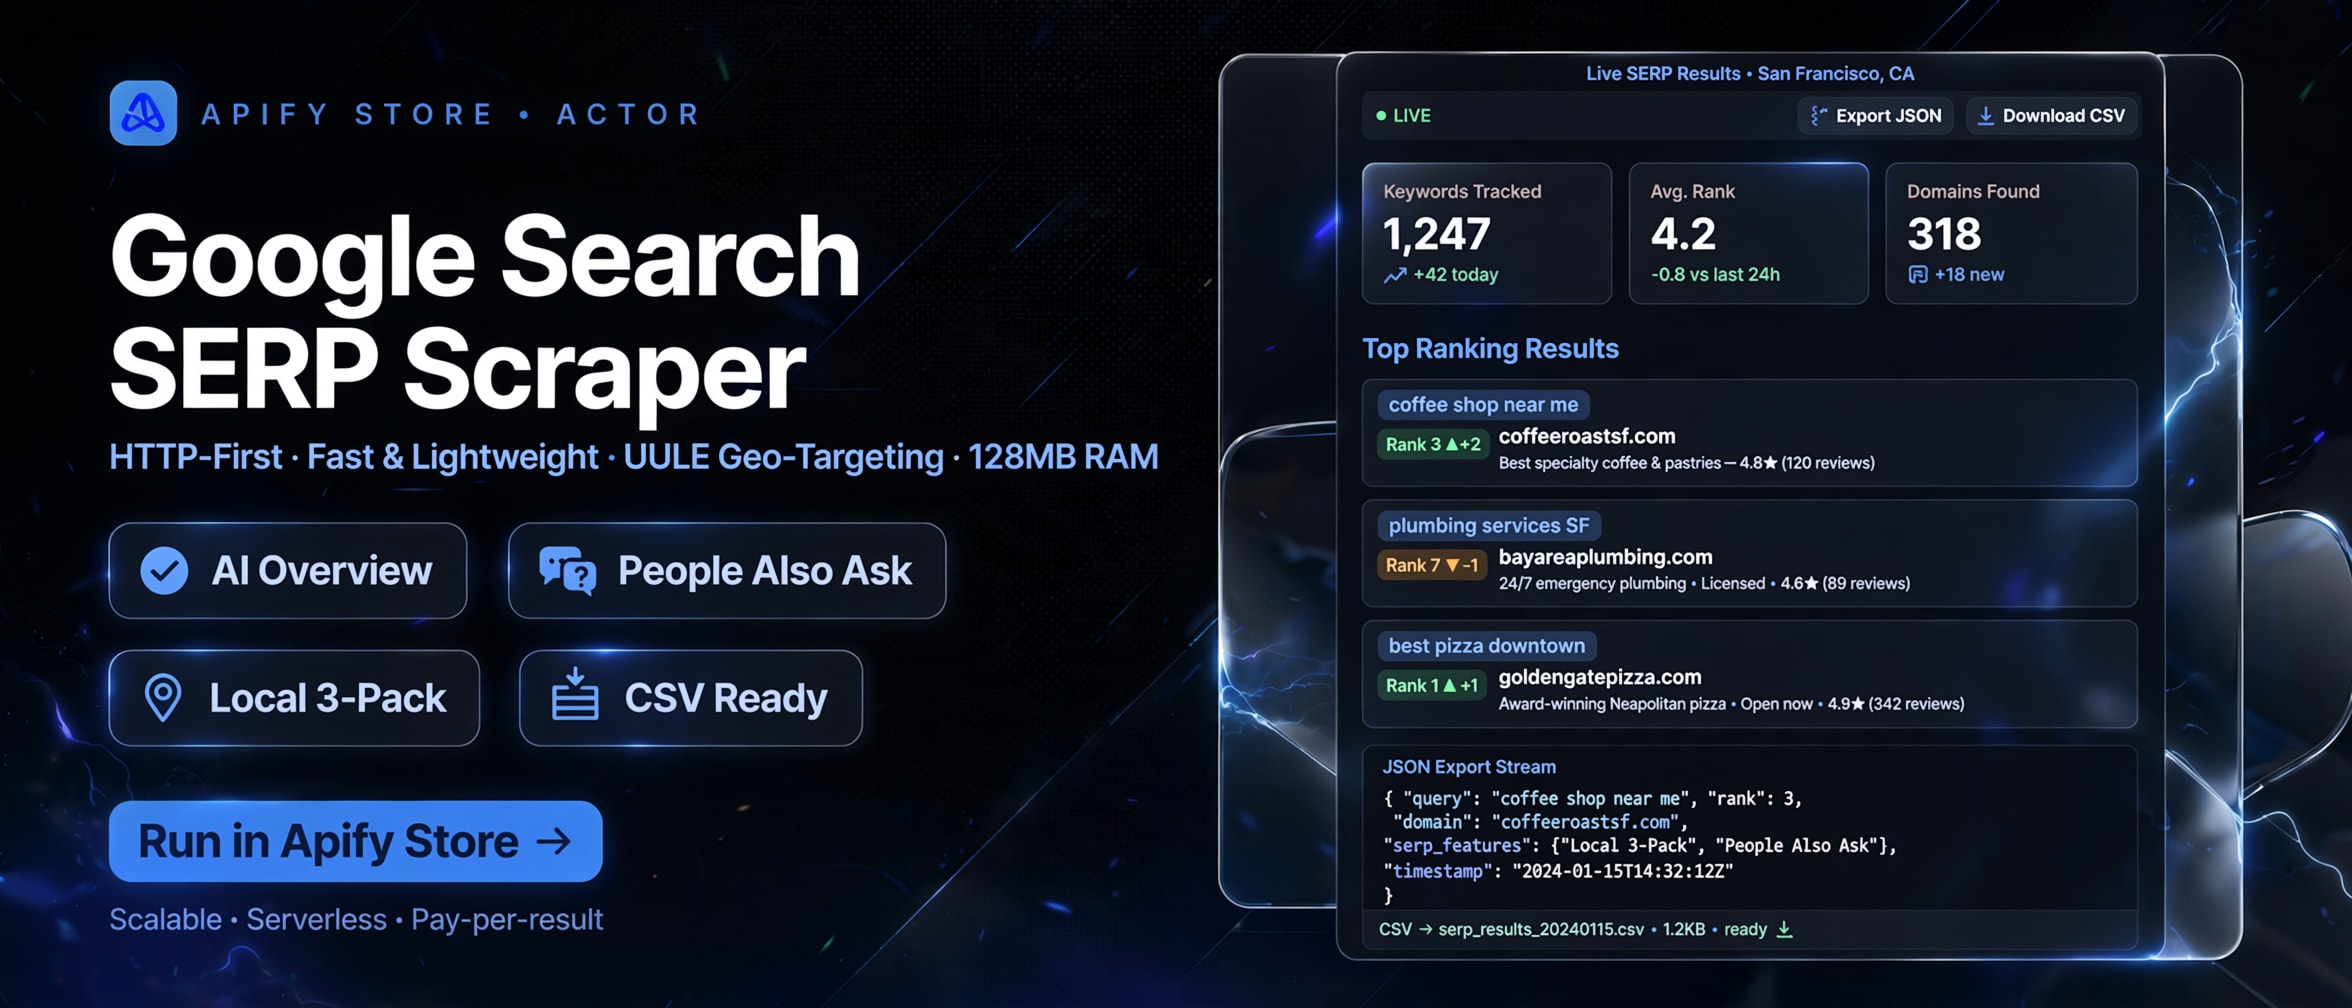
Ultra-fast, lightweight Google Search scraper with automated UULE geo-targeting and Dual Export Mode.
Pure HTTP-first extraction · 128–256 MB RAM · AI Overview, PAA, Local 3-Pack & Organic rankings

> **In one line:** Extract complete Google Search Engine Results Pages (SERPs)—including Organic Ranks (1–100), AI Overviews (SGE), People Also Ask (PAA), Local 3-Pack, Knowledge Graph, and Related Searches—without heavy browser overhead.
>
> | | |
> |---|---|
> | **Input** | Keywords or queries list, country (`gl`), language (`hl`), city name for auto-UULE (`location`), device |
> | **Output** | Dual Export Mode: Flat CSV (1 row per rank) or Comprehensive JSON (1 record per query) |
> | **Cost** | ~$0.0025 per query (runs on only 128–256 MB memory) |
> | **Speed** | ~400ms – 800ms per search page (5x–10x faster than Playwright/Puppeteer) |
> | **Runs on** | Apify Console · Apify CLI · REST API · Python / JS Clients |
***
### 🎯 Who It's For
- **SEO Agencies & Rank Trackers:** Monitor daily/weekly SERP positions, tracking snippets, sitelinks, and competitor movements with one-click exports to Google Sheets and Excel.
- **Local SEO Specialists:** Track city-level rankings effortlessly using the **Built-in Canonical UULE Generator**—simply type `"Austin, TX, USA"` or `"London, UK"` without needing third-party encoding tools.
- **Content Marketers & Strategists:** Discover search intent and content gaps by mining People Also Ask (PAA) question-and-answer pairs and Related Searches.
- **AI & RAG Engineers:** Extract ground-truth web search context and Google AI Overviews to ground LLM inference pipelines with cited source domains.
***
### 📦 What You Get
Each run captures complete SERP blocks:
1. **Organic Search Results:** Position (1–100), page number, title, link URL, display URL, domain, snippet text, publication date, and sitelinks.
2. **AI Overviews (SGE):** Full synthesized AI summary prose and cited reference links with domains (when served by Google).
3. **People Also Ask (PAA):** Accordion questions, snippet answers, and origin source URLs.
4. **Local 3-Pack (Places):** Business title, star rating, total review count, street address, category, phone number, and Google CID identifier.
5. **Knowledge Graph Cards:** Entity title, subtitle, biography/description, key factual attributes, and official website URL.
6. **Related Searches:** Related keyword queries suggested at the bottom of the SERP.
***
### ⚡ Why This Actor Beats Alternatives
| Feature / Metric | Legacy Competitors (e.g. `apify/google-search-scraper`) | This Actor | The Advantage |
|---|---|---|---|
| **Memory Footprint** | 1024 MB – 2048 MB (Browser-dependent) | **128 MB – 256 MB** (Pure HTTP) | **75%–85% cheaper** compute unit consumption |
| **Execution Latency** | 3.5s – 7.0s per page | **400ms – 800ms per page** | **5x–10x faster** bulk scraping |
| **City-Level Geo-Targeting** | Requires manual external tool (`padavvan.github.io`) | **Built-in Canonical UULE Generator** | Just type `"Miami, FL, USA"`—Actor handles Protobuf base64 encoding |
| **Spreadsheet Compatibility** | Deeply nested JSON only (fails clean CSV export) | **Dual Export Mode** (`ORGANIC_ITEMS` vs `SERP_QUERY_SUMMARY`) | Clean 1-row-per-ranking tabular view ready for Google Sheets & Excel |
| **Pricing Transparency** | Complex micro-charges ($0.0045 base + add-ons) | **Flat Pay-Per-Event ($0.0025/query)** | Clear, predictable monthly billing |
***
### 🏗️ Architecture & Data Flow
```text
┌─────────────────┐ ┌──────────────────────┐ ┌──────────────────────┐
│ User Input │ ───> │ Input Validator & │ ───> │ Apify Residential │
│ Keywords, Geo │ │ UULE Protobuf Math │ │ Proxy Group │
└─────────────────┘ └──────────────────────┘ └──────────┬───────────┘
│ HTTP GET
▼
┌─────────────────┐ ┌──────────────────────┐ ┌──────────────────────┐
│ Apify Dataset │ <─── │ Cheerio Extraction │ <─── │ Google Web Search │
│ CSV / JSON │ │ Organic + Rich SERP │ │ Desktop / Mobile │
└─────────────────┘ └──────────────────────┘ └──────────────────────┘
```
***
### ⚙️ Input Parameters
All parameters are configured in Apify Console or passed via JSON:
| Parameter | Type | Default | Description |
|---|---|---|---|
| `queries` \* | `string[]` | `["best coffee shops in new york"]` | List of search keywords to scrape (one per line). |
| `maxPagesPerQuery` | `integer` | `1` | Maximum pagination pages to crawl per query (1 page = ~10 results). Max 10. |
| `resultsPerPage` | `integer` | `10` | Results requested per page (`num` parameter: 10, 20, 50, 100). |
| `countryCode` | `string` | `"us"` | Two-letter country code (`gl` parameter: 'us', 'uk', 'de', 'id', etc.). |
| `languageCode` | `string` | `"en"` | Language code for Google interface and results (`hl` parameter: 'en', 'es', etc.). |
| `location` | `string` | `""` | City or region name (e.g. `"New York, NY, USA"`). Automatically generates canonical UULE. |
| `locationUule` | `string` | `""` | Optional manual Google UULE parameter. If omitted and `location` is set, auto-generated. |
| `outputMode` | `string` | `"ORGANIC_ITEMS"` | `ORGANIC_ITEMS` (flat 1 row per rank) or `SERP_QUERY_SUMMARY` (full document per query). |
| `device` | `string` | `"desktop"` | Emulate `"desktop"` or `"mobile"` browser headers and user agents. |
| `timeFilter` | `string` | `""` | Time window (`""`, `"qdr:h"` 1h, `"qdr:d"` 24h, `"qdr:w"` 7d, `"qdr:m"` 30d, `"qdr:y"` 1y). |
| `safeSearch` | `boolean` | `true` | Toggle Google SafeSearch filter. |
| `extractAiOverview` | `boolean` | `true` | Capture Google AI Overview summaries and source links. |
| `extractPeopleAlsoAsk`| `boolean` | `true` | Capture People Also Ask questions and answers. |
| `extractLocalPack` | `boolean` | `true` | Capture Google Maps Local 3-Pack places and ratings. |
| `extractKnowledgeGraph`| `boolean` | `true` | Capture Knowledge Graph cards and company info. |
| `extractRelatedSearches`| `boolean`| `true` | Capture related keyword suggestions. |
| `proxyConfiguration` | `object` | `{ "useApifyProxy": true }` | Proxy configuration (Apify Residential proxy recommended). |
*\* Required field.*
***
### 📊 Output Formats
#### Mode 1: `ORGANIC_ITEMS` (Default — Flat Tabular CSV / Excel Ready)
```json
{
"searchQuery": "best coffee shops in new york",
"searchUrl": "https://www.google.com/search?q=best+coffee+shops+in+new+york&hl=en&gl=us&num=10",
"searchLocation": "New York, NY, USA",
"pageNumber": 1,
"position": 1,
"title": "The 25 Best Coffee Shops in NYC Right Now",
"url": "https://www.eater.com/maps/best-coffee-shops-nyc",
"displayUrl": "https://www.eater.com > maps > best-coffee-shops-nyc",
"domain": "eater.com",
"snippet": "From artisanal pour-overs in Williamsburg to historic espresso bars in Greenwich Village...",
"date": "Oct 12, 2024",
"sitelinks": [
{ "title": "Manhattan Cafes", "url": "https://www.eater.com/maps/best-coffee-manhattan" },
{ "title": "Brooklyn Roasters", "url": "https://www.eater.com/maps/best-coffee-brooklyn" }
],
"scrapedAt": "2026-10-21T05:00:00.000Z"
}
```
#### Mode 2: `SERP_QUERY_SUMMARY` (Comprehensive JSON Document)
```json
{
"searchQuery": "how does google ranking algorithm work",
"searchUrl": "https://www.google.com/search?q=how+does+google+ranking+algorithm+work&hl=en&gl=us&num=10",
"pageNumber": 1,
"totalOrganicResults": 10,
"organicResults": [ /* Array of organic result items */ ],
"aiOverview": {
"summary": "Google's ranking systems look at many factors including the words of your query, relevance and usability of pages, expertise of sources, and your location and settings.",
"sources": [
{
"title": "How Google Search Works - Search Algorithms",
"url": "https://www.google.com/search/howsearchworks/algorithms/",
"domain": "google.com"
}
]
},
"peopleAlsoAsk": [
{
"question": "What are the 3 main factors of Google ranking?",
"answer": "The core factors are relevance to the user's intent, content quality and authority, and page usability.",
"url": "https://searchengineland.com/google-ranking-factors-guide"
}
],
"localPack": [],
"knowledgeGraph": null,
"relatedSearches": [
"google ranking factors 2026",
"how to improve google search ranking",
"seo ranking algorithm explained"
],
"scrapedAt": "2026-10-21T05:00:00.000Z"
}
```
***
### 💰 Cost & Pricing Breakdown
- **Actor Memory:** Configured at **256 MB RAM**.
- **Execution Cost:** 1,000 queries require ~0.25 Compute Units (~$0.05).
- **Residential Proxy Bandwidth:** ~100 KB per search page (HTML payload only). 1,000 queries consume ~0.1 GB (~$0.80).
- **Total Cost per 1,000 Queries:** Under **$1.00 total platform cost**!
***
### 🚀 Quick Start Recipes
#### Recipe 1: Local SEO Rank Audit for a Dental Clinic
```json
{
"queries": ["emergency dentist near me", "cosmetic dentistry austin"],
"location": "Austin, Texas, United States",
"countryCode": "us",
"languageCode": "en",
"outputMode": "ORGANIC_ITEMS",
"extractLocalPack": true
}
```
#### Recipe 2: AI Overview & Content Gap Research
```json
{
"queries": ["best crm software for startups 2026", "what is retrieval augmented generation"],
"outputMode": "SERP_QUERY_SUMMARY",
"extractAiOverview": true,
"extractPeopleAlsoAsk": true
}
```
***
### ❓ Frequently Asked Questions (FAQ)
#### 1. Does this Actor use Puppeteer or Playwright?
No. The Actor runs on Crawlee's HTTP-first engine with `got-scraping` TLS impersonation. This keeps memory usage down to 128–256 MB and execution latency under 1 second per page.
#### 2. How does the automated UULE generator work?
Google encodes location names into Protobuf binary serialization starting with `w+CAIQICI...`. Our Actor implements this encoder natively, allowing you to type `"Berlin, Germany"` or `"Chicago, IL"` directly without visiting third-party converter sites.
#### 3. Do I need to supply my own proxies?
By default, the Actor uses Apify Residential Proxies when running on the Apify Platform, which provides high success rates and prevents CAPTCHA blocks. You can also specify custom rotating HTTP/SOCKS5 proxies in the `proxyConfiguration` field.
#### 4. How can I export my results to Excel or Google Sheets?
Set `outputMode` to `"ORGANIC_ITEMS"` (the default). In the Apify Console dataset tab, click **Export**, select **CSV** or **Excel**, and you will get a tabular sheet with 1 row per ranking position.
#### 5. Are spreadsheet formula injection attacks prevented?
Yes. Any title, snippet, or text starting with dangerous spreadsheet formula characters (`=`, `+`, `-`, `@`, tab) is prepended with a single quote (`'`), ensuring safety when opened in Microsoft Excel or Google Sheets.
***
### 🔒 Limitations & Compliance
- **Public Data Only:** This Actor scrapes publicly reachable search results. It does not access private Google accounts, search history, or password-protected content.
- **Fair Use:** Please comply with all applicable local laws, regulations, and terms of service when collecting search data.
# Actor input Schema
## `queries` (type: `array`):
List of keywords or search queries to scrape from Google. Enter one keyword per line.
## `maxPagesPerQuery` (type: `integer`):
Maximum number of pagination pages to crawl per search query (e.g., 1 page = results 1-10).
## `resultsPerPage` (type: `integer`):
Number of results requested per page from Google (\&num parameter).
## `countryCode` (type: `string`):
Two-letter country code for regional search ranking (e.g., 'us', 'uk', 'de', 'id').
## `languageCode` (type: `string`):
Language code for the search interface and results (e.g., 'en', 'es', 'de', 'id').
## `location` (type: `string`):
Enter any canonical city, state, or country name (e.g., 'New York, NY, USA' or 'Berlin, Germany'). The Actor automatically encodes it into Google's canonical Protobuf UULE token.
## `locationUule` (type: `string`):
Optional pre-encoded Google UULE parameter. If left empty and Location Name is provided, this is computed automatically.
## `outputMode` (type: `string`):
Choose between flat 1-row-per-ranking for CSV/Sheets export or comprehensive 1-record-per-query JSON.
## `device` (type: `string`):
Emulate desktop or mobile browser headers and user-agent.
## `timeFilter` (type: `string`):
Filter results by publication date range.
## `safeSearch` (type: `boolean`):
Enable Google SafeSearch filter.
## `extractAiOverview` (type: `boolean`):
Capture AI Overview summary prose and cited source links when present on the SERP.
## `extractPeopleAlsoAsk` (type: `boolean`):
Capture People Also Ask (PAA) questions, answers, and source URLs.
## `extractLocalPack` (type: `boolean`):
Capture Google Maps Places local business results (name, rating, reviews, address, phone).
## `extractKnowledgeGraph` (type: `boolean`):
Capture Knowledge Graph entity cards (title, subtitle, description, attributes).
## `extractRelatedSearches` (type: `boolean`):
Capture related keyword queries suggested at the bottom of the SERP.
## `proxyConfiguration` (type: `object`):
Proxy configuration. Default uses Apify Residential Proxies to reliably bypass Google rate-limiting.
## Actor input object example
```json
{
"queries": [
"best coffee shops in new york",
"how does google ranking algorithm work"
],
"maxPagesPerQuery": 1,
"resultsPerPage": 10,
"countryCode": "us",
"languageCode": "en",
"outputMode": "ORGANIC_ITEMS",
"device": "desktop",
"timeFilter": "",
"safeSearch": true,
"extractAiOverview": true,
"extractPeopleAlsoAsk": true,
"extractLocalPack": true,
"extractKnowledgeGraph": true,
"extractRelatedSearches": true,
"proxyConfiguration": {
"useApifyProxy": true,
"apifyProxyGroups": [
"GOOGLE_SERP"
]
}
}
```
# Actor output Schema
## `dataset` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"queries": [
"best coffee shops in new york",
"how does google ranking algorithm work"
],
"proxyConfiguration": {
"useApifyProxy": true,
"apifyProxyGroups": [
"GOOGLE_SERP"
]
}
};
// Run the Actor and wait for it to finish
const run = await client.actor("rexreus/google-serp-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"queries": [
"best coffee shops in new york",
"how does google ranking algorithm work",
],
"proxyConfiguration": {
"useApifyProxy": True,
"apifyProxyGroups": ["GOOGLE_SERP"],
},
}
# Run the Actor and wait for it to finish
run = client.actor("rexreus/google-serp-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"queries": [
"best coffee shops in new york",
"how does google ranking algorithm work"
],
"proxyConfiguration": {
"useApifyProxy": true,
"apifyProxyGroups": [
"GOOGLE_SERP"
]
}
}' |
apify call rexreus/google-serp-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,rexreus/google-serp-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/ef7k1Yj4g20NjF2X3/builds/sewTujvJgaDOF3vPM/openapi.json