# Reddit Profile Scraper (Bulk & Massive) | No Login | No Cookie (`rexreus/reddit-profile-scraper`) Actor
Ultra-fast, lightweight bulk Reddit profile scraper. Extracts karma breakdown, bio, recent posts, comments, and top subreddit affinity analytics without browser overhead.
- **URL**: https://apify.com/rexreus/reddit-profile-scraper.md
- **Developed by:** [REXREUS D.O](https://apify.com/rexreus) (community)
- **Stats:** 3 total users, 2 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $0.50 / 1,000 results
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
Actors are web data automations that power AI and operations. They run on the Apify platform to scrape websites, process data, connect APIs, and automate workflows.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Actors are written with capital "A".
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
The best way to integrate Actors is as follows.
- **AI agents and MCP clients** — the [Apify MCP server](https://docs.apify.com/integrations/mcp.md) at `https://mcp.apify.com` (remote, streamable HTTP, OAuth on first use).
- **Agentic workflows and local Actor development** — [Agent Skills](https://apify.com/.well-known/agent-skills/index.json) with the [Apify CLI](https://docs.apify.com/cli/docs.md): `npm install -g apify-cli`, then `apify login`.
- **JavaScript/TypeScript projects** — the official [JS/TS client](https://docs.apify.com/api/client/js/docs.md): `npm install apify-client`.
- **Python projects** — the official [Python client](https://docs.apify.com/api/client/python/docs.md): `pip install apify-client`.
- **Any other language** — the [REST API](https://docs.apify.com/api/v2.md).
For usage examples, see the [API](#api) section below.
For more details, see Apify documentation as [Markdown index](https://docs.apify.com/llms.txt) and [Markdown full-text](https://docs.apify.com/llms-full.txt).
# README
Reddit Profile Scraper (Bulk & Massive)
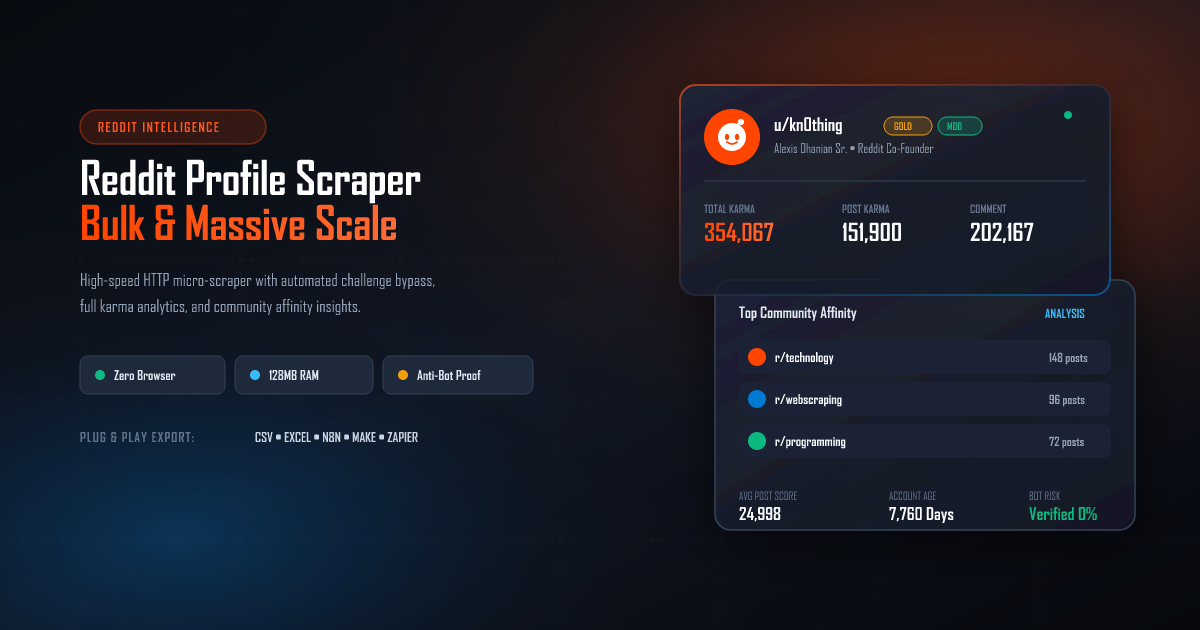
Ultra-fast, lightweight bulk scraper for Reddit profiles, karma analytics, and community affinity.
Pure HTTP micro-scraper · TypeScript · Automatic anti-bot challenge bypass · Zero browser overhead


***
### 💡 Why this Actor?
| Feature | What you get |
|---|---|
| **Zero Browser Overhead** | Operates on pure HTTP requests (Crawlee + `got-scraping`). Uses only 128MB–256MB RAM with zero Puppeteer/Playwright crashes. |
| **Bulk & Massive Ingestion** | Extract 10 to 10,000+ accounts in a single run via arrays, URLs, or multiline text block. |
| **Automated Anti-Bot Bypass** | In-engine pure HTTP challenge solver bypasses Reddit's JavaScript verification and secures persistent session cookies. |
| **Subreddit Affinity Engine** | Aggregates the top 5 communities where the user is active, total posts, and earned karma. Perfect for audience and influencer discovery! |
| **Karma Breakdown & Account Age** | Granular data: post karma, comment karma, awardee karma, awarder karma, and exact account age in days. |
| **Timeline Activity Snapshot** | Optional extraction of recent submissions and comments with upvote count, upvote ratios, and permalinks. |
| **Single-Row Unified Dataset** | Clean, 1-row-per-profile output optimized for direct CSV/Excel export, Google Sheets, Make, Zapier, and n8n pipelines. |
| **Resilient Proxy & Session Pooling** | Automatic session retirement and IP rotation upon encountering HTTP 429 or 403 status codes. |
***
### ⚡ Quick start
#### Apify Console
1. Open the Actor in **Apify Console** and click **Start**.
2. Paste target usernames or Reddit profile URLs into the **Target Usernames** or **Bulk Textarea** field.
3. Click **Save & Start**.
4. Monitor live progress; results stream directly into **Storage → Dataset**.
5. Export to **CSV**, **Excel**, or **JSON** with one click.
***
### 🔄 How it works
```text
┌─────────────────┐ ┌─────────────────────┐ ┌──────────────────────┐
│ Input Target │ ──► │ Input Normalizer │ ──► │ Pure HTTP Reddit │
│ Usernames/URLs │ │ (Dedupe & Sanitize) │ │ Client (JS Solver) │
└─────────────────┘ └─────────────────────┘ └──────────┬───────────┘
│
▼
┌─────────────────┐ ┌─────────────────────┐ ┌──────────────────────┐
│ Apify Dataset │ ◄── │ Flattened Profile │ ◄── │ Affinity Analytics │
│ (CSV/JSON/XLSX) │ │ Record Generator │ │ (Top Communities) │
└─────────────────┘ └─────────────────────┘ └──────────────────────┘
```
***
### 📥 Input
#### Basic Input Example
```json
{
"usernames": ["spez", "https://reddit.com/user/kn0thing"]
}
```
#### Full Bulk Input Example
```json
{
"usernames": ["spez"],
"rawUsernames": "kn0thing\nu/kojima_san\nhttps://reddit.com/u/alex_claw",
"includeRecentPosts": true,
"maxPosts": 10,
"includeRecentComments": true,
"maxComments": 10,
"maxConcurrency": 5,
"proxyConfiguration": {
"useApifyProxy": true,
"apifyProxyGroups": ["RESIDENTIAL"]
}
}
```
#### Field Specification
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
| `usernames` | `array` | No | `["spez", "kn0thing"]` | Array of Reddit usernames or profile URLs. |
| `rawUsernames` | `string` | No | `""` | Multiline textarea to paste hundreds of usernames/URLs (1 per line). |
| `includeRecentPosts` | `boolean` | No | `true` | When enabled, fetches recent posts and computes post analytics. |
| `maxPosts` | `integer` | No | `10` | Maximum recent submissions to extract per user (1 to 50). |
| `includeRecentComments` | `boolean` | No | `true` | When enabled, fetches recent comments and analyzes community engagement. |
| `maxComments` | `integer` | No | `10` | Maximum recent comments to extract per user (1 to 50). |
| `maxConcurrency` | `integer` | No | `5` | Parallel profile extractions (1 to 50). |
| `proxyConfiguration` | `object` | No | `RESIDENTIAL` | Apify Residential proxy recommended for high-volume runs. |
***
### 📤 Output
Each scraped Reddit profile is formatted into a clean, unified record:
```json
{
"username": "kn0thing",
"id": "1wh0",
"url": "https://www.reddit.com/user/kn0thing/",
"displayName": "Alexis Ohanian Sr.",
"bio": "Created Reddit, now doing my life's work building Seven Seven Six.",
"totalKarma": 354067,
"linkKarma": 151900,
"commentKarma": 202167,
"awardeeKarma": 0,
"awarderKarma": 0,
"accountAgeDays": 7760,
"createdAt": "2005-06-06T04:00:00.000Z",
"isGold": true,
"isMod": true,
"isVerified": true,
"hasVerifiedEmail": true,
"isNsfw": false,
"avatarUrl": "https://styles.redditmedia.com/t5_3jgyq/styles/profileIcon_xxxx.png",
"bannerUrl": "https://b.thumbs.redditmedia.com/xxxx.png",
"topSubreddits": "u_kn0thing, iama, blog, gta, maryland",
"topSubredditsDetailed": [
{ "subreddit": "u_kn0thing", "count": 3, "totalScore": 8664 },
{ "subreddit": "iama", "count": 3, "totalScore": 490 },
{ "subreddit": "blog", "count": 1, "totalScore": 115845 }
],
"averagePostScore": 24998.8,
"recentPostsCount": 5,
"recentCommentsCount": 5,
"recentPosts": [
{
"id": "5r43td",
"title": "An Open Letter to the Reddit Community",
"subreddit": "blog",
"score": 115845,
"upvoteRatio": 0.73,
"numComments": 30149,
"createdAt": "2017-01-30T22:34:49.000Z",
"permalink": "https://reddit.com/r/blog/comments/5r43td/an_open_letter_to_the_reddit_community/",
"url": "https://www.reddit.com/r/blog/comments/5r43td/an_open_letter_to_the_reddit_community/"
}
],
"recentComments": [
{
"id": "ox9viy9",
"subreddit": "GTA",
"postTitle": "What would you say Vice City does better than all the other GTA games?",
"bodyPreview": "Came here to say this",
"score": 5,
"createdAt": "2026-07-13T13:52:10.000Z",
"permalink": "https://reddit.com/r/GTA/comments/1uv84qa/what_would_you_say_vice_city_does_better_than_all/ox9viy9/"
}
],
"status": "ok",
"scrapedAt": "2026-09-04T22:19:00.151Z"
}
```
#### Dataset Fields Specification
| Field | Type | Description |
|---|---|---|
| `username` | String | Target username. |
| `id` | String | Reddit internal ID (`t2_*`). |
| `url` | String | Direct profile URL. |
| `displayName` | String | Public display title or vanity name. |
| `bio` | String | User bio or public description. |
| `totalKarma` | Number | Sum of all karma points. |
| `linkKarma` | Number | Karma from submitted links/posts. |
| `commentKarma` | Number | Karma from submitted comments. |
| `accountAgeDays` | Number | Age of the account in days. |
| `createdAt` | String | ISO 8601 UTC creation date. |
| `isGold` | Boolean | Whether account has Reddit Premium. |
| `isMod` | Boolean | Whether user moderates subreddits. |
| `isVerified` | Boolean | Whether profile is verified. |
| `isNsfw` | Boolean | Whether profile is flagged 18+. |
| `avatarUrl` | String | URL to user's profile avatar image. |
| `bannerUrl` | String | URL to user's profile banner image. |
| `topSubreddits` | String | Comma-separated top communities for easy CSV filtering. |
| `topSubredditsDetailed`| Array | Array of objects with `{ subreddit, count, totalScore }`. |
| `averagePostScore`| Number | Average upvote score per recent post. |
| `recentPosts` | Array | Array of recent submission previews. |
| `recentComments`| Array | Array of recent comment previews. |
| `status` | String | `"ok"`, `"not_found"`, or `"error"`. |
***
### 💰 Cost, Limits & Proxy
- **Memory**: Configured at **256MB** (can run on 128MB).
- **Concurrency**: 5 to 20 parallel workers recommended.
- **Proxy Recommendation**:
- **Apify Residential Proxies (`RESIDENTIAL`)**: Required for bulk/massive workloads (100+ profiles) to bypass Reddit's IP-level rate limits and IP blocking.
- **Datacenter Proxies**: Suitable for small batches (1–20 profiles) when paired with lower concurrency.
- **Estimated Costs**:
- \~0.15 Compute Units (CU) per 1,000 scraped profiles (up to 20x cheaper than browser-based scrapers).
***
### 🍲 Recipes
#### Recipe 1: Quick Single Profile Audit
Audit an account for karma breakdown and community affinity:
```json
{
"usernames": ["spez"],
"includeRecentPosts": true,
"maxPosts": 5,
"includeRecentComments": true,
"maxComments": 5
}
```
#### Recipe 2: Bulk Influencer & Lead Generation
Scrape 50+ prospective influencers via raw copy-paste:
```json
{
"rawUsernames": "kn0thing\nspez\nkojima_san\nalex_claw",
"maxConcurrency": 10,
"includeRecentPosts": true,
"maxPosts": 10,
"includeRecentComments": false,
"proxyConfiguration": {
"useApifyProxy": true,
"apifyProxyGroups": ["RESIDENTIAL"]
}
}
```
***
### 🩺 Troubleshooting
| Symptom | Cause | Fix |
|---|---|---|
| `status: "not_found"` | User was deleted, suspended, or shadowbanned by Reddit. | Normal behavior. The Actor records status without failing the run. |
| `STATUS_403_FORBIDDEN` | Target IP blocked by Reddit network security. | Enable Apify Residential Proxies (`RESIDENTIAL`) in proxy configuration. |
| `STATUS_429_RATE_LIMITED` | High request frequency on a single proxy IP. | Lower `maxConcurrency` or ensure Residential Proxy group is active. |
| `0 targets found` | Empty input or malformed usernames. | Check input formats; supply plain usernames (`spez`) or standard profile URLs. |
***
### ❓ FAQ
##### 1. Do I need a Reddit account or API credentials?
**No.** This scraper operates on public profile endpoints. No username, password, or Reddit Developer API credentials are required.
##### 2. Does this use Puppeteer or Playwright?
**No.** It is a pure HTTP micro-scraper. It does not launch headless Chromium, saving gigabytes of memory and keeping compute costs near zero.
##### 3. How does it handle private or 18+ (NSFW) profiles?
Public NSFW profiles are extracted normally with the `isNsfw: true` flag populated. Fully private or quarantined accounts return `"status": "not_found"` gracefully.
##### 4. Can I export data directly to Excel or Google Sheets?
**Yes.** Because every profile is formatted as a single unified record with clean string summaries, exports to CSV and Excel work seamlessly without column corruption.
##### 5. What happens if an account has no posts or comments?
The Actor handles empty activity arrays gracefully, setting post counts to 0 and leaving affinity empty while returning all core profile metadata.
***
### ⚖️ Limitations & Legal
- This Actor extracts public data only.
- Users are responsible for complying with Reddit's Terms of Service and local data privacy laws (e.g., GDPR).
- Does not extract private direct messages, email addresses, or unverified private credentials.
***
### 🚀 Run It
Ready to scrape? Open **Reddit Profile Scraper** on Apify Console and click **Start**.
# Actor input Schema
## `usernames` (type: `array`):
List of Reddit usernames (e.g. 'spez', 'kn0thing') or profile URLs (e.g. 'https://reddit.com/user/spez').
## `rawUsernames` (type: `string`):
Paste hundreds or thousands of usernames or profile URLs, one per line.
## `includeRecentPosts` (type: `boolean`):
Scrapes recent submissions made by the user to extract titles, upvotes, and compute community affinity.
## `maxPosts` (type: `integer`):
Maximum number of recent posts to fetch per profile (default: 10).
## `includeRecentComments` (type: `boolean`):
Scrapes recent comments to analyze comment activity and active subreddits.
## `maxComments` (type: `integer`):
Maximum number of recent comments to fetch per profile (default: 10).
## `maxConcurrency` (type: `integer`):
Maximum parallel profiles to process simultaneously.
## `proxyConfiguration` (type: `object`):
Apify Residential Proxy is strongly recommended to prevent rate limits and 403 blocks.
## Actor input object example
```json
{
"usernames": [
"spez",
"kn0thing"
],
"includeRecentPosts": true,
"maxPosts": 10,
"includeRecentComments": true,
"maxComments": 10,
"maxConcurrency": 5,
"proxyConfiguration": {
"useApifyProxy": true,
"apifyProxyGroups": [
"RESIDENTIAL"
]
}
}
```
# Actor output Schema
## `dataset` (type: `string`):
No description
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"usernames": [
"spez",
"kn0thing"
]
};
// Run the Actor and wait for it to finish
const run = await client.actor("rexreus/reddit-profile-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = { "usernames": [
"spez",
"kn0thing",
] }
# Run the Actor and wait for it to finish
run = client.actor("rexreus/reddit-profile-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"usernames": [
"spez",
"kn0thing"
]
}' |
apify call rexreus/reddit-profile-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,rexreus/reddit-profile-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/Ra7v4UEFIdlDTLeNP/builds/mi2ArDY2sQ45PulGt/openapi.json