# GitHub Scraper - Repos, Users, Orgs, Trending & Search (`topapi/github-scraper`) Actor
Scrape GitHub repositories, developer and organisation profiles from search, links, logins and trending: stars, forks, language shares, topics, license, contributors, used-by, followers, socials and the email shown on the profile. Monitor mode, no token. $0.45 per 1,000 rows.
- **URL**: https://apify.com/topapi/github-scraper.md
- **Developed by:** [Top Api](https://apify.com/topapi) (community)
- **Categories:** Developer tools, Lead generation, Automation
- **Features:** Limited permissions
- **Stats:** 1 total users, 1 monthly users, 80.6% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet
## Pricing
from $0.45 / 1,000 repositories
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
## What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
## How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the [API](#api) section below.
Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).
# README
### What does GitHub Scraper do?
**GitHub Scraper** turns GitHub into rows: repositories, developer profiles and organisation profiles, from a GitHub search, any GitHub link, owner/repo names, logins or the trending pages. Each repository row carries stars, forks, language shares, topics, license, dates, latest release, contributor count and used-by count; each developer row carries name, bio, company, location, website, social accounts, followers, organisations and the email shown on the public profile. Recruiters, devtool sales teams, investors and researchers can use it to find projects and the people behind them. No GitHub token, no login, no browser.
GitHub Scraper - GitHub Repository Scraper - GitHub Profile Scraper - GitHub Trending Scraper - GitHub Search API alternative.
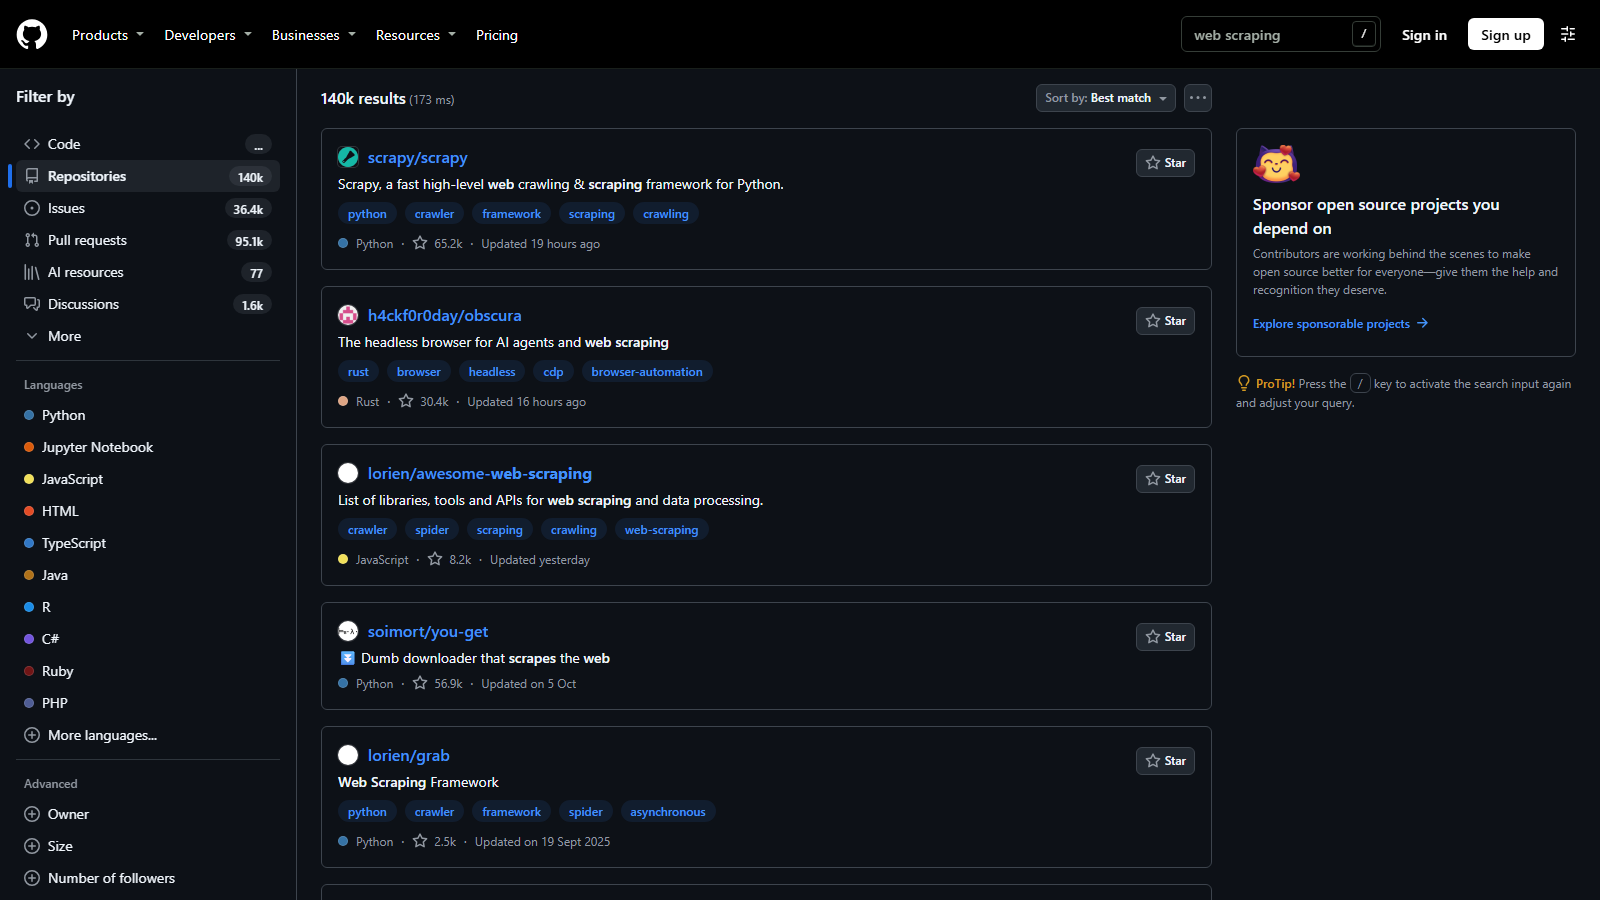 - **Search like GitHub does**: plain words plus GitHub's own qualifiers (`language:`, `stars:`, `topic:`, `location:`, `followers:`), or the filters in the form. Up to 1,000 results per search, and more: a bigger search is split by creation date automatically.
- **Every input in one actor**: repositories, users, organisations, trending repositories and developers, topics, an owner's repositories, an organisation's public members, a user's followers or following, a repository's contributors.
- **Repository details GitHub's search does not give**: language shares in percent, contributor count and top contributors, latest release, "used by" count; README, commit count, watchers and open pull requests with one switch.
- **Developer leads**: social accounts (LinkedIn, X, Bluesky, Mastodon...), the email a developer shows on the public profile, a 0-100 lead score with its reasons and the best contact channel.
- **Monitor mode** for schedules: only repositories and accounts you have not seen before, or also the ones whose stars, forks or followers moved, with the change.
- **Pay per row**: $0.45 per 1,000 rows. Filtered rows, duplicates and links GitHub does not serve are never charged.
### What data can you get from GitHub?
| | | |
|---|---|---|
| 📦 Repository `fullName`, `owner`, `ownerType` | ⭐ `stars`, `forks`, `watchers` | 🐞 `openIssues`, `openPullRequests` |
| 💻 `language` + `languages` (share in %) | 🏷️ `topics` | 📜 `license`, `licenseSpdxId` |
| 📅 `createdAt`, `updatedAt`, `pushedAt` | 🚀 `latestRelease`, `releasesCount` | 🧑💻 `contributorsCount`, `topContributors` |
| 🔗 `dependentsCount` ("used by") | 📄 `readme`, `commitCount` | 🤖 `isAiRelated` |
| 🔥 Trending `rank`, `starsInPeriod`, `builtBy` | 👤 Developer `login`, `name`, `bio` | 🏢 `company`, `location`, `organizations` |
| 📧 `email`, `emailSource`, `emails` | 🌐 `website`, `linkedin`, `twitterUsername`, `socialAccounts` | 👥 `followers`, `following`, `publicRepos` |
| 🗓️ `createdAt` (joined), `hireable` | 🏅 `achievements`, `pinnedRepositories` | 🎯 `leadScore`, `leadTier`, `bestContact` |
| 📈 `contributionsLastYear`, `totalStars`, `topLanguages` | 🏛️ Organisation `email`, `isVerified`, `verifiedDomains` | 🔁 `monitorStatus`, `starsChange` |
### How to scrape GitHub with GitHub Scraper
1. [Create a free Apify account](https://console.apify.com/sign-up) (it comes with free monthly credit).
2. Open **GitHub Scraper** and type a search (e.g. `web scraping`), or paste GitHub links, `owner/repo` names or logins.
3. Pick **Search for**: Repositories, or Users and organisations. Add filters if you want (language, stars, location...).
4. Set **Max results per input** and turn on any extra data (README, owner details, contributors, followers...).
5. Click **Start**. A 50-repository search takes about 5 seconds.
6. Download the rows as JSON, CSV, Excel or HTML, or read them over the API.
### Input
| Parameter | Type | Description |
|---|---|---|
| **🔍 What to scrape** | | |
| `searchQueries` | array | Searches in GitHub's syntax, one per line, e.g. `"llm agent language:python stars:>500"`. Prefilled with `"web scraping"`. |
| `searchType` | string | `repositories` (default) or `users` (people and organisations). |
| `startUrls` | array | Any GitHub link: repository, profile, search page, trending page, topic, `/orgs//people`, `?tab=followers`, `?tab=repositories`, `/graphs/contributors`. |
| `repositories` | array | `owner/repo` names or links. |
| `usernames` | array | Logins or profile links; a person becomes a user row, an organisation an organisation row. |
| `trending`, `trendingType`, `trendingLanguages`, `trendingSince`, `spokenLanguageCode` | | GitHub's trending repositories or developers, per language, today / this week / this month. |
| **🎯 Search filters** (added to every search as GitHub qualifiers) | | |
| `language`, `topics`, `minStars`, `maxStars`, `minForks`, `license` | | Repository filters. |
| `createdAfter`, `createdBefore`, `pushedAfter` | date | Absolute (`2026-01-01`) or relative (`30 days`). |
| `owner`, `includeForks`, `excludeArchived` | | Only one owner's repositories; forks in or out; archived out. |
| `location`, `minFollowers`, `minRepos`, `accountType` | | User search filters. |
| `sort`, `order`, `splitLargeSearches` | | Best match, stars, forks, updated, help-wanted issues, followers, repositories, joined; past 1,000 results (default on). |
| **✂️ Refine results** (applied before the charge) | | |
| `withEmailOnly`, `withWebsiteOnly`, `hireableOnly`, `minLeadScore` | | Keep only the developer rows you can use. |
| `excludeForks`, `filterTopics`, `aiOnly` | | Drop forks, keep topics, keep AI repositories (also on trending and owner lists). |
| **➕ Extra data** (included in the price) | | |
| `includeDetails` | boolean | Language shares, contributors, latest release, used-by. Default **on**. |
| `includeReadme` | boolean | README text, commit count, watchers, releases, tags, open issues and pull requests apart; profile README. |
| `includeOwnerDetails`, `includeRestFields`, `includeContributions`, `includeRepoStats`, `includeStarred`, `includeLeadScore`, `verifyEmail` | boolean | Owner profile on repository rows; join date and gists; contributions in the last year; stars over a developer's repositories; starred repositories; lead score (default on); email domain check. |
| **👥 Related rows** (each a row of its own) | | |
| `includeRepositories` + `maxRepositoriesPerOwner` | | Each delivered account's repositories (most-starred first). |
| `includeMembers`, `includeFollowers`, `includeFollowing` + `maxPeoplePerSource` | | An organisation's public members, a user's followers / following. |
| `includeContributors` + `maxContributorsPerRepo` | | Each delivered repository's top contributors (bots left out). |
| **🔁 Monitoring** | | |
| `monitorMode`, `monitorChanges`, `monitorStoreName`, `resetMonitor` | | Only new rows (and changed ones) since the last run of the same store; a row delivered before without an add-on this run asks for comes back once with it (`monitorStatus: "details"`). |
| **📦 Output** | | |
| `maxResults` | integer | Rows per search, list or trending page (default 100, prefill 50). GitHub serves 1,000 per search and 25 per trending list. 0 = no limit. |
| `maxItems`, `compact`, `dedupe` | | Run total; core fields only (for sheets, AI agents and MCP); one row per record (default). |
| **⚙️ Advanced** | | |
| `proxyConfiguration`, `maxConcurrency` | | Default: the platform's own connection first, then an Apify datacenter session, then residential. |
Field names of other GitHub actors are accepted too (`query`, `queries`, `type`, `repos`, `repoFullNames`, `profileUrls`, `githubIds`, `orgs`, `since`, `timeframe`, `maxItems`...), so switching is a copy-paste.
#### Input JSON
```json
{
"searchQueries": ["llm agent"],
"language": "python",
"minStars": 500,
"pushedAfter": "90 days",
"maxResults": 200
}
```
```json
{
"searchQueries": ["location:berlin followers:>200"],
"searchType": "users",
"withEmailOnly": true,
"includeRepoStats": true,
"maxResults": 100
}
```
```json
{
"trending": true,
"trendingLanguages": ["python", "rust"],
"trendingSince": "weekly",
"monitorMode": true,
"monitorChanges": true
}
```
### Output
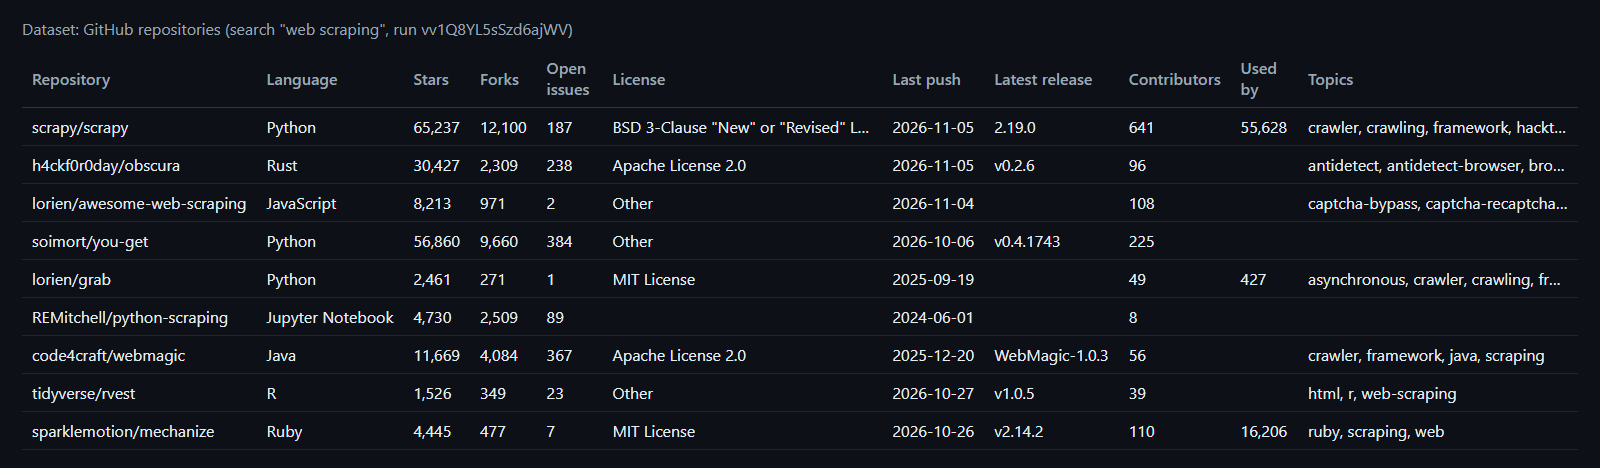 A repository row (search `web scraping`, run `vv1Q8YL5sSzd6ajWV`, shortened):
```json
{
"type": "repository",
"id": 529502,
"fullName": "scrapy/scrapy",
"ownerType": "Organization",
"description": "Scrapy, a fast high-level web crawling & scraping framework for Python.",
"homepage": "https://scrapy.org",
"language": "Python",
"languages": [{ "name": "Python", "percentage": 98.1 }, { "name": "HTML", "percentage": 1.6 }],
"topics": ["crawler", "crawling", "framework", "hacktoberfest"],
"stars": 65237,
"forks": 12100,
"openIssues": 187,
"licenseSpdxId": "BSD-3-Clause",
"createdAt": "2010-02-22T02:01:14.000Z",
"pushedAt": "2026-11-05T11:09:52.000Z",
"latestRelease": { "tagName": "2.19.0", "publishedAt": "2026-09-10T11:48:30.000Z" },
"contributorsCount": 641,
"dependentsCount": 55628,
"foundBy": "search"
}
```
A developer row (login `schacon`, run `Ob57hc53Mo2s8QGUS`, shortened):
```json
{
"type": "user",
"id": 70,
"login": "schacon",
"name": "Scott Chacon",
"company": "@gitbutlerapp",
"location": "Berlin, Germany",
"email": "schacon@gmail.com",
"emailSource": "profileReadme",
"website": "http://scottchacon.com",
"twitterUsername": "chacon",
"followers": 14290,
"publicRepos": 249,
"createdAt": "2008-01-27T17:19:28.000Z",
"contributionsLastYear": 16078,
"totalStars": 5540,
"topLanguages": ["Ruby", "JavaScript", "C", "Objective-C", "Rust"],
"leadScore": 78,
"leadTier": "scorching"
}
```
#### Fields and how often they are filled
Measured on real runs: a 1,000-repository search (`database`, run `SKfWGDsGWk2fFtFMo`), 96 developer rows (user search, add-on runs) and 4 organisations.
| Row | Field | Filled |
|---|---|---|
| Repository | `id`, `fullName`, `stars`, `forks`, `openIssues`, `defaultBranch`, `createdAt`, `updatedAt`, `pushedAt`, `sizeKb`, `contributorsCount` | 100% |
| Repository | `description` 94% · `language` / `languages` 88% · `license` 79% · `topics` 61% · `latestRelease` 50% · `homepage` 47% · `dependentsCount` 16% (GitHub shows "used by" only for packages) | as GitHub has them |
| Repository (README on) | `readme`, `commitCount`, `watchers`, `releasesCount`, `tagsCount` 100% · `openPullRequests` 79% | 33 rows |
| Developer | `followers`, `following`, `publicRepos`, `leadScore` 99-100% · `pinnedRepositories` 93% · `name` 84% · `achievements` 83% · `location` 73% · `bio` 69% · `company` 65% · `website` 53% · `socialAccounts` 53% · `organizations` 46% · `twitterUsername` 33% · `linkedin` 16% · `email` 5% | 96 rows |
| Developer (REST fields) | `createdAt`, `publicGists` 74% (GitHub answers 60 of these lookups an hour per IP) · `hireable` 11% (true only when the developer says so) | |
| Organisation | `name`, `description`, `followers`, `publicRepos`, `isVerified`, `topLanguages` 100% · `website` 75% · `email` 50% | 4 rows |
| Trending | `rank`, `starsInPeriod`, `starsGrowthPercent`, `builtBy` 100% | 10 rows |
Every field is described in the dataset schema (Output tab). A field GitHub does not show a signed-out visitor is `null`, never a made-up value.
### How can I use GitHub data?
- 🧑💼 **Recruiters**: developers by location, language and followers, with their public email, LinkedIn, contributions and top languages.
- 💼 **Devtool sales and DevRel**: the maintainers and contributors of the projects your product plugs into, with company and best contact.
- 📈 **Investors and analysts**: trending repositories with stars gained per day, week or month; monitor mode for star growth.
- 🔍 **Open-source research**: every repository on a topic or language with license, release cadence, contributors and used-by count.
- 🤖 **AI and agents**: README text for RAG, `isAiRelated` to find AI projects, compact rows for MCP tools.
- 🛡️ **Supply-chain checks**: license, archived flag, last push and latest release for a list of dependencies.
### How much does it cost to scrape GitHub?
$0.45 per 1,000 rows: **$0.00045 per repository, user or organisation row**. No start fee. Apify platform usage is included in this price; there is nothing else to pay.
| Rows | Price |
|---|---|
| 10 | $0.0045 |
| 100 | $0.045 |
| 1,000 | $0.45 |
| 10,000 | $4.50 |
The extra data switches are included in the row price. Related rows (an owner's repositories, members, followers, contributors) are rows like any other. Duplicates, filtered rows, rows seen in an earlier monitor run and links GitHub does not serve are not charged. Set a spending limit on the run and it stops there (measured: a $0.01 limit delivered 22 rows and charged 22).
### Integrations, API, scheduling & MCP
- **Schedule it**: Apify Schedules run it daily or hourly; with monitor mode on, each run returns only what is new.
- **Webhooks** notify your system when a run ends; **Make, Zapier, n8n, Google Sheets, Slack** and other integrations pick the rows up.
- **API**: start runs and read rows with the [Python](https://apify.com/topapi/github-scraper/api/python) or [JavaScript](https://apify.com/topapi/github-scraper/api/javascript) client, or plain HTTP.
- **MCP**: AI agents can call GitHub Scraper as a tool through [Apify's MCP server](https://apify.com/topapi/github-scraper/api/mcp); `compact` keeps the rows small.
### More scrapers from TopApi
| | | |
|---|---|---|
| 🧰 [Website Technology Scraper](https://apify.com/topapi/website-technology-scraper) - the tech stack behind a company's website | 📝 [Website Content Crawler](https://apify.com/topapi/website-content-crawler) - docs and sites as clean text and Markdown for RAG | 💼 [Indeed Jobs Scraper](https://apify.com/topapi/indeed-jobs-scraper) - who is hiring developers, with salary |
| 🐦 [Twitter Profile Scraper](https://apify.com/topapi/x-profile-scraper) - the X profiles behind a developer's handle | 🦋 [Bluesky Scraper](https://apify.com/topapi/bluesky-scraper) - posts, profiles and followers on Bluesky | 📰 [Substack Scraper](https://apify.com/topapi/substack-scraper) - newsletters and their authors' socials |
All TopApi actors: [apify.com/topapi](https://apify.com/topapi).
### Limits & empty runs
- **Per search**: GitHub returns at most 1,000 results; with **Go past 1,000 results** on (default), a bigger search is split by creation date.
- **Search speed**: GitHub allows 10 searches a minute per IP without a token (100 rows each). The run waits for GitHub's reset instead of failing; a 1,000-row search took 92-95 s on runs that did not wait.
- **Repository details**: GitHub answers about 1,000 detail requests per IP before it refuses them for several minutes; at the first refusal the run moves those requests to an Apify datacenter connection (then residential on bigger runs). A small run gives that detour about 1.5 seconds; if it is slower, or GitHub still refuses, the row is delivered without languages, contributors and release (the status message counts them).
- **REST fields** (join date, gists, hireable): 60 lookups an hour per IP, so large runs fill them for the first ~55 people.
- **Emails**: GitHub shows a developer's profile email only to signed-in visitors. This actor reports an email when the developer wrote it on the public profile (bio or profile README) and an organisation's listed email. It does not read emails out of commits.
- **Not available signed out**: stargazer lists and code search.
- **Empty runs** end with a status that says why ("GitHub found nothing for this search", "nothing new since the last monitor run"); nothing is charged.
### FAQ
#### How much does GitHub Scraper cost?
$0.00045 per row ($0.45 per 1,000), no start fee. A 50-repository search costs $0.0225.
#### How many GitHub repositories can GitHub Scraper return?
Up to 1,000 per search from GitHub, more when the search is split by date, as many searches per run as you like. Trending pages hold up to 25 repositories or developers each.
#### Does GitHub Scraper need a GitHub token or a login?
No. It reads what GitHub shows a signed-out visitor and GitHub's public search, with no token, cookie or account.
#### Can GitHub Scraper find developers' emails?
It returns the email a developer published on the public profile page (in the bio or profile README) and an organisation's public email, with `emailSource` saying where it came from. In our test rows 5% of developers and half of the organisations had one; `withEmailOnly` keeps only those.
#### Can I monitor GitHub repositories with GitHub Scraper on a schedule?
Yes. Turn on monitor mode and schedule the run: each run returns only new repositories or accounts, and with **Also changed rows** the ones whose stars, forks or followers moved, with `starsChange` and `previous`. A poll with nothing new delivers no rows, so nothing is charged.
#### Can GitHub Scraper scrape GitHub trending?
Yes: trending repositories or developers, any language, today, this week or this month, with `rank`, `starsInPeriod`, `starsGrowthPercent` and `builtBy`.
#### Can I use GitHub Scraper with the Apify API?
Yes. Start a run with the input JSON above and read the dataset with the Python or JavaScript client, or connect it to Make, Zapier or n8n.
#### Can AI agents use GitHub Scraper through MCP?
Yes, through Apify's MCP server. Use `compact` for short rows.
#### Why did GitHub Scraper return no results?
The search matched nothing, every row was filtered out, or (monitor mode) nothing was new. The status message says which, and nothing is charged.
#### Can GitHub Scraper get a repository's contributors or an organisation's members?
Yes: paste the repository's contributors link or the organisation's people link, or turn on **Contributors** / **Organisation members** under Related rows.
### Your feedback
Something missing or wrong? Open an issue on the [Issues tab](https://apify.com/topapi/github-scraper/issues/open) and we will look at it.
# Actor input Schema
## `searchQueries` (type: `array`):
Searches, one per line, in GitHub's own search syntax, e.g. "web scraping", "llm agent language:python stars:>500", "location:berlin followers:>100" (with Search for: Users). Each line is its own search.
## `searchType` (type: `string`):
What the searches above look for: repositories, or users and organisations (people rows with their full profile).
## `startUrls` (type: `array`):
Any GitHub link: a repository, a user or organisation profile, a search page (github.com/search?q=..\&type=repositories), a trending page, a topic (github.com/topics/cli), an organisation's people page, a user's followers tab or a repository's contributors graph.
## `repositories` (type: `array`):
Repositories as owner/repo or links, one per line, e.g. "apify/crawlee", "https://github.com/facebook/react". Each comes back as one repository row.
## `usernames` (type: `array`):
GitHub logins or profile links, one per line, e.g. "torvalds", "https://github.com/apify". A person comes back as a user row, an organisation as an organisation row.
## `trending` (type: `boolean`):
Also read GitHub's trending page (github.com/trending): up to 25 repositories or developers per language and period, with their rank and stars gained.
## `trendingType` (type: `string`):
Trending repositories or trending developers (developer rows are full user profiles with their popular repository).
## `trendingLanguages` (type: `array`):
Programming languages for the trending lists, one per line, as GitHub names them, e.g. "python", "rust", "c++". Empty = all languages.
## `trendingSince` (type: `string`):
Trending today, this week or this month.
## `spokenLanguageCode` (type: `string`):
Trending repositories whose README is in this spoken language, as a two-letter code, e.g. "en", "zh", "es". Empty = any.
## `language` (type: `string`):
Only repositories in this language, or users who write it, e.g. "python", "typescript", "go". Added to every search as language:.
## `topics` (type: `array`):
Only repositories tagged with every one of these topics, e.g. "cli", "llm". Added as topic:.
## `minStars` (type: `integer`):
Only repositories with at least this many stars (stars:>=). Also applied to repositories from links, trending and owner lists.
## `maxStars` (type: `integer`):
Only repositories with at most this many stars, e.g. 500 to find young projects. Empty = no limit.
## `minForks` (type: `integer`):
Only repositories with at least this many forks (forks:>=).
## `license` (type: `string`):
Only repositories under this license.
## `createdAfter` (type: `string`):
Only repositories (or accounts) created on or after this date, e.g. 2026-01-01, or a relative window such as "30 days".
## `createdBefore` (type: `string`):
Only repositories (or accounts) created on or before this date.
## `pushedAfter` (type: `string`):
Only repositories with a push on or after this date (actively maintained), e.g. 2026-06-01 or "90 days".
## `owner` (type: `string`):
Only repositories owned by this user or organisation login, e.g. "microsoft" (user:).
## `includeForks` (type: `boolean`):
GitHub's search leaves forks out; turn on to include them (fork:true).
## `excludeArchived` (type: `boolean`):
Leave out archived (read-only) repositories.
## `location` (type: `string`):
User searches: only accounts whose profile location matches, e.g. "Berlin", "San Francisco" (location:).
## `minFollowers` (type: `integer`):
Only users with at least this many followers (followers:>= on user searches; also applied to people from lists).
## `minRepos` (type: `integer`):
Only users with at least this many public repositories (repos:>=).
## `accountType` (type: `string`):
User searches: people, organisations or both.
## `sort` (type: `string`):
GitHub's order for searches. Stars, forks, updated and help-wanted issues sort repositories; followers, repositories and joined sort users.
## `order` (type: `string`):
Highest / newest first, or the reverse.
## `splitLargeSearches` (type: `boolean`):
GitHub returns at most 1,000 results per search. When a search matches more and Max results asks for more, it is split by creation date so each part stays under the cap.
## `withEmailOnly` (type: `boolean`):
Keep only users and organisations that show an email on their public profile (bio, profile README or the organisation's email). Others are not delivered or charged.
## `withWebsiteOnly` (type: `boolean`):
Keep only users and organisations with a website on their profile.
## `hireableOnly` (type: `boolean`):
Keep only users who mark themselves available for hire (needs Join date and REST fields on; GitHub answers 60 of those lookups an hour per IP).
## `minLeadScore` (type: `integer`):
Keep only users whose lead score (0-100: followers, stars, repositories, email, LinkedIn, website, company) is at least this, e.g. 40.
## `excludeForks` (type: `boolean`):
Drop forked repositories from links, trending and owner lists too.
## `filterTopics` (type: `array`):
Keep only repositories with at least one of these topics, e.g. "llm", "rag" (applied after GitHub's answer, so it works on trending and owner lists).
## `aiOnly` (type: `boolean`):
Keep only repositories about AI (topics or description mention AI, LLMs, agents, RAG, machine learning and the like). Every row carries isAiRelated either way.
## `includeDetails` (type: `boolean`):
Language shares, contributor count and top contributors, latest release and used-by count (one small request per repository, included in the price).
## `includeReadme` (type: `boolean`):
Reads each repository's page: README as plain text (up to 20,000 characters), commit count, open issues and pull requests apart, watchers, releases and tags. On user and organisation rows: the profile README.
## `includeOwnerDetails` (type: `boolean`):
On repository rows, the owner's name, company, website, location, email, bio, X handle, followers and public repositories (one profile read per owner).
## `includeRestFields` (type: `boolean`):
Join date, last update, gists, hireable and exact follower counts from GitHub's REST API. Without a token GitHub answers 60 of these an hour per IP, so large runs fill them for the first ~55 people.
## `includeContributions` (type: `boolean`):
Each user's public contributions in the last year (one request per user).
## `includeRepoStats` (type: `boolean`):
totalStars, totalForks and topLanguages over each user's or organisation's own top 60 repositories (two requests per person).
## `includeStarred` (type: `boolean`):
The 30 repositories each user starred most recently (interests and tech stack).
## `includeLeadScore` (type: `boolean`):
leadScore 0-100, leadTier (cold / warm / hot / scorching), leadReasons and bestContact on user rows.
## `verifyEmail` (type: `boolean`):
emailDomainHasMx: whether the email's domain has mail servers (a DNS check, not a mailbox test).
## `includeRepositories` (type: `boolean`):
For every user or organisation delivered, also deliver its repositories (most-starred first, up to the number below), each charged as a repository row.
## `maxRepositoriesPerOwner` (type: `integer`):
Repositories delivered per owner when the option above is on.
## `includeMembers` (type: `boolean`):
For every organisation delivered, also deliver its public members as user rows.
## `includeFollowers` (type: `boolean`):
For every user delivered, also deliver their followers as user rows.
## `includeFollowing` (type: `boolean`):
For every user delivered, also deliver the accounts they follow as user rows.
## `maxPeoplePerSource` (type: `integer`):
Members, followers or following delivered per account.
## `includeContributors` (type: `boolean`):
For every repository delivered, also deliver its top contributors as user rows (bots left out).
## `maxContributorsPerRepo` (type: `integer`):
Top contributors delivered per repository.
## `monitorMode` (type: `boolean`):
Deliver only repositories and accounts not delivered by an earlier monitor run of the same store. Pairs with a daily schedule.
## `monitorChanges` (type: `boolean`):
In monitor mode, also deliver known repositories whose stars or forks moved (and accounts whose followers or repositories moved), with starsChange, forksChange or followersChange.
## `monitorStoreName` (type: `string`):
Name of the key-value store that remembers what was delivered. Use one name per watch list.
## `resetMonitor` (type: `boolean`):
Forget what the store remembers and start over.
## `maxResults` (type: `integer`):
Rows per search, trending list, owner list or people list. GitHub serves 1,000 per search (more with Go past 1,000 results) and 25 per trending list. 0 = no limit.
## `maxItems` (type: `integer`):
Stop after this many rows across all inputs (all row types). 0 = no limit.
## `compact` (type: `boolean`):
Core fields only (name, link, stars, language, contact fields...) - trimmed for spreadsheets, AI agents and MCP.
## `dedupe` (type: `boolean`):
A repository or account found by several inputs is delivered (and charged) once. Turn off to get one row per input.
## `proxyConfiguration` (type: `object`):
Default: the platform's own connection first, then an Apify datacenter session, then residential if GitHub keeps refusing. Set your own proxy only if you need a specific exit.
## `maxConcurrency` (type: `integer`):
Requests in flight at once (GitHub's search is always one at a time).
## Actor input object example
```json
{
"searchQueries": [
"web scraping"
],
"searchType": "repositories",
"trending": false,
"trendingType": "repositories",
"trendingSince": "daily",
"license": "any",
"includeForks": false,
"excludeArchived": false,
"accountType": "",
"sort": "best-match",
"order": "desc",
"splitLargeSearches": true,
"withEmailOnly": false,
"withWebsiteOnly": false,
"hireableOnly": false,
"excludeForks": false,
"aiOnly": false,
"includeDetails": true,
"includeReadme": false,
"includeOwnerDetails": false,
"includeRestFields": true,
"includeContributions": false,
"includeRepoStats": false,
"includeStarred": false,
"includeLeadScore": true,
"verifyEmail": false,
"includeRepositories": false,
"maxRepositoriesPerOwner": 30,
"includeMembers": false,
"includeFollowers": false,
"includeFollowing": false,
"maxPeoplePerSource": 50,
"includeContributors": false,
"maxContributorsPerRepo": 10,
"monitorMode": false,
"monitorChanges": false,
"monitorStoreName": "github-monitor",
"resetMonitor": false,
"maxResults": 50,
"compact": false,
"dedupe": true,
"proxyConfiguration": {
"useApifyProxy": true
},
"maxConcurrency": 8
}
```
# Actor output Schema
## `results` (type: `string`):
One item per GitHub repository (type "repository"), user ("user") or organisation ("organization").
# API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
## JavaScript example
```javascript
import { ApifyClient } from 'apify-client';
// Initialize the ApifyClient with your Apify API token
// Replace the '' with your token
const client = new ApifyClient({
token: '',
});
// Prepare Actor input
const input = {
"searchQueries": [
"web scraping"
],
"maxResults": 50
};
// Run the Actor and wait for it to finish
const run = await client.actor("topapi/github-scraper").call(input);
// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
console.dir(item);
});
// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
```
## Python example
```python
from apify_client import ApifyClient
# Initialize the ApifyClient with your Apify API token
# Replace '' with your token.
client = ApifyClient("")
# Prepare the Actor input
run_input = {
"searchQueries": ["web scraping"],
"maxResults": 50,
}
# Run the Actor and wait for it to finish
run = client.actor("topapi/github-scraper").call(run_input=run_input)
# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
print(item)
# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
```
## CLI example
```bash
echo '{
"searchQueries": [
"web scraping"
],
"maxResults": 50
}' |
apify call topapi/github-scraper --silent --output-dataset
```
## MCP server setup
```json
{
"mcpServers": {
"apify": {
"type": "http",
"url": "https://mcp.apify.com/?tools=fetch-actor-details,topapi/github-scraper"
}
}
}
```
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer ` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
## OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/xXfxyLJg7rioroF6W/builds/KsxnT8Z905C0ATUDd/openapi.json