# Facebook Search Scraper (`apify/facebook-search-scraper`) Actor

Scrape Facebook search results: posts, pages, profiles and reels. Add a keyword and extract search results like pages details, profile information, recent posts or reels. Export scraped data, schedule via API, integrate with other tools or AI workflows.

- **URL**: https://apify.com/apify/facebook-search-scraper.md
- **Developed by:** [Apify](https://apify.com/apify) (Apify)
- **Categories:** Social media
- **Stats:** 16,500 total users, 929 monthly users, 100.0% runs succeeded, 180 bookmarks
- **User rating**: 4.96 out of 5 stars

## Pricing

from $3.00 / 1,000 facebook results

This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.
Since this Actor supports Apify Store discounts, the price gets lower the higher subscription plan you have.

Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event

## What's an Apify Actor?

An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.

Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.

## How to integrate an Actor?

If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.

Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.

For examples already wired to this Actor's own input schema, see the [API](#api) section below.

Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).

# README

### 🕵️‍♀️ What is Facebook Search Scraper?

Facebook Search Scraper is an easy-to-use scraping tool that allows you to **scrape Facebook pages by keywords**. This tool will help you extract Facebook page contact information: addresses, email, likes, websites, check-ins, and phone numbers.

#### 🔎 What can this Facebook scraper do?

Facebook Search Scraper is a data extraction tool created to go beyond the limitations of Facebook API. If a Facebook page matches your search query, the scraper will extract that page's data. With this scraping tool, you can:

🗝 Scrape a bunch of Facebook pages or profiles **by keyword**

📍 Specify Facebook scraping **by location** (indicate country, city, province)

⬇️ **Download Facebook search data** in Excel, CSV, JSON, and other formats

🦾 Export search data using API or integrate it with apps and platforms

> If you need details from **specific Facebook Pages**, you can use [Facebook Pages Scraper](https://apify.com/apify/facebook-pages-scraper) 🔗, which scrapes available **details from each Facebook page based on its URL**. And if you want to scrape contact details from **specific Facebook Pages by handles or URLs**, you can use [Facebook Pages Contact Info Scraper](https://apify.com/apify/facebook-page-contact-information) 📱.

### 🔑 What data can Facebook Search Scraper extract?

Facebook Search Scraper crawls specified **search queries and locations** and extracts Facebook pages details such as:

<table>
<tr>
<td>📇 Page name and URL</td>
<td>📑 Page categories</td>
</tr>
<tr>
<td>🌐 Website</td>
<td>📧 Email address</td>
</tr>
<tr>
<td>🏠 Address</td>
<td>📱 Phone number</td>
</tr>
<tr>
<td>👥 Followers</td>
<td>👍 Likes</td>
</tr>
<tr>
<td>🔗 Social media links</td>
<td>⭐ Rating and rating count</td>
</tr>
<tr>
<td>🆔 Facebook ID and page description</td>
<td>🗣 Messenger link</td>
</tr>
<tr>
<td>📅 Creation date</td>
<td>📢 Ad status</td>
</tr>
</table>

### 🌐 How do I use Facebook Search Scraper?

Facebook Search Scraper is designed to be user-friendly, even for those who have never extracted data from the web before. Here’s how you can use Facebook Search Scraper to extract pages data from Facebook search results:

1. [Create](https://apify.com/sign-up) a free Apify account.
2. Open [Facebook Search Scraper](https://apify.com/apify/facebook-search-scraper).
3. Enter your search term and location.
4. Click the “Start” button and wait for the data to be extracted.
5. Download your data in JSON, CSV, Excel, XML or HTML.

For a step-by-step guide on how to scrape pages from Facebook Search, follow our video guide:

https://www.youtube.com/watch?v=lhXX20sYTK0

### 💸 How much does it cost to scrape Facebook Search results?

Facebook Search Scraper uses the [Pay-Per-Event](https://docs.apify.com/platform/actors/running/actors-in-store#pay-per-event) model, making it simple to calculate costs. Here’s the breakdown:

- $0.03 for starting the scraper
- $0.012 for every page or profile

Apify's free plan gives you $5 of prepaid credits. That means for that amount of credits you can start the Actor 1x and scrape 416 pages or profiles. Or start the Actor 2x and scrape 332 pages or profiles each time. You get the idea - it’s flexible and transparent.

### ⬇️ Input example

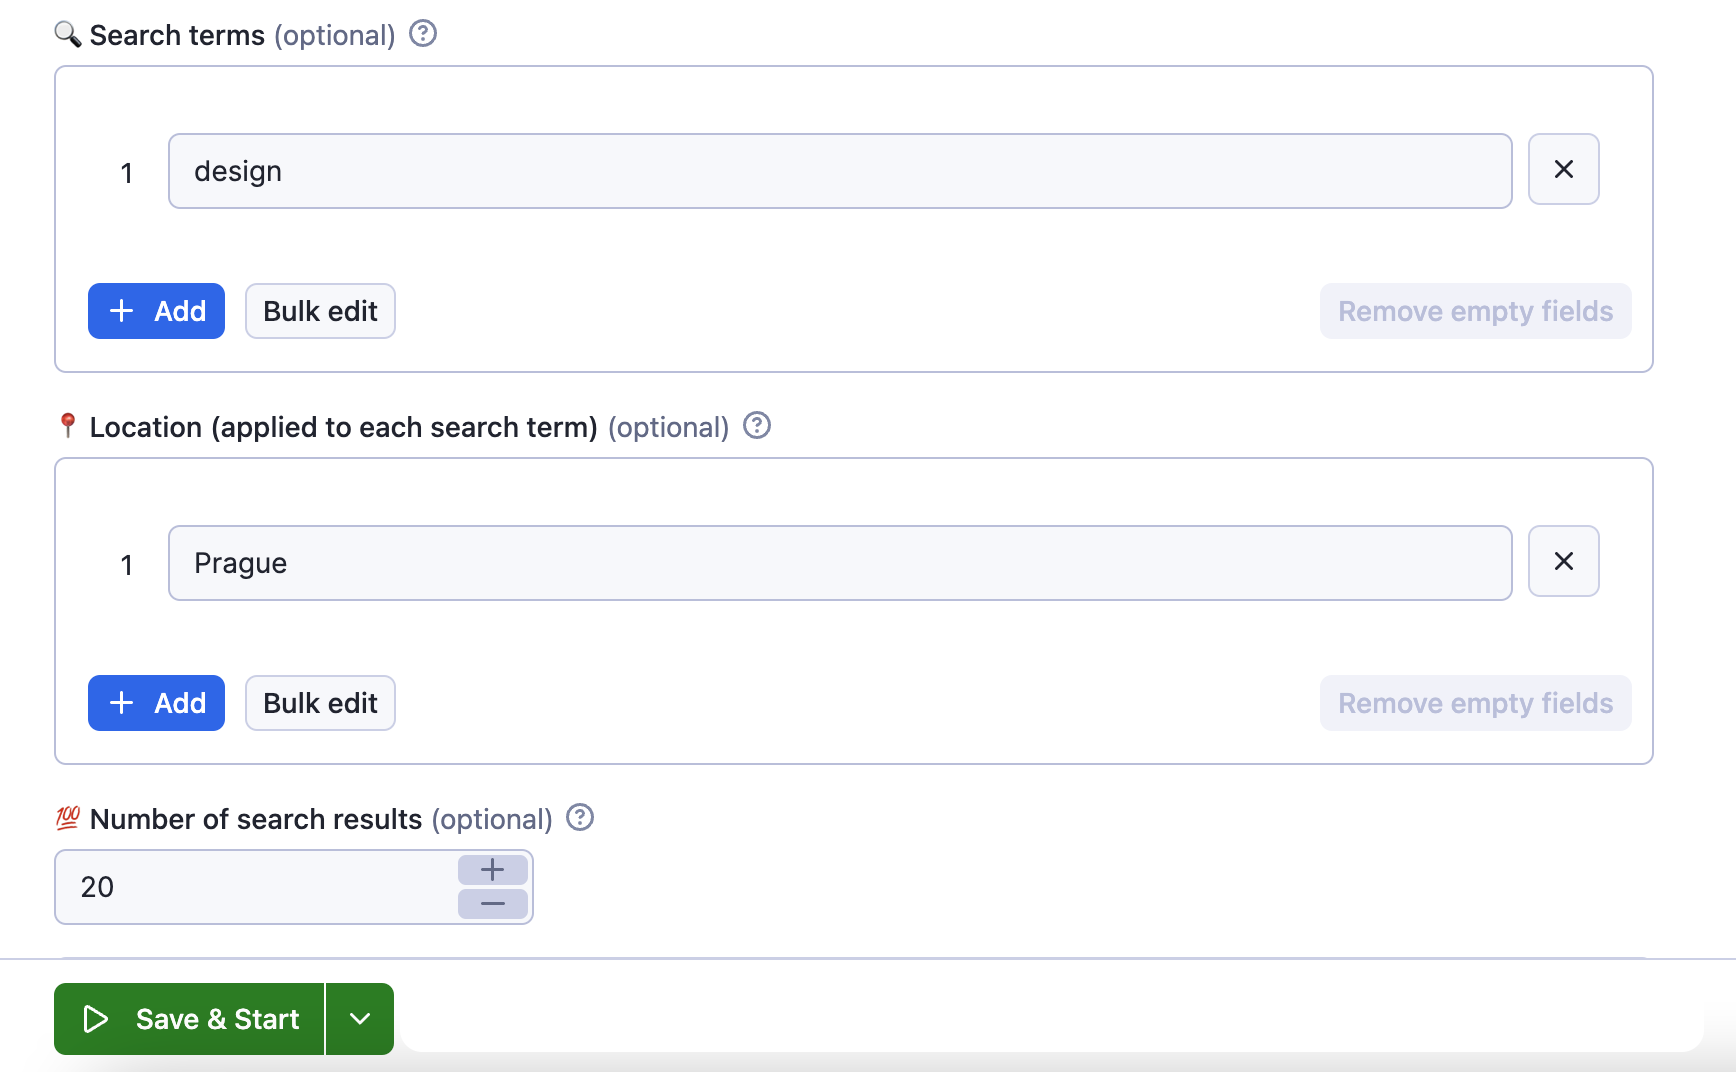
You can scrape Facebook Search **by search query** and **by location**. If a Facebook page matches your search keyword, the scraper will extract that page's data. You can add as many keywords and locations as you want. For a full explanation of input including an example in JSON, head over to the [input tab](https://apify.com/apify/facebook-search-scraper/input-schema).

You can set up the input programmatically or use the fields in scraper’s interface:

<img width="80%" src="https://raw.githubusercontent.com/apify-projects/actor-readme-images/1978f9824ec706a9ba6d79a10b016f6fded6a2ec/facebook%20search%20scraper%20api.png" />

### ⬆️ Output example

The scraped Facebook Search data will be shown as a dataset which you can find in the **Output** tab. Note that the output is organized as a table for viewing convenience:

[![Facebook search dataset](https://github.com/apify-projects/actor-readme-images/blob/master/Facebook%20Search%20dataset.png?raw=true)](https://console.apify.com/actors/Us34x9p7VgjCz99H6/console/)

And here is the same data but in JSON. You can choose in which format to download your Facebook search data: JSON, JSONL, Excel, HTML table or CSV.

```json
[
    {
        "facebookUrl": "https://www.facebook.com/Jordanmcinnisdesigns/",
        "categories": ["Page", "Graphic Designer"],
        "info": [
            "Jordan Mcinnis Designs, Montreal, Quebec. 88 likes. I'm Jordan Mcinnis, Montreal based Graphic & Web Designer. I Design Websites, Logo, Apps and Many..."
        ],
        "likes": 88,
        "messenger": null,
        "title": "Jordan Mcinnis Designs | Montreal QC",
        "address": "4972 belleville, Montreal, QC, Canada, Quebec https://maps.google.com/maps?q=4972+belleville%2C+Montreal%2C+QC%2C+Canada%2C+Quebec&hl=en",
        "pageId": "100068579062225",
        "pageName": "Jordanmcinnisdesigns",
        "pageUrl": "https://www.facebook.com/Jordanmcinnisdesigns/",
        "phone": "+1 514-716-0922",
        "email": "mcinnisj.design@gmail.com",
        "website": "jordanmcinnis.com",
        "rating": "5.0 (6 Reviews)",
        "ratingOverall": 5,
        "ratingCount": 6,
        "followers": 86,
        "creation_date": "October 2, 2017",
        "ad_status": "This Page is not currently running ads.",
        "facebookId": "100068579062225",
        "pageAdLibrary": {
            "is_business_page_active": false,
            "id": "1449158455201923"
        }
    },
    {
        "facebookUrl": "https://www.facebook.com/MKDCLangley/",
        "categories": ["Page", "Kitchen & bathroom contractor"],
        "info": [
            "Merit Kitchens Design Centre Langley, Langley, British Columbia. 324 likes",
            "1 talking about this",
            "10 were here. Along with being an exclusive dealer of..."
        ],
        "likes": 324,
        "messenger": null,
        "priceRange": "££",
        "title": "Merit Kitchens Design Centre Langley | Langley BC",
        "address": "Unit 150 - 19888 Langley Bypass, Langley, BC, Canada, British Columbia https://maps.google.com/maps?q=Unit+150+-+19888+Langley+Bypass%2C+Langley%2C+BC%2C+Canada%2C+British+Columbia&hl=en",
        "pageId": "100063562495135",
        "pageName": "MKDCLangley",
        "pageUrl": "https://www.facebook.com/MKDCLangley/",
        "phone": "+1 604-532-7197",
        "email": "langley@merit-kitchens.com",
        "website": "meritdesignlangley.com",
        "rating": "4.2 (8 reviews)",
        "ratingOverall": 4.2,
        "ratingCount": 8,
        "followers": 355,
        "creation_date": "May 15, 2012",
        "ad_status": "This Page is not currently running ads.",
        "about_me": {
            "text": "Merit Kitchens was founded by craftspeople in Vancouver, British Columbia, Canada in 1971. Since opening, they began providing Western Canada with high-quality standard and customized kitchen cabinets. The company has long since grown into a world-class supplier of beautiful custom made to order cabinetry with many price points to accommodate most budgets. Today, Merit Kitchens products can be found in homes throughout Canada, the United States, and parts of Asia.\n\nAt Merit Kitchens, we are committed to researching the latest cabinetry trends and techniques and continually blending them with strong, traditional expert construction.\n\nAll our products are manufactured and assembled in our state-of-the-art facility, in British Columbia, where we pair the precision of modern machinery technology with the delicate touch of hand-finishing. \n\nMerit Kitchens Design Centre in Langley offers the complete line of Merit Kitchens cabinets and Lectus cabinets. We also work with top suppliers in counter tops, appliances, and other design elements to help you save time and money. With the help from one of expert designers and professional installers, we will help turn your dream kitchen or bathroom into your reality.",
            "urls": []
        },
        "facebookId": "100063562495135",
        "pageAdLibrary": {
            "is_business_page_active": false,
            "id": "236732366428351"
        }
    },
    {
        "facebookUrl": "https://www.facebook.com/mmdesignswindsor/",
        "categories": ["Page", "Screen Printing & Embroidery"],
        "info": [
            "M & M Designs, Windsor, Ontario. 335 likes. We are your premier source for promotional products and custom printing. We offer screen printing, e"
        ],
        "likes": 335,
        "messenger": null,
        "title": "M & M Designs | Windsor ON",
        "address": "3395 Howard Ave, Windsor, ON, Canada, Ontario https://maps.google.com/maps?q=3395+Howard+Ave%2C+Windsor%2C+ON%2C+Canada%2C+Ontario&hl=en",
        "pageId": "100069457230966",
        "pageName": "mmdesignswindsor",
        "pageUrl": "https://www.facebook.com/mmdesignswindsor/",
        "phone": "+1 519-982-5252",
        "email": "mmdesigns@outlook.com",
        "website": "gifts-promotions.com",
        "rating": "Not yet rated (1 Review)",
        "ratingOverall": null,
        "ratingCount": 1,
        "followers": 336,
        "creation_date": "January 31, 2010",
        "ad_status": "This Page is not currently running ads.",
        "facebookId": "100069457230966",
        "pageAdLibrary": {
            "is_business_page_active": false,
            "id": "279552274420"
        }
    }
]
```

### 🚩 Want to try other Facebook scraping tools?

Use the dedicated scrapers below if you want to scrape specific public data from Facebook. Each of them is built particularly for the relevant scraping case be it Facebook comments, posts from Facebook groups, Facebook events, images or page reviews. Feel free to browse them:

<table>
<tr>
<td>🚩 <a href="https://apify.com/apify/facebook-pages-scraper">Facebook Pages Scraper</a></td>
<td>🌟 <a href="https://apify.com/apify/facebook-reviews-scraper">Facebook Reviews Scraper</a></td>
</tr>
<tr>
<td>🗓 <a href="https://apify.com/apify/facebook-events-scraper">Facebook Events Scraper</a></td>
<td>📝 <a href="https://apify.com/apify/facebook-posts-scraper">Facebook Posts Scraper</a></td>
</tr>
<tr>
<td>🛍️ <a href="https://apify.com/apify/facebook-ads-scraper">Facebook Ad Library Scraper</a></td>
<td>👍 <a href="https://apify.com/apify/facebook-likes-scraper">Facebook Likes and Reactions Scraper</a></td>
</tr>
<tr>
<td>👥 <a href="https://apify.com/apify/facebook-groups-scraper">Facebook Groups Scraper</a></td>
<td>🏞 <a href="https://apify.com/apify/facebook-photos-scraper">Facebook Photos Scraper</a></td>
</tr>
<tr>
<td>🕹 <a href="https://apify.com/apify/facebook-games-scraper">Facebook Games Scraper</a></td>
<td>👀 <a href="https://apify.com/apify/facebook-marketplace-scraper">Facebook Marketplace Scraper</a></td>
</tr>
<tr>
<td>💬 <a href="https://apify.com/apify/facebook-comments-scraper">Facebook Comments Scraper</a></td>
<td>📱 <a href="https://apify.com/apify/facebook-page-contact-information">Facebook Pages Info Scraper</a></td>
</tr>
<tr>
<td>🔮 <a href="https://apify.com/apify/brand-collaboration-scraper">Brand Collaboration Scraper</a></td>
</tr>
</table>

### ❓FAQ

#### Is there a Facebook Search API?

Facebook search does not offer an official API for public use. This means there isn't a dedicated Application Programming Interface provided by Facebook specifically for Facebook search data. There is a similarly named official [Facebook Pages Search API](https://developers.facebook.com/docs/pages-api/search-pages) which does allow extracting data from Facebook pages under certain conditions (app review approval, user authentication). However, the official Facebook Pages API doesn't allow extracting pages data by keyword. But you can use scrapers and crawlers as a stand-in for a web scraping API to extract details from Facebook Pages by keyword, e.g. 🕵️‍♀️ **[Facebook Search Scraper](https://apify.com/apify/facebook-search-scraper)**.

#### Can I use Facebook Search Scraper data with API?

Yes, you can do so by using Apify API. It gives you programmatic access to the Apify platform. The API is organized around RESTful HTTP endpoints that enable you to manage, schedule, and run Apify Actors such as this one. The API also lets you access any datasets, monitor actor performance, fetch results, create and update versions, and more.

To access the API using Node.js, use the `apify-client` [NPM package](https://apify.com/apify/facebook-search-scraper/api/client/nodejs). To access the API using Python, use the `apify-client` [PyPI package](https://apify.com/apify/facebook-search-scraper/api/client/python).

Check out the <a href="https://docs.apify.com/api/v2"  target="_blank"> Apify API reference</a> docs for full details or click on the <a href="https://apify.com/apify/facebook-search-scraper/api"  target="_blank"> API tab</a> for code examples and API Endpoints.

#### Can I create a Facebook search integration using data from this scraper?

Yes. Facebook Search Scraper can be connected with almost any cloud service or web app thanks to <a href="https://apify.com/integrations"  target="_blank">integrations on the Apify platform</a>. You can integrate with Zapier, Slack, Make, Airbyte, GitHub, Google Sheets, Google Drive, LangChain <a href="https://docs.apify.com/integrations"  target="_blank">and more</a>.

Or you can use <a href="https://docs.apify.com/integrations/webhooks"  target="_blank">webhooks</a> to carry out an action whenever an event occurs, e.g. get a notification whenever Facebook Search Scraper successfully finishes a run.

#### Can I use this Facebook Search API in Python?

Yes, by using Apify API. To access the [Facebook Search API using Python](https://apify.com/apify/facebook-search-scraper/api/client/python), use the `apify-client` PyPI package. You can find more details about the client [in our Docs](https://docs.apify.com/api/client/python/).

#### Is it legal to scrape data from Facebook search?

It is legal to scrape publicly available data from Facebook search. However, you should always review and comply with Facebook's terms of service and any applicable laws and regulations regarding web scraping. Additionally, be mindful of any rate limits or restrictions imposed by Facebook to avoid potential issues. You can read more about the legality of web scraping from [our blogpost](https://blog.apify.com/is-web-scraping-legal/).

#### Your feedback

We’re always working on improving the performance of our Actors. So if you’ve got any technical feedback for Facebook Search Scraper or simply found a bug, please create an issue on the Actor’s [Issues tab](https://apify.com/apify/facebook-search-scraper/issues/open) in Apify Console.

# Changelog

This Actor's version history is a separate document: https://apify.com/apify/facebook-search-scraper/changelog.md

# Actor input Schema

## `categories` (type: `array`):

Add one or multiple keywords. You can add the keywords one by one, or use the <b>Bulk edit</b> section to pull them from a prepared list.

## `locations` (type: `array`):

Free text location definition. Just add a name of a country, city or province.

## `searchType` (type: `string`):

Choose the type of Facebook search data you want to scrape. Posts return both images and reels.

## `resultsLimit` (type: `integer`):

Set the number of results you expect for the entire run (if this limit is not set, as many results as possible are returned).

## Actor input object example

```json
{
  "categories": [
    "Restaurant"
  ],
  "locations": [],
  "searchType": "pages",
  "resultsLimit": 20
}
```

# Actor output Schema

## `dataset` (type: `string`):

Dataset containing all scraped data

# API

You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.

## JavaScript example

```javascript
import { ApifyClient } from 'apify-client';

// Initialize the ApifyClient with your Apify API token
// Replace the '<YOUR_API_TOKEN>' with your token
const client = new ApifyClient({
    token: '<YOUR_API_TOKEN>',
});

// Prepare Actor input
const input = {
    "categories": [
        "Restaurant"
    ],
    "searchType": "pages",
    "resultsLimit": 20
};

// Run the Actor and wait for it to finish
const run = await client.actor("apify/facebook-search-scraper").call(input);

// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
    console.dir(item);
});

// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs

```

## Python example

```python
from apify_client import ApifyClient

# Initialize the ApifyClient with your Apify API token
# Replace '<YOUR_API_TOKEN>' with your token.
client = ApifyClient("<YOUR_API_TOKEN>")

# Prepare the Actor input
run_input = {
    "categories": ["Restaurant"],
    "searchType": "pages",
    "resultsLimit": 20,
}

# Run the Actor and wait for it to finish
run = client.actor("apify/facebook-search-scraper").call(run_input=run_input)

# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
    print(item)

# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start

```

## CLI example

```bash
echo '{
  "categories": [
    "Restaurant"
  ],
  "searchType": "pages",
  "resultsLimit": 20
}' |
apify call apify/facebook-search-scraper --silent --output-dataset

```

## MCP server setup

```json
{
    "mcpServers": {
        "apify": {
            "type": "http",
            "url": "https://mcp.apify.com/?tools=fetch-actor-details,apify/facebook-search-scraper"
        }
    }
}
```

The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer <APIFY_API_TOKEN>` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).

## OpenAPI specification

Download the OpenAPI definition: https://api.apify.com/v2/actors/Us34x9p7VgjCz99H6/builds/bmN9WC7wmtqUiEM9w/openapi.json