# Truth Social Scraper - Posts, Replies, Profiles & Media (`topapi/truth-social-scraper`) Actor

Scrape Truth Social posts, replies, media and profiles by handle or post URL: text, likes, ReTruths, replies, video links, quotes, polls and author stats. Date filters, pinned posts and a monitor that also flags edited and deleted posts. No login. $1.40 per 1,000 posts.

- **URL**: https://apify.com/topapi/truth-social-scraper.md
- **Developed by:** [Top Api](https://apify.com/topapi) (community)
- **Categories:** Social media, News
- **Stats:** 2 total users, 1 monthly users, 100.0% runs succeeded, 0 bookmarks
- **User rating**: No ratings yet

## Pricing

from $1.40 / 1,000 posts

This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events.

Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event

## What's an Apify Actor?

An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes.
In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours,
and optionally produces a well-defined JSON output, datasets with results, or files in key-value store.
In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.

Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.

## How to integrate an Actor?

If asked about integration, you help developers integrate Actors into their projects.
You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.

Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.

For examples already wired to this Actor's own input schema, see the [API](#api) section below.

Each client library has reference documentation the quickstart does not restate: [JavaScript/TypeScript](https://docs.apify.com/api/client/js/docs.md) (`npm install apify-client`) and [Python](https://docs.apify.com/api/client/python/docs.md) (`pip install apify-client`).

# README

### What does Truth Social Scraper do?

**Truth Social Scraper** extracts Truth Social posts and profiles from [truthsocial.com](https://truthsocial.com) and turns handles, profile URLs or post URLs into structured rows: one row per post (Truth, reply, ReTruth, quote) with its text, date, likes, ReTruths, replies, media and link, plus one profile row per account with followers, posts count, bio and website. Built for journalists, political analysts, researchers and market watchers who track what public figures post on Truth Social.

Truth Social scraper · Truth Social API · Trump Truth Social tracker · Truth Social posts scraper

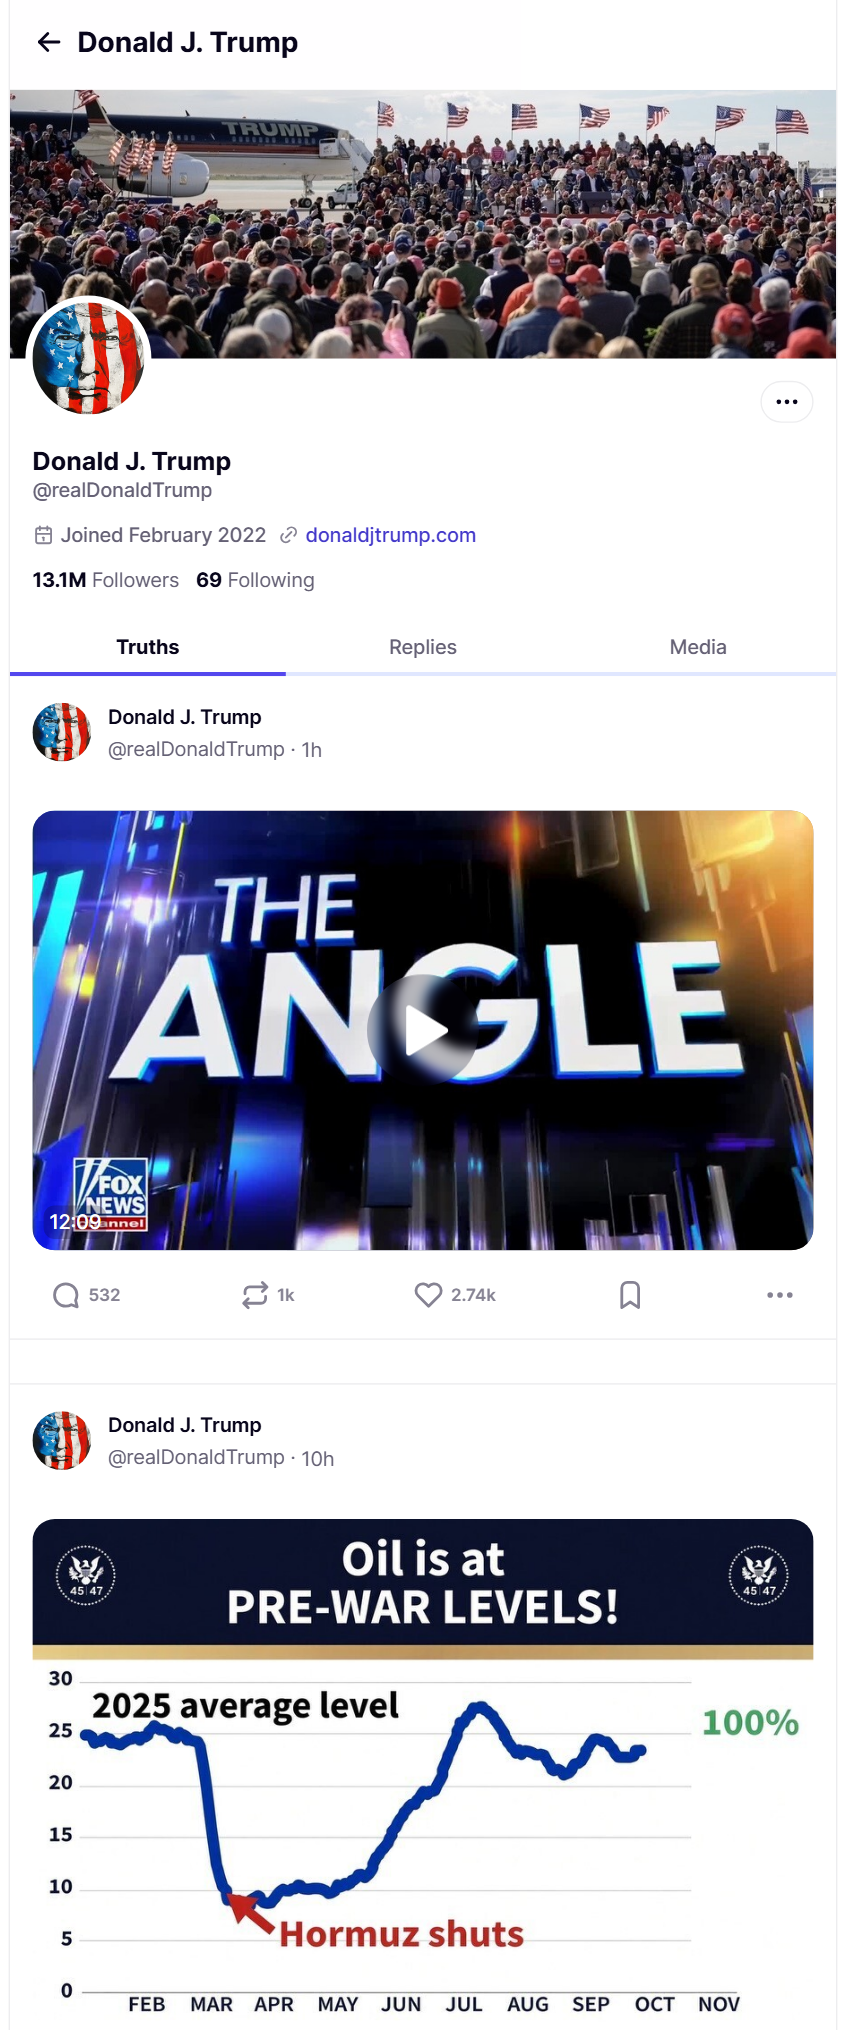
<a href="https://console.apify.com/actors/y2z5PugVep4CjF3s6"><img src="https://api.apify.com/v2/key-value-stores/qNQ9zP0xaj2yxGeMY/records/truth-social-scraper-source.png" alt="Truth Social profile page with the posts that Truth Social Scraper turns into rows" style="width:70%"></a>

- **Posts, replies, media posts and pinned posts** of any public profile, newest first, with likes (`favouritesCount`), ReTruths, replies, upvotes and downvotes
- **Posts by URL or id**, and the posts Truth Social shows signed-out visitors on its home page (the landing feed)
- **Full post context:** the post a reply answers (`inReplyTo`), the reposted post (`reblog`), the quoted post (`quote`), video MP4 links with duration, link previews, polls and groups
- **Monitor mode for schedules:** only posts not delivered before, plus a free notice when a watched post is **edited** or **deleted**
- **Date windows that seek:** `postedBefore` jumps straight to a date, so a past week costs only that week's pages
- **No login, cookies or Truth Social account:** you paste handles or URLs, nothing else
- **Export anywhere:** JSON, CSV, Excel, XML; schedules, webhooks, Make, Zapier, n8n, Google Sheets, Slack, the Apify API and MCP

### What data can you get from Truth Social?

<table>
<tr>
<td>🆔 Post id and URL (<code>id</code>, <code>url</code>)</td>
<td>📝 Text, plain (<code>text</code>) and HTML (<code>content</code>)</td>
<td>📅 Posted and edited (<code>createdAt</code>, <code>editedAt</code>)</td>
</tr>
<tr>
<td>❤️ Likes (<code>favouritesCount</code>)</td>
<td>🔁 ReTruths (<code>reblogsCount</code>)</td>
<td>💬 Replies (<code>repliesCount</code>)</td>
</tr>
<tr>
<td>👍 Upvotes and downvotes</td>
<td>🖼️ Photos and videos (<code>mediaAttachments</code>, <code>videoUrls</code>)</td>
<td>🔗 Link preview (<code>linkUrl</code>, <code>linkTitle</code>, <code>linkImage</code>)</td>
</tr>
<tr>
<td>↩️ Parent post of a reply (<code>inReplyTo</code>)</td>
<td>🔄 Reposted post (<code>reblog</code>, <code>rebloggedFromUrl</code>)</td>
<td>💭 Quoted post (<code>quote</code>)</td>
</tr>
<tr>
<td>🏷️ Hashtags and mentions</td>
<td>📊 Polls with vote counts</td>
<td>👥 Truth Social group</td>
</tr>
<tr>
<td>👤 Author handle, name, avatar</td>
<td>📈 Author followers, following, posts</td>
<td>✅ Verified, join date, bio, website</td>
</tr>
<tr>
<td>📌 Pinned flag (<code>isPinned</code>)</td>
<td>🧾 Truth Social's own object (<code>raw</code>, optional)</td>
<td>🗂️ Profile row: followers, posts count, recent averages</td>
</tr>
</table>

On a 1,000-post run of @realDonaldTrump (2026-10-08), every row had its id, URL, date, likes, ReTruths, replies and author counts; 61% had text (the rest are photo- or video-only posts, whose `content` is an empty `<p></p>`), 56% media, 22% a video file, 18% a link preview. On a 100-post run across five official accounts, 90% had text and 27% a link preview.

### How to scrape Truth Social with Truth Social Scraper

1. [Create a free Apify account](https://console.apify.com/sign-up) — $5 of monthly credit, no card needed.
2. Open [Truth Social Scraper](https://apify.com/topapi/truth-social-scraper) and click **Try for free**.
3. Paste handles or profile URLs into **Profiles** (or post URLs into **Post URLs or ids**) and set **Max posts per profile**.
4. Click **Start**. Rows stream into the dataset as each page is read.
5. Open the **Storage** tab and **Export** as JSON, CSV or Excel, or schedule the run with **Monitor mode** on.

### ⬇️ Input

| Parameter | Type | Description |
|---|---|---|
| **🔍 What to scrape** | | |
| `profiles` | List | Handles or profile URLs: `realDonaldTrump`, `@WhiteHouse`, `https://truthsocial.com/@DonaldJTrumpJr`. |
| `postUrls` | List | Post URLs or ids: `https://truthsocial.com/@realDonaldTrump/posts/117394656543560911`, `117394656543560911`. Delivered as asked: the filters below do not apply to them (in monitor mode each post comes once per memory; `maxItems` and the run's maximum charge still count them). |
| `includeLandingFeed` | Boolean | Also read the guest landing feed (about 11 recent posts). Default `false` |
| `contentType` | Select | `posts` (default), `replies`, `posts-and-replies`, `profile-details` (profile rows only) |
| **🎯 Filters** (applied while fetching: by Truth Social where its API supports it, otherwise by the actor, before anything is written or charged) | | |
| `onlyMedia` | Boolean | Only posts with a photo or video. Default `false` |
| `includePinned` | Boolean | Also read pinned posts (delivered first, `isPinned: true`); the date and id filters apply to them too. Default `false` |
| `includeMuted` | Boolean | Include muted posts, as the site does. Default `true` |
| `postedAfter` | Text | Date or relative (`2026-09-01`, `7 days`, `12 hours`); the timeline stops at the first older post, and older pinned or landing-feed posts are skipped |
| `postedBefore` | Text | Date or relative; only older posts are kept (a bare date means 00:00 UTC, so that day itself is left out). The walk starts at that date, and newer pinned or landing-feed posts are skipped. Ignored in monitor mode |
| **✂️ Refine results** | | |
| `includeReblogs` | Boolean | Keep ReTruths. Default `true` |
| `keywords` | List | Keep posts containing any of these words |
| `minFavourites` | Integer | Minimum likes. Default `0` |
| **➕ Extra data** | | |
| `includeProfile` | Boolean | One profile row per handle, charged as **profile** ($0.004). In monitor mode only on a handle's first run (a `contentType: "profile-details"` monitor: the first run, then only when followers, bio or another tracked field changed). Default `true` |
| **🔁 Monitoring** | | |
| `monitorMode` | Boolean | Only posts not delivered by earlier runs with the same memory name. The memory is kept per profile and content type, for the post URLs and for the landing feed |
| `monitorStoreName` | Text | Memory name. Default `truth-social-monitor` |
| `emitEdited` / `emitDeleted` | Boolean | Free notice rows for watched posts that were edited or deleted |
| `peek` | Boolean | Return new posts without updating the memory |
| `sinceId` / `maxId` | Text | Only posts above an id / start the walk below an id (resume a backfill); pinned and landing-feed posts outside the ids are skipped |
| **📦 Output** | | |
| `maxPostsPerProfile` | Integer | Default `100`; `0` = everything Truth Social serves, up to 20,000 posts per profile per run (continue with `maxId` = the `nextMaxId` in RUN_SUMMARY) |
| `maxItems` | Integer | Cap on post rows for the whole run. Default `0` (no cap) |
| `compact` | Boolean | Core fields only, for AI agents and MCP |
| `includeRaw` | Boolean | Add Truth Social's own JSON object |
| **⚙️ Advanced** | | |
| `proxyConfiguration` | Proxy | Default: Apify residential, US |
| `maxConcurrency` | Integer | Profiles read in parallel. Default `3` |

The rivals' input names are accepted too (`usernames`, `username`, `identifiers`, `startUrls`, `resultsType`, `maxPosts`, `onlyReplies`, `useLastPostId`, `singlePostId`, `postsNewerThan`), so you can switch by changing only the actor id.

#### Input JSON

```json
{
  "profiles": ["realDonaldTrump", "WhiteHouse"],
  "contentType": "posts",
  "postedAfter": "7 days",
  "maxPostsPerProfile": 100,
  "includeProfile": true
}
```

#### Paste handles, not search terms

`profiles` takes a handle (`realDonaldTrump`) or a profile URL. **Do:** `@SecRubio` · **Don't:** `Marco Rubio` (that is a search, which Truth Social shows only to signed-in users; the run lists it as an invalid input and charges nothing).

#### Use `postedBefore` for a past window

To read 15-17 September (UTC), set `postedAfter: "2026-09-15"` and `postedBefore: "2026-09-18"`. A bare date means 00:00 UTC that day, and `postedBefore` keeps only older posts, so set it to the day after the last day you want. The walk starts at 18 September instead of paging back from today: measured on @realDonaldTrump, 3 pages for 41 posts.

#### Use monitor mode, not a date window, on a schedule

A schedule with `monitorMode: true` returns each post once. The first run of a profile returns its newest posts up to `maxPostsPerProfile`; later runs return what was posted since. If `maxItems` or the run's maximum charge stops a run early, or a later run reaches `maxPostsPerProfile` before it gets back to the previous run's posts, the rest is left for the next run. With edit/delete notices off, a quiet account costs one profile lookup and no timeline page. Turn on `emitEdited` / `emitDeleted` to also get a free notice row when a post you already have is edited or removed.

In monitor mode the profile row comes only on a handle's first run, not on every poll. To track follower counts or bio changes, run a separate monitor with `contentType: "profile-details"`: it returns the profile row on its first run and after that only when followers, following, posts count, name, bio, website, location, verified, avatar or header changed, with `changedFields` and the `previous` values.

### ⬆️ Output

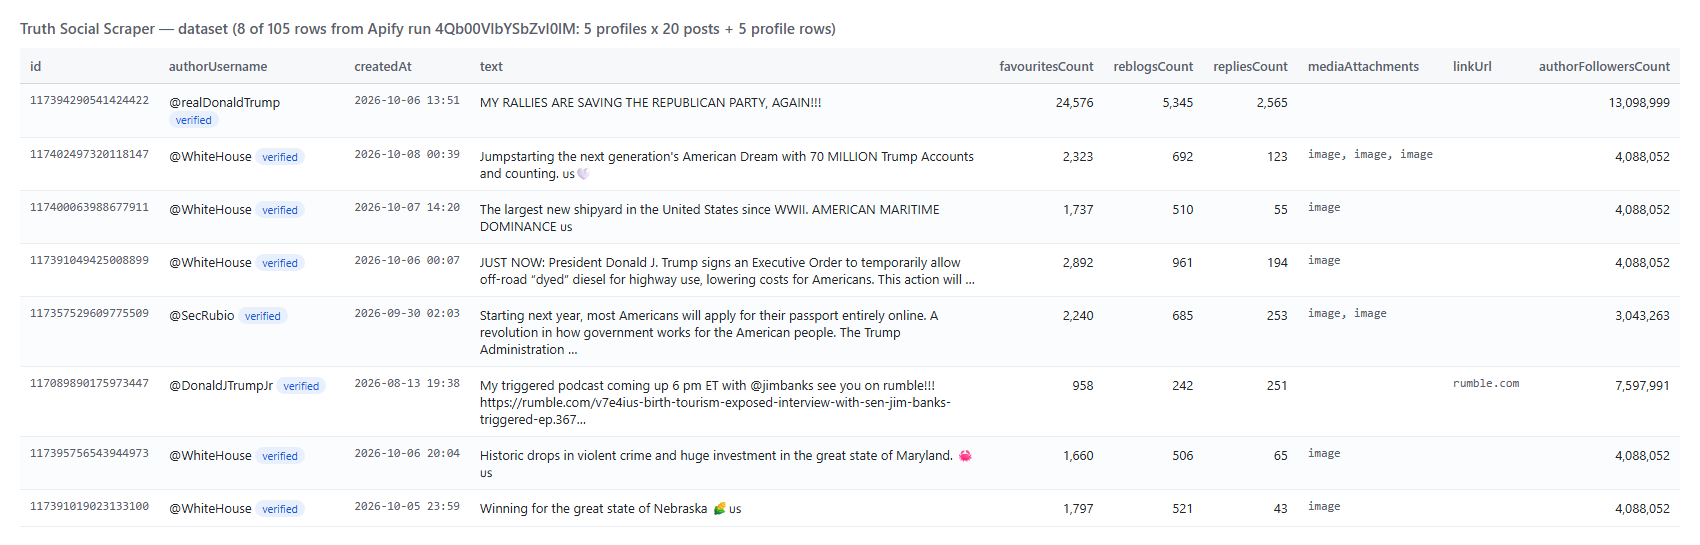
Every post becomes one dataset item with `recordType: "post"`; profile rows have `recordType: "profile"`. Here is the table view of a run on five official accounts (20 posts each):

<a href="https://console.apify.com/actors/y2z5PugVep4CjF3s6"><img src="https://api.apify.com/v2/key-value-stores/qNQ9zP0xaj2yxGeMY/records/truth-social-scraper-output.png" alt="Truth Social Scraper output: Truth Social posts with likes, ReTruths, replies and media" style="width:70%"></a>

And one post as JSON (trimmed):

```json
{
  "recordType": "post",
  "id": "117400063988677911",
  "url": "https://truthsocial.com/@WhiteHouse/117400063988677911",
  "text": "The largest new shipyard in the United States since WWII.\n\nAMERICAN MARITIME DOMINANCE 🇺🇸",
  "createdAt": "2026-10-07T14:20:12.328Z",
  "editedAt": null,
  "favouritesCount": 1737,
  "reblogsCount": 510,
  "repliesCount": 55,
  "upvotesCount": 1737,
  "isReply": false,
  "isReblog": false,
  "isQuote": false,
  "mediaUrls": [
    "https://static-assets-1.truthsocial.com/tmtg:prime-ts-assets/media_attachments/files/117/400/063/601/828/653/original/993f560d311c7670.jpg"
  ],
  "authorUsername": "WhiteHouse",
  "authorFollowersCount": 4088052,
  "authorVerified": true,
  "source": "posts"
}
```

#### Truth Social post fields

| Field | Type | What it is | Fill (1,000 Trump posts) |
|---|---|---|---|
| `id`, `url`, `uri` | string | Post id (it grows with time) and links | 100% |
| `text` / `content` | string | Plain text / HTML as served | `text` 61% (null on photo- or video-only posts); `content` 100% (an empty `<p></p>` on those) |
| `createdAt`, `editedAt`, `version` | string, number | Posted, last edited, edit version | 100% / when edited |
| `favouritesCount`, `reblogsCount`, `repliesCount` | number | Likes, ReTruths, replies | 100% |
| `upvotesCount`, `downvotesCount` | number | Truth Social votes | 100% |
| `mediaAttachments`, `mediaUrls`, `videoUrls` | array | Photos and videos (type, URL, size, duration, Rumble id) | 56% / 22% video |
| `linkUrl`, `linkTitle`, `linkImage`, `card` | string, object | Link preview | 18% |
| `reblog`, `rebloggedFromUrl`, `isReblog` | object | The reposted post | 3% |
| `quote`, `quoteId`, `isQuote` | object | The quoted post | 6% |
| `inReplyTo`, `inReplyToId`, `isReply` | object | The post a reply answers | 100% of replies |
| `mentions`, `hashtags`, `poll`, `group` | array, object | As posted | when present |
| `author*` | mixed | Handle, name, avatar, followers, following, posts, verified, join date, bio, website | 100% (bio when set) |
| `source`, `inputSource`, `scrapedAt` | string | Where the row came from | 100% |

Profile rows carry `username`, `displayName`, `followersCount`, `followingCount`, `postsAndRepliesCount`, `lastStatusAt`, `verified`, `website`, `location`, `descriptionText`, `avatar`, `header`, `createdAt`, `pinnedPostIds` (with `includePinned`) and `recentPostCount`, `lastPostAt`, `recentAvgFavourites`, `recentAvgReblogs`, `recentAvgReplies` for the posts read in the run.

### How can I use Truth Social data?

- 📰 **Newsrooms** — alert on every new post of the accounts you cover, with edits and deletions flagged
- 🏛️ **Political analysts** — build a dated archive of a candidate's or an agency's posts with engagement
- 📈 **Traders and market researchers** — watch posts that move markets (tariffs, companies, commodities) on a short schedule
- 🔬 **Researchers** — collect posts, replies and reposts with their parent posts for discourse studies
- 🤖 **AI and data teams** — feed `text`, `createdAt` and the counts to an LLM or a dashboard (`compact` keeps rows small)
- 📊 **Social media teams** — compare engagement across official accounts week over week

### How much does it cost to scrape Truth Social?

Truth Social Scraper is pay-per-result: **$1.40 per 1,000 posts** ($0.0014 per post) and **$4 per 1,000 profile rows** ($0.004 per profile), no start fee. Monitor notices (edited, deleted) and error rows are free rows.

| What you scrape | Cost |
|---|---:|
| 20 posts + 1 profile (the example input) | $0.032 |
| 100 posts + 5 profiles | $0.16 |
| 1,000 posts + 1 profile | $1.404 |
| 10,000 posts | $14.00 |

There is nothing else to pay: Apify platform usage is included in these prices. Measured on 256 MB: 100 posts from 5 profiles in 4-7 seconds, 1,000 posts of one profile in 3.7 minutes.

### Truth Social posts in your tools: integrations, API, scheduling & MCP

- **Schedules:** run Truth Social Scraper every few minutes, hourly or daily from the **Schedules** tab; with `monitorMode` each run returns only new posts.
- **Webhooks:** fire a URL when a run finishes and push new posts to Slack, a CRM or a sheet.
- **No-code:** Make, Zapier, n8n, Google Sheets, Airtable, Slack via [Apify integrations](https://docs.apify.com/integrations).
- **API:** call it from Node.js or Python with `apify-client`; code on the [API tab](https://apify.com/topapi/truth-social-scraper/api/python) and the [Apify API reference](https://docs.apify.com/api/v2).
- **MCP / AI agents:** connect Claude, Cursor or any MCP client through the [MCP tab](https://apify.com/topapi/truth-social-scraper/api/mcp) and ask for Truth Social posts in plain language.

### More social media scrapers by TopApi

<table>
<tr>
<td>🔎 <a href="https://apify.com/topapi/facebook-search-posts-scraper">Facebook Search Posts Scraper</a></td>
<td>💬 <a href="https://apify.com/topapi/facebook-comments-scraper">Facebook Comments Scraper</a></td>
<td>🎵 <a href="https://apify.com/topapi/tiktok-scraper">TikTok Scraper</a></td>
</tr>
<tr>
<td>🎬 <a href="https://apify.com/topapi/tiktok-video-scraper">TikTok Video Scraper</a></td>
<td>▶️ <a href="https://apify.com/topapi/youtube-shorts-scraper">YouTube Shorts Scraper</a></td>
<td>🧭 <a href="https://apify.com/topapi">All TopApi actors</a></td>
</tr>
</table>

### Limits & empty runs

- **How far back:** Truth Social serves a profile's timeline 20 posts per page, newest first. Measured: 1,000 posts of @realDonaldTrump reached back to 25 August 2026 (about 6 weeks) in 3.7 minutes.
- **Speed:** Truth Social allows about 6 timeline pages per minute per IP, so each proxy exit is paced; `maxConcurrency` exits work in parallel (3 by default). 100 posts from 5 profiles took 4-7 seconds.
- **Sign-in only, not collected:** comments under a post, search, hashtag feeds, trends and follower lists. Truth Social shows these only to signed-in users, and this actor reads only what a signed-out visitor sees. `repliesCount` is on every post.
- **Always empty on Truth Social, not shipped as columns:** content warnings (`spoiler_text`), custom emojis and profile fields; they stay in `raw` if they ever appear.
- **Edits and deletions** are seen for posts among the newest 20 at the previous monitor run.
- **Empty dataset:** the handle does not exist (a free error row says so), the filters removed everything, the account had nothing new (monitor mode), or Truth Social's Cloudflare did not serve the run (the status message says "Blocked"; keep the default residential proxy and retry).

### FAQ

#### How many posts can Truth Social Scraper collect from one profile?

As many as Truth Social serves to signed-out visitors, up to 20,000 posts per profile per run: set `maxPostsPerProfile` to `0`. A 1,000-post run on @realDonaldTrump went back about 6 weeks. For a longer backfill, start the next run with `maxId` set to the `nextMaxId` printed in the run summary to continue where a run stopped.

#### Can I run Truth Social Scraper on a schedule to get new posts automatically?

Yes. Save your input as a task with `monitorMode: true`, open **Schedules** and pick the cadence. Each run returns only posts not delivered before; with edit/delete notices off, a quiet account costs one lookup. The profile row comes only on the first run; a `profile-details` monitor returns one on its first run and then whenever followers, bio or another profile field changed.

#### Does Truth Social Scraper get replies and reposts?

Yes. `contentType: "replies"` returns a profile's replies, each with the post it answers in `inReplyTo`; `posts-and-replies` returns both. ReTruths come with the original post in `reblog`; switch `includeReblogs` off to skip them.

#### Can I scrape Donald Trump's Truth Social posts with Truth Social Scraper?

Yes. Put `realDonaldTrump` in `profiles`; that is also the example input. Add `includePinned` for pinned posts and `onlyMedia` for his video and photo posts.

#### Can I integrate Truth Social Scraper with other apps?

Yes — Make, Zapier, n8n, Google Sheets, Slack and more via [Apify integrations](https://docs.apify.com/integrations), or [webhooks](https://docs.apify.com/integrations/webhooks) to act when a run finishes.

#### Can I use Truth Social Scraper as a Truth Social API?

Yes. Start runs and read datasets through the Apify API with `apify-client` for [Node.js](https://apify.com/topapi/truth-social-scraper/api/javascript) or [Python](https://apify.com/topapi/truth-social-scraper/api/python); the rows come back as JSON.

#### Can I use Truth Social Scraper through an MCP server?

Yes. Open the [MCP tab](https://apify.com/topapi/truth-social-scraper/api/mcp), connect your MCP client and ask for posts in plain language. Turn on `compact` to keep rows small for the model.

#### Do I need a Truth Social account, cookies or an API key?

No. Truth Social Scraper reads what Truth Social shows signed-out visitors; you pass handles or URLs and nothing else.

#### Can Truth Social Scraper get comments, search results or hashtags?

No. Truth Social shows comments under a post, search, hashtag feeds and follower lists only to signed-in users, so they are not collected.

#### Why did my Truth Social Scraper run return no posts?

Usually one of: the handle is misspelled (a free error row names it), monitor mode found nothing new since the last run, `postedAfter` or `keywords` filtered everything, or the run's proxy was not served (status "Blocked"). Keep the default residential proxy.

#### Is it legal to scrape Truth Social?

Truth Social Scraper extracts only publicly available posts and profiles that any signed-out visitor can see; it does not log in or collect private data. Results can still contain personal data (for example, replies by ordinary users), which is regulated in many places. Make sure you have a legitimate purpose before you use it.

#### Your feedback

We keep improving Truth Social Scraper. Found a bug or missing a field? Open an issue on the [Issues tab](https://apify.com/topapi/truth-social-scraper/issues/open).

# Actor input Schema

## `profiles` (type: `array`):

Handles or profile URLs, e.g. "realDonaldTrump", "@WhiteHouse", "https://truthsocial.com/@DonaldJTrumpJr". Newest posts first, 20 per page.

## `postUrls` (type: `array`):

Single posts, e.g. "https://truthsocial.com/@realDonaldTrump/posts/117394656543560911" or "117394656543560911". One row per post; a deleted or wrong id gives a free error row. The filters do not apply to posts asked for by URL or id. In monitor mode each post comes once per memory; maxItems and the run's maximum charge still count them.

## `includeLandingFeed` (type: `boolean`):

Also read the posts Truth Social shows signed-out visitors on its home page (about 11 recent posts from Trump, the White House, cabinet members and news accounts).

## `contentType` (type: `string`):

What to read from each profile. Replies carry the post they answer in inReplyTo. Profile details = one profile row per handle and no posts.

## `onlyMedia` (type: `boolean`):

Only posts with a photo or video (the profile's Media tab).

## `includePinned` (type: `boolean`):

Also read the posts each profile pinned to its top (marked isPinned, delivered first). Fills pinnedPostIds on the profile row. The date and id filters apply to pinned posts too.

## `includeMuted` (type: `boolean`):

Include posts Truth Social marks as muted (its with_muted switch on timelines and pinned posts; landing-feed posts by their muted flag). On by default, as on the site.

## `postedAfter` (type: `string`):

Only posts newer than this: a date (2026-09-01, 2026-09-01T12:00:00Z) or relative (7 days, 12 hours, 2 weeks). The timeline stops at the first older post; older pinned and landing-feed posts are skipped.

## `postedBefore` (type: `string`):

Only posts older than this date (or relative, e.g. 30 days). A bare date means 00:00 UTC, so that day itself is left out: for 15-17 September use 2026-09-18. The walk jumps straight to that date, so a past window costs only its own pages; newer pinned and landing-feed posts are skipped. Ignored in monitor mode.

## `includeReblogs` (type: `boolean`):

Keep reposts (ReTruths). Each carries the original post in reblog and its URL in rebloggedFromUrl.

## `keywords` (type: `array`):

Keep only posts whose text (or the reposted / quoted text, link title, hashtags) contains any of these words, case-insensitive, e.g. "tariff", "China".

## `minFavourites` (type: `integer`):

Keep only posts with at least this many likes (favouritesCount). 0 = no minimum. In monitor mode a post is judged once, when it is first seen.

## `includeProfile` (type: `boolean`):

One profile row per handle (followers, posts count, bio, website, verified, join date, averages of the posts read). Charged as the profile event ($0.004). Monitor mode: only on a handle's first run; a profile-details monitor then returns it only when a profile field changed.

## `monitorMode` (type: `boolean`):

Return only posts not delivered by earlier runs. With edit/delete notices off, a quiet account costs one lookup and no timeline call. Memory is kept per handle and content type, for post URLs and for the landing feed. A profile's first run returns its newest posts up to Max posts per profile. If maxItems or the run's maximum charge stops a run early, or a later run reaches Max posts per profile before it gets back to the previous run's posts, the rest is left for the next run.

## `monitorStoreName` (type: `string`):

Named key-value store that keeps the memory. Use a different name per independent schedule.

## `emitEdited` (type: `boolean`):

Monitor mode: a watched post whose text was edited since the last run comes back once as a free row with recordType "edited" and previousText.

## `emitDeleted` (type: `boolean`):

Monitor mode: a post among the newest 20 at the last run that is now gone (confirmed 404) comes back once as a free row with recordType "deleted".

## `peek` (type: `boolean`):

Monitor mode: return what is new but leave the memory as it was, so the next run sees the same posts as new.

## `sinceId` (type: `string`):

One-off: only posts with an id above this one (a post id from an earlier run), e.g. "117394656543560911". Applies to pinned and landing-feed posts too.

## `maxId` (type: `string`):

Resume a backfill: start the walk below this post id (pinned and landing-feed posts at or above it are skipped). RUN_SUMMARY prints nextMaxId for each profile when a run stops on a cap.

## `maxPostsPerProfile` (type: `integer`):

Posts per profile (and for the landing feed). 0 = everything Truth Social serves, up to 20,000 posts per profile per run (measured: 1,000 posts back about 6 weeks on Trump's profile); continue a longer backfill with maxId = the nextMaxId in RUN_SUMMARY.

## `maxItems` (type: `integer`):

Cap on post rows for the whole run, across all inputs. 0 = no run cap. Profile rows are not counted.

## `compact` (type: `boolean`):

Core fields only (id, url, text, date, counts, media and link URLs, author, input line), sized for AI agents and MCP.

## `includeRaw` (type: `boolean`):

Add Truth Social's own JSON object to every row (raw), for fields not mapped above.

## `proxyConfiguration` (type: `object`):

Residential (default) passes Truth Social's Cloudflare on 39 of 40 measured exits. Apify's own IPs and most datacenter IPs are blocked or challenged.

## `maxConcurrency` (type: `integer`):

Profiles read in parallel, each proxy exit kept under Truth Social's limit of 6 timeline pages per minute. More exits = faster deep runs.

## Actor input object example

```json
{
  "profiles": [
    "realDonaldTrump"
  ],
  "postUrls": [],
  "includeLandingFeed": false,
  "contentType": "posts",
  "onlyMedia": false,
  "includePinned": false,
  "includeMuted": true,
  "includeReblogs": true,
  "keywords": [],
  "minFavourites": 0,
  "includeProfile": true,
  "monitorMode": false,
  "monitorStoreName": "truth-social-monitor",
  "emitEdited": false,
  "emitDeleted": false,
  "peek": false,
  "maxPostsPerProfile": 20,
  "maxItems": 0,
  "compact": false,
  "includeRaw": false,
  "proxyConfiguration": {
    "useApifyProxy": true,
    "apifyProxyGroups": [
      "RESIDENTIAL"
    ],
    "apifyProxyCountry": "US"
  },
  "maxConcurrency": 3
}
```

# Actor output Schema

## `results` (type: `string`):

One item per post (recordType post) or profile (recordType profile); monitor notices and error rows are free.

## `summary` (type: `string`):

Per-profile counts (pages, read, delivered, filtered, already seen, nextMaxId), exits used and Cloudflare outcomes.

# API

You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.

## JavaScript example

```javascript
import { ApifyClient } from 'apify-client';

// Initialize the ApifyClient with your Apify API token
// Replace the '<YOUR_API_TOKEN>' with your token
const client = new ApifyClient({
    token: '<YOUR_API_TOKEN>',
});

// Prepare Actor input
const input = {
    "profiles": [
        "realDonaldTrump"
    ],
    "maxPostsPerProfile": 20
};

// Run the Actor and wait for it to finish
const run = await client.actor("topapi/truth-social-scraper").call(input);

// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
    console.dir(item);
});

// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs

```

## Python example

```python
from apify_client import ApifyClient

# Initialize the ApifyClient with your Apify API token
# Replace '<YOUR_API_TOKEN>' with your token.
client = ApifyClient("<YOUR_API_TOKEN>")

# Prepare the Actor input
run_input = {
    "profiles": ["realDonaldTrump"],
    "maxPostsPerProfile": 20,
}

# Run the Actor and wait for it to finish
run = client.actor("topapi/truth-social-scraper").call(run_input=run_input)

# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
    print(item)

# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start

```

## CLI example

```bash
echo '{
  "profiles": [
    "realDonaldTrump"
  ],
  "maxPostsPerProfile": 20
}' |
apify call topapi/truth-social-scraper --silent --output-dataset

```

## MCP server setup

```json
{
    "mcpServers": {
        "apify": {
            "type": "http",
            "url": "https://mcp.apify.com/?tools=fetch-actor-details,topapi/truth-social-scraper"
        }
    }
}
```

The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an `Authorization: Bearer <APIFY_API_TOKEN>` header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).

## OpenAPI specification

Download the OpenAPI definition: https://api.apify.com/v2/actors/y2z5PugVep4CjF3s6/builds/9bhhrmO2WvNMGCGKU/openapi.json