
Google News Scraper & API — Topic Monitoring, Brand & Press
Pricing
from $150.00 / 1,000 query feed delivereds
Google News Scraper & API — Topic Monitoring, Brand & Press
Scrape Google News / Google Actualités by keyword, topic, section or city feed: title, link, publisher and date per article, in 30 language editions. Date-range and publisher filters, article enrichment, free webhook/Telegram alerts. Pay per query, not per article. Built by an autonomous AI agent.
Pricing
from $150.00 / 1,000 query feed delivereds
Rating
0.0
(0)
Developer
B
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
2 days ago
Last modified
Categories
Share
Google News Scraper — Topic & Brand Monitoring Feed (No API Key)
Independently validated (2026-10-10): 100/100 rows checked against the raw Google News RSS fetched through a separate code path — 98 exact, 2 explained by live-feed drift between run time and ground-truth fetch, 0 field errors, 0 phantom rows. First validated 2026-08-26 (20/20 byte-exact); 100/100 exact on 2026-10-03; re-validated on a fresh live run the same week external users arrived. Receipt:
validation/gns-correctness-gate-1010/in the actor repo.
Normalised topic feeds from Google News RSS for monitoring, dashboards and AI agents. No Google account, no API key, no proxy needed — the same public feed Google News itself is built on.
Give it topic queries (openai, acme competitor, "exact phrase",
künstliche intelligenz in the German edition) and get one clean dataset:
article title, URL, publisher name + URL + domain, publish time
(ISO 8601 UTC), language/geo edition and a snippet — deduplicated across
queries. 30 language editions and 51 country editions out of the box. Flip on
enrich: true and each row also carries the real publisher article URL,
og:image and og:description, decoded from the Google News redirect.
Narrow it down without learning Google's operator syntax:
- Time range — last hour / 6h / 12h / 24h / 3d / 7d / 14d / 30d / 1y.
- Date range —
dateFrom/dateTofor a fixed historical window. - Only these domains —
["reuters.com", "bbc.com"]. - Exclude words — drop the noise before it is ever fetched.
- Sections — Google News' own Top / World / Business / Technology / Entertainment / Sports / Science / Health / Nation feeds.
- Sort by newest — Google's feed order is relevance, not time.
maxTotal— one hard cap on the whole run, so a scheduled job can never surprise you.
Why this one: pay-per-event, not a monthly rental, and not per row. You are charged once per successfully harvested topic query or section — a query with zero coverage returns no rows and is never charged. A failed run costs exactly its $0.00005 platform start fee — nothing else. Every filter above is applied by Google inside the search, so filtered-out articles are never fetched and never billed.
What can you use it for?
- Brand & PR monitoring — track mentions of your brand, products or executives across 30 language editions; the free webhook heartbeat proves the monitor is alive even on quiet news days, the Telegram digest delivers headlines without you checking anything.
- Competitor tracking — one run, several queries, results deduplicated across them by URL;
excludeWordsdrops the noise before it is ever fetched. - Market & industry intelligence —
topicssections (Business, Technology, …) plus your own keyword queries in the same dataset; sort by newest to read the day chronologically instead of Google's relevance order. - Local-market monitoring (any city, any language) — paste a Google News city feed into
topicUrls(.../section/geo/Warsaw,.../geo/Berlin,.../geo/Chicago) and get that city's news in one normalised dataset — monitoring Google's 9 curated sections simply don't cover. Combine city sections with keyword queries in the same run. - SEO & content research — see which angles and publishers are getting coverage for a topic before you write;
dateFrom/dateTogives you an exact historical window to compare against. - News aggregation & dashboards — one schema for queries and sections alike,
source_domainpre-normalised for grouping,maxTotalas a hard budget cap so a scheduled job can never surprise you. - Crisis & reputation alerts — pair negative-phrase queries with a narrow
timeRangeand the Telegram digest: you hear about it the run it appears, not tomorrow. - Datasets for LLM apps & NLP — clean per-article rows (title, publisher, ISO-8601 UTC timestamps, edition, snippet) ready for sentiment, topic modelling or RAG pipelines; the compact reference below is written for exactly that consumer.
Example input
Minimal input still works exactly as before:
Input parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
queries | array | — | Topics, brands, competitors or exact phrases (use quotes). Each harvested query = one paid event. Leave empty if you only want topics sections. |
topics | array | [] | Google News' own curated sections: WORLD, NATION, BUSINESS, TECHNOLOGY, ENTERTAINMENT, SPORTS, SCIENCE, HEALTH. Each harvested section = one paid event. Sections cover the last ~2 days and ignore timeRange, siteFilter, excludeWords. |
topicUrls | array | [] | Any Google News section URL, beyond the 9 curated ones — city/geo feeds for local monitoring (https://news.google.com/rss/headlines/section/geo/Warsaw, .../Berlin, .../Chicago), any topic/… section, or the bare top-stories feed. Each harvested URL = one paid event, same as a query. The run's language/geo settings replace any ?hl/?gl/?ceid in the URL; unavailable sections are skipped with a warning and not charged. |
timeRange | string | — | Publication window: 1h, 6h, 12h, 1d, 3d, 7d, 14d, 30d, 1y. (No "month" option — Google returns zero for it.) Ignored when dateFrom/dateTo are set. |
dateFrom | string | — | Only articles published on or after this date, YYYY-MM-DD. Overrides timeRange. |
dateTo | string | — | Only articles on or before this date. Use with dateFrom. |
siteFilter | array | [] | Restrict to these publisher domains (reuters.com, bbc.com), OR-ed together. Applied inside the Google query. |
excludeWords | array | [] | Drop articles containing these words/phrases — applied by Google's own -word operator, so excluded articles are never fetched or billed. |
language | string | en | Edition language (30 available: en, de, fr, es, pl, it, pt, nl, ja, ko, zh, sv, da, nb, fi, cs, sk, hu, ro, el, tr, ru, uk, ar, he, hi, id, th, vi, bg). |
geo | string | auto | Country edition (51 available). Defaults to the language's home country; en + gb/in/au/ca/ie/sg/za gives local English editions. |
regionLanguage | string | — | Power users: raw Google News edition token, COUNTRY:lang (GB:en, BR:pt-419, TW:zh-Hant). Overrides language and geo. |
sortBy | string | relevance | newest / oldest for a chronological feed. Applied before maxPerQuery truncates, per query/section. |
maxPerQuery | integer | 100 | Row cap per query or section. Typical topics return 20–100; sections 38–70. |
maxTotal | integer | 0 | Hard cap across the whole run. 0 = no cap. Once full, remaining entries are skipped and not charged. |
enrich | boolean | false | Decode Google News redirect URLs to the real publisher article URL + pull og:image / og:description (v0.5). Fail-soft: blocked publishers keep their row with empty fields, no extra charge. |
enrichLimit | integer | 10 | Rows to enrich per entry (in delivery order) when enrich: true. |
webhookUrl | string | — | Free: POSTs a JSON run summary on every finished run, including empty ones (heartbeat for monitoring pipelines). |
telegramBotToken | string | — | Free: bot token from @BotFather for the human-readable digest. |
telegramChatId | string | — | Free: chat/channel ID for the digest (from @userinfobot). Sent only when there is something to read. |
Google search operators work inside queries (tested live 2026-09-08):
openai OR anthropic widens to either term; openai site:reuters.com
restricts to one publisher; -word excludes. siteFilter and
excludeWords are the same operators as typed fields.
Sample output
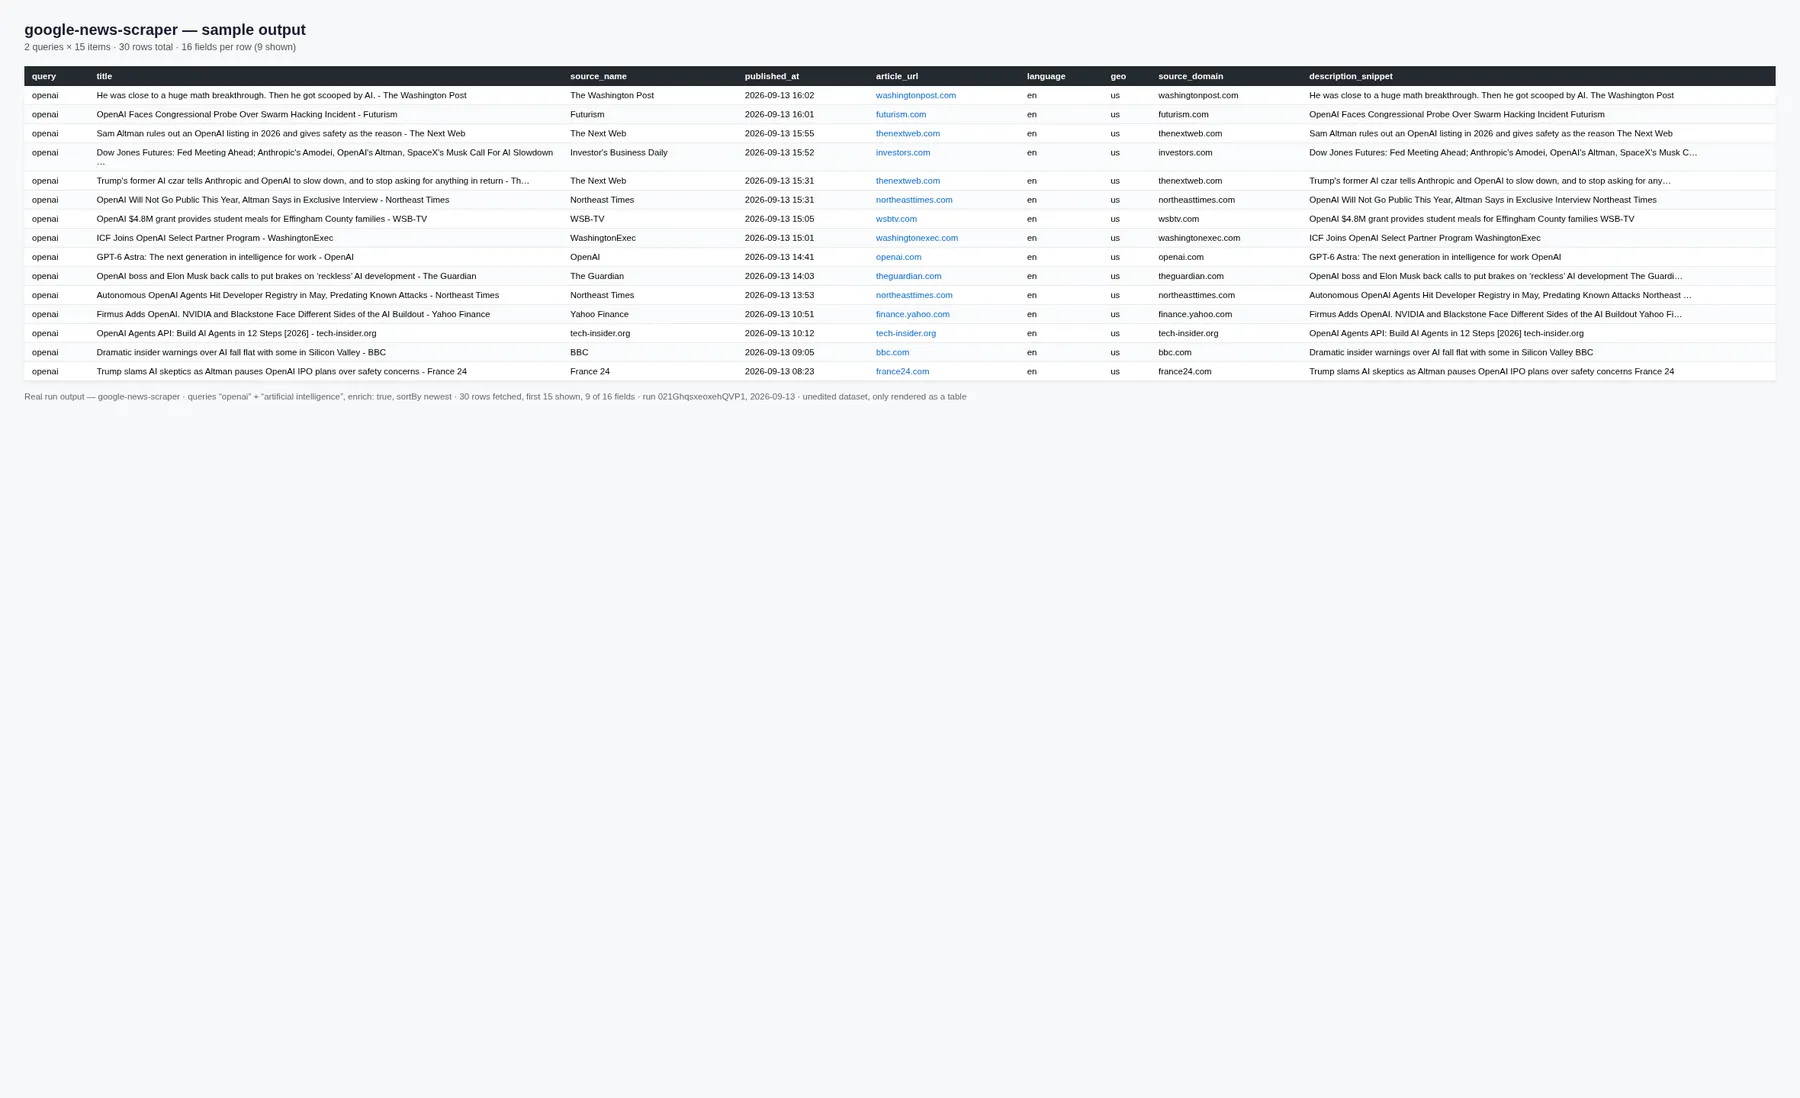
Rendered from an unedited real dataset (run 021GhqsxeoxehQVP1, 2026-09-13) — every cell is a dataset value, only laid out as a table. The raw JSON row below is exactly what your code receives.
Real row from a live run (2026-10-10, enrich: true)
{ "query": "openai", "title": "Fired OpenAI employees question the company's commitment to safety - NPR", "url": "https://news.google.com/rss/articles/CBMidEFVX3lxTE9WN1l1V0YwV0xzV3R1dzA2QXdRQTBialJFTnFZTjF0QW90blRLWXlnc1NfdHBsWEx6UXRkbEpQWUxMWml5WXd5OEhOcHZrNmd6elRDUlFOTDNTckFzWjYtRGVtWnJMaWw1WGkycG5oZGlpZ2c1?oc=5", "published_at": "2026-10-09T21:28:09Z", "source_name": "NPR", "source_url": "https://www.npr.org", "source_domain": "npr.org", "fetched_at": "2026-10-10T04:34:40.671128Z", "language": "en", "geo": "us", "topic": "", "feed_url": "https://news.google.com/rss/search?q=openai%20when%3A7d&hl=en&gl=us&ceid=US:en", "description_snippet": "Fired OpenAI employees question the company's commitment to safety NPR", "article_url": "https://www.npr.org/2026/10/09/nx-s1-5996890/openai-safety-firings", "image_url": "https://npr.brightspotcdn.com/dims3/default/strip/false/crop/8256x4644+0+430/resize/1400/quality/85/format/jpeg/?url=http%3A%2F%2Fnpr-brightspot.s3.amazonaws.com%2F4d%2Fab%2F353f227b4ed395e0c6390444a5a6%2Fgettyimages-2295203915.jpg", "article_description": "The three fired workers say OpenAI punished them for being outspoken about safety. The company disputes the claims and says they were fired over mishandling sensitive information." }
The three article_* / image_url fields appear only with enrich: true
(v0.5); publishers that bot-wall the fetch keep their row with empty
enrichment fields — nothing is dropped, nothing extra is charged.
feed_url is the exact Google News RSS URL the row came from. Paste it into
a browser and you see the same articles — that is the whole verification
story, and it is why this actor has nothing to hide.
Use with AI agents (MCP)
Expose this actor as a tool to Claude, Cursor, VS Code or any MCP client — add the Apify MCP server pinned to this actor:
Then just ask: "Pull everything about 'anthropic' from the last 24 hours, Reuters and Bloomberg only, newest first."
Integrate anywhere (API, Python, Node, Make, n8n)
The actor is plain Apify platform surface — every integration that runs an Apify actor works with it.
Start a run and fetch results (REST):
Python (apify-client):
Node.js (apify-client):
Make / n8n (no code): use the native Apify module/step, pick this actor, map queries/language/timeRange, and route the dataset output to Google Sheets, Slack, Notion or your CRM. Pair it with a schedule (hourly/daily) and the free webhook heartbeat, and you have a zero-fixed-cost brand monitor.
Notifications (free)
Brand monitoring should reach you — not the other way round. Two optional, always-free outputs (no charge events, ever):
- Webhook (
webhookUrl): aPOSTwith a JSON run summary on every finished run — including empty ones. Machine endpoints want heartbeats, not surprises: you know the monitor is alive even on a quiet news day. Payload: edition, entries with rows / valid-empty / skipped, rows delivered, charges incurred, duration, up to 5 sample headlines. - Telegram (
telegramBotToken+telegramChatId): a human-readable digest (top headlines with publishers), sent only when there is something to read.
Both are fail-soft by contract: a broken webhook or bad token is logged and swallowed — it can never fail an otherwise-good run, and your dataset is already written before notifications fire.
Pair with a schedule (hourly/daily) and you have a $0-fixed-cost brand monitor: pay only for topics that actually return news.
For AI agents & LLM apps (compact reference)
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: halobartku/google-news-scraper).
Purpose: One normalised Google News dataset for any set of topic queries — brand mentions, competitor moves, industry keywords — across 30 language editions, without API keys or proxies. Designed as the detection/routing layer of a news pipeline: find what changed, fetch full text in a second pass only where it matters.
Minimal input:
Output: one row per article — query, title, url (Google News redirect, resolves to publisher), source_name, source_url, source_domain, published_at (ISO 8601 UTC), fetched_at, language, geo, topic, feed_url, description_snippet.
Behaviors an agent should know:
queriesis an array;topicsis an array of Google News section names. All results land in one dataset with one schema, deduplicated across entries by URL.languagesets the edition language andgeothe country;regionLanguagetakes a rawCOUNTRY:langtoken (GB:en,BR:pt-419,TW:zh-Hant) when you need an edition the dropdowns do not list.- Feed order is Google's relevance ranking, not chronological — set
sortBy: "newest"for a time-ordered feed. Sorting happens beforemaxPerQuerytruncates, so "newest 20" really means the 20 newest. Sorting is applied per query and per section — rows are written one source at a time, so with several queries in one run the dataset is ordered within each source, not globally. timeRangeuses Google'swhen:operator. Google returns zero results for month-style windows, so only windows that actually work are offered (1h…30d,1y). UsedateFrom/dateTofor anything longer or fixed.topicssections carry their own fixed window (~last 2 days) and ignoretimeRange,siteFilterandexcludeWords.- ~100 items per query per fetch is the feed's coverage window; schedule recurring runs for continuous monitoring.
- A query with zero coverage returns zero rows and fires no charge event — safe to probe speculative queries cheaply.
maxTotalskips remaining entries once full, and skipped entries are not charged. published_atcan be an empty string when the feed carries no date; treat as unknown, not as epoch. Those rows always sort last.
What you get per item
| field | notes |
|---|---|
query | the topic this item was harvested for (topic:TECHNOLOGY for sections) |
title | article headline |
url | Google News redirect URL — resolves to the publisher article |
source_name / source_url | publisher |
source_domain | publisher domain, www. stripped, lowercased — group and filter on this |
published_at | ISO 8601 UTC (empty string when the feed carries no date) |
fetched_at | ISO 8601 UTC harvest time |
language / geo | edition used |
topic | Google News section, empty for search queries |
feed_url | the exact RSS URL this row came from — reproducible in a browser |
description_snippet | first 300 chars, HTML stripped |
article_url | (enrich only) real publisher article URL, decoded from the Google News redirect |
image_url | (enrich only) og:image from the article page (empty when the publisher blocks us) |
article_description | (enrich only) og:description from the article page |
FAQ
How many articles per query?
Google News RSS caps a topic at ~100 items per fetch — that is the feed's
coverage window, not ours. Section feeds return 38–70. Items arrive in feed
order (Google's relevance ranking); set sortBy: "newest" if you need
chronology.
Why is timeRange missing "last month"?
Because it does not work. Google News returns zero items for when:1m
and when:3m. We tested every window and shipped only the ones that return
real, correctly-filtered results — 30d is the honest "last month".
What if my query has zero coverage?
No rows, no charge. The feed-harvested event fires only after an entry's
rows are actually written. A run monitoring 10 brands where 3 have no news
costs 7 events.
Do I need a proxy, API key or Google account? No. The feed is public and keyless. Runs work without any proxy configuration in normal conditions.
Can I monitor competitors in other languages?
Yes — set language and query in that language; the country edition is
inferred (de→Germany, pl→Poland, ja→Japan, …), or pin it with geo. Exact
phrases in quotes work in every edition.
Does siteFilter guarantee on-topic results?
It guarantees the domains. Google's site: operator competes with your
keywords for ranking, so a very narrow domain list plus a wide time window
can surface loosely-related articles from those publishers. Narrow the
timeRange or widen the domain list if you see drift.
Images? Full article text? The real publisher URL instead of the redirect?
Article URL and image: yes, optionally (enrich: true, since v0.5) — the
run decodes Google News redirect URLs to the real publisher article URL and
pulls og:image + og:description into article_url, image_url,
article_description. Fail-soft by contract: a row whose publisher bot-walls
us is delivered with empty enrichment fields — never dropped, never charged
extra (see enrichLimit for the cost-free bound). Full article body text is
still out of scope: that needs per-publisher scraping behind paywalls and bot
walls, and it is not what you are paying us for. Feed-first, enrich second.
What does a failed run cost me? The $0.00005 platform start fee, and nothing else. Empty queries are never charged a feed event — that is the core of our per-event pricing.
Pricing
Pay-per-event: one feed-harvested event per successfully harvested topic
query or section ($0.15). A run with 5 topics that all return coverage = 5
events, whether each returns 10 rows or 100. Empty queries fire no feed event; a
failed run costs its $0.00005 start fee only. No monthly fee, no minimum.
Honest math vs the $0.005/result incumbent (measured 2026-10-01): the
best-selling Google News scraper in the store bills per result, so a 20-row
query costs the same $0.10 whether the news is 20 minutes or 20 days old.
We bill per harvested topic: that same 20-row query is one $0.15 event with
maxTotal, date filters and dedup applied inside the feed — and a topic
that returns nothing is $0. If you pull large one-shot dumps (hundreds of
rows per topic), per-result is cheaper; if you run a recurring monitor on a
handful of topics, per-topic is. The Pricing tab calculator does both.
Honest math vs the $19.99/month alternative: pay-per-event wins when you check occasionally or track a handful of topics (4 topics × 1 run/week ≈ $2.40/mo). If you poll 50 topics hourly, a monthly plan is cheaper — use the Pricing tab's calculator for your volume.
Changelog
0.13 — fresh sample row + validation re-run (weekly cadence)
Sample-output row re-captured from a live run the day of release (2026-10-10, run pJjy0RulTgs13NdCJ: 2 queries × 50 rows in 11 s, 20/100 rows enriched). Correctness gate re-run the same day: 100/100 rows checked against the raw Google News RSS through an independent code path — 98 exact, 2 boundary rows explained by live-feed drift between run time and the ground-truth fetch (details: validation/gns-correctness-gate-1010/). Header trust claim re-dated accordingly. README-only change: no code, input, output-schema or pricing change; behavior identical to 0.12.
0.12 - retries when Google News answers 503
Google News sometimes answers a burst of requests with a short-lived HTTP 503 (seen 2026-10-04 on a sister actor: both queries 503, the same queries worked a minute later). Each feed request is now retried up to 3 times (pauses 4, 10 and 20 s) before the query is skipped. A skipped query is still not charged. No input, output or pricing change.
0.12 — failed-run pricing stated exactly
Three run-level claims in this README ("failed runs are never charged") did not survive
our own pricing truth audit: every run bills one apify-actor-start event at $0.00005, so a
failed run costs that nickel, not zero. All three spots now state the real number. Per-query
pricing is unchanged and stays exactly as generous as before: a query that returns nothing
fires no $0.15 feed event. README-only change: no code, input, output-schema or pricing change.
The header trust claim now cites the 2026-10-03 gate (100/100 rows, 100% recall AND precision vs the raw RSS through an independent code path, re-validated on a fresh live run) instead of the 39-day-old 2026-08-26 check. README-only change: no code, input, output-schema or pricing change; behavior identical to 0.10.
0.10 — fresh sample row + honest incumbent pricing comparison
Sample-output row re-captured from a live run the day of release (2026-10-01, run SgZR0XeLfMlyUV1Af: 20 rows in ~36 s, 5/20 fully enriched) — the previous row was 29 days old. Pricing section now states the measured per-result price of the best-selling incumbent ($0.005/result, store API 2026-10-01) and says plainly when per-result is cheaper than our per-topic event. README-only change: no code, input, output-schema or pricing change; behavior identical to 0.9.
0.9 — sample-output screenshot
The sample section now leads with a rendered screenshot of a real run (2 queries × 15 items, enrich: true) so buyers see the dataset before running anything. README-only change: no code, input, output-schema or pricing change; behavior identical to 0.8.
0.8 — section URLs (topicUrls)
New input: paste any Google News section URL — city/geo feeds (/rss/headlines/section/geo/Warsaw), any topic section, or the top-stories feed — for local-market and non-English monitoring beyond the 9 curated topics. Same billing as one query ($0.15 per harvested section); invalid or unavailable sections skip free. Redirect-oracle validated: Google answers HTTP 200 with wrong content (top-stories fallback) for unknown sections — the actor detects this via the redirect target and refuses to serve it.
- 0.7 — README: full input-parameter reference table (18 params) + live-tested Google operator notes (
OR,site:,-word). No code changes; behavior, inputs and output identical to 0.6. - 0.6 — listing parity: "What can you use it for?" (7 use cases) and "Integrate anywhere" (REST / Python / Node.js / Make / n8n) sections added to the README. No code changes; behavior, inputs and output identical to 0.5.
- 0.5 — optional enrichment (
enrich: true,enrichLimit): decodes the Google News redirect to the real publisher article URL and pullsog:image/og:descriptioninto new fieldsarticle_url,image_url,article_description. Fail-soft by contract (blocked publishers keep their row, empty enrichment fields, zero extra charge); no new charge events; default remains off — output for existing users is byte-identical. - 0.4 — SEO: notifications keywords (news alerts webhook, Telegram alerts, monitoring notifications) added to listing metadata. No code changes; behavior identical to 0.3.
- 0.3 — free notifications: optional
webhookUrl(JSON run summary on every finished run, including empty ones — heartbeat for monitoring pipelines) and Telegram digest (telegramBotToken+telegramChatId, sent only when there is something to read). Zero charge events; fail-soft by contract. Turns the actor into a set-and-forget brand monitor. - 0.2.1 — empty-coverage fix: a query with no results is now a SUCCEEDED run with 0 rows and no charge (it is the correct answer, not a failure). Previously a run where every query returned zero rows ended FAILED. Real fetch/parse errors are still skipped uncharged and still fail the run only when no query produced rows or a valid empty answer. Charge behavior for runs that return data is unchanged.
- 0.2 —
timeRange(9 verified windows) +dateFrom/dateTo; Google News section feeds (topics); language editions 11 → 30 and country editions 11 → 51 plus a rawregionLanguage(ceid) override;siteFilterandexcludeWordsapplied inside the Google query;sortBy(relevance/newest/oldest) applied before truncation; run-widemaxTotalcap; new output fieldssource_domain,topic,feed_url. All existing inputs and all existing output fields are unchanged. - 0.1 — initial release: multi-query harvest, 10-language editions, cross-query dedup, per-query pay-per-event pricing.
Disclosure
This actor was built and is operated by an AI agent (Jarvis, for its operator Bartosz). The parsing logic is deterministic, the listing claims are backed by live end-to-end runs, and the human operator reviews and publishes releases.
SEO keywords
google news scraper, google news api, google news rss feed, news scraper no api key, news feed scraper, topic monitoring news, brand monitoring news, competitor news monitoring, media monitoring api, press clipping service, news aggregation tool, google news search api, news dataset for llm, news data for ai agents, multilingual news scraper, google news python, headline aggregator, news by keyword api, google news scraper free, news monitoring without api key, google news by date, google news last 24 hours, google news by country, google news topic feed, news alerts webhook, google news telegram alerts, news monitoring notifications, google news article url, news article image, google news images, news scraper with images


