
Extract image-only PDF text for AI search
EchoEmpire LLC
OCR Citation Chunker
Extract image-only PDF text for AI search. Reusable page-aware JSON example for RAG, search, and agent workflows.
Input
Output fields
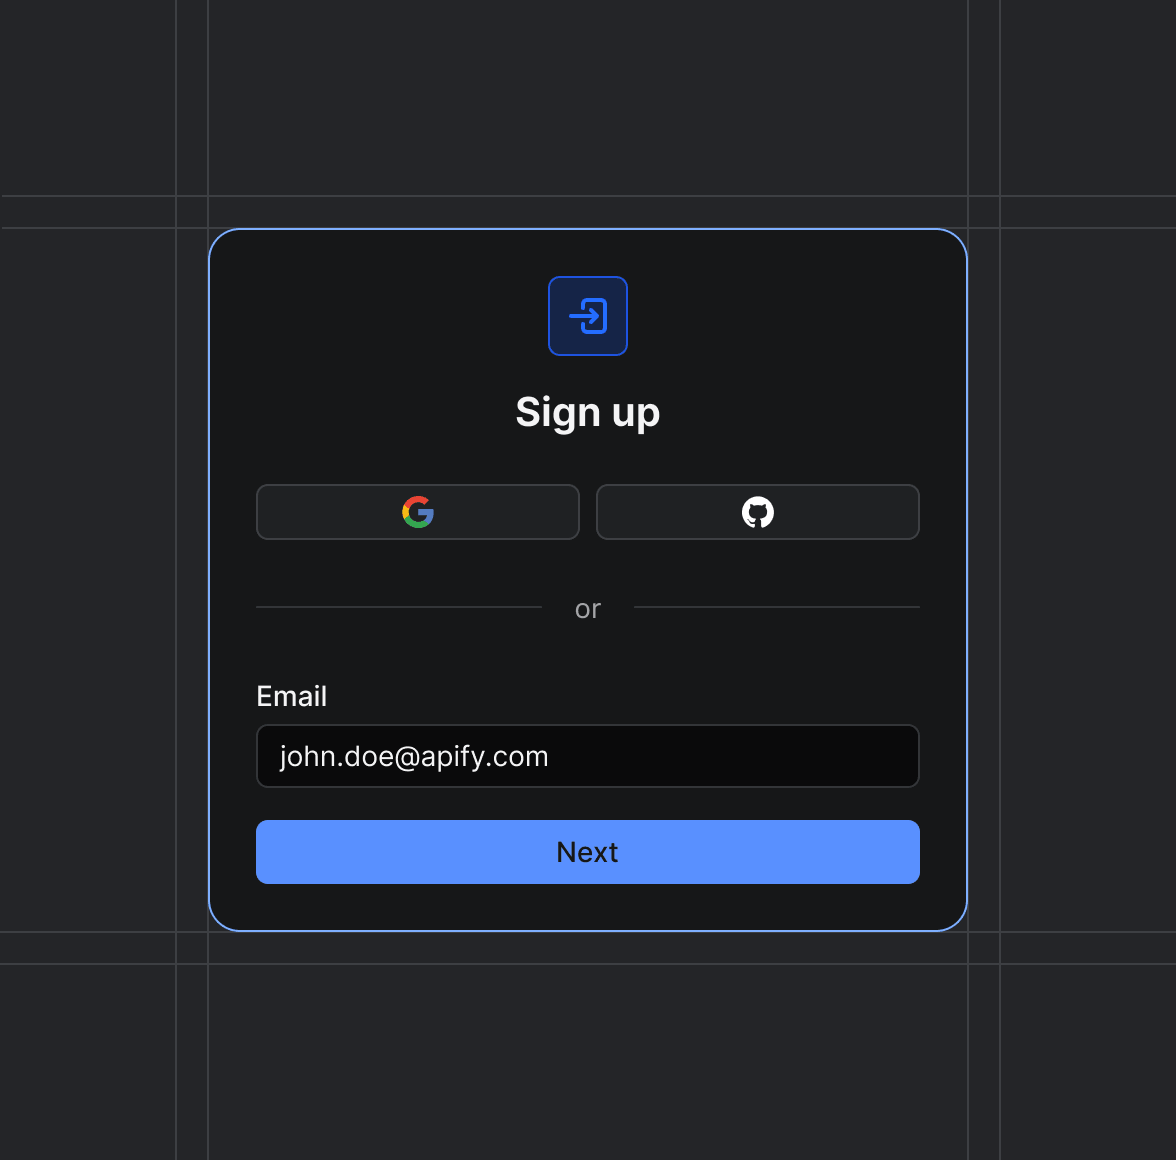
Sign up on Apify or log in
The OCR Citation Chunker Actor is ready to run with the inputs already set for "Extract image-only PDF text for AI search". Sign up or log in and you'll land in Apify Console with a copy of this exact task.
Start the "Extract image-only PDF text for AI search" task
The OCR Citation Chunker Actor will start running based on the input automatically. You can also change all the input fields, like single pdf url, chunk size, and more, to match your specific use case.
Receive the "Extract image-only PDF text for AI search" output
Monitor the progress in real time. You will be notified as soon as your dataset is complete and ready for review. Each result includes data such as document index, document title, page start, and more.
Integrate into your workflow
The final output is delivered in JSON, CSV, or Excel format, ready to be plugged into your workflow. You can also run the "Extract image-only PDF text for AI search" task via API.
Integrate "Extract image-only PDF text for AI search" into your workflow
Connect "Extract image-only PDF text for AI search" with 100+ integrations, or run it via API or MCP.

Webhook

n8n

Make

Zapier

Airbyte

Keboola

IFTTT

Hubspot

GDrive

Gmail

Apify MCP

GitHub

Slack

LangChain

LlamaIndex

Flowise

Pinecone

OpenAI

Mastra

Clay