
BambooHR Scraper [Only $0.90/1K💰] | Jobs | Salary | Openings
Pricing
from $0.85 / 1,000 results
BambooHR Scraper [Only $0.90/1K💰] | Jobs | Salary | Openings
Extract every open role from any BambooHR careers board - title, department, location, remote flag, salary and full description - via BambooHR's public JSON endpoints. Build job feeds, hiring-intent lists and labour-market datasets with no API key, no login and no browser.
Pricing
from $0.85 / 1,000 results
Rating
0.0
(0)
Developer

Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
BambooHR Scraper
BambooHR scraper that pulls every open job from any company's BambooHR careers board through the same public JSON endpoints the careers page itself uses - job title, department, location, remote status, salary, full description and apply URL. No login, no API key and no browser.
Main Use Cases
- Build a live job-board or ATS aggregation feed from thousands of SMB career pages
- Collect hiring-intent signals for recruiters, staffing agencies and B2B sales teams
- Run labour-market and salary research across companies, departments, countries and cities
- Monitor new and updated openings for a watchlist of target companies
- Enrich CRM and lead lists with the roles a prospect is currently hiring for
How It Works
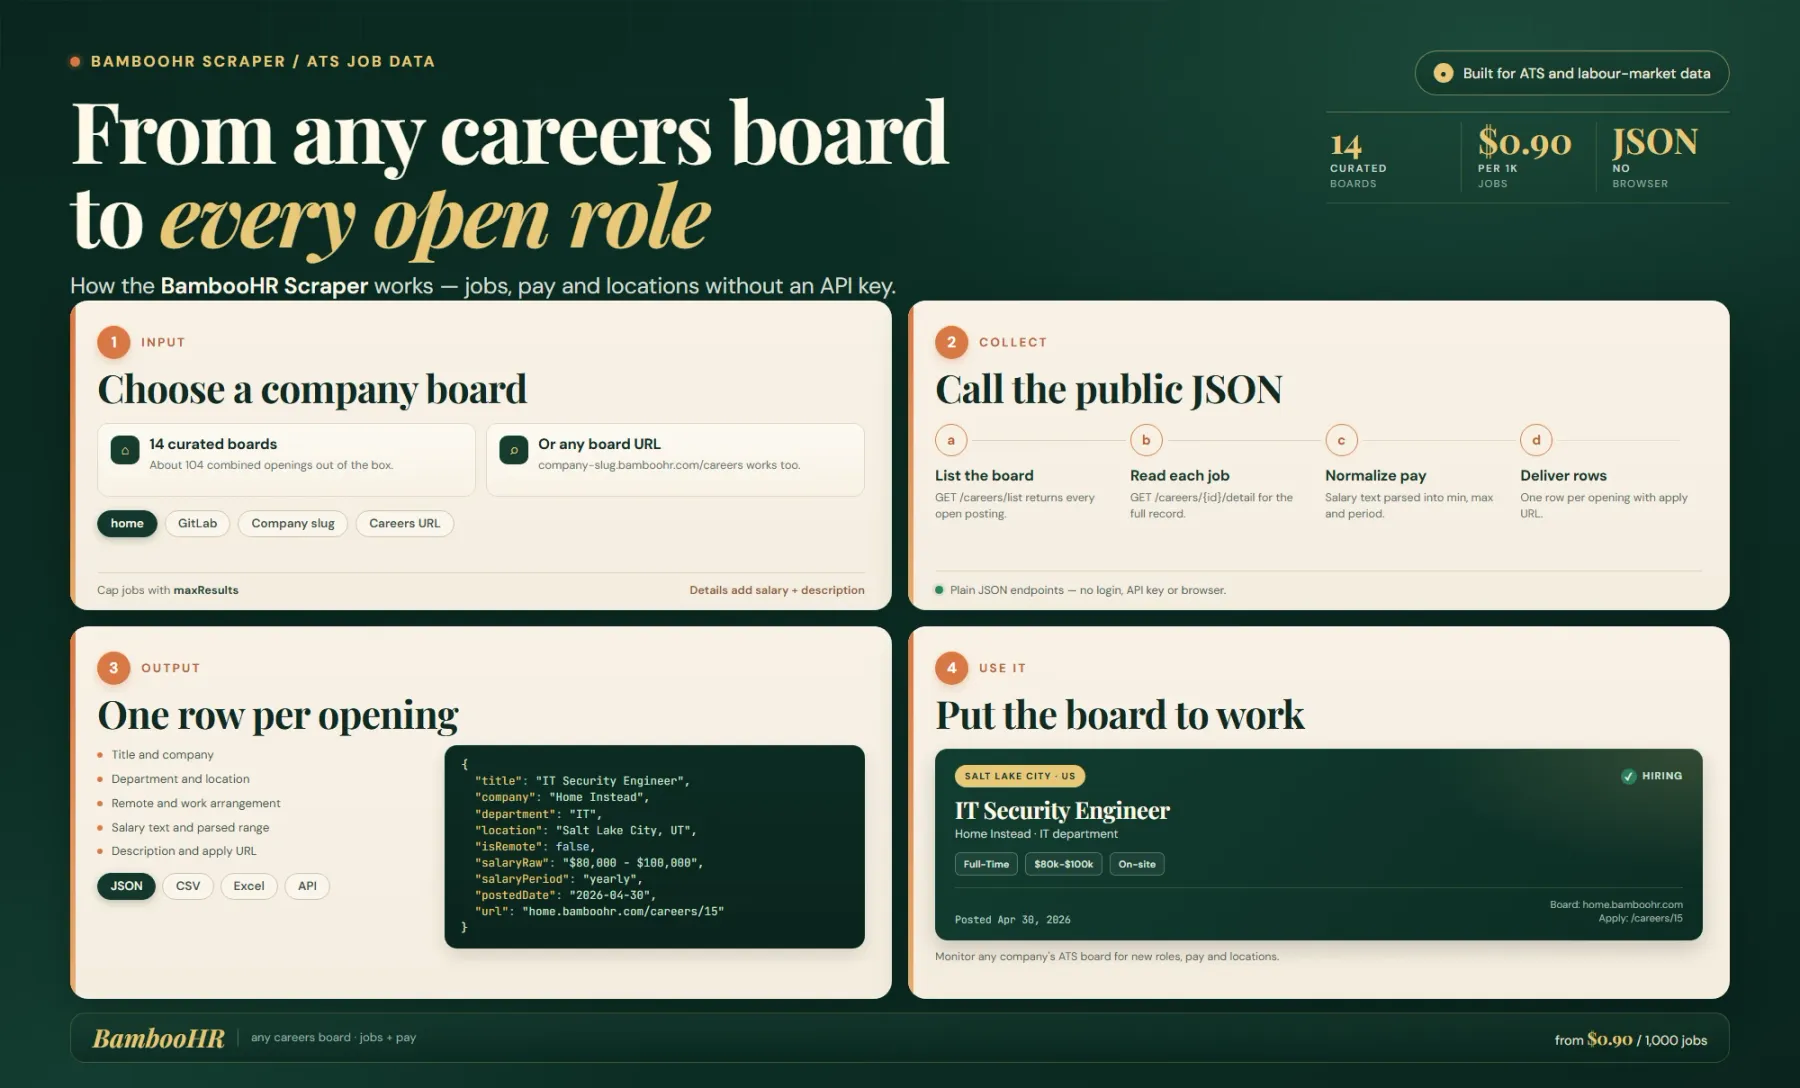
BambooHR hosts a public careers page at https://{company-slug}.bamboohr.com/careers. That page loads its data from two unauthenticated JSON endpoints, which this actor calls directly with a plain HTTP crawler:
GET https://{slug}.bamboohr.com/careers/listreturns a JSON index of every open posting (id, title, department, employment status, city/state, remote flags).GET https://{slug}.bamboohr.com/careers/{id}/detailreturns the full record for one job - HTML description, free-text compensation, posting date, structured location and share URL.
The company display name is not in the JSON, so it is read once per board from the og:site_name meta tag on the careers HTML. Because the endpoints are plain JSON, the actor runs on a lightweight Cheerio (HTTP) crawler - no headless browser is involved. Dead or suspended tenants redirect to the BambooHR marketing site instead of returning JSON, and those boards are logged and skipped rather than failing the run.
Scrape BambooHR Job Listings Without An API Key
BambooHR's official jobs API ("Get Job Summaries") requires OAuth and an authenticated caller with access to ATS settings, and it only returns jobs for the account that authenticates. The public careers feed that this actor reads needs no credentials, works for any company hosted on BambooHR, and returns the same postings the employer already publishes to every visitor - including the description, country and pay text that the official summaries endpoint does not carry.
Because BambooHR has no public directory of company slugs, you supply the boards you want either as a bare subdomain (home) or as a full URL (https://home.bamboohr.com/careers).
Input
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
boards | string[] | No | 14 curated boards (~104 combined openings) | Company slugs ("home") or full board URLs ("https://home.bamboohr.com/careers"). Both forms are accepted per entry. |
maxResults | integer | No | 100 | Maximum job postings returned in total across all boards. Range 1-5000. |
includeDescription | boolean | No | true | Fetch each job's detail page for the full description, salary text, country and posting date. Turn off for a faster list-only scrape (title, location, department, type). |
proxy | object | No | off | Apify Proxy picker. Only needed if a specific board rate-limits datacenter IPs. |
Output
One dataset item per job opening:
| Field | Description |
|---|---|
jobId | Job opening ID on the BambooHR board |
title | Job title |
company | Company display name (from the board HTML) |
companySlug | BambooHR subdomain, e.g. home for home.bamboohr.com |
boardUrl | Root URL of the company careers board |
department | Department label |
employmentType | Employment status/type, e.g. Full-Time |
location | Combined location string |
city, state, country, postalCode | Structured location fields |
isRemote | true when the posting is explicitly remote, null when unknown |
workArrangement | "remote" when remote, otherwise null |
locationType | Raw BambooHR locationType code |
salaryRaw | Compensation exactly as the employer wrote it |
salaryMin, salaryMax | Best-effort parsed salary bounds |
salaryCurrency | USD / EUR / GBP / CAD / AUD when detectable |
salaryPeriod | hourly / monthly / yearly |
postedDate | ISO date the opening was posted |
descriptionText | Plain-text job description |
descriptionHtml | Original HTML job description |
url, applyUrl | Public posting and application URL |
scrapedAt | ISO timestamp of the scrape |
Example Input
Example Output
Integrations & Automation
- Apify API / JavaScript / Python clients - pull the dataset programmatically for a job board, CRM or data warehouse.
- Webhooks - trigger a downstream workflow whenever a run finishes.
- Zapier, Make, Google Sheets - push new openings into a spreadsheet or alerting channel.
- Scheduling - run daily (or a few times a day) over a company watchlist to catch new and updated roles quickly. Recurring runs are the recommended way to use this actor as a hiring-intent feed.
Related Actors
- BambooHR Jobs Scraper & API - Any Company - the most established BambooHR scraper in the Store.
- BambooHR Jobs Scraper - multi-tenant BambooHR careers scraper.
- BambooHR Jobs Scraper - Any Company Careers (No Key) - list-only variant.
- Apna Scraper - India blue-collar job listings for a non-ATS source.
- Welcome to the Jungle Scraper - tech-job listings to round out a multi-source jobs dataset.
FAQ
Why use this actor instead of the official BambooHR API?
BambooHR's official "Get Job Summaries" endpoint requires OAuth authentication and an account with access to ATS settings - it returns the openings of the authenticated account only. This actor reads the public careers feed that every BambooHR-hosted company already serves to visitors, so you can collect jobs from any company you know the subdomain for, with no credentials and no per-account setup.
How can I collect job postings from a company that is not in the default board list?
BambooHR has no public directory of company subdomains, so you add boards yourself: pass the company's subdomain (for https://acme.bamboohr.com/careers, use acme) or the full careers URL in the boards field. If a company embeds its board in its own website, view the page source and look for a *.bamboohr.com host.
What are alternatives to this actor?
If you need a hosted jobs API instead of scraping, BambooHR's own jobs API (with an account and OAuth scope) or third-party normalized-jobs APIs are options - but they require credentials and typically only cover the accounts or employers they index. For a self-contained, keyless scrape of any BambooHR board, this actor is the direct route.
Why are some fields null?
BambooHR exposes remote status, country and salary inconsistently across tenants. isRemote is null when the employer left it unspecified (it does not mean "on-site"), salary is free text so it is empty on postings without published pay, and evergreen postings can carry a postedDate far in the past even though the role is still open.
For AI Agents & LLM Apps
Purpose: return one structured record per open job on any BambooHR careers board, from the public /careers/list and /careers/{id}/detail JSON endpoints.
Minimal working input:
Output fields: jobId, title, company, companySlug, boardUrl, department, employmentType, location, city, state, country, postalCode, isRemote, workArrangement, locationType, salaryRaw, salaryMin, salaryMax, salaryCurrency, salaryPeriod, postedDate, descriptionText, descriptionHtml, url, applyUrl, scrapedAt.
Behaviors an agent should know:
boardsis the only field that selects the data; if it is omitted, the actor scrapes a default curated set of 14 boards, not "all companies" - there is no public subdomain directory.maxResultsdefaults to 100 and caps total rows (1-5000); set it explicitly for large runs.includeDescriptiondefaults totrueand issues one extra HTTP request per job. Turning it off keepstitle,department,employmentTypeandlocationbut leavesdescriptionText,descriptionHtml,salary*,countryandpostedDateempty.- Dead/suspended tenants are skipped and logged; a board that returns HTML instead of JSON yields no rows rather than an error.
Billing: pay-per-event, charged per result row (about $0.90 per 1,000 jobs on the free tier, lower on paid Apify plans), plus the one-time actor-start event.
Legal & Compliance Disclaimer
This actor is independent and is not affiliated with, endorsed by, or sponsored by BambooHR. It accesses only publicly available career pages and the public JSON endpoints those pages call; it does not log in, bypass authentication, or solve CAPTCHAs on any account-gated surface. Users are responsible for complying with BambooHR's and the source companies' terms of service and with applicable data-protection law when storing or republishing the collected job data. The dataset contains company job-posting information, not private personal contact data.
SEO Keywords
bamboohr scraper, bamboohr jobs api, bamboohr careers scraper, scrape bamboohr job listings, bamboohr api alternative, hiring intent data, job posting api, ats job scraping, company careers page scraper, job board aggregator data, remote job listings api, salary data extraction, job listing monitoring, recruiting intelligence, greenhouse lever bamboohr jobs, applicant tracking system data, smb hiring data, job openings dataset


