
HigherEdJobs Scraper [$1.4/1K💰] | Academic Jobs | Faculty Data
Pricing
from $1.30 / 1,000 results
HigherEdJobs Scraper [$1.4/1K💰] | Academic Jobs | Faculty Data
Extract faculty, administrative and executive job postings from HigherEdJobs.com — titles, institutions, locations, salaries, categories, deadlines, descriptions and apply links. Built for academic job-market research, salary benchmarking and higher-ed hiring intelligence. $1.40 per 1,000 jobs.
Pricing
from $1.30 / 1,000 results
Rating
0.0
(0)
Developer
Ahmed Jasarevic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Security
Limited permissionsShare
HigherEdJobs Scraper
Extract faculty, administrative and executive job postings from HigherEdJobs.com — job titles, hiring institutions, locations, published salaries, categories, application deadlines, full descriptions and direct apply links — in structured JSON.
Built for academic job-market research, faculty salary benchmarking, higher-education hiring intelligence and university-career-data pipelines.
Track Faculty and Executive Hiring Across US Higher Education
- Academic job-market research — faculty, administrative and executive openings across US colleges and universities in one dataset.
- Salary benchmarking — capture published salary text (
salaryText) wherever institutions disclose it. - Institution-level hiring intelligence — which universities hire, for which disciplines, in which states, on what timeline.
- Job-aggregation feeds — normalized rows (title, institution, location, categories, apply URL) ready for boards or AI matching.
- Deadline & pipeline monitoring — application deadlines (
validThrough) and posted dates for time-sensitive tracking. - Discipline-level analysis — structured categories (Physics, Computer Science, Nursing …) for field-by-field comparisons.
How It Works
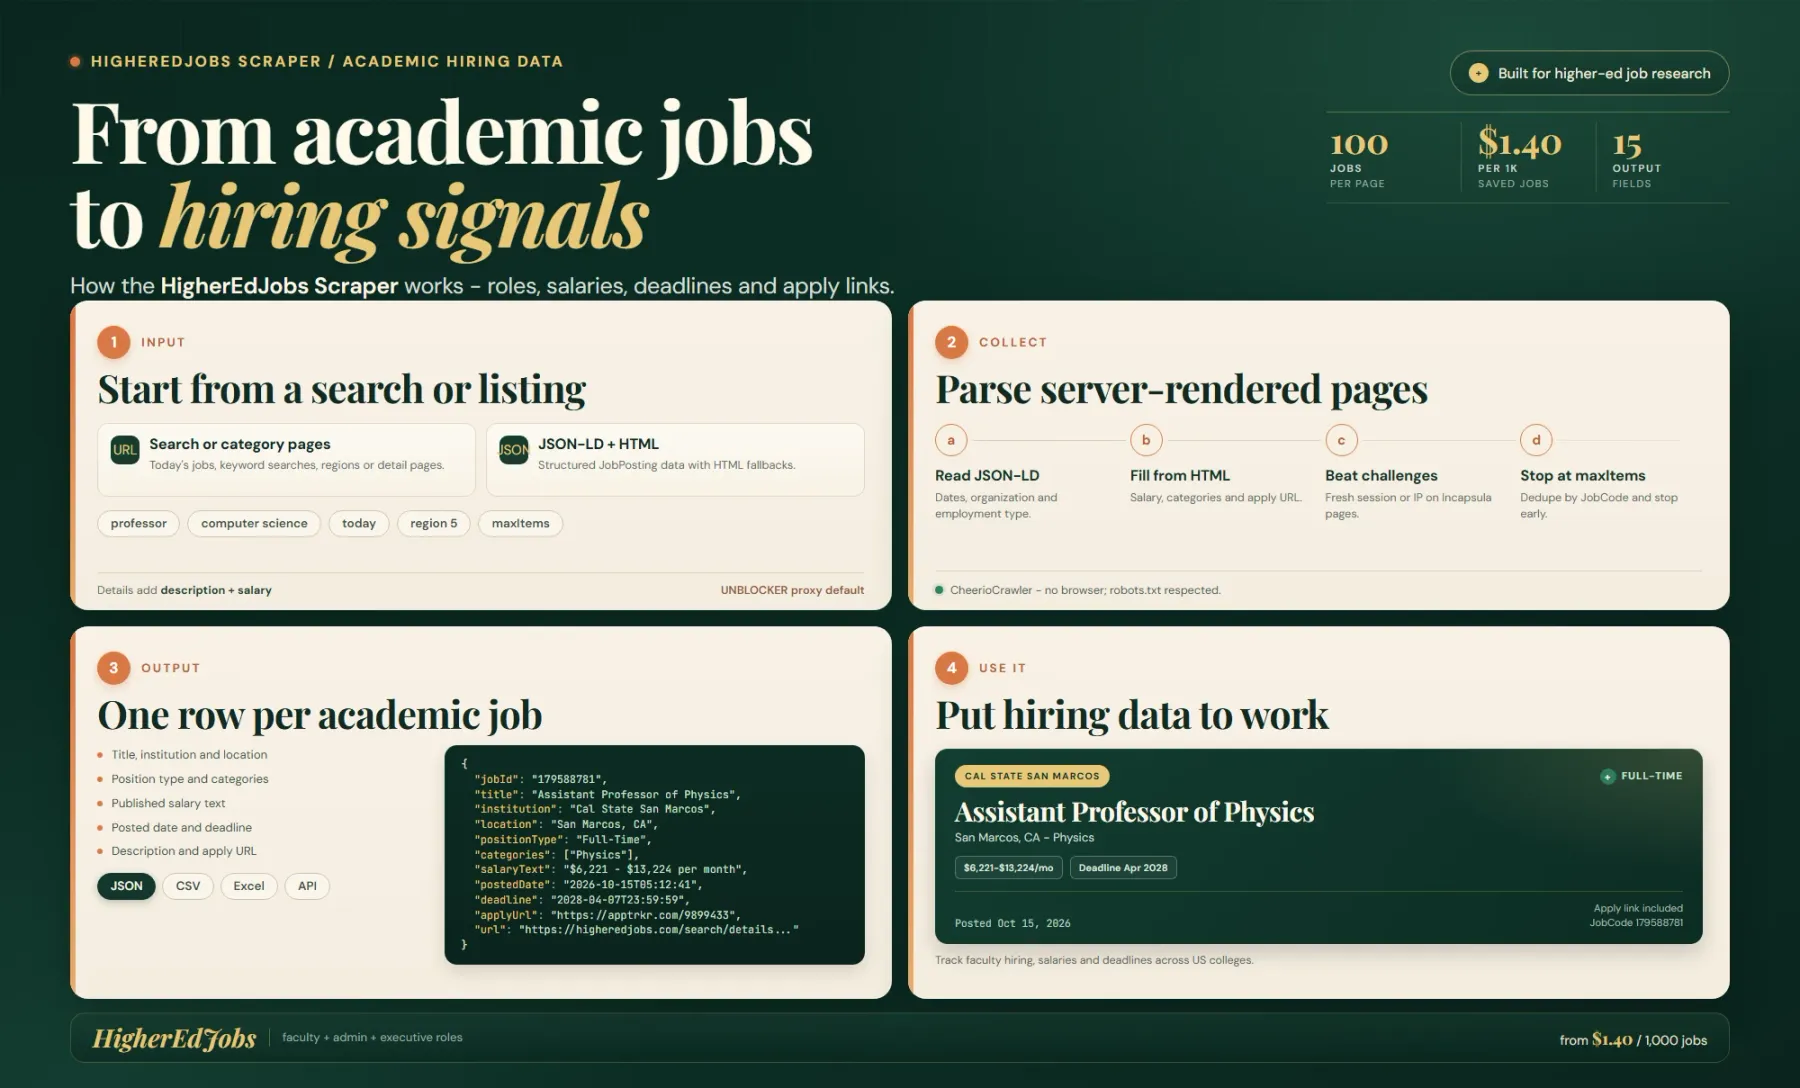
The Actor parses the JSON-LD JobPosting block on each server-rendered page, then fills gaps from the HTML for salary, categories and application URLs. Incapsula challenges are detected and retried through fresh sessions or IPs.
Each row covers one job with its JobCode, title, institution, location, position type, categories, published salary text, posted date, deadline, description and apply link. Results are deduplicated by JobCode and stop exactly at maxItems.
HigherEdJobs is server-rendered, so a CheerioCrawler (plain HTTP + HTML parsing) is enough — no browser automation. Per page the Actor:
- Parses the embedded JSON-LD
JobPostingstructured data (dates, description, organization, employment type). - Falls back to the HTML markup for fields JSON-LD does not expose (salary, categories, apply URL) and for VIP-branded page layouts.
- Detects anti-bot challenge pages (Imperva Incapsula challenges datacenter IPs) and retries them with a fresh session or IP instead of saving empty data — the default proxy group is UNBLOCKER, which solves those challenges.
- Deduplicates job detail pages by JobCode, follows pagination with
NumJobs=100enforced, and counts saved results internally somaxItemsis honored exactly — the crawl stops early instead of wasting requests.robots.txtis respected.
Input Parameters
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
startUrls | array | No | Today's jobs, 100/page | Search results, category/region listings, or individual detail pages. |
maxItems | integer | No | 10 | Max saved job results; the crawl stops as soon as it is reached. |
maxRequestsPerCrawl | integer | No | 200 | Page budget; each job detail costs one request. |
includeDetails | boolean | No | true | Visit each job's detail page for description, apply URL, deadline and salary. false = fast listing-only crawl (billed per detail saved). |
maxConcurrency | integer | No | 25 | Pages downloaded in parallel. Applied from the first request, so detail pages are fetched in parallel right away (10–50 recommended). |
proxy | object | No | Apify Proxy, UNBLOCKER group | The site challenges datacenter IPs; UNBLOCKER solves it, RESIDENTIAL works as an alternative. |
Example start URLs:
Output Fields
One object per job (15 fields):
| Field | Description |
|---|---|
jobId | HigherEdJobs JobCode identifier |
title | Job title |
institution, institutionUrl | Hiring institution and its website |
location, city, state | Job location |
positionType | Full-Time, Part-Time, Contract, … |
categories | Job categories (e.g. Physics, Computer Science) |
salaryText | Salary as published, when provided |
postedDate | Posting date (ISO from JSON-LD when available) |
deadline | Application deadline (validThrough), when published |
description | Full job description as plain text (detail mode) |
applyUrl | Direct application link to the employer's site |
url | HigherEdJobs detail page |
Example Input
Example Output
Automate Academic Job Monitoring With Schedules & Webhooks
- Schedule daily runs on Today's Jobs or per-discipline searches to keep a rolling academic job-market dataset.
- Webhooks fire on run completion — push new postings into Slack, Sheets, a data warehouse or your own board.
- API / MCP — start runs and download datasets from any pipeline or AI agent.
- Listing-only mode (
includeDetails: false) gives a cheap daily inventory of titles, institutions, locations and salaries; turn details on for full records. - Cost control — free accounts get a capped preview; paid accounts are billed
$1.40per 1,000 saved jobs plus$2.00per 1,000 detail fetches.
Related Actors
Verified related actors on Apify that pair well with this one. All links point to real, publicly available actors.
- Greenhouse, Lever & Ashby Job Scraper API | $1.50/1K
- Greenhouse, Lever & Ashby Jobs Scraper — with Salaries
- Greenhouse, Lever & Ashby Jobs Scraper — Salaries, No Login
- HigherEdJobs Scraper: Academic Jobs, Salaries, and Monitoring
- HigherEdJobs.com Scraper
Frequently Asked Questions
Does HigherEdJobs have an official API?
No public job-data API is published. HigherEdJobs serves server-rendered HTML search and detail pages (plus RSS feeds for categories, which open-source academic-job trackers use). Institutions post their ads through paid placement, not through a public developer API. This Actor reads the same public pages any visitor sees and returns them as structured JSON.
What are alternatives to HigherEdJobs for academic job data?
Comparable US higher-ed job boards: The Chronicle of Higher Education jobs (jobs.chronicle.com), Inside Higher Ed Careers (which offers employer-side posting automation but no public read API) and HERC (hercjobs.org, 550+ member institutions). For employer-direct feeds, many universities also publish through Greenhouse or Lever, whose public APIs (and the scrapers in Related Actors) cover them. Most serious academic-job trackers aggregate several boards at once.
Is salary data included?
Wherever an institution publishes a salary, the Actor captures the exact published text in salaryText (e.g. $6,221 - $13,224 per month). Many academic postings do not disclose salary — those rows carry an empty value rather than an estimate.
Can I monitor only new or changed postings?
This Actor returns the current state of each run's scope. For change-only feeds (NEW / UPDATED / EXPIRED events between scheduled runs), pair it with the monitoring-enabled HigherEdJobs actor linked in Related Actors, or diff consecutive datasets yourself — jobId is stable across runs.
How much does a run cost?
Pay per event: $1.40 per 1,000 saved jobs plus $2.00 per 1,000 detail-page fetches when includeDetails is on. 100 jobs with details cost 100 × ($0.0014 + $0.002) = $0.34. includeDetails: false drops the detail charge entirely for listing-only snapshots.
Can an AI agent call this Actor?
Yes — JSON input through the Apify API and MCP server. See For AI Agents & LLM Apps for the minimal call, output fields and billing rules.
Why does the default proxy use the UNBLOCKER group?
HigherEdJobs runs Imperva Incapsula, which challenges datacenter IP addresses immediately. The default proxy input is Apify Proxy with the UNBLOCKER group, which solves those challenges automatically; RESIDENTIAL is a working alternative. Set useApifyProxy: false only for small crawls from a residential IP.
For AI Agents & LLM Apps
Returns structured academic job postings from HigherEdJobs.com: institution, location, position type, categories, published salary, deadlines, description and apply link.
Minimal input (today's jobs, 100 saved):
Keyword search with details:
Output fields: jobId, title, institution, institutionUrl, location, city, state, positionType, categories, salaryText, postedDate, deadline, description, applyUrl, url.
Behaviors an agent should know:
- Omitted
startUrlsdefaults to Today's jobs at 100 per page. includeDetails: true(default) adds one billedjob-detailevent ($2/1K) per saved job;falsereturns listing-only fields (nodescription,applyUrlordeadline).maxItemsis enforced exactly via an internal counter — the run stops early once reached.- Results are deduplicated by
jobId(JobCode) even when multiple search pages link to the same job. - Pagination links are rewritten with
NumJobs=100so each listing page yields up to 100 jobs. - Leave
proxyat its default (UNBLOCKER) unless you have residential IPs; the site challenges datacenter addresses.
Billing: pay per event — $0.0014 per saved job (apify-default-dataset-item) plus $0.002 per detail page fetched (job-detail).
Legal & Compliance Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by or sponsored by HigherEdJobs, Inc. or higheredjobs.com. It accesses only publicly available search and detail pages — no login, no authenticated areas; anti-bot challenge pages are retried through Apify's standard proxy products rather than by breaking into protected areas, and the Actor respects robots.txt. Job data returned (institutions, titles, locations, published salaries, descriptions) is what each institution already publishes to every visitor; where personal contact data appears inside descriptions, handle it under GDPR/CCPA rules. You are responsible for your own compliance with HigherEdJobs' Terms of Service and applicable data-protection law; do not use contact data from the output for unsolicited commercial outreach in violation of applicable law such as CAN-SPAM, GDPR or TCPA.
SEO Keywords
higheredjobs scraper, higheredjobs api, higheredjobs data, academic job listings, higher education jobs data, faculty job postings, university job board data, higher ed job market, academic job market data, college job listings, faculty salary data, higher education hiring, scrape academic jobs, academic positions database, inside higher ed jobs, chronicle higher education jobs, herc jobs data, job data universities


