
Substack Archive Scraper | Public Posts & Clean Text
Pricing
from $0.75 / 1,000 substack posts
Substack Archive Scraper | Public Posts & Clean Text
Export public Substack newsletter archives and post URLs with dates, authors, engagement and optional public text. Custom domains, filters, deduplication and continuation. Paid posts return metadata and short preview only.
Pricing
from $0.75 / 1,000 substack posts
Rating
0.0
(0)
Developer
Apivault Labs
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 hours ago
Last modified
Categories
Share
Substack Archive Scraper — Public Posts & Clean Text
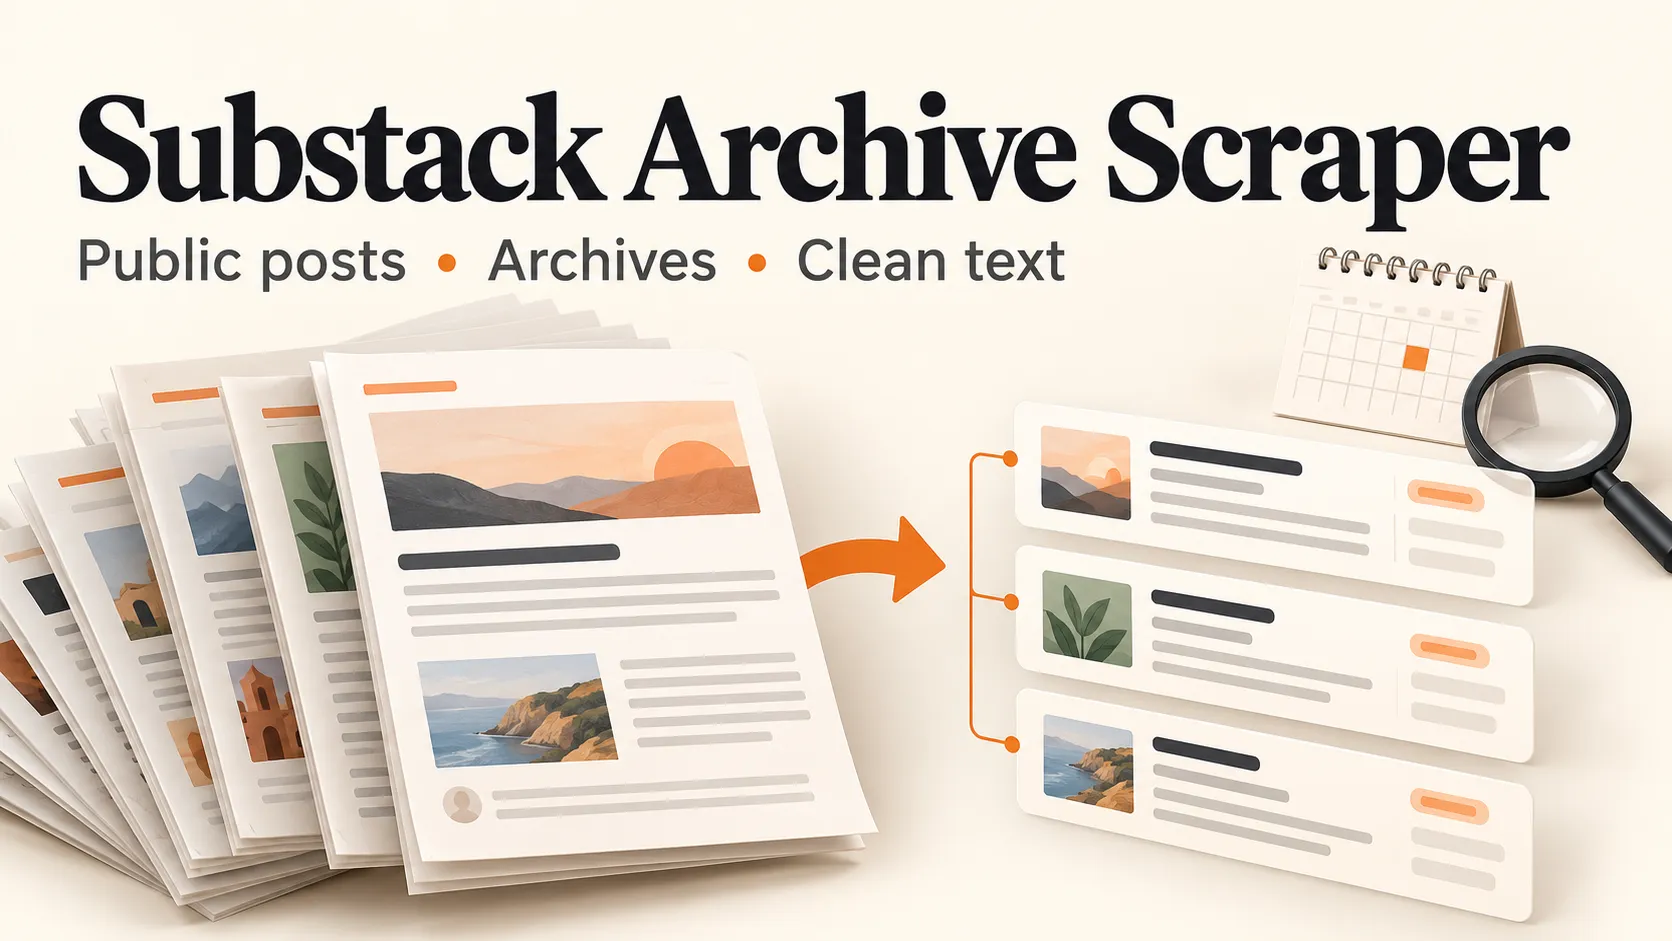
Turn public newsletter archives into structured post data for content research, publication audits and editorial monitoring. Supply Substack publication URLs, custom domains or specific post URLs. Export titles, source dates, author names, available engagement and optional public HTML/clean text to CSV, Excel or JSON.
This is an independent tool. It does not log in, access subscriber accounts or unlock paid articles. A restricted post returns metadata and a short source preview only. Keyword discovery, comments, subscriber counts, audio downloads and immutable archive snapshots are outside this version.
First export: five articles
Defaults request up to five metadata rows, at most 20 archive pages. The limit is global across inputs. Real output depends on matching posts, source availability, your spending cap and run resources. Some publishers or regions can return403/429; an empty Dataset alone does not prove an empty archive.
What it does
| Goal | Supported result |
|---|---|
| Audit a newsletter archive | Post IDs, canonical URLs, titles, source publication dates and audience flags. |
| Export a reading corpus | Public/free bodyHtml and bodyText if returned by the anonymous source. |
| Track a publication window | Inclusive start/end date filters plus available author/engagement fields. |
| Compare several newsletters | Up to20inputs, one global result limit and cross-input identity deduplication. |
| Resume a capped collection | CONTINUATION.resumeInput keeps source offsets and previously accepted IDs. |
Input settings
| Setting | Default / limit | Meaning |
|---|---|---|
| urls | One sample publication;1–20 | Public HTTPS homepage, /archive, or /p/post-slug. |
| maxItems | 5; maximum10000 | Maximum useful post rows across all inputs. |
| includeContent | false | Return public body HTML/text when present; never paid-body content. |
| onlyFree | false | Skip restricted audience/unlock-required posts. |
| startDate / endDate | omitted | Inclusive source post_date filters, YYYY-MM-DD. |
| maxPages | 20; maximum5000 | Global cap on archive/post input pages; up to20posts per archive page. Requested public content can add one detail request per accepted free post. |
| cursor | omitted | Copy from continuation only. Keep URLs/content/date/free settings unchanged. |
Five ready-to-copy scenarios
Public text corpus
Several publications with one limit
Publication date window
Specific article URL
Metadata from a custom domain
Five corresponding saved Tasks are prepared for verification. Public one-click Task availability must be checked separately; private Tasks are not published templates.
Output fields
| Field group | What it means |
|---|---|
| postId, publicationId, url | Source identity; publicationId/postId deduplicate overlapping inputs. |
| title, subtitle, authors, tags | Source editorial metadata; optional values can be absent. |
| publishedAt, updatedAt | Source timestamps; updatedAt is unknown when not supplied. |
| isPaid, audience, contentStatus | Access classification; paid_preview_only never contains bodyHtml/bodyText. |
| previewText | Short available preview, capped at1000characters. |
| bodyHtml, bodyText | Only requested public/free body, without an assertion that it is the complete copyrighted article. |
| reactionCount, commentCount, restackCount | Available source counters, not extracted comments. Missing values remain unknown. |
| sourceUrl, scrapedAt | Actual anonymous endpoint and observation time. |
No sample customer data or fabricated article output is inserted into the Dataset. wordCount is the source's article count when provided; it can exceed the available public text length. contentStatus distinguishes not_requested, public_body_returned, public_body_unavailable and paid_preview_only.
Larger archives and continuation
Use asynchronous runs for larger exports. Increase maxItems and maxPages within the schema; allow enough time and memory. This is a finite, bounded exporter, not a promise of unlimited archive depth or a500Kexport. Public content can require an additional identity-checked detail request per accepted free post. The first source version reads pages sequentially and writes accepted rows as they are processed.
When capped by items/pages/budget, read CONTINUATION.resumeInput in the run's Key-Value Store and submit that object as the next Actor input. Previously accepted IDs in the cursor prevent repeated billing across an unchanged continuation chain up to its100000IDwindow. Source updates can move offsets: this is not an immutable snapshot and cannot guarantee no omissions during concurrent index changes. Also deduplicate at your destination. Independent runs begin a new collection.
Check SUMMARY.isComplete and ERRORS. COMPLETE means the requested source list was exhausted without recorded source errors, not that every historical Substack post exists in the source. ITEM_LIMIT_REACHED, PAGE_LIMIT_REACHED and CHARGE_LIMIT_REACHED retain continuation. A source failure preserves its current offset; mixed results can be useful but incomplete. A complete source outage fails the run with no fabricated paid rows.
Pricing and run resources
Candidate result tariff: $1.00 per1,000 post rows on Free; $0.75 per1,000 on all paid tiers. Metadata and requested public body use the same post event; there is no extra body event. Actor Start is $0.00005 per GB of memory, minimum one; platform resources are additional and paid by the user. Read the Pricing tab for effective account rates.
Useful post rows are the only lead/result event. Source errors, duplicates, filtered-out posts and diagnostics are not billed as posts. Actor platform resources can still apply on empty or failed runs. An available paid-post metadata row is still a useful result and can be billed; it is not a full paid article. Downloading an existing Dataset in another format does not start a new export.
Start with512MB and900seconds for a small export. A source response is limited to8MB, individual requests to25seconds and redirects are checked for public HTTPS destinations. The source may block this service or return incomplete text. No external API key, proxy subscription or publisher login is required by this version; reliability and constant speed are not guaranteed.
API, MCP and integrations
Actor slug: apivault_labs/substack-archive-scraper. Start an asynchronous Actor run, wait for a terminal status, read the default Dataset and its diagnostics, and download Dataset items. Keep your Apify token in secure client credentials.
Official Python client, JavaScript client and Apify MCP can call this exact slug with its input. They are generic clients, not dedicated packages for this product. No matching dedicated npm/PyPI package is currently verified. n8n/Make can use HTTP integration; execution and n8n verification are not claimed.
FAQ
Does it bypass a paywall? No. Restricted/unlock-required posts are metadata plus a short preview only; body fields are omitted even if an anonymous endpoint happens to supply them.
Can I search all Substack by keyword? Not in this version. Supply known publications or post URLs. A keyword option must not silently substitute an unrelated source.
Does it support custom domains? It queries the public Substack archive/post shape at the supplied domain and follows safe redirects. A custom domain that no longer uses Substack is reported as an error, not scraped as an unrelated website.
Why are there fewer rows than maxItems? Date/free filters, overlap, source exhaustion, request/page limits and spending cap can all reduce the result. Inspect the summary and continuation.
Are missing counters zero? No. Unknown source fields are null, not guessed zeros. Comments themselves and subscriber counts are not collected.
Is this a monitoring snapshot? No. Continuation is offset-based with identity deduplication. Store your own observations by source identity to compare runs; editing/deletion history is not reconstructed.


