
Journalist Requests Scraper - #journorequest Media Requests
Pricing
from $1.70 / 1,000 requests
Journalist Requests Scraper - #journorequest Media Requests
Open journalist requests for expert sources from Bluesky and Mastodon, plus optional UK and US calls for evidence, with deadlines, sections and your topics matched.
Pricing
from $1.70 / 1,000 requests
Rating
0.0
(0)
Developer
Dami's Studio
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
Find open journalist requests for expert sources (#journorequest): run it and you get every open request posted on Bluesky in the last 30 days, each with its deadline when the post states one, a section, who is asking, and your topics matched and ranked first. Switch on the UK Parliament, GOV.UK and US Federal Register lists and you also get open calls for expert evidence, with their real closing dates.
The honest part first: journalists post only a handful of requests a day under these tags. Across all of Bluesky we counted 6 in one full day of posts (27 Oct 2026), and most came from services that relay requests and link to their own site. A run gives you days or weeks of requests, not hundreds a day.
| Input | Nothing required. Optionally your topics, sections, countries and sources |
| Output | One row per open request: title, full text, link, deadline, days left, section, who is asking, your matched topics |
| Ceiling | 2,000 requests per run |
| Speed | 1 to 3 seconds a run in our tests, every source together included |
| Account needed | None from you |
| Price | $1.70 per 1,000 requests, flat on every plan. The free plan's $5 a month covers about 2,900 |
| Using an AI agent? | |
|---|---|
| Actor | dami_studio/journalist-requests-scraper |
| Set one field | keywords, labelled "Your topics" in the Console |
| Cap the bill | maxTotalChargeUsd on the run, for example 0.10: it never charges past that |
| MCP, one link | https://mcp.apify.com/?tools=fetch-actor-details,dami_studio/journalist-requests-scraper |
| How often | Daily, with onlyNewRequests on, so each morning brings only requests you have not seen |
🔍 What Journalist Requests Scraper does
It reads the public #journorequest and #prrequest posts on Bluesky, keeps the ones from the last 30 days, and turns
each into a row you can sort and filter. A post's own words decide its section, the deadline (only when the post names
one, such as "Deadline 28 Oct, 17:00" or "by Friday") and who is asking. Requests that mention one of your topics are
tagged in matchedKeywords and come first, then the rest by soonest deadline.
Mastodon is there too, but its request tags have been quiet since September 2026, so it is off unless you tick it.
The three government sources are a different kind of request. UK Parliament committees asking for written evidence, GOV.UK consultations and US Federal Register requests for information all want expert input by a fixed date. They are not journalists, so they are off by default, but a published response with your name on it is the kind of thing some people answer journalist requests to get.
Each post is fetched fresh on every run, so a request its author has deleted is gone from your results too.
📋 What data you get from each journalist request
| What you want | Field |
|---|---|
| The request | title, summary (the full text) |
| Where to answer it | url |
| Deadline | deadline (UTC), deadlineText (as written), daysLeft, isOpen |
| Who is asking | requesterName, requesterType, outlet (only when named plainly) |
| Topic | industry (one of twelve sections), matchedKeywords |
| Where it came from | source, authorHandle, authorUrl, datePosted, language, country |
| For scheduled runs | isNew |
| Licence line on government rows | attribution |
▶️ How to scrape journalist requests
- Open the actor and press Try for free.
- Type the subjects you can speak on into Your topics, for example
pensionsorcybersecurity. - Leave Where to look on Bluesky, or tick the government lists as well.
- Press Start. Open the Output tab and the Requests view.
- To get a fresh list every morning, schedule it daily with Only new requests switched on.
💰 How much does it cost to scrape journalist requests?
$1.70 per 1,000 requests, the same on the Free, Starter, Scale and Business plans, plus $0.00005 when a run starts. The free plan's $5 a month covers about 2,900 requests. Requests left out by your filters are not charged, and neither are the note rows that say a source did not answer or nothing matched.
📥 What you give it
| Field | What it does | Default |
|---|---|---|
keywords | Your topics. Matches are tagged and listed first. A single word also matches plain endings: finance finds "financial" | none |
keywordsOnly | Leave out requests that match none of your topics | false |
excludeKeywords | Leave out requests that mention any of these | none |
onlyOpenDeadlines | Hide requests past their deadline. A post with no stated deadline counts as open for 30 days | true |
maxAgeDays | Only requests posted in the last this many days | no limit |
maxRequests | Stop after this many | 200 |
sources | bluesky, mastodon, uk_parliament, gov_uk, us_federal_register | ["bluesky"] |
industries | Keep only these sections | all |
countries | Keep only requests about these countries | all |
onlyNewRequests | Only requests not returned to you before | false |
📤 What you get back
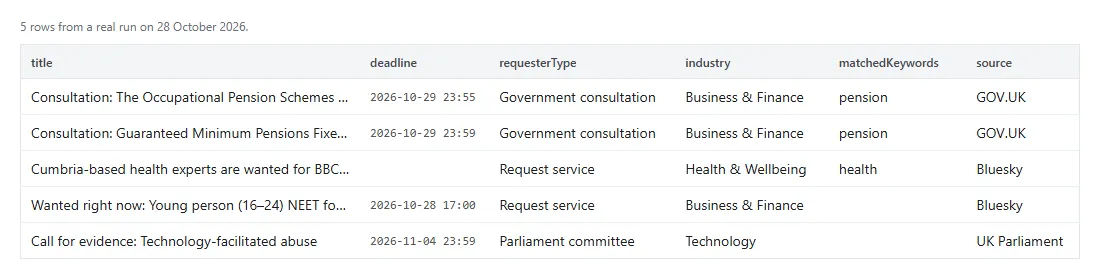
One full row from a run on 28 Oct 2026. A Bluesky row has the same fields, with authorHandle and authorUrl filled
and attribution empty.
| Field | Read it like this |
|---|---|
deadline | UTC. On a post it is the day the post names, end of day when no time is given. A time in the post is taken as written, since posts rarely say which time zone |
daysLeft | Whole days to the deadline; 0 means it closes today. Empty when no deadline is stated |
summary | E-mail addresses and phone numbers in a post are replaced with "[e-mail in the original post]". The link takes you to the post itself |
requesterType | Journalist, Podcaster, Blogger, Author, PR Pro, or Request service for accounts that relay requests and link to their own site. Read from the post and the poster's profile |
outlet | Filled only when the post names the publication plainly, such as "for Newsweek features". Often empty |
isNew | Whether this request was returned to your account before |
🧾 Reading the output
A real request row has no _diagnostic field. A note row has _diagnostic: true, costs nothing, and carries a
status:
status | Meaning |
|---|---|
NO_RESULTS | Nothing was found, or your filters left everything out. leftOut counts the reasons |
NOT_SERVED | One source did not answer this run. The others still came back |
TIME_LIMIT | The run's time limit came first; sourcesNotFinished names what was left |
COST_LIMIT | The maximum cost you set for the run was reached |
BAD_INPUT | No source was picked |
To keep only requests, filter out rows where _diagnostic is true.
💡 What people use it for
- An expert or a founder who wants to be quoted: put your subjects in
keywords, schedule it daily withonlyNewRequests, and read the morning's list over coffee. - A PR team answering requests for several clients: one task per client, each with its own
keywords, sent to a sheet. - A consultancy that answers government consultations: tick
gov_ukanduk_parliament, filter byindustries, and sort bydeadline.
A recipe that chains three of our actors: run this one on your subjects, open the url of each matched request, then
run Google News Scraper on the same subject to see what that
outlet and others have already published before you pitch.
🚧 What it does not do
- It is not a high-volume feed. The public request tags carry a handful of posts a day, and most come from services that relay requests.
- No contact details. Addresses and numbers in a post are masked; you answer through the post or the link in it.
- No X (Twitter), LinkedIn, Facebook or Reddit requests, and no request boards that need an account.
- Sections and requester types are read from the words, so a mixed request can land in the wrong section.
- Most posts name no country, so the
countriesfilter leaves most posts out. - It is not an official Bluesky, Mastodon, UK Parliament, GOV.UK or Federal Register tool. Dami's Studio is independent and is not affiliated with or endorsed by Bluesky, Mastodon, UK Parliament, GOV.UK or the Federal Register, or by any other company named on this page.
🧭 Which scraper do you need?
| If you want | Use |
|---|---|
| Open journalist requests and calls for evidence | This one |
| Any keyword on Bluesky, or a person's posts | Bluesky Scraper |
| Hashtags and accounts on Mastodon | Mastodon Scraper |
| What the press has already written on a subject | Google News Scraper |
| Newsletter posts from a Substack publication | Substack Scraper |
❓ Questions people ask
Do I need a Bluesky account to get journalist requests?
No. You don't need a Bluesky or Mastodon account. It reads public posts the way a signed-out visitor sees them.
Why is a request I saw on Bluesky not in my results?
Either it was posted without one of the request tags, its deadline has passed (or it is over 30 days old with none
stated), or your filters left it out. The NO_RESULTS note row counts what each filter removed.
How do I get only new requests each day?
Schedule a daily run with Only new requests on. The ids it returned are kept in a store named
journalist-requests-seen in your own account; delete that store to start over.
Can I call it from code or connect it to an AI assistant?
The API tab has code for Python, JavaScript and
the CLI. MCP clients like Claude and ChatGPT use
https://mcp.apify.com/?tools=fetch-actor-details,dami_studio/journalist-requests-scraper. Both bill your Apify
account at the same price.
Is scraping journalist requests legal?
The posts are public and read without an account, and nothing private is collected. They still carry personal data, such as the poster's name and handle, so GDPR and similar laws apply to what you keep, and the rules on unsolicited contact apply to how you reply. Each site's own terms apply to what you do with the rows. Apify's write-up on the legality of web scraping is a good start, and we are not lawyers.
🆘 If something breaks
Open the Issues tab on the actor page. Send the input you used and the run ID, and the status of any note row.


