Crunchbase Companies Scraper
Pricing
from $0.67 / 1,000 results
Crunchbase Companies Scraper
Crunchbase Companies Scraper looks up company profiles in bulk by Crunchbase URL or ID, company name or website domain: description, website, HQ, founded date, industries, founders, employees, social links, ticker and US funding totals. Export JSON, CSV or Excel, or use the API.
Pricing
from $0.67 / 1,000 results
Rating
0.0
(0)
Developer

Fast Data API
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
7 days ago
Last modified
Categories
Features
Share
Crunchbase Companies Scraper — Company Profiles, Founders and US Funding by Crunchbase ID
Crunchbase Companies Scraper returns one company profile per Crunchbase company URL, company ID, company name or website domain: name, legal name, description, website, founded date, headquarters, country, employees, industries, founders, key people and directors, social links, stock ticker, and for US companies the total funding, funding rounds with dates, amounts and investor counts. Profiles are built from public company data and keyed by the Crunchbase company ID, so every row links back to its Crunchbase page. It needs no account, no cookies and no browser. Coverage is best for well-known and funded companies; an input with no public data gets a plain "not found" row that is not charged.
What data can I extract with Crunchbase Companies Scraper?
| 🏢 Company name and legal name | 🔗 Crunchbase page and ID | 🌐 Website | 📝 Description and short description |
|---|---|---|---|
| 📅 Founded date | 📍 Headquarters and country | 👥 Employees (with the year of the count) | 🏷️ Industries |
| 💰 Total funding in USD (US companies) | 📆 Last funding date | 🧾 Funding rounds: date, money raised, offering size, investor count | 🤝 Known investor names |
| 👤 Founders | 🧑💼 Key people and directors with roles | 📞 Phone and email when public | 🔗 X, LinkedIn, Facebook, Instagram and YouTube links |
| 📈 Stock ticker and public status | 🧩 Subsidiaries | 📦 Products | 🔎 The name or domain you searched |
Crunchbase-only signals (Crunchbase rank, heat and growth scores, web traffic, tech stack, patents, news, similar companies, logo, round labels such as "Series B") have no public source. Their columns stay in the output, empty, so existing pipelines keep working; values are never guessed.
How to use Crunchbase Companies Scraper
Sales teams, investors and analysts paste a list of Crunchbase links, company names or domains and get one clean profile row per company.
Copy to your AI assistant:
Crunchbase Companies Scraper MCP Server: use it from ChatGPT, Claude or Cursor
Point your AI assistant at this actor and it can look up company profiles on its own.
Step by step
- Open Crunchbase Companies Scraper and click Try for free.
- Paste Crunchbase company URLs or IDs (
https://www.crunchbase.com/organization/stripe,notion-so) into the first field, and/or company names or domains (Klarna,openai.com) into the second. - Set Max companies (default 20).
- Click Start. Rows appear in the Output tab while the run is going.
- Download as JSON, CSV or Excel, or read the dataset through the API.
How to scale Crunchbase Companies Scraper to bulk
Put hundreds of URLs, IDs, names or domains in one run and set Max companies to 0 (no limit). Inputs are looked up in batches, so a long list is much faster per company than a short one; in our local tests 50 well-known companies took 45 to 60 seconds in total (about 1 second per company). Duplicates are looked up once.
✨ Features
- Four ways in: Crunchbase company URL, bare Crunchbase ID, company name, or website domain.
- One row per company, pushed as soon as it is ready.
- Funding for US companies: total funding, number of rounds, last funding date, and per round the date, money raised, offering size and investor count.
- People: founders, CEO and chair, plus officers and directors with their roles.
- Honest output: a value with no public source stays
null; an input with no data gets anot_foundrow that is never charged. - No account, cookies, browser or proxy needed; if a request is blocked the actor switches to a proxy by itself.
- Four output views: Overview, Funding, People & contacts, Market & products.
Use cases 💡
- CRM enrichment: turn a list of company domains into profiles with founders, HQ, industry and social links.
- Deal sourcing: see how much a US startup has raised, how many rounds and when the last one closed.
- Investor research: list the founders, directors and known investors of a set of companies.
- Data cleaning: map company names or domains to their Crunchbase IDs and pages.
- AI agents and RAG: feed clean, structured company descriptions to an LLM.
Why choose this actor?
- Every row comes from public company data, with no login and no scraping of private pages.
- It accepts names and domains, not only Crunchbase links.
- Funding rows give real dollar amounts and dates for US companies (Stripe: 13 rounds and their totals in one row).
- Not-found inputs are free and clearly marked, so you only pay for companies that were found.
⬇️ Input
| Field | Type | Description |
|---|---|---|
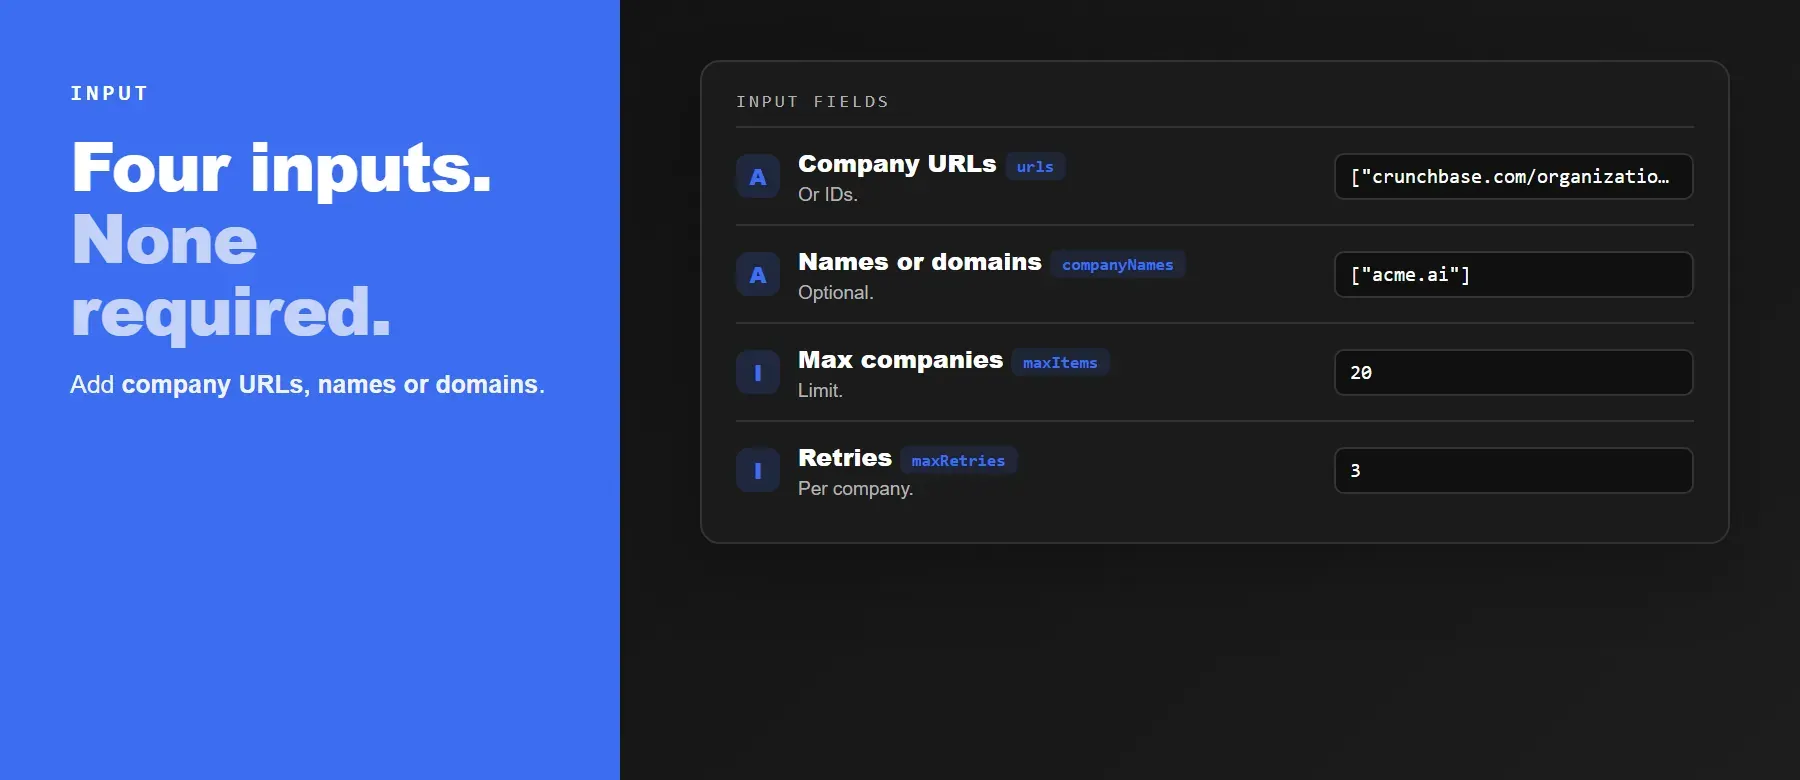
🔗 Crunchbase company URLs or IDs (urls) | array | https://www.crunchbase.com/organization/stripe or stripe. One row each. List / discover URLs are not supported. |
🔎 Company names or website domains (companyNames) | array | Klarna or openai.com. A name is matched to the company with that exact name (else the closest match); a domain to the company with that official website. |
🔢 Max companies (maxItems) | integer | Total companies for the whole run. 0 = no limit. Default 20. Not-found rows do not count. |
🔁 Max retries (maxRetries) | integer | Advanced. Tries per failed or busy request, 1 to 10. Default 3. Proxy switches do not count. |
🌐 Proxy configuration (proxyConfiguration) | object | Optional. By default the actor connects directly and switches to a proxy by itself when a request is blocked. |
Free plan limits
Free plan: up to 20 companies per run (all inputs together) and 200 per month; paid plans have no limit. The run log and status message say when the limit applies.
Example input
⬆️ Output
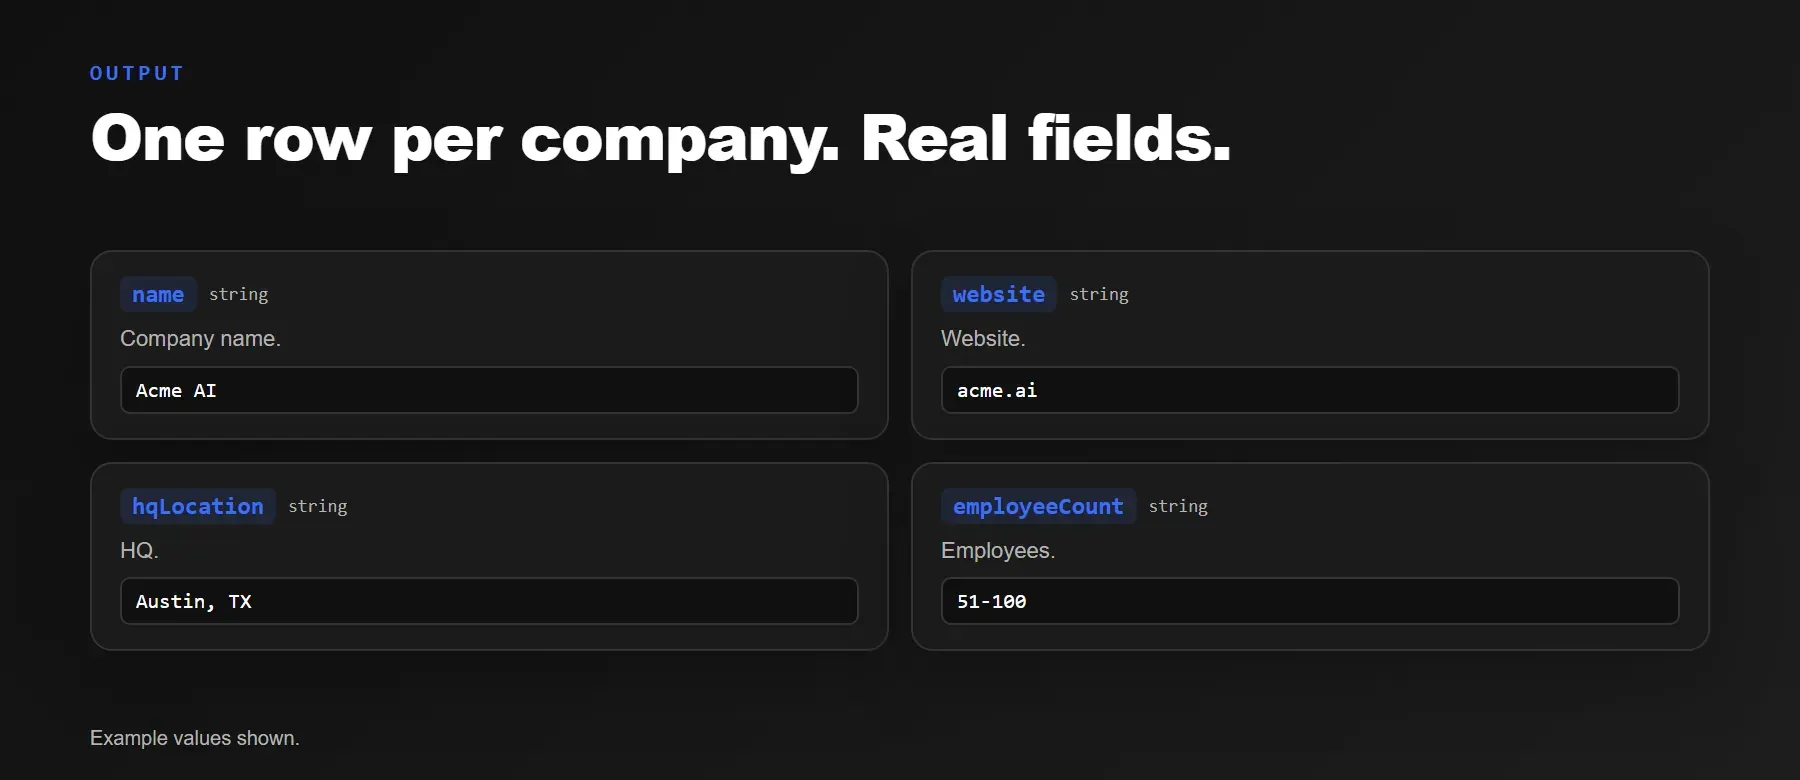
One row per company. Found companies have result_type: "company"; inputs with no public data have result_type: "not_found", the input, and an error text, and are not charged.
Example output
A not-found row:
totalFundingUsd is the sum of moneyRaisedUsd over the rounds listed; amounts can include share sales such as employee tender offers.
How does it work?
The actor reads public company data, matches each input to a company by its Crunchbase ID, exact name or official website, and writes one row per company. It looks up inputs in batches, retries a busy source, and switches to a proxy by itself when a request is blocked.
How do you integrate Crunchbase Companies Scraper into your stack?
Using Crunchbase Companies Scraper with the Apify API
MCP integration for AI agents
Add https://mcp.apify.com?tools=fastdataapi/crunchbase-companies-scraper to any MCP client (Claude, ChatGPT, Cursor).
No-code tools (n8n, Make, LangChain)
Use the Apify integration in n8n, Make, Zapier or LangChain with the actor ID fastdataapi/crunchbase-companies-scraper.
Is it legal to use this data?
The actor does not log in anywhere and does not copy Crunchbase pages; it builds profiles from public company data and uses the Crunchbase company ID only as a key. Personal data (names of founders and officers) can still fall under laws such as GDPR, so use it for a legitimate purpose and check with your lawyer if unsure.
Frequently asked questions
What fields does Crunchbase Companies Scraper return?
Name, legal name, description, website, founded date, headquarters, country, employees, industries, funding totals and rounds (US), investors, founders, key people, contacts, social links, ticker, subsidiaries, products and the Crunchbase page. See the example output above.
Why are some companies "not found"?
Public company data covers well-known and funded companies best. Small, very new or private companies with little public footprint may have no profile; those rows are marked not_found and are free.
Why is funding empty for some companies?
Funding amounts and rounds are available for US companies with public funding records. Companies outside the US, or US companies without such records, keep these fields empty.
Does it need a Crunchbase account or login?
No. No account, cookies, API key or browser.
Can I look up many companies at once?
Yes. Put any number of URLs, IDs, names or domains in one run; set Max companies to 0 for no limit.
Does it work with Claude, ChatGPT and other AI agent tools?
Yes, through the Apify MCP server (see above) or the API. Rows are flat JSON that LLMs read directly.
Your feedback
Found a wrong match or a missing field? Open an issue on the actor's Issues tab and we will look at it.