
Redbubble Email Scraper
Pricing
from $1.99 / 1,000 results
Redbubble Email Scraper
Redbubble Email Scraper finds emails shown on public Redbubble artist shops and product pages from your keywords: email, page link, title and the public text it appeared in. Filter by location and email domain. No Redbubble account or login. Export as JSON, CSV or Excel, or use the API.
Pricing
from $1.99 / 1,000 results
Rating
0.0
(0)
Developer

Fast Data API
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Categories
Security
Limited permissionsShare
Redbubble Email Scraper — Emails, Page Titles and Links
Redbubble Email Scraper finds email addresses that public Redbubble artist shops and product pages show for your keywords. Each result returns the email, the Redbubble page link, the page title and the public text it appears in, filtered by the email domains you choose. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a lead-generation pipeline. No Redbubble account or login needed to run a search. Add more keywords to scrape Redbubble emails across more pages in one run.
What data can I extract with Redbubble Email Scraper?
Using this Redbubble email API, you will be able to extract the following Redbubble email data:
| 🌐 Network | 🔑 Keyword searched | 📝 Page title |
|---|---|---|
| 📰 Page description | 🔗 Page URL | 📧 Email address |
How to use Redbubble Email Scraper
Marketers, recruiters and lead-generation teams use this actor to find emails on Redbubble without opening every page by hand.
Copy to your AI assistant:
Redbubble Email Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Add the Apify MCP server and your AI assistant can call Redbubble Email Scraper directly from your prompts - no glue code, no scraping logic to write.
Works the same way in Claude Code, Cursor and Windsurf.
Step by step
- Create a free Apify account.
- Open Redbubble Email Scraper in the Apify Store.
- Enter one or more keywords, for example
artist,illustrationordesign. - Optionally add a location and the email domains you want (default
@gmail.com). - Click Start, then download your results as JSON, CSV or Excel.
How to scale Redbubble Email Scraper to bulk
keywords takes a list, so add every search term to run a bulk Redbubble email search in one call — up to 3 keywords are processed at the same time, each with its own maxEmails budget. To cover more ground over time, schedule the Actor with a rotating keyword list, or call it from the Apify API with a different keywords / location pair per run.
✨ Features
Redbubble Email Scraper is a Redbubble email finder and Redbubble email extractor: give it a keyword and it returns clean, structured matches from public Redbubble artist shops and product pages.
It extracts, per match:
- Email – the address shown on the page, lower case, matching your email domains.
- Page URL – the public Redbubble page the email was found on.
- Page title – the result's title as shown in the search listing.
- Description – the public text the email appears in (up to 500 characters).
- Keyword / network – the keyword that found the row and the platform (
redbubble.com).
⚡ Every address is checked before it is kept: shortened or cut-off addresses, prose such as "that @gmail.com" and placeholders such as "username@gmail.com" are rejected, and the same email is returned once per keyword.
Use cases 💡
- Sales rep — use this Redbubble lead generation tool to build an outreach list by keyword and city.
- Recruiter — run this Redbubble contact scraper to find emails behind niche artist shops.
- Agency — use this Redbubble email list builder to collect leads for a client's niche.
- Market researcher — map which artist shops and product pages publish a contact email for a topic.
- AI agent builder — feed matched emails straight into a CRM-enrichment or lead-scoring pipeline with no parsing step.
Why choose this actor?
- Real public emails, not guesses. A recorded local test run returned 3 emails for the keyword
artistin 126.7 seconds. - Six clean fields per match. Every row carries the keyword, the page title, the public text the email appeared in and the page link.
- Built-in retry. When a search attempt is blocked the actor retries it with a fresh connection and continues on a backup source, so a run still delivers results.
⬇️ Input
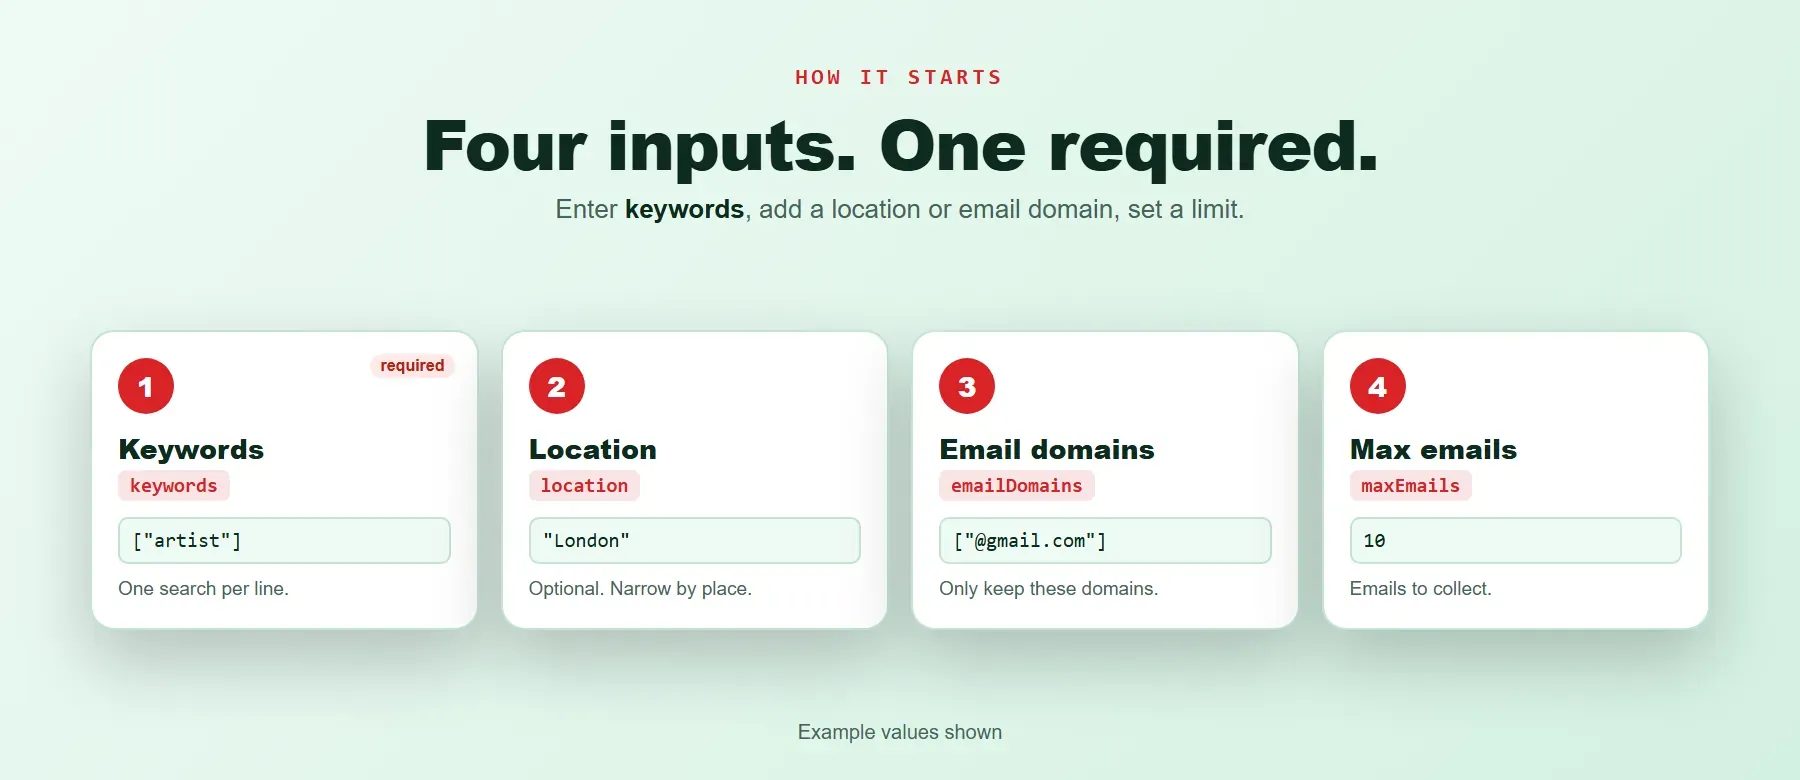
Enter one or more keywords (required); the rest is optional and has a working default.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
keywords | Yes | Array of strings | Keywords to search on public Redbubble artist shops and product pages. Each one gets its own maxEmails budget; duplicates are removed. | ["artist", "illustration"] |
location | No | String | City or region searched as an exact phrase. Empty = worldwide. | "London" |
emailDomains | No | Array of strings | Keep only emails of these domains (@ optional). Default ["@gmail.com"]; [] accepts any domain. | ["@gmail.com", "@outlook.com"] |
maxEmails | No | Integer | Emails to collect per keyword (1–100,000, default 10). Free-plan runs are capped at 20 per run in total (all keywords together) and 200 per month. | 50 |
engine | No | String (select) | Processing engine; legacy is the only value. | "legacy" |
proxyConfiguration | No | Object | Connection settings. Leave as it is and a suitable Apify proxy is selected automatically. | {"useApifyProxy": false} |
Free plan limits
Users on the Apify free plan can fetch up to 20 emails per run (all keywords together) and 200 emails per month. When the limit is reached, the run finishes successfully with a status message explaining the limit. Upgrade to any paid Apify plan to remove these limits.
Example input
⬆️ Output
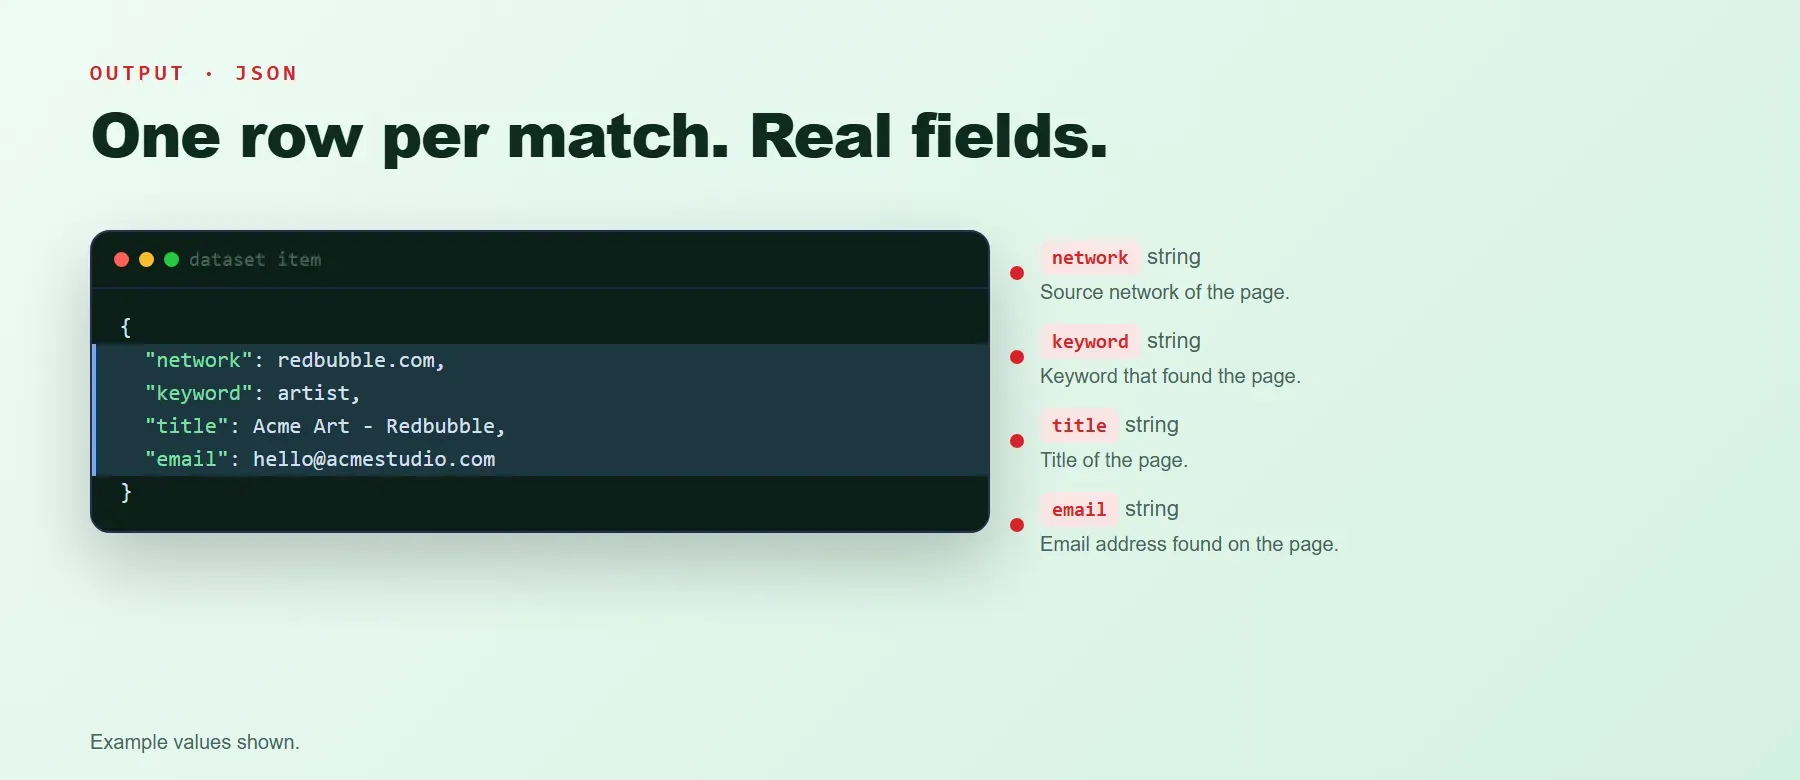
Every match is one JSON item with the same six fields on every run. Within a keyword the same email is returned once. Export Redbubble emails as JSON, CSV or Excel.
Example output
How does it work?
Redbubble Email Scraper doesn't log into Redbubble at all. For every keyword it searches public Redbubble artist shops and product pages that show an email address of your chosen domains (retrying with a fresh connection and continuing on a backup source when a search is blocked or runs dry). It only reads what any logged-out visitor can already see. The email is read from the page's public title and text, checked, lower-cased and returned with the page link.
How do you integrate Redbubble Email Scraper into your stack?
Call it from any language over the Apify REST API, or wire it into a no-code tool.
No-code tools (n8n, Make, LangChain)
In n8n, use the Apify node's Run an Actor action. In Make, use the Apify app's Run an Actor module followed by Get Dataset Items. In LangChain, install langchain-apify and call ApifyActorsTool() to let an agent run it as a tool.
Is it legal to scrape Redbubble data?
Scraping publicly available data is generally permitted; the legal risk sits mostly in how the data is stored and used afterward. Redbubble Email Scraper returns only data that any logged-out visitor already sees. If you operate in the EU, GDPR applies to storing and using emails you collect: keep records you can justify and delete them when asked. Anti-spam rules (such as CAN-SPAM) still apply to outreach — the Actor finds public emails, it does not grant permission to contact them. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Redbubble Email Scraper return?
The network, keyword, page title, description, page URL and email for every match. See the data fields section.
Does Redbubble Email Scraper require a Redbubble account or login?
No. Only public pages are read and no Redbubble credentials are ever requested.
Can I get emails of any domain, not only Gmail?
Yes. Set emailDomains to the domains you want (for example @outlook.com or your company domain), or to [] to accept any domain.
Can I search many keywords at once?
Yes. keywords takes a list; up to 3 keywords are processed at the same time, each with its own maxEmails budget.
Does Redbubble Email Scraper return data in a format LLMs can use directly?
Yes. Every result is typed JSON with consistent field names — pass it straight to an LLM, a vector store or an agent tool.
Can I use it with an AI agent through MCP?
Yes. Add the Apify MCP server (https://mcp.apify.com?tools=fastdataapi/redbubble-email-scraper) to your agent; it can then call this Actor directly.
What happens when Redbubble changes its layout or anti-bot system?
The actor reads general page text rather than one fixed selector, so most layout changes don't break it. When a bigger change happens the actor is updated and your calls keep returning the same JSON schema.
Do I need to manage proxies?
No. Proxy rotation and retries run on the Actor's side — plain HTTP requests, no browser to maintain.
Related scrapers
| Scraper | What it extracts |
|---|---|
| Gumroad Email Scraper | Emails from public Gumroad creator and product pages |
| Pinterest Email Scraper | Emails from public Pinterest pins and profiles |
| Walmart Email Scraper | Emails from public Walmart product and seller pages |
Your feedback
Found a bug or missing a field? Let us know through the Issues tab on this actor's Apify Store page.


