

Telegram Channel Messages
Pricing
from $0.18 / 1,000 post delivereds
Telegram Channel Messages
Pricing
from $0.18 / 1,000 post delivereds
Rating
0.0
(0)
Developer

FeedMiner
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
🔓 Nothing to connect. No Telegram login, no phone number, no bot token, no API key, no cookies to paste. Every read is a public t.me page Telegram serves to anyone, so there is nothing in the loop that can expire on you.
⚡ 9 704 posts from 10 channels in under three minutes. Measured on platform run 2kxvM6LRqgi4IRBmu, at the 256 MB this Actor asks for — 561 pages of history walked, eight channels at a time, nothing refused.
💬 Twenty-three columns, all read off one page. The reactions with their per-emoji counts and the paid and custom ones identified, the edited mark, the author's signature, the forward's origin, the message a post replies to, the photo and video links, the poll question on a post that has no text at all, and the unfurled link card — plus collected_at, so a view count you compare next week is comparable with something.
💸 You pay for delivered posts, and for nothing else. A channel that gives nothing — a dead handle, a bot, a group, a channel with no posts in your window — is named in the run's closing line with the reason why, and costs you nothing at all. Neither does a post the dataset refused.
| FeedMiner • Social data, measured before it is promised | ||
| Telegram Channel Messages You are here | Telegram Channel Enrichment One row per channel: size, cadence, reach, velocity | X Tweet Scraper Search, threads, lists, communities · $0.12/1K tweets |
Copy to your AI assistant
How to scrape Telegram channel posts
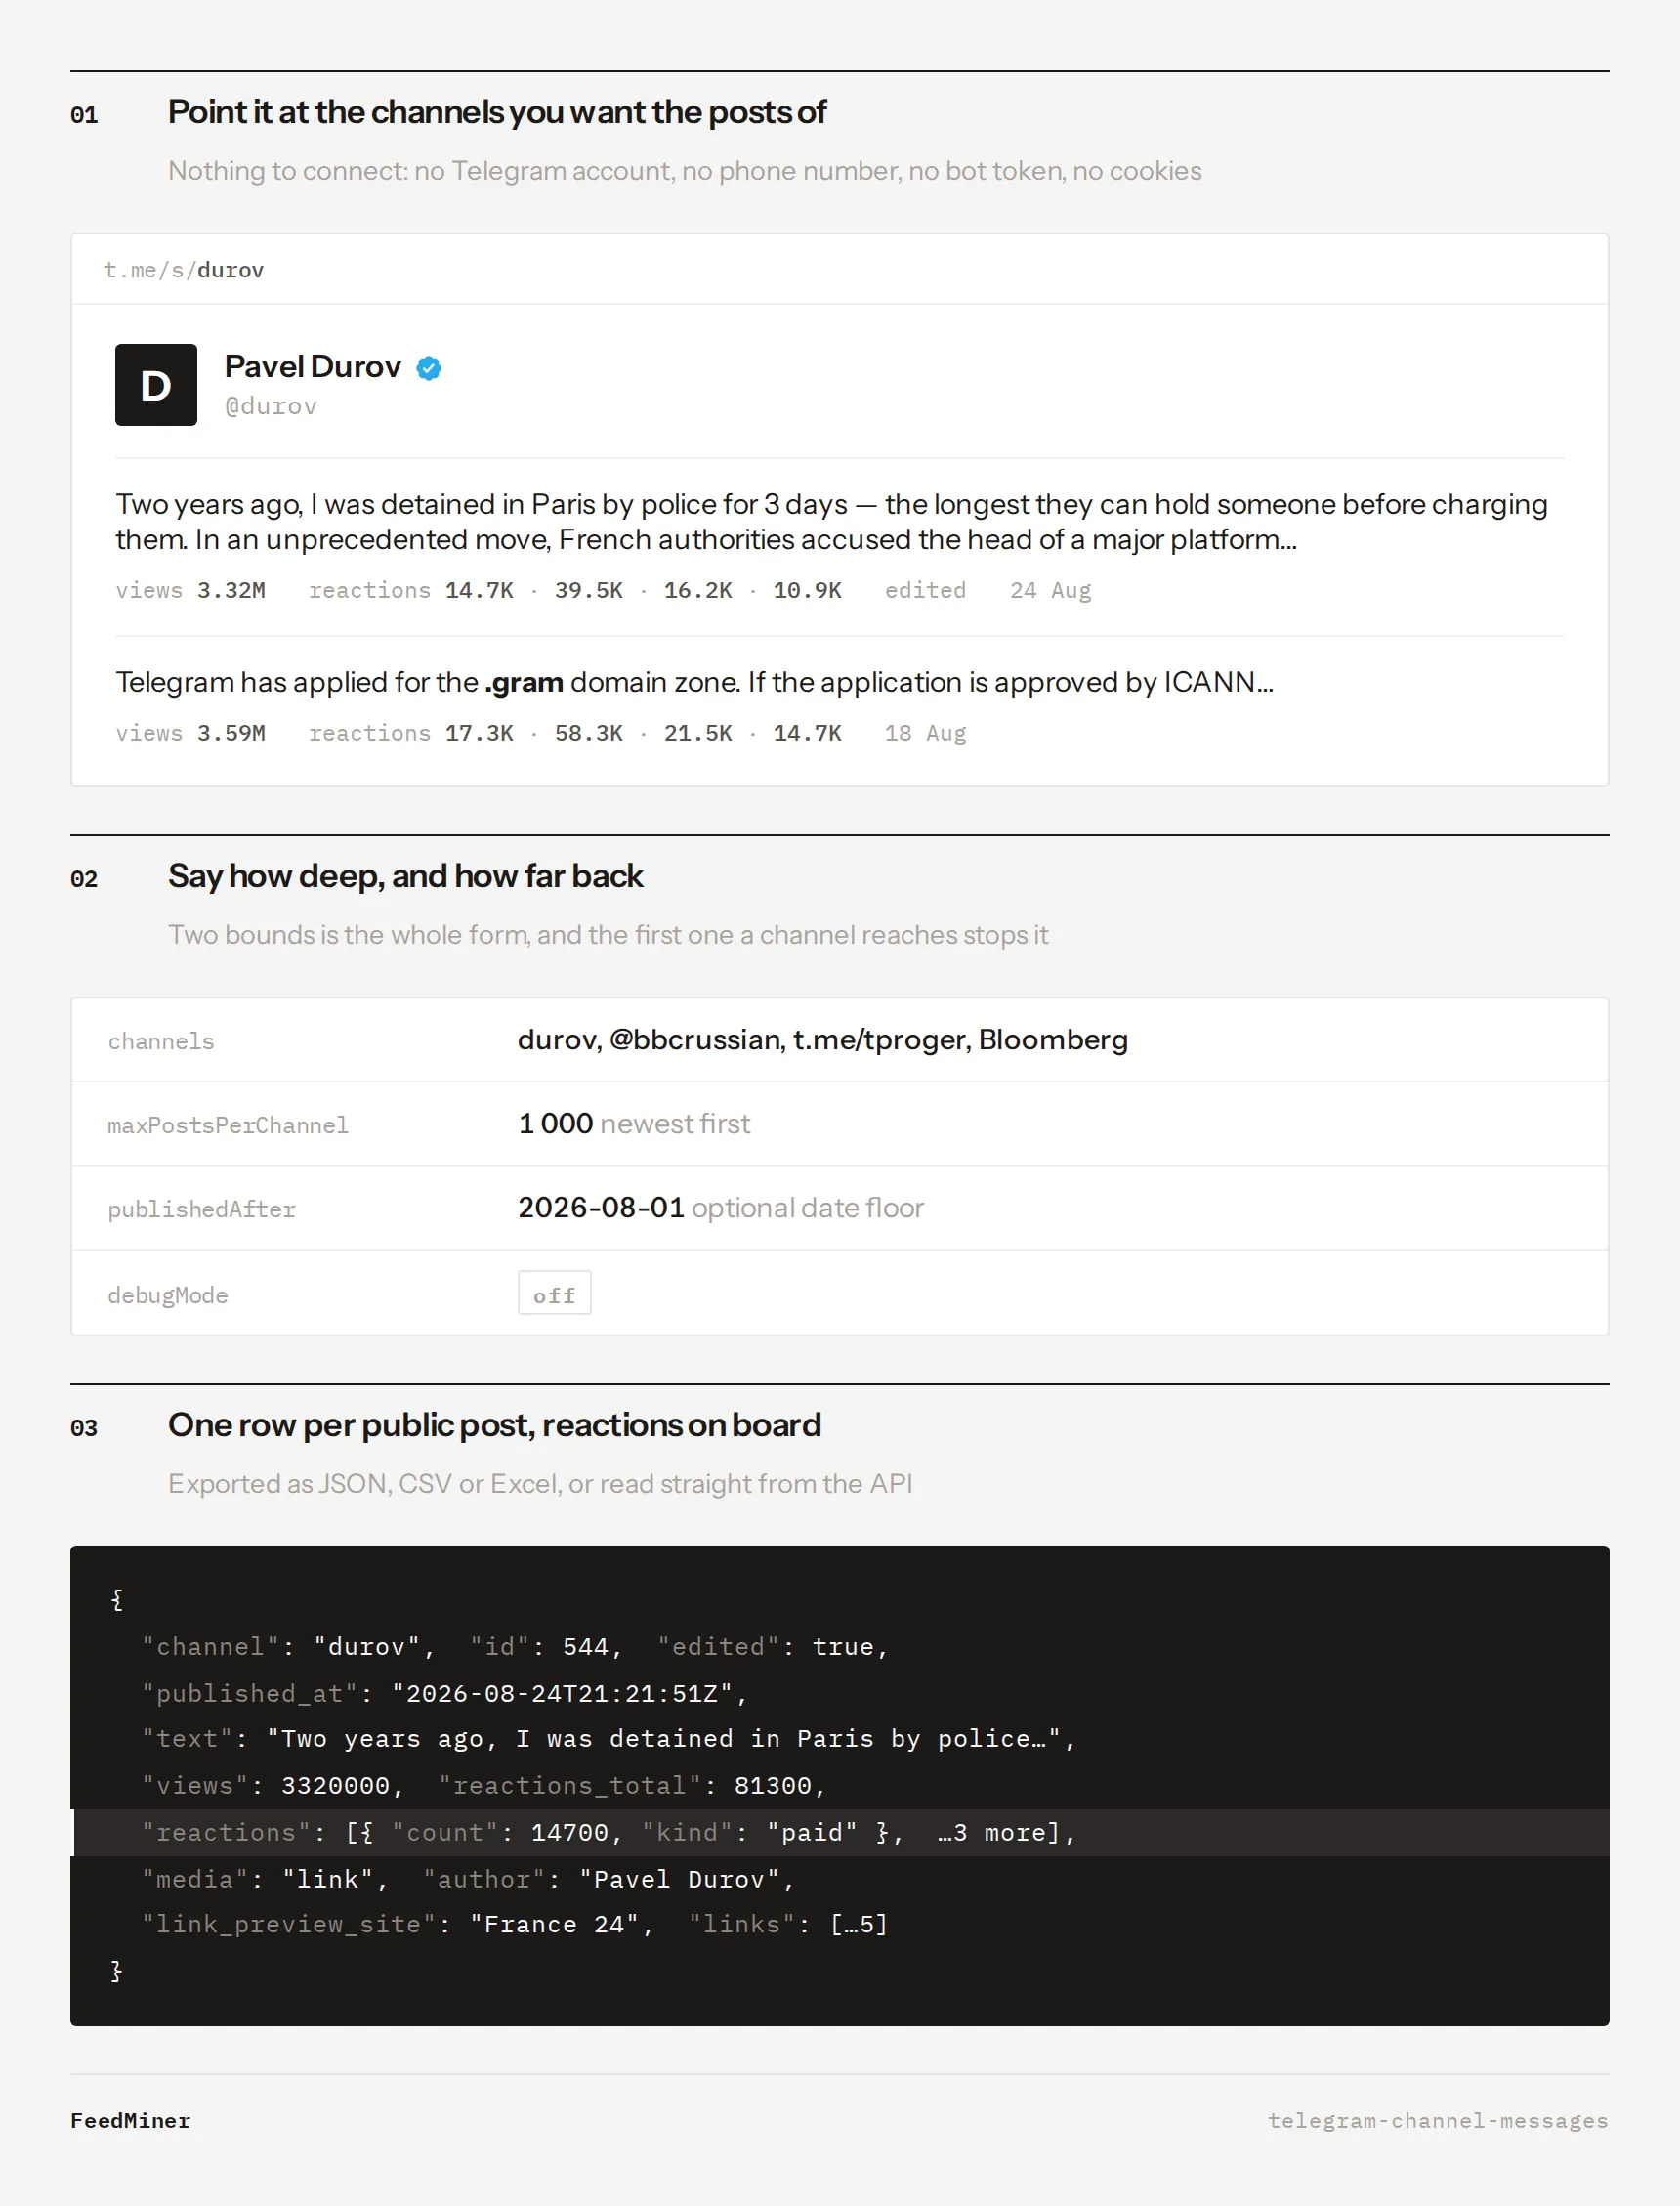
Paste the channels you want the posts of. That is the whole input.
The smallest run
A hundred posts from each, newest first.
However the channels were sent to you
With or without the @, as a t.me link, as a pasted t.me/s/ preview URL, as a link to a single post, in any case. Duplicates fold, so a column copied out of a spreadsheet runs unedited.
Everything since a date
Each channel stops at the first post published before your date. Raise the cap when the window is wide and the channels are busy — a news channel publishes hundreds of posts a week, and the cap is what stops before the date does.
A deep archive pull
Telegram serves twenty posts a page, so this is up to five hundred pages of one channel. A channel shorter than that simply ends: the run stops where the history does.
Measured: 10 000 posts from bbcrussian — the deepest single-channel pull the input allows — took 543 pages and under seven minutes, on each of two runs, well inside the hour a run is given by default. One channel is walked by one worker, so depth on a single channel is paced by that worker alone; a list of channels is walked eight at a time.
Input parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
channels | string[] | — | Required. The channel usernames. With or without @, as a t.me link, a t.me/s/ preview URL or a link to one post, in any case. Duplicates fold. |
maxPostsPerChannel | integer | 100 | How many posts to take from each channel, newest first. 1 to 10 000. |
publishedAfter | string | empty | Optional date floor, as 2026-08-01. Read as UTC midnight; write the full RFC3339 form with an offset if the boundary matters in your timezone. |
debugMode | boolean | false | Verbose log lines for support. Leave off. |
The two bounds work together and the first one reached stops a channel: whichever of "enough posts" and "far enough back" comes first. A channel also stops on its own when its history ends.
What data can you extract from a Telegram channel?
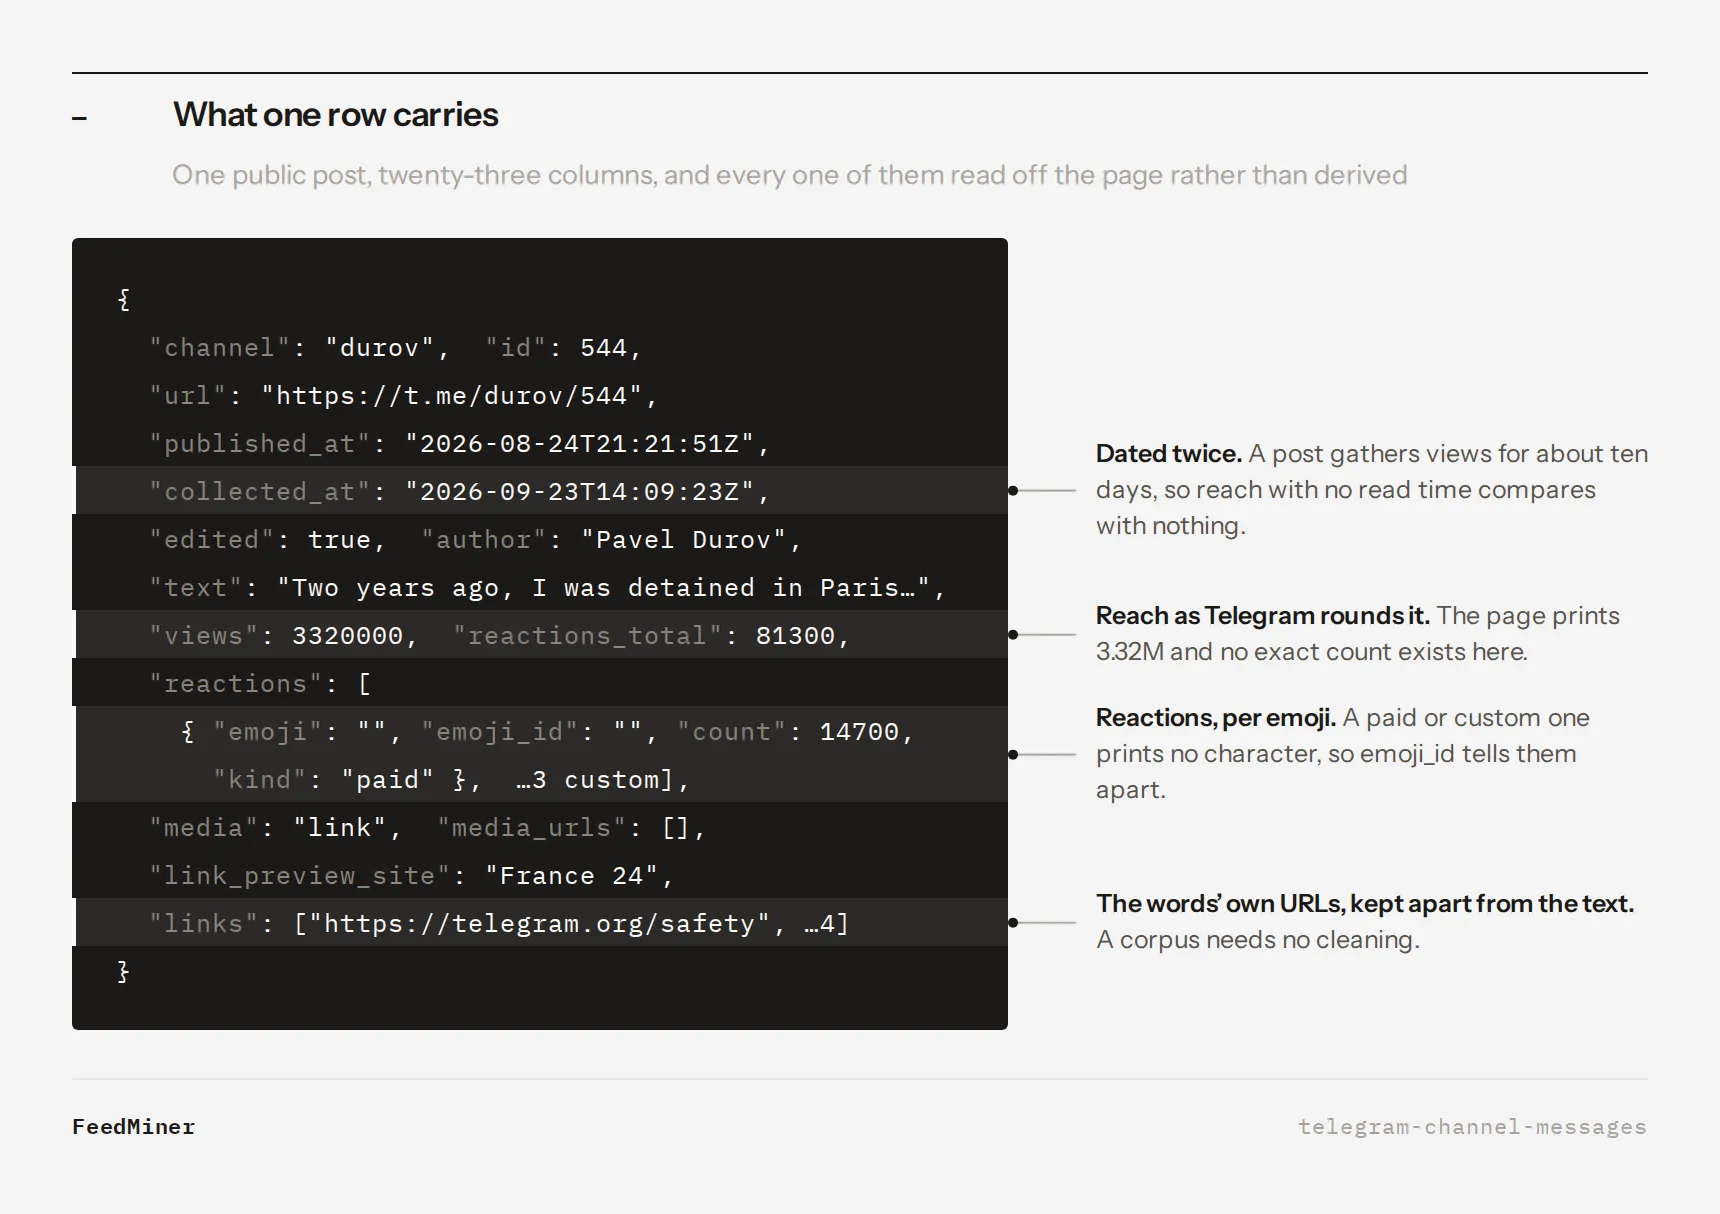
The post — id, url, published_at, edited, text, author (the per-post signature, when the channel signs its posts).
Its reach — views, reactions_total, and reactions, one entry per emoji with emoji, emoji_id, count and kind (standard, custom or paid).
Where it came from — forwarded_from and forwarded_from_url when the post was carried over from another channel, reply_to_url when it answers another post.
What it is made of — media (the heaviest attachment: photo, video, document, voice, poll, sticker, link or none), media_urls (the addresses Telegram prints for photos and videos, several of them for an album), poll_question and poll_votes, the unfurled card's link_preview_url / link_preview_site / link_preview_title, and links — every URL the post's own words point at.
Its context — channel, channel_title, and collected_at, the moment this run read the page.
A column a post does not carry ships as its zero: an empty string, 0, or an empty list. There is no null anywhere in the row.
Example row
Why views is a rounded number, and why every row is dated twice
Telegram prints view counts abbreviated — 5.14M, 40.7K — and that is the only figure this surface carries, for anyone. views is that string read back into an integer, so a post printed 5.14M ships as 5140000 and the true count is somewhere in a 10 000-wide band. Reaction counts are printed the same way, and reactions_total is our sum of them.
A Telegram post also keeps gathering views for about ten days after it is published. A reach figure with no read time is therefore a number you cannot compare with anything — including the same post read again next week — which is why every row carries collected_at beside published_at.
What a channel that gives nothing tells you
A row is a post, so a channel that has none produces no row and costs nothing. It is named in the run's closing line with one word:
| Reason | What to do about it |
|---|---|
no_such_handle | nobody holds this username — purge it from your list |
not_a_channel | it is a group, a bot or a person; none of those has a public message page |
no_preview | it is a channel, and Telegram serves no public message page for it |
no_posts | the channel has published nothing |
no_posts_in_window | it has posts, all of them older than your publishedAfter — widen it |
unreadable | Telegram would not serve the page, from two different exits. Run it again |
What this Actor covers
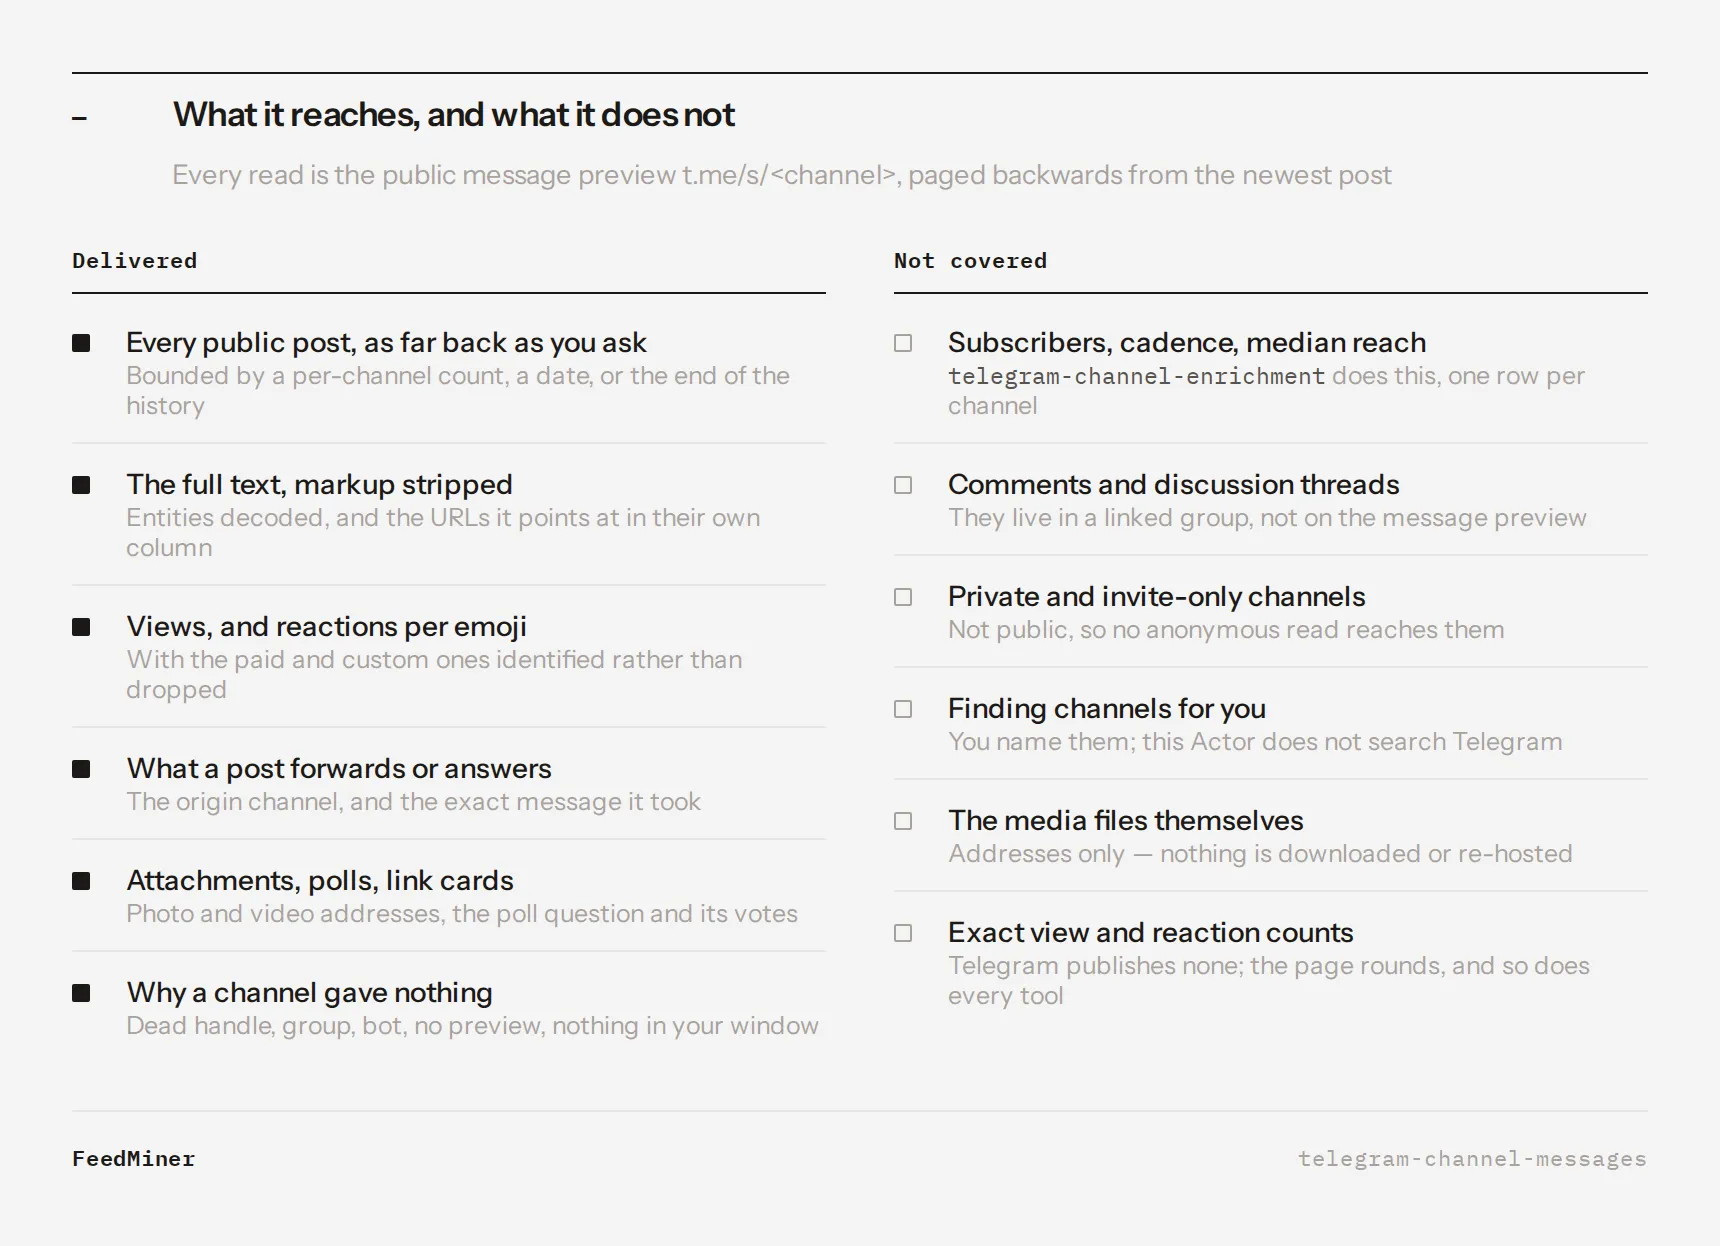
It reads what t.me/s/<channel> publishes to anyone: the posts of a public channel, as far back as you ask.
It does not read private or invite-only channels, group chats, comments and discussion threads, or members — none of those appear on that page. It does not search for channels: you name them. It does not download media; media_urls gives you the links.
For one enriched row per channel instead of one per post — the exact subscriber count, days since the last post, posts per week, median reach, reach per subscriber, script, content mix and the settled reach velocity — use Telegram Channel Enrichment. The two are built to be run together: qualify a list of channels with the first, then pull the posts of the ones worth reading with this one.
Pricing
| Event | What it is |
|---|---|
post | one delivered post. This is the whole bill. |
| Actor start | the platform's own fee, once per run |
You are charged for what reaches your dataset and for nothing else. A channel that gives no post is not billed, and neither is a post the dataset refused.
Against the market
The Telegram Actors on the Store that bill per message spread over two orders of magnitude. On the free plan, 1 000 messages costs between $0.35 and $30 depending on which one you pick; the ones that price in tiers come down to about $0.11 on the deepest Apify plan. Several also sell a channel-info row, which is the job of Telegram Channel Enrichment.
Compare them on two things rather than on the field list. What the run needs to exist: everything here comes off the public t.me/s/ page with no account anywhere in the loop, which is also why the perimeter above is what it is. And what you are billed for: a post that reached your dataset, never a handle you sent in, never a page that was read to find nothing.
What a real run costs
| Run | What it did | Duration |
|---|---|---|
| 10 channels, 1 200 posts each | 9 704 posts over 561 pages | 2 min 47 s |
| 1 channel, the full 10 000-post cap | 10 000 posts over 543 pages | 4 min 10 s |
| 12 channels, 60 posts each, since January | 403 posts, and four channels named as giving nothing | 3.9 s |
Free tier
Apify's free plan comes with monthly credits. A first run of a few hundred posts costs a fraction of a cent of platform usage, so there is nothing to commit before you have seen the output.
Advanced usage
Watch a set of channels every morning
Move publishedAfter forward each day and you pull only what is new. Nothing is kept between runs on our side, so the date is the whole state.
Build a corpus for text analysis
text is the message with markup stripped and entities decoded, and links holds the URLs separately, so the corpus does not need cleaning before it is tokenised.
Rank a channel's own posts by engagement
Sort the rows of one channel on reactions_total or on views. Both are rounded by Telegram, so read them as an ordering rather than as figures — and compare posts of similar age, since a post published yesterday has not finished gathering views.
Follow what a channel amplifies
Filter on forwarded_from being non-empty: that is the list of channels this one carries, with the exact post it took each time in forwarded_from_url.
Integrate Telegram data into your stack
Everything Apify offers applies: scheduled runs, webhooks on finish, and exports to S3, Google Sheets, Airtable or a database. The dataset is readable as JSON, CSV, Excel or XML from the API.
Python
JavaScript
Performance
| Measure | Value | Measured on |
|---|---|---|
| Posts per second | 58 | run 2kxvM6LRqgi4IRBmu, 9 704 posts in 166.7 s |
| Posts per request | 17.3 | the same run: 561 pages for 9 704 posts |
| Depth reached | 561 pages in one run | the same run, ten channels at once |
| Depth on one channel | the full 10 000-post cap, 543 pages, in 4 min 10 s | run dn4vQZOxWlmLEKMG1, bbcrussian alone |
| Memory used | 46 MB of the 256 asked for | the stress run, and the single-channel one |
| Requests refused by Telegram | none | every run to date, on every channel |
| Rows kept when a run is stopped early | 8 362 of the 8 431 collected | run 5R7wkh4FJkpvewVYK, stopped 65 s in |
Posts are written to the dataset as each page is read, which is why a run that is stopped or times out still hands you what it had already written. The gap is what was in flight at the moment it stopped — 69 posts in the run above — and you are not charged for those: billing follows what the dataset accepted.
FAQ
Do I need a Telegram account, a phone number or a bot token?
No. There is nothing to connect and nothing to keep alive on your side. Every read is the public t.me/s/<channel> page, served to anyone who asks.
How far back can it go?
As far as the channel's history, up to the cap of 10 000 posts per channel the input allows. Telegram serves twenty posts a page and this Actor pages backwards until your cap, your date, or the end of the channel — whichever comes first. The full cap has been walked on one channel: bbcrussian, 10 000 posts over 543 pages in under seven minutes, nothing refused. A single channel is read by one worker, so that is the pace depth runs at — and it fits the hour a run is given by default.
Why are the view counts round?
Because Telegram publishes them that way. The page prints 5.14M, not 5 143 882, and there is no exact figure anywhere on this surface. The same is true of reaction counts.
Why do some reactions have no emoji?
Because Telegram does not print a character for them. A custom reaction is an identifier — it is in emoji_id — and a paid reaction is Telegram Stars. kind tells you which of the three you are looking at.
A channel I know is alive came back as giving nothing.
Check the reason in the run's closing line. no_preview means Telegram genuinely serves no public message page for it. unreadable means the page would not load from two different exits — run it again. There is also a case this page will not claim to know about: Telegram hides some channels from some countries, and this Actor does not pin its exit.
Is the data live?
Yes. Every run reads Telegram at that moment. Nothing is cached, nothing is resold, and nothing is kept between runs — which is also why collected_at is on every row.
What does it not do? It does not find channels for you, does not read private or invite-only channels, does not read group chats, comments or discussion threads, does not list members, and does not download media files.
Support
- Found something off in the output, or need a field that is missing? Open the Issues tab on this Actor's page with the input you ran and what you expected. Issues are read daily.
- Need a custom variant — a different bound, a filter, a column this one does not carry? Ask in the Issues tab; FeedMiner builds on request.
Legal compliance
This Actor collects only public data, the same information any visitor can see on t.me. Message text, signatures and channel titles can contain personal data: processing information about people in the EU, the UK or California requires a lawful basis under GDPR or CCPA. Use the data for market research, analytics and business intelligence, not for spam or harassment.
FeedMiner · Fast, honestly priced scrapers, kept alive when platforms change.
Telegram Channel Messages · Telegram Channel Enrichment · All FeedMiner Actors


