
Website SEO Audit for Agencies: Crawler, Reports & Alerts
Pricing
from $4.00 / 1,000 page auditeds
Website SEO Audit for Agencies: Crawler, Reports & Alerts
Crawl client sites and run 77 SEO checks (titles, canonicals, hreflang, noindex, redirects, broken links, sitemaps, structured data). Get a prioritized fix plan, a white-label HTML report and alerts when SEO-critical things change. Respects robots.txt. Not affiliated with Google.
Pricing
from $4.00 / 1,000 page auditeds
Rating
0.0
(0)
Developer

HaniDev
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
8 hours ago
Last modified
Categories
Share
Website SEO Audit for Agencies: On-Page Crawler, Client Reports & Change Alerts
Crawl your clients' websites and get an on-page SEO audit with 77 checks, a prioritized fix plan, a white-label HTML client report and alerts when something SEO-critical changes (a page suddenly set to noindex, a canonical that moved, robots.txt blocking the site, a sitemap that disappeared, new broken links).
Built for SEO and web agencies, freelancers and in-house teams who look after several sites and want a repeatable, scheduled site audit they can send to clients — without per-seat SaaS pricing.
- ✅ Titles, meta descriptions, headings, canonicals, hreflang return links, noindex/X-Robots-Tag, redirects and redirect chains, broken internal links (with anchor text), click depth, orphan pages, XML sitemap consistency, structured data (JSON-LD) basics, Open Graph, mixed content, thin content and more
- ✅ Fix plan ranked by severity × affected pages × page importance, in plain English with "how to fix"
- ✅ White-label report per site (your agency name, client name, logo, colour) + portfolio overview + CSV for Excel
- ✅ Change tracking between runs: new/fixed issues and critical changes, optional webhook and fail-the-run for CI
- ✅ Pay only for pages that were analysed: error pages, redirects, robots-blocked and unreachable URLs are free
- ✅ Respects robots.txt, rate-limited, honest User-Agent, no proxies. HTML only (no browser), so it is fast and cheap
Responsible use: only audit websites that you own or that you are authorised to audit (for example, your clients' sites). You are responsible for how you use this Actor. robots.txt is always respected and cannot be turned off.
What does it check?
Severity: C critical · H high · M medium · L low · info (shown but never counted in the score).
| Area | Checks |
|---|---|
| Titles & descriptions | title-missing (H), title-empty (H), title-multiple (H), title-long (L), title-short (L), title-duplicate (M), desc-missing (M), desc-multiple (M), desc-long (L), desc-short (L), desc-duplicate (M) |
| Headings | h1-missing (M), h1-multiple (L), heading-skip (L) |
| Canonicals | canonical-missing (L), canonical-multiple (H), canonical-relative (L), canonical-invalid (H), canonical-outside-head (M), canonical-to-non200 (H), canonical-to-redirect (M), canonical-to-noindex (H), canonical-cross-domain (M), canonical-noindex-conflict (M) |
| hreflang | hreflang-invalid-code (M), hreflang-no-self (M), hreflang-no-return (M), hreflang-to-non200 (M), hreflang-to-noncanonical (M), hreflang-missing-xdefault (info) |
| Indexability & robots.txt | noindex-meta (info), noindex-header (info), nofollow-page (info), noindex-in-sitemap (H), robots-blocks-home (C), robots-missing (L), robots-sitemap-missing (L), robots-unreachable (H) |
| Status codes & redirects | status-4xx (H), status-5xx (H), redirect-chain (M), redirect-loop (H), redirect-temporary (L), http-not-redirected (M) |
| Internal links & structure | link-broken-internal (H), link-to-redirect (L), link-nofollow-internal (L), depth-deep (M), orphan-in-sitemap (M) |
| XML sitemap | sitemap-url-non200 (H), sitemap-url-redirect (M), sitemap-url-noncanonical (M), sitemap-url-blocked-by-robots (H), indexable-not-in-sitemap (L), sitemap-too-large (H), sitemap-missing (L), sitemap-error (M) |
| Content | thin-content (M), js-dependent-suspect (M) |
| Images, social & structured data | img-alt-missing (M), og-missing (L), og-image-relative (L), twitter-card-missing (L), jsonld-parse-error (H), jsonld-no-context (M), jsonld-no-type (M), jsonld-basic-missing (L), microdata-present (info) |
| Security, weight & basics | mixed-active (H), mixed-passive (M), html-heavy (L), html-truncated (L), resources-many (L), response-slow (L), viewport-missing (M), lang-missing (L), charset-missing (L) |
Rules marked as heuristics in the report (title/description length, thin content, page weight, response time, JavaScript-dependence) are rules of thumb, not search-engine requirements. Google, for example, states there is no fixed limit for title length; titles are shortened to fit the device width.
Site-wide checks include: robots.txt (missing, blocking the home page for search engines, no Sitemap: line, unreachable), sitemap (missing, unreadable, over 50,000 URLs / 50 MB, URLs that are broken, redirecting, non-canonical, noindex or blocked by robots.txt, indexable pages missing from it) and whether http:// redirects to https://.
Output
| Where | What |
|---|---|
| Dataset (one row per URL) | status, HTTP code, redirect chain, title/description (+ length, approx. pixel width), H1s, heading outline, canonical, robots directives, indexable, in-sitemap, hreflang, word count, images, Open Graph, JSON-LD types, link counts, broken links with anchor text, inlinks, mixed content, HTML size, response time, issues[], charged flag |
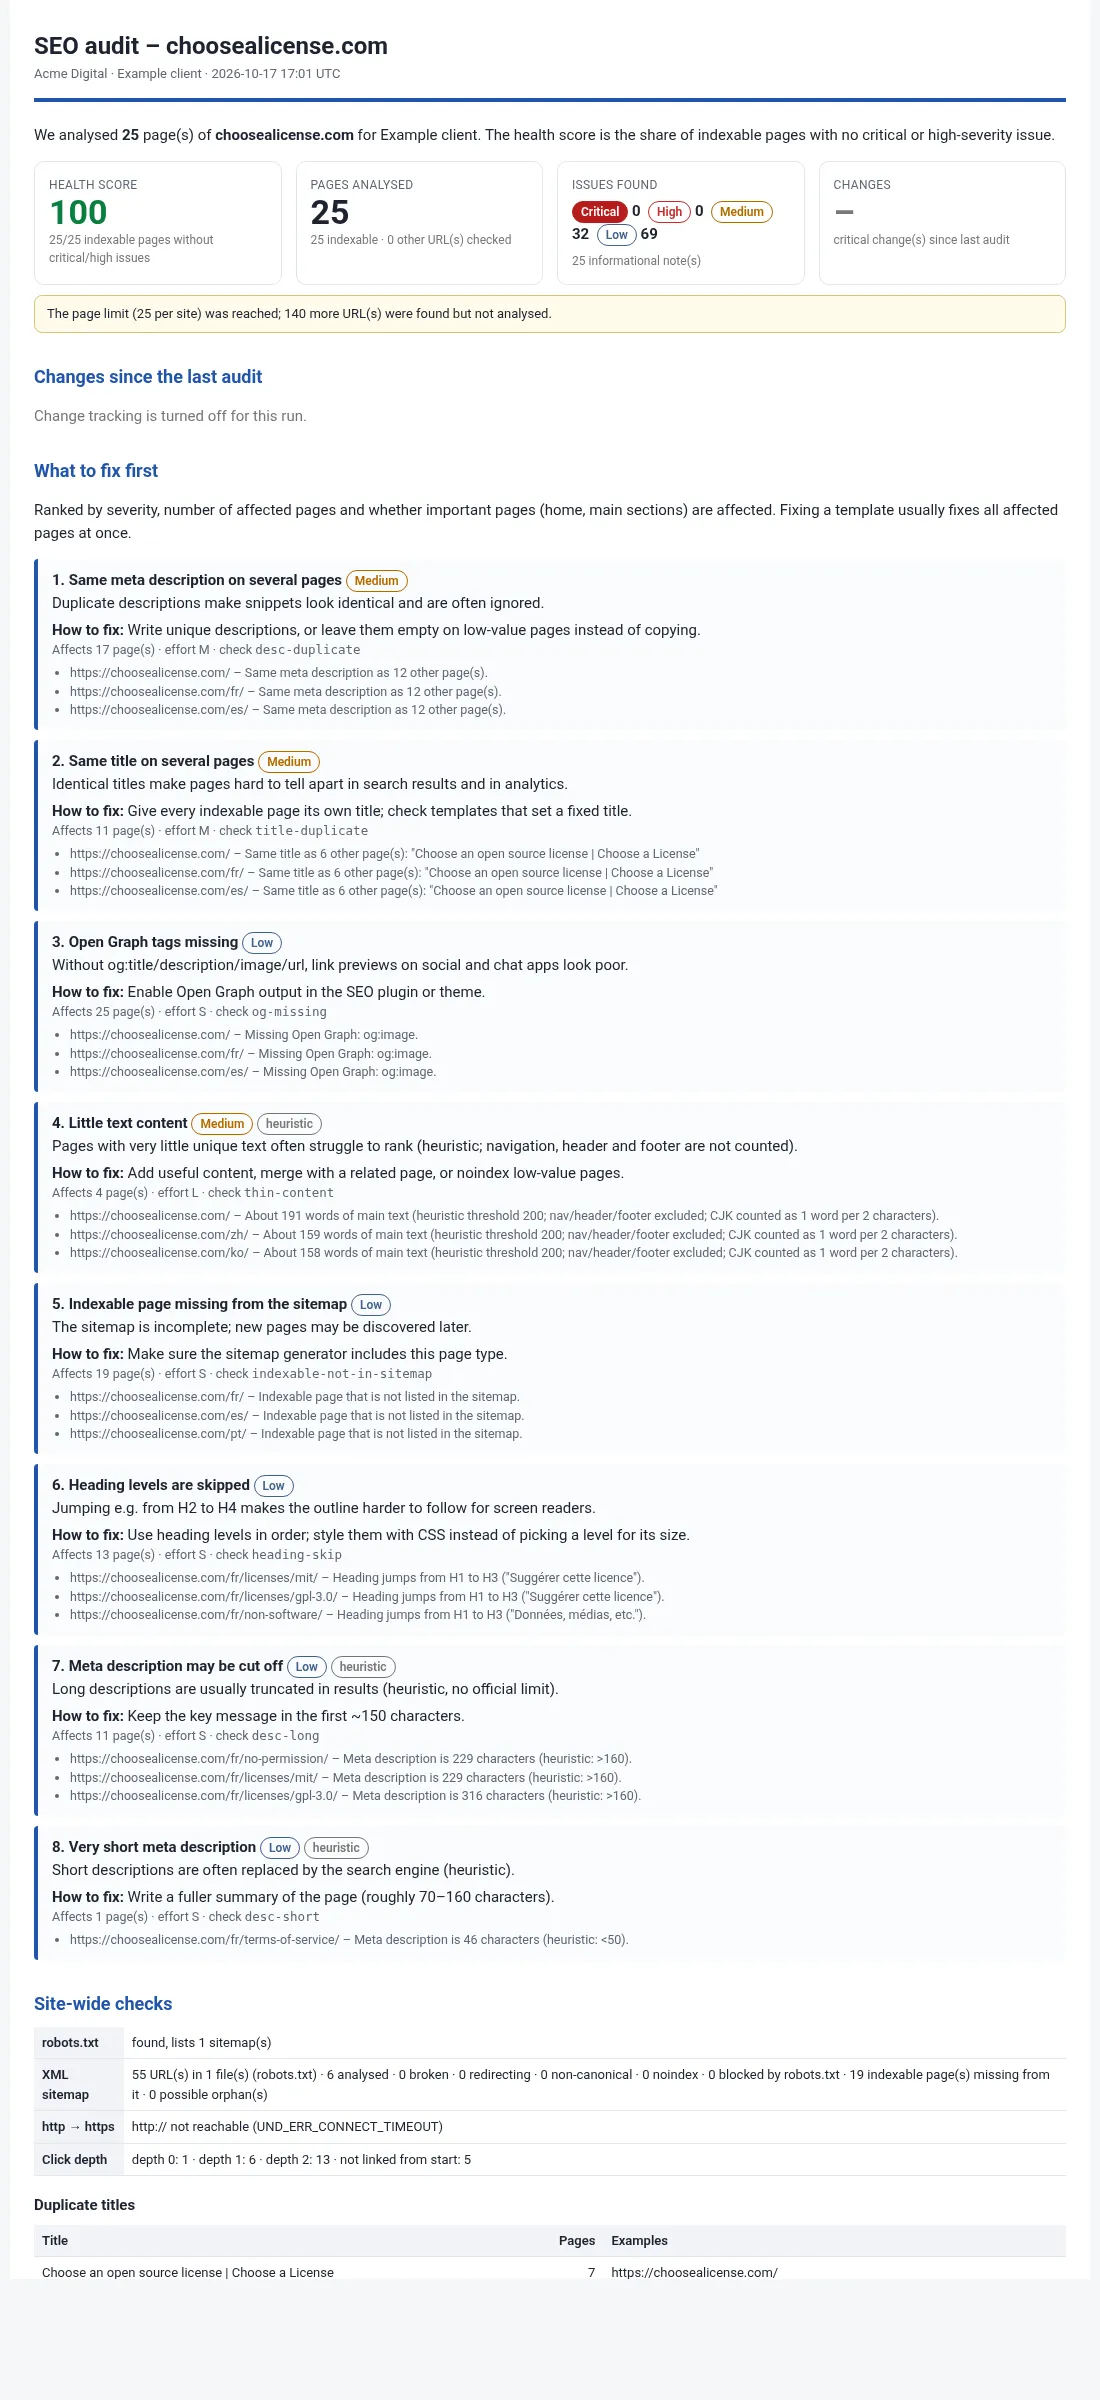
Key-value store REPORT-<site>.html | Self-contained white-label client report: health score, critical changes, fix plan, site-wide checks, duplicate titles, all URLs |
PORTFOLIO.html | One-page overview of all sites in the run |
ISSUES-<site>.csv | One row per issue, ready for Excel / Google Sheets |
summary.md | Short Markdown summary for Slack, email or an AI assistant |
OUTPUT | Machine-readable run result for CI and automations (status, critical change count, report URLs) |
Dataset seo-audit-site-summaries | One row per site and run (health score, issue counts, fix plan, sitemap consistency, depth histogram, changes). This named dataset keeps the history across runs. |
Health score (0–100) = share of indexable pages that have no critical or high-severity issue. If there is a site-wide critical issue (e.g. robots.txt blocks the home page), the score is capped at 49. "Indexable" = HTML page with HTTP 2xx, not noindex, canonical pointing to itself or absent.
Change alerts
Turn on Compare with the previous audit (default) and schedule the Actor (e.g. weekly per client). Each site keeps a baseline in a named key-value store (seo-audit-baselines-<baselineName>). The next run reports:
- Critical changes: page was indexable and is now noindex; page was 200 and now returns 4xx/5xx; canonical changed (or moved to another domain); robots.txt now blocks pages that were indexable; the XML sitemap is gone; a title was removed; at least N new broken internal links.
- New and fixed issues, pages whose title/description/H1/canonical changed, new pages and pages that are gone.
Pages that a run did not reach (page limit, spending limit) are reported as not re-checked, never as removed, so a partial run does not cause false alarms. If Alert webhook URL is set, a JSON payload is POSTed when there is at least one critical change. Fail the run on critical changes makes the run fail, which is handy in deploy pipelines.
Sample report
Open the full sample HTML report – this is the white-label report the Actor saves for each site.
Pricing (pay per event)
| Event | When it is charged | Price |
|---|---|---|
page-audited | an HTML page returned HTTP 2xx and was analysed | $0.006 (Free/Bronze), $0.005 (Silver), $0.004 (Gold and above) |
site-report | a site with at least one analysed page got its white-label report, fix plan and change comparison | $0.05 (Free/Bronze), $0.04 (Silver), $0.03 (Gold and above) |
Free: 4xx/5xx pages, redirects, robots.txt-blocked URLs, non-HTML files, blocked/unreachable URLs, extra target checks (HEAD requests), the portfolio, CSV, Markdown summary, OUTPUT and webhooks. Apify also charges its standard small Actor start fee.
Examples: one site with 25 pages ≈ $0.20 · 100 pages ≈ $0.65 · ten client sites × 100 pages per month ≈ $6.50.
Spending limit: if you set a maximum cost per run, the Actor keeps enough budget for each site's report, stops requesting new pages when the next one could not be paid for, and still delivers the report for the pages it analysed, clearly marked partial audit.
Input example
Useful options: Sample N pages per section (samplePerPathPattern) to cover big sites evenly, include/exclude patterns, max click depth, thresholds (e.g. {"titleMax": 65, "thinWords": 150}), include subdomains.
How it crawls (and how it treats your clients' servers)
- Plain HTTP requests (no browser). The User-Agent identifies the Actor:
Mozilla/5.0 (compatible; AgencySEOAudit/1.0; +<Actor page URL>). No proxies, no User-Agent rotation, no CAPTCHA or login bypass. - robots.txt is always respected for the
AgencySEOAudittoken (falling back to*rules). If robots.txt returns a server error, the site is not crawled. ACrawl-delayup to 10 s is honoured. - One request at a time per site, at least 1 s apart by default (minimum 0.5 s). HTTP 429/503 responses are retried after
Retry-After. After 5 failures in a row the site is skipped (shown as blocked/unverified, not charged). - Pages are discovered from the start URL and the XML sitemap (breadth-first, so click depth is real). About 20% of the page limit is reserved for sitemap-only URLs so orphan and sitemap checks have data.
- Every redirect hop is checked; private/internal network addresses are refused.
- Page content is analysed in memory. Pages are not stored except for the fields listed in Output.
Limitations
- JavaScript is not executed. Content that only appears after JavaScript runs is not seen. Pages that look like a JavaScript app shell are flagged (
js-dependent-suspect) so you know to check them with a rendering crawler. A JavaScript rendering mode is planned. - Response time is a single measurement and includes network latency; this is not a page-speed test.
- Structured-data checks are basic and do not claim rich-result eligibility.
- Click depth and orphan detection only see the pages that were crawled; with a page limit they are estimates (labelled "possible").
- No keyword rankings, backlinks or traffic data (these need third-party data).
FAQ
Can I audit a site I do not manage? Only if you have permission. The Actor respects robots.txt and rate limits, but you are responsible for having the right to audit the site.
Why is a page missing from my results? It may be blocked by robots.txt (listed as skipped (robots.txt)), outside the page/depth limit, filtered by your patterns, or not linked from any crawled page and not in the sitemap.
Is this a Google tool? No. Not affiliated with or endorsed by Google. It uses no Google APIs. Googlebot rules in robots.txt are evaluated locally to report SEO problems; nothing is requested as or pretending to be Googlebot.
Can I use it from my own code or an AI agent? Yes: run it via the Apify API, read OUTPUT and summary.md from the key-value store.
Not affiliated with or endorsed by Google. No Google APIs are used.


