
Reddit Scraper API
Pricing
from $1.50 / 1,000 results
Reddit Scraper API
Real-time Reddit API: send one HTTP request with keywords or Reddit links and get posts, comments, communities or user profiles back in seconds. No Reddit API key. Pay per result.
Pricing
from $1.50 / 1,000 results
Rating
0.0
(0)
Developer
Harsh Maur
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
16 minutes ago
Last modified
Categories
Features
Share
Reddit Scraper API — Real-Time Reddit Data in One HTTP Request (No Reddit API Key)
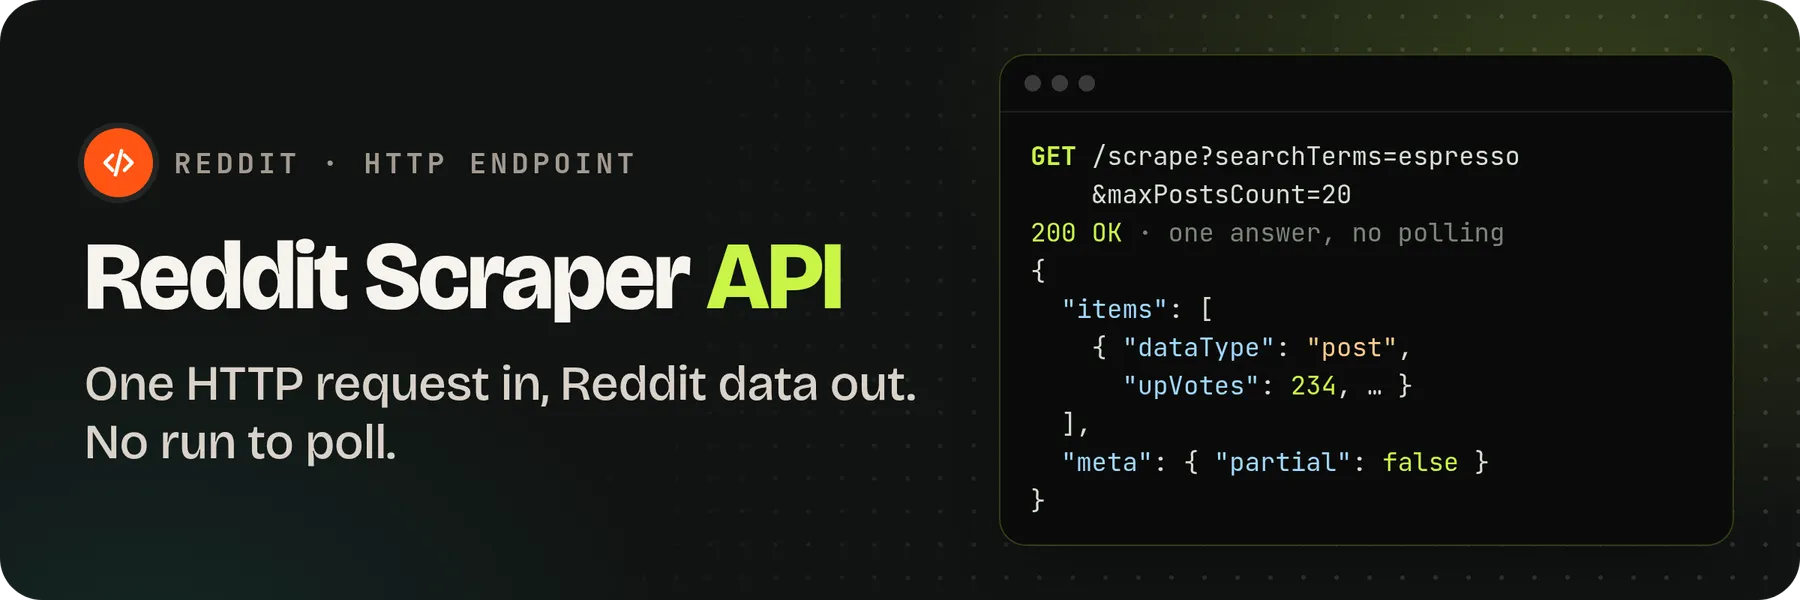
Call one URL, get Reddit posts, comments, communities and user profiles back in the same answer. No run to start, no dataset to poll, no Reddit app to register. Pay only for the items you get.


What it is • Quick start • Requests • Response • Limits • Errors • Pricing • FAQ
What is Reddit Scraper API?
Reddit Scraper API is a Reddit data endpoint that stays online. You send an HTTP request with keywords or Reddit links. The answer to that request holds the items as JSON.
Use it when your code needs Reddit data now:
- A chatbot or AI agent that looks up what Reddit says about a product while the user waits.
- A sales tool that checks new posts that mention a competitor when a rep opens a lead.
- A dashboard widget that shows the latest posts from a subreddit when the page loads.
- A Slack command or a webhook step in n8n, Make or Zapier that needs one answer, not a job to track.
It reads the public Reddit pages that anyone can open in a browser. You do not need a Reddit account, a Reddit developer app or a Reddit API key.
What one request can return
Each item has a dataType field:
post: title, body, author, subreddit, score, comment count, flair, media and dates.comment: body, author, score, depth, the parent and the post it belongs to.community: a subreddit with its title, description and member count.user_profile: a Redditor's karma, account age and profile links.
The fields have the same names as the dataset of Reddit Scraper, so code that reads one listing can read the other.
How to call the Reddit Scraper API
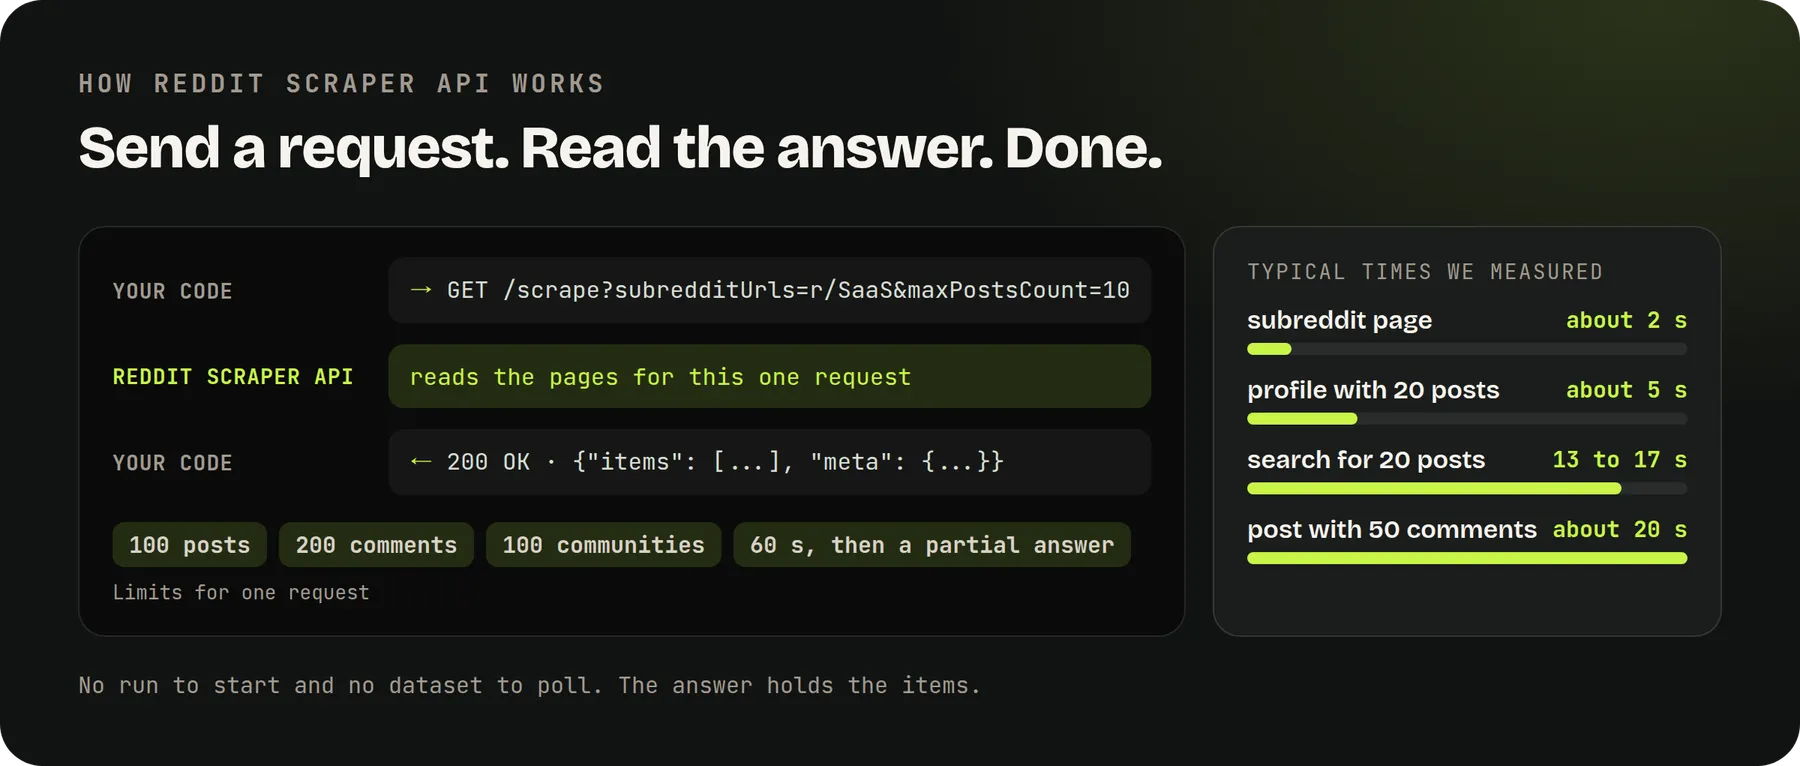
- Copy your Apify API token from Settings → API & Integrations.
- Send a GET request to
/scrapewith the fields as query parameters:
- Read
itemsfrom the JSON answer.
You can also send the token as a token query parameter. The first request after a quiet period can take longer, because the server starts first. The next requests go to the server that is already running.
Request examples: keywords, subreddits, posts and users
Every field from the input form works as a query parameter (GET) or in a JSON body (POST). Repeat a query parameter to send a list: searchTerms=crm&searchTerms=helpdesk.
Search Reddit for a keyword
Get the newest posts from a subreddit
Get a post and its comments
Get a user profile and recent posts
Python
JavaScript
Response format
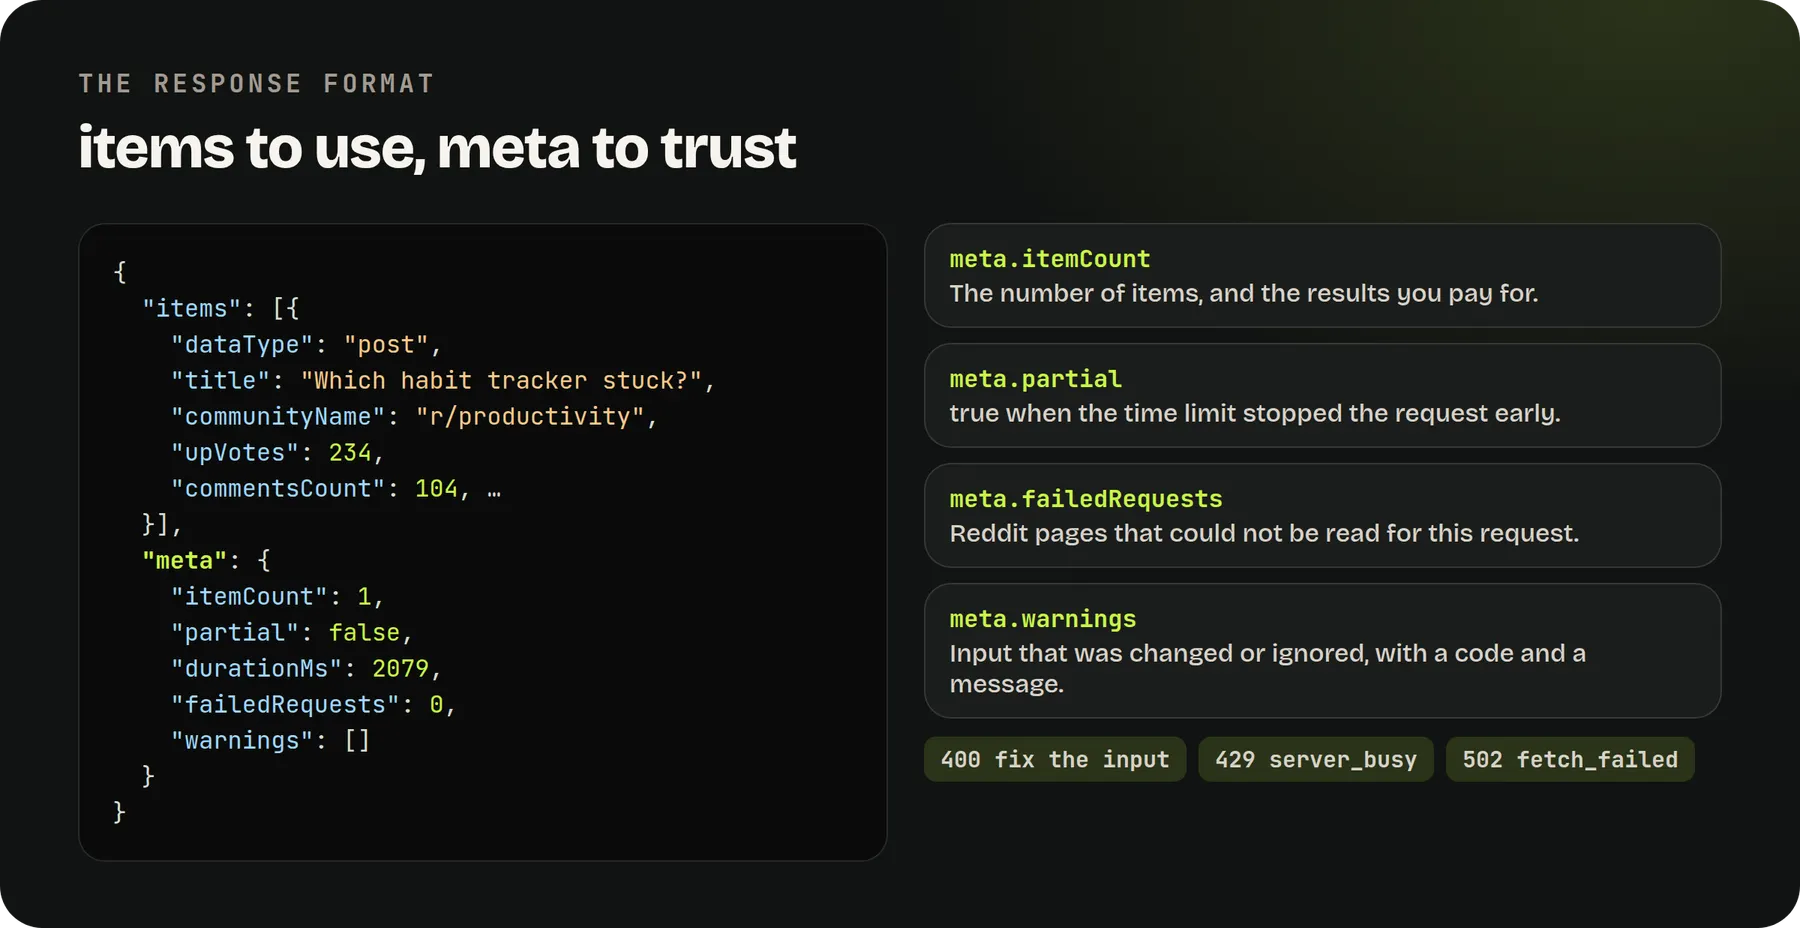
A successful answer has HTTP status 200, the items list and a meta summary:
meta.itemCountis the number of items, and the number of results you pay for.meta.partialistruewhen the time limit stopped the request early. You get the items found until then.meta.failedRequestscounts Reddit pages that could not be read for this request.meta.warningslists input that was changed or ignored, each with acodeand amessage.
Request limits and response time
One request is one short job. These limits keep each answer fast:
| Limit | Value |
|---|---|
| Posts in one request | 100 |
| Comments in one request | 200 |
| Communities in one request | 100 |
| Time for one request | 60 seconds, then a partial answer |
| Request body | 1 MB |
The posts limit counts every target together. For example, 3 keywords with maxPostsCount 50 ask for 150 posts, so the API refuses the request and tells you which field to lower. The answer arrives in milliseconds, and you pay nothing for it.
Typical times we measured: a subreddit page in about 2 seconds, a user profile with 20 posts in about 5 seconds, a keyword search for 20 posts in 13 to 17 seconds, and a post with 50 comments in about 20 seconds.
Do you need thousands of posts, a full subreddit archive or a daily schedule? Use Reddit Scraper. It runs as a batch job with no per-request limit.
Error codes
An error answer has this shape: {"error": {"code": "...", "message": "..."}}.
| Status | code | What to do |
|---|---|---|
| 400 | invalid_value, invalid_json, limit_exceeded, missing_targets and other input codes | Fix the input. The message names the field. |
| 404 | not_found | Send the request to /scrape. |
| 405 | method_not_allowed | Use GET or POST. |
| 413 | body_too_large | Send a body smaller than 1 MB. |
| 429 | server_busy | Wait for the seconds in the Retry-After header, then send it again. |
| 502 | fetch_failed | Reddit gave no data for this request. Try again in a minute. |
| 500 | internal_error | Try again. If it continues, open an issue. |
How much does the Reddit Scraper API cost?
You pay per result. Each post, comment, community or user profile in an answer is one result. The price per 1,000 results is on the Pricing tab.
- A request that fails, or that the API refuses, costs nothing.
- An empty answer costs nothing.
maxPostsCountand the other limits are caps. If a keyword matches only 8 posts, you pay for 8.
FAQ
How is this different from running Reddit Scraper through the API?
Reddit Scraper is a batch job. You start a run, wait for it to finish, then read the dataset. Reddit Scraper API answers the HTTP request itself, so one call gives you the data. Choose the API for small, fast lookups and Reddit Scraper for large or scheduled jobs.
Which input fields does the API support?
It supports the search, URL, date, flair, NSFW, sort and comment fields of Reddit Scraper, with the same names. The AI analysis fields and delivery to Slack, Notion or Google Sheets are only in Reddit Scraper. If you send one of those fields, the API ignores it and adds an unsupported_field warning to meta.warnings.
Can I filter posts by date?
Yes. Use postedAfter and postedBefore with a date (2026-11-01) or a relative period (7 days). Use commentedAfter and commentedBefore for comments.
Can I search inside one subreddit?
Yes. Add withinCommunity with the subreddit name, for example withinCommunity=startups.
Can I send many requests at the same time?
Yes. The API runs several requests at the same time and adds more capacity when the load goes up. When all slots are in use, you get a 429 answer with a Retry-After header. Wait that many seconds and send the request again.
Can I use it from an AI agent?
Yes. The API answers plain HTTP with JSON, so any agent that can call a URL can use it. This listing also publishes an OpenAPI description of /scrape, which many agent frameworks can import as a tool.
Can I start it from the Apify Console instead?
Yes. Fill in the input form and start a run. The run does one request and saves the items to the run's dataset.
Do I need a Reddit account or API key?
No. The API reads public Reddit pages. You need only your Apify API token.
More Reddit scrapers
| Actor | When to use it instead |
|---|---|
| Reddit Scraper | Large or scheduled jobs: thousands of posts, full subreddits, AI analysis and delivery to Slack, Notion or Sheets. |
| Reddit Search Scraper | Keyword monitoring as a scheduled run that saves every match to a dataset. |
| Reddit Comments Scraper | Every comment in long threads, with nested replies, from a list of post links. |
| Reddit User Scraper | Post and comment history of many Redditors in one run. |
| Subreddit Scraper | The full post archive of a community. |
Built by Harsh Maur • Questions? Contact support


