
Meta (Facebook & Instagram) Ads Library Scraper
Pricing
from $0.14 / 1,000 results
Meta (Facebook & Instagram) Ads Library Scraper
💰From $0.14/1K ads | Scrape all Facebook & Instagram ads of any page from the Meta Ad Library. Extract ad creatives, texts, titles, CTAs, image & HD video URLs, spend, reach and dates. Fast parallel scraping, multiple pages per run, date filters, no login or API key. Daily checks to ensure quality!
Pricing
from $0.14 / 1,000 results
Rating
4.9
(12)
Developer
Mary Lou
Maintained by CommunityActor stats
8
Bookmarked
2.2K
Total users
1.1K
Monthly active users
1.8 hours
Issues response
3 days ago
Last modified
Categories
Features
Share
📣 Meta (Facebook & Instagram) Ads Library Scraper
Every ad a brand or keyword is running on Facebook, Instagram, Messenger and Threads, in one spreadsheet.
Copy, headlines, buttons, landing pages, image and HD video links, dates and platforms. In minutes.
🔓 No Facebook login · 🔑 No API key · 🧑💻 No code · 💸 From $0.14 per 1,000 ads
🎬 Watch it in about a minute
📊 What one run tells you
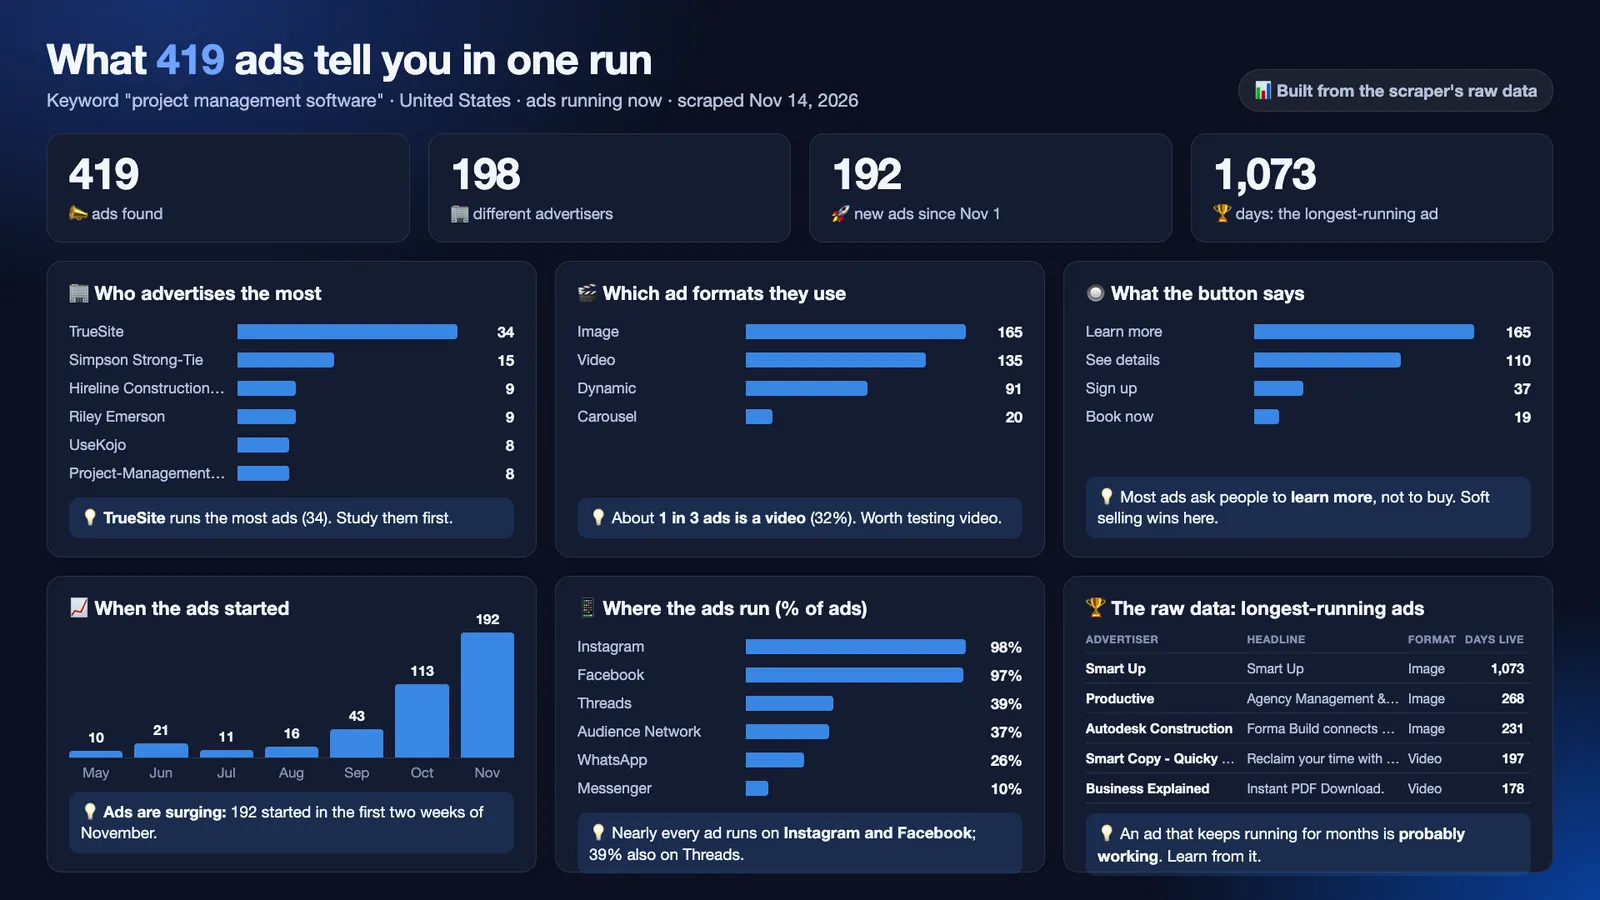
One keyword, one run, 419 ads. Here's what the raw data showed about who advertises "project management software" in the US:
| You'll see | Why it matters |
|---|---|
| 🏢 Who runs the most ads | Your biggest competitors, ranked |
| 🎬 Which formats they use | Whether to make videos, images or carousels |
| 🔘 What the buttons say | How hard competitors push for the sale |
| 📈 When ads started | Who just launched a campaign |
| 🏆 How long each ad has run | Ads that run for months are usually the ones that work |
🎯 What people use it for
| Use case | What you get | |
|---|---|---|
| 🔍 | Competitor research | Every ad a rival runs right now. Ads running for months are usually their winners. |
| 🎨 | Creative inspiration | Direct links to every image and video, to study hooks, formats and angles. |
| 📊 | Market research | Search a keyword across all advertisers and see a whole industry's messaging. |
| 🧲 | Lead generation | Find brands advertising on a topic that you didn't know about yet. |
| 📈 | Tracking over time | Schedule daily runs and spot when competitors launch, pause or scale ads. |
| 🇪🇺 | EU reach | For ads shown in the EU: people reached by country, age and gender, plus who paid (optional). |
🚀 How to use it in 3 steps
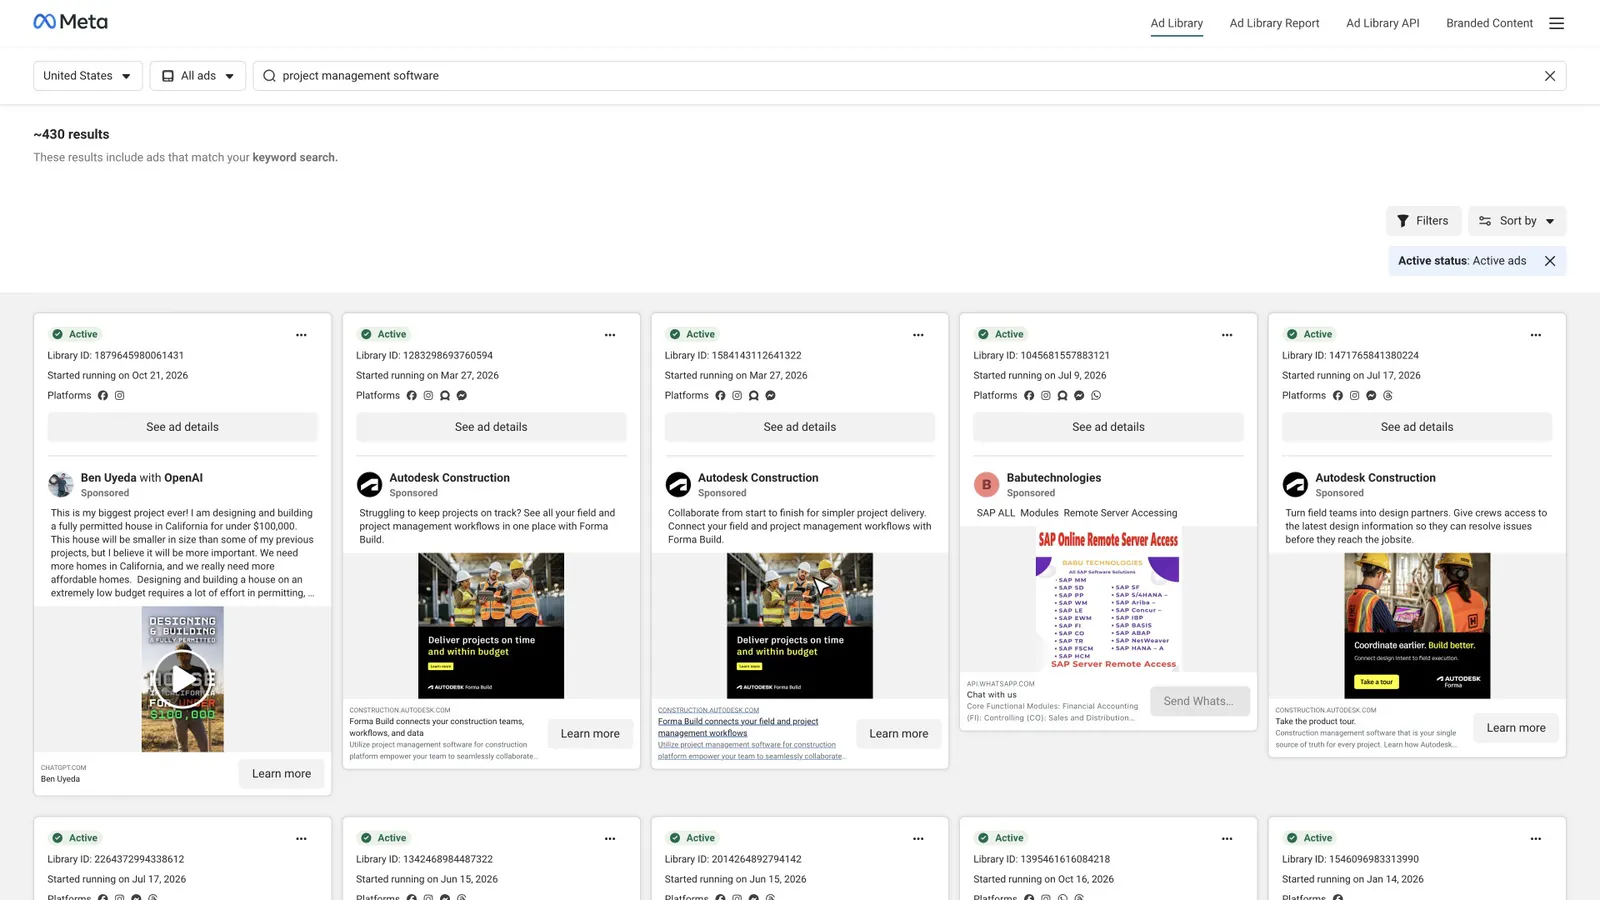
1️⃣ Search the Meta Ad Library and copy the link
Open facebook.com/ads/library, choose a country and All ads, then search for a brand or a keyword. Copy the URL from the address bar.
2️⃣ Paste it and press Start
Paste the link into Ad Library or Facebook page URLs. That's the only field you have to fill in.
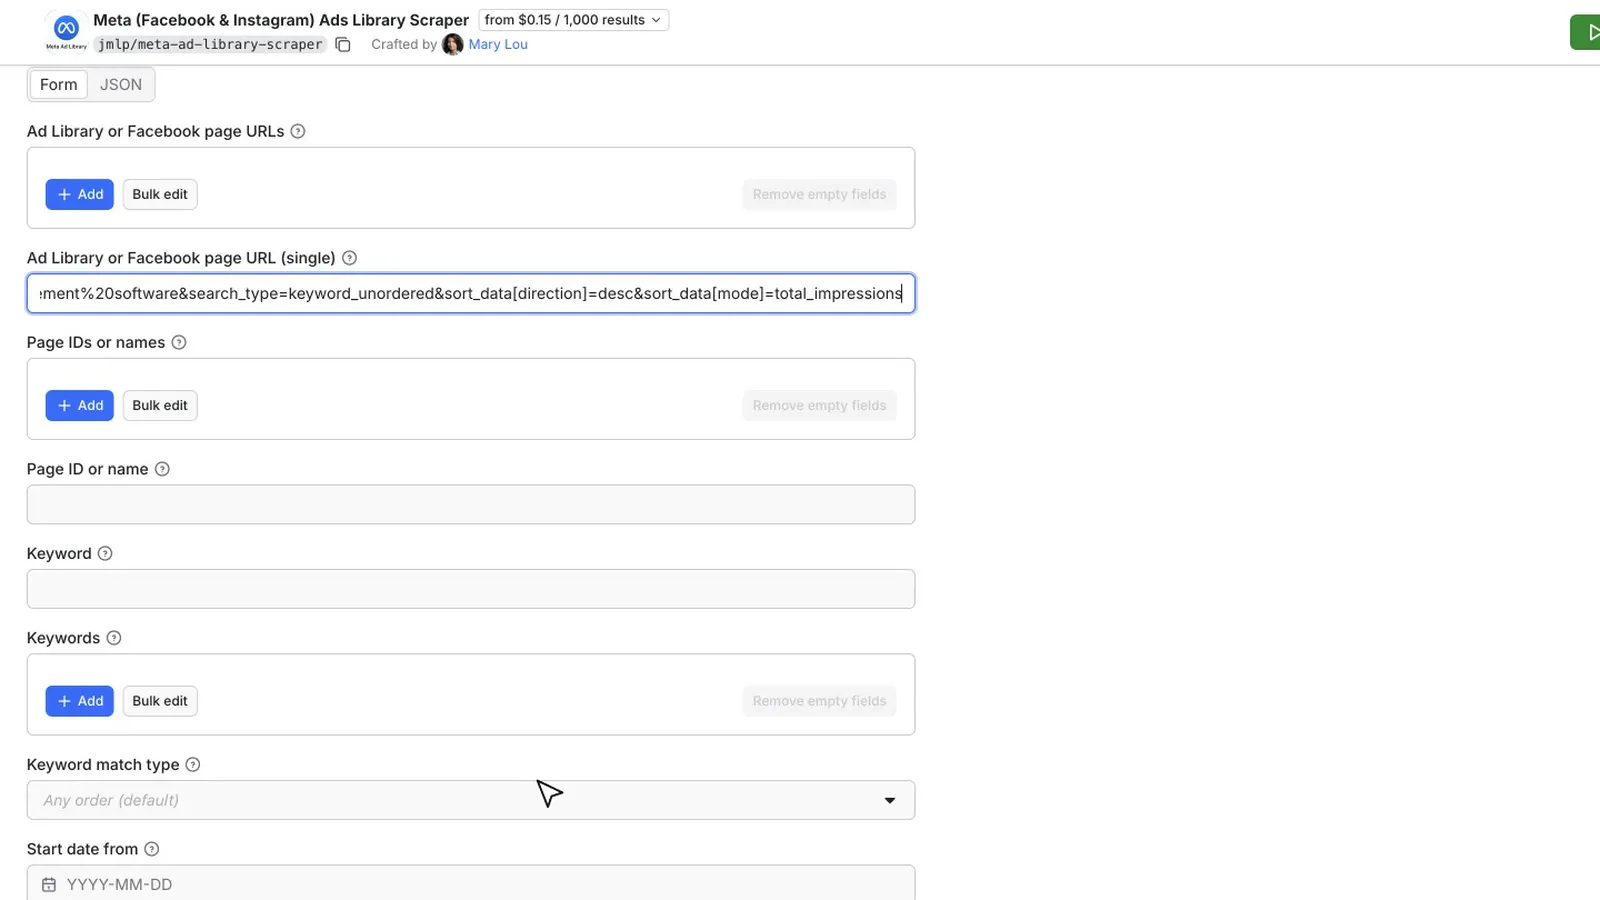
💡 No URL? Type a brand name (
Nike,ZARA) into Page IDs or names, or a word into Keyword. A brand's facebook.com, Instagram or website link works too.📚 Many brands? Paste one link per line. They're scraped in parallel into one dataset.
🧪 Max ads is prefilled with
100, so your first run costs about a cent. Raise it or clear it to get everything.
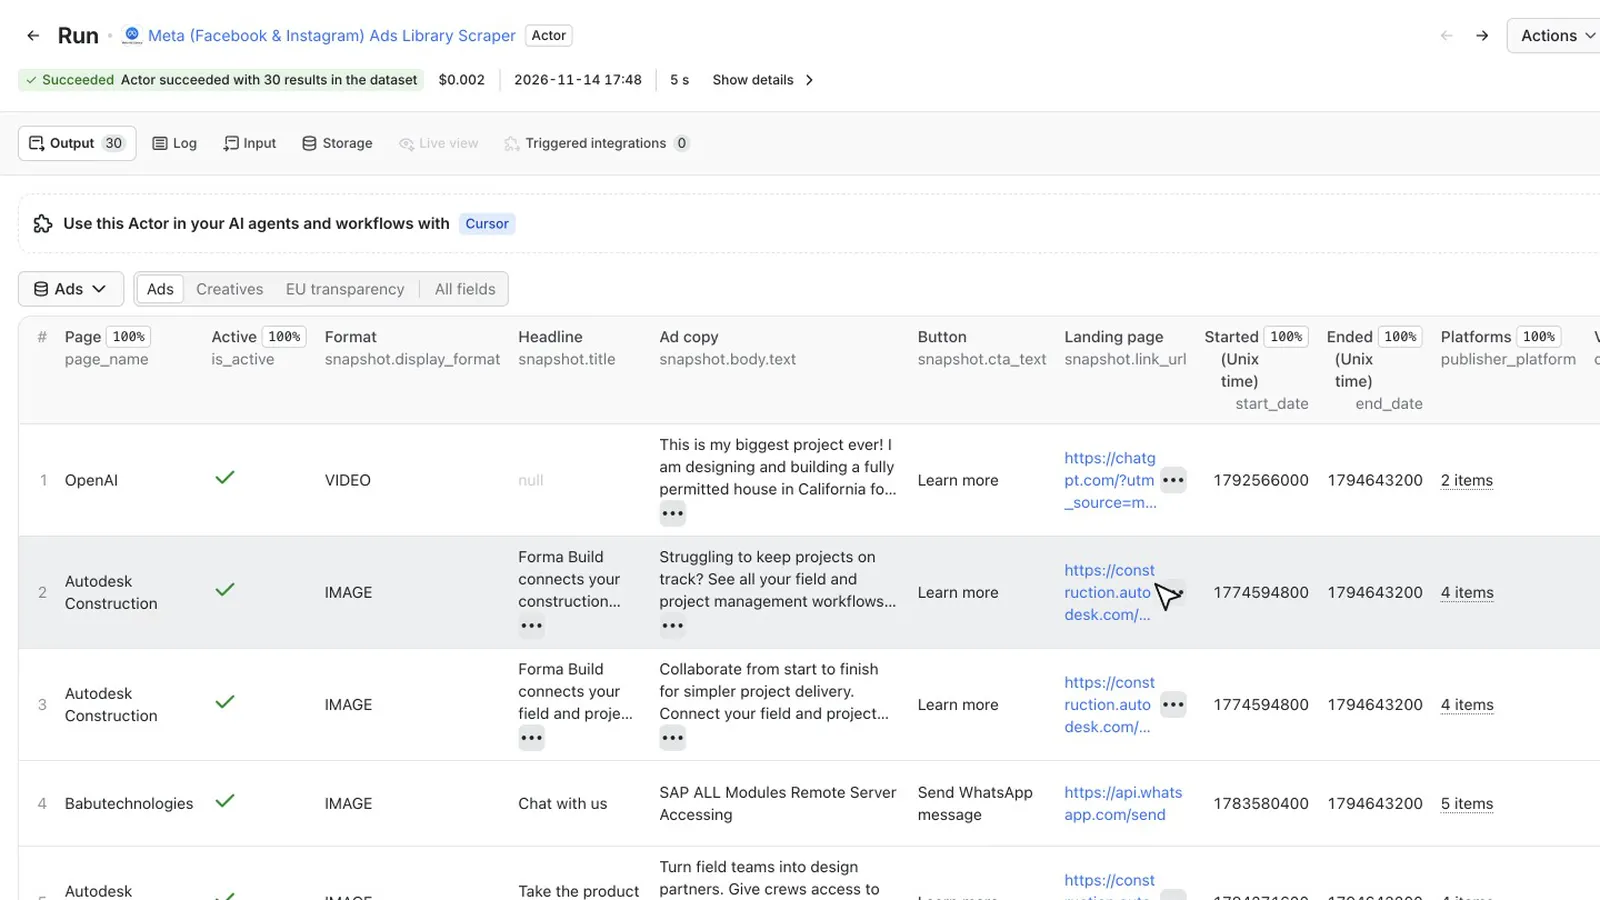
3️⃣ Get every ad as a clean table
Ads appear in the run's Output tab as they're scraped: page, format, headline, ad copy, button, landing page, dates, platforms and media links.
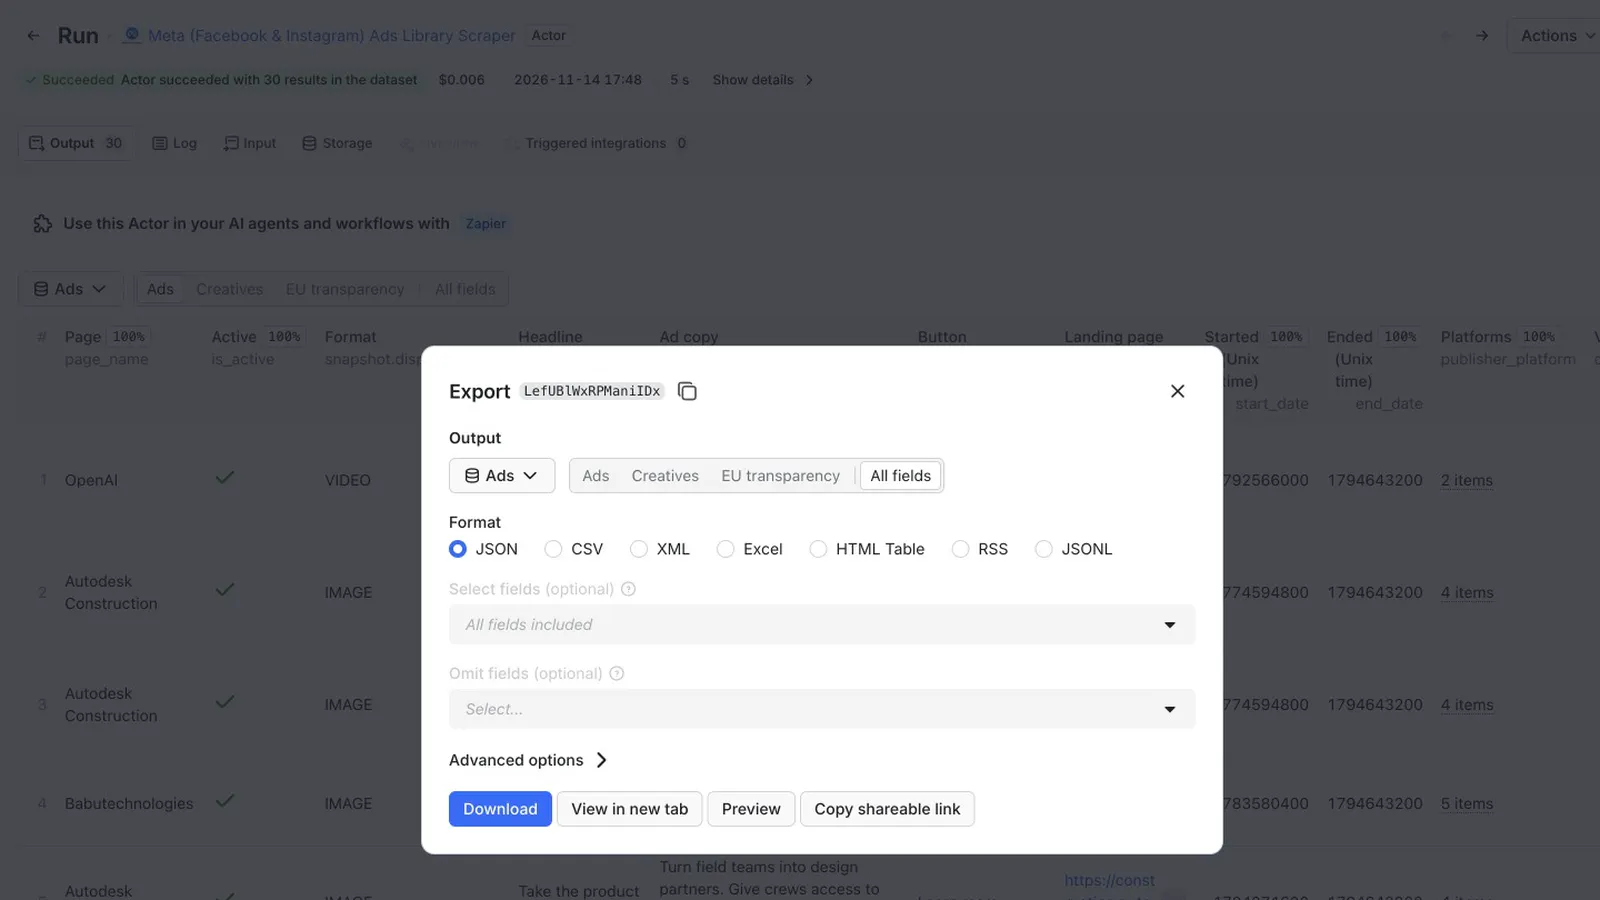
Click Export for Excel, CSV, JSON, XML or HTML, or read the dataset through the API.
⚙️ Input: every setting explained
You only have to tell the scraper what to scrape: a link, a page, a name or a keyword. Everything else has a sensible default. The API name of each setting is shown in code, for calling it from code.
1. What to scrape (fill in at least one)
| Setting | Default | What it does |
|---|---|---|
🔗 Ad Library or Facebook page URLs adLibraryUrls | empty | Paste links copied from your browser, one per line. Four kinds work: an Ad Library page (…view_all_page_id=…), an Ad Library keyword search (…q=…), a single ad (…?id=…, gets just that ad), or a brand's Facebook page (facebook.com/zara, /people/Name/123, profile.php?id=…, fb.me/zara). Instagram profiles and websites work too. A pasted Ad Library link keeps all its filters: country, dates, active status, sort order, media type, platform and language. The settings below only fill in what the link doesn't say. |
🔗 Ad Library or Facebook page URL (single) adLibraryUrl | empty | The same, for one link. |
🏷️ Page IDs or names pageIDs | empty | Several pages without links: a numeric page ID (the view_all_page_id number), the name as the Ad Library shows it (ZARA), an @username or a facebook.com link. Names are looked up the way the Ad Library's search box does it: a verified page wins; if several unverified pages share the name, all of them are scraped, most-liked first. |
🏷️ Page ID or name pageID | 15087023444 (Nike) in the form | One page, any of those ways. Clear it when you search by keyword or paste a link, or Nike gets scraped too. |
🔍 Keyword keyword | empty | Search every advertiser's ads for this text, like typing it into the Ad Library search box. Can match tens of thousands of ads, so set Max ads and narrow the country. |
🔍 Keywords keywords | empty | Several keywords in one run, all with the same settings. |
🔤 Keyword match type searchType | Any order | Any order finds the words anywhere in the ad (the Ad Library's default). Exact phrase needs the words together, in order. Only for keywords. |
2. Which ads (filters)
| Setting | Default | What it does |
|---|---|---|
✅ Active status activeStatus | Active only in the form (all through the API) | Active only: ads running right now, as the Ad Library shows by default. All ads: the page's whole history, often 10–100× more. Inactive only: ads that have stopped. |
🌍 Country country | ALL | Only ads shown in this country, or ALL for everywhere. Pick it from the list or type a name or code (Italy, it). One the scraper can't recognise is searched as ALL, so the run never fails over it. |
📅 Start date from minDate | empty | YYYY-MM-DD. Ads that were running on or after this date. An ad that started last year and is still running counts. Empty = the whole archive. |
📅 Start date to maxDate | empty | YYYY-MM-DD, included. Ads that were running on or before this date. |
⏮️ Keep active ads that last ran before the start date keepActiveBeforeMinDate | off | With a start date, the Ad Library leaves out an ad that is still active but was last shown before that date. Turn this on to keep every active ad. Costs one more request per page or keyword. Only applies when your dates reach today. |
↕️ Sort by sortBy | Impressions: high to low | Impressions is the Ad Library's default and the fastest. Most recent gets ads newest first, so Max ads keeps the newest ones (for example, the latest 300 for a keyword). A big search without Max ads is slower this way. |
3. Extra data
| Setting | Default | What it does |
|---|---|---|
🇪🇺 EU transparency euTransparency | off | For every ad shown in the EU, adds what the Ad Library shows under See ad details: how many people it reached in the EU, that reach by country, age and gender, the countries, ages and gender it targeted, and who paid for it. One extra request per EU ad, so runs take a little longer (about +35%) and use a little more proxy traffic (about $0.04 per 1,000 EU ads). Ads not shown in the EU get empty values. |
🧩 Compatible output (aaa_info) aaaInfoCompat | off | Adds the field names other Ad Library scrapers use (aaa_info, start_date_formatted, end_date_formatted, url), so a pipeline built for them works unchanged. Turns on EU transparency. |
🧾 Raw output raw | off | Saves Facebook's data exactly as it comes, without filling empty fields or ordering keys. Leave off unless you need it. |
4. Limits and cost
| Setting | Default | What it does |
|---|---|---|
🔢 Max ads maxAds | 100 in the form (no limit through the API) | Stop after this many ads in total, across everything you asked for. Caps both time and cost. Clear it or set 0 for no limit. |
🎯 Max ads per target maxAdsPerTarget | no limit | Stop each page, keyword or link after this many ads, so one huge advertiser can't use up Max ads for the others. |
💤 Trust pages known to be empty for (days) trustKnownEmptyDays | 0 (off) | A page that shows no ads is normally checked twice, because a blocked connection also looks empty. Set a number of days, and a page found empty by both checks within that time is checked once. About half the cost for pages without ads, with a small risk (about 1 check in 400) of missing a page that just started advertising. |
🪶 Lean first page leanFirstPage | off | Uses less proxy traffic when you check many pages: about 45% less on 20 pages and about 30% less on a single search, with the same ads. Falls back to the normal way by itself if Facebook refuses. |
5. Speed and reliability
| Setting | Default | What it does |
|---|---|---|
⚡ Max concurrency maxConcurrency | 4 | How many parts are scraped at the same time. Big searches are split into parts automatically. For tens of thousands of ads use 20–100: 100,000 ads took about 10 minutes at 50. Memory grows with it (64 MB each). Use 1 only if you need strict impression order. |
⏱️ Delay between pages (ms) delayMs | 0 | A pause between requests. Raise it to 1000 or more only if the log shows captcha warnings. |
🌐 Proxy proxyConfiguration | Apify Residential | Keep Residential. Facebook blocks datacenter IPs, so a run on anything else switches to residential when blocked. Your own proxies work too: put {session} where your provider takes a session id (http://user-session-{session}:pass@gate.example.com:7000) and every session gets its own IP. |
🔁 Proxy rotation attempts proxyRotations | 3 | How many fresh connections a page or search gets when Facebook blocks it (1–6). |
💾 Checkpoint progress resume | on | Saves progress every ~30 seconds, so a run the platform restarts carries on where it stopped without duplicates. |
▶️ Continue from last run continueFromLastRun | off | If your last run with the same input was interrupted, scrape only what it missed. Its earlier ads stay in that run's dataset. |
6. Advanced (leave as they are)
| Setting | Default | What it does |
|---|---|---|
Search by keyword when a page isn't found keywordFallback | on | A name that matches no page is searched as a keyword (up to 1,000 ads), a page with no matching ads brings its regional pages (Gymshark Germany, …), and a name with commas is tried as a list. Turn off to scrape only pages it can pin down exactly. |
Max pages per shard maxPages | no limit | Stops each part after this many pages of 10 ads. For testing. |
Page size pageSize | 10 | Facebook answers at most 10 ads per page, so anything larger is sent as 10. |
Shard split threshold shardSplitThreshold | 1500 | A page or search with more ads than this is split into parts that run in parallel. |
Pagination doc_id override docId | empty | Leave empty; it refreshes itself. |
Proxy session id proxySessionId | empty | Pins one IP, for debugging. Ignored when Max concurrency is above 1. |
TLS fingerprint impersonate | chrome146 | Which browser the requests look like. Leave as is. |
📦 Output
One row per ad. Every row has the same columns, and fields Facebook doesn't publish come back empty rather than missing.
| Field | What it is |
|---|---|
page_name, page_id | 🏢 Who is running the ad |
snapshot.title | 📰 Headline |
snapshot.body.text | ✍️ Ad copy |
snapshot.cta_text | 🔘 Button ("Shop now", "Install now"…) |
snapshot.link_url | 🔗 Landing page |
snapshot.images[] / snapshot.videos[] | 🖼️ 🎬 Direct image and HD/SD video URLs |
snapshot.display_format | IMAGE, VIDEO, DCO, DPA (catalog), carousel… |
is_active, start_date, end_date | ⏱️ Is it running, and when it ran |
publisher_platform | 📱 Facebook, Instagram, Messenger, Audience Network, Threads |
collation_count | 🧬 How many versions of the ad exist |
input | 🧷 The entry from your input that found this ad, exactly as you sent it |
eu_total_reach, eu_transparency, payer_beneficiary_data | 🇪🇺 With EU transparency on |
spend, reach_estimate | 💵 Only for political and social-issue ads, where Meta discloses them |
📄 A full sample record, a real video ad with EU transparency on (keyword "project management software", Germany). Long media links are cut short with …, and the EU lists show 3 of 19 countries and 2 of 19 country breakdowns:
💰 Pricing
$0.15 per 1,000 ads on Free and Starter plans, $0.14 on Scale and above, plus Apify platform usage at your plan's own rate. Runs that find nothing have no scraper charge.
| You scrape | Scraper charge | + Platform usage | ≈ Total |
|---|---|---|---|
| 200 ads | $0.03 | ~$0.01 | ~$0.04 |
| 1,000 ads | $0.15 | ~$0.04 | ~$0.19 |
| 10,000 ads | $1.50 | ~$0.40 | ~$1.90 |
| 100,000 ads | $15.00 | ~$4.00 | ~$19.00 |
Quoted at Free-plan rates, the most this gets. Usage is mostly residential proxy traffic, measured on real runs.
🛡️ Keep it predictable: set Max ads for a hard ceiling, or a maximum cost per run in the run options. The scraper stops itself just under your budget and finishes normally.
⚡ Speed
| Ads | Time |
|---|---|
| 200 | ~30 seconds |
| 1,000 | ~2–3 minutes |
| 30,000 | ~3 minutes (Max concurrency 50) |
| 100,000 | ~10 minutes (50) · ~8 minutes (100) |
Big pages and searches are split into parts and scraped in parallel. If a run is interrupted, progress is saved: a platform restart resumes by itself, and Continue from last run fetches only what was missed.
🧑💻 For developers and AI agents
Run it from the API, the Apify SDKs, Make, Zapier, n8n, or any AI agent through Apify's MCP server.
Input is read forgivingly. Names other scrapers use work too: startUrls, urls, url, maxItems, resultsLimit, count, limitPerSource, scrapeAdDetails, scrapePageAds.*. A country can be Italy or it; a date can be 20/11/2025 or Nov 20 2025. Anything it can't use is skipped with a warning instead of failing the run, and the log says how each field was read.
❓ FAQ
Do I need a Facebook account or the official API?
No. The Ad Library is public. Meta's official API only covers political and social-issue ads in most countries; this scraper returns every category, with full creatives.
Is it legal?
It collects only what Meta publishes in its public ad-transparency tool: no private or logged-in data. You're responsible for how you use the data in your jurisdiction.
Why do I get more ads than the Ad Library showed me?
All ads returns a page's full history, often 10–100× what's active. Choose Active only to match what the Ad Library shows by default.
My date range returns ads that started earlier. Why?
Facebook's date filter means "was running in this window", so a long-running ad matches every window it was live in.
An ad is active in the Ad Library but missing from my dated run. Why?
For an active ad, Facebook's end date is the last day it was shown. An active ad last shown before your start date is left out, in the Ad Library too. Turn on Keep active ads that last ran before the start date to include it. The run's SUMMARY record counts these as activeAdsBeforeMinDate.
Where are spend and reach?
Meta only publishes spend for political and social-issue ads. For ads shown in the EU, turn on EU transparency to get reach by country, age and gender, and who paid.
My run finished without ads. Why?
Either nothing to scrape was given, or the page has no ads matching your filters (try Country ALL or All ads). Empty pages are double-checked on a fresh connection, and the brand's regional pages are checked for you. A name with no matching page is searched as a keyword. The run log says which happened.
Why did I get ads from a page I didn't ask for?
Some brands advertise from a separate page per country (Gymshark, Gymshark Germany…). When your page has nothing matching, its regional pages are checked. Every ad carries its own page_id and page_name.
The log shows a captcha warning.
Facebook rate-limited part of the run. That part moves to a fresh connection and continues; anything still blocked is retried at the end. To avoid it, lower Max concurrency or raise Delay between pages.
How do I download the images and videos?
The dataset has direct URLs. Open them, or feed the column to any bulk downloader.
💬 Support
Found a bug, need a field, or want a custom setup? Open an issue on the Issues tab.


