

Website Screenshot: Full Page or Mobile, with Blank-Page Checks
Pricing
from $1.50 / 1,000 screenshot without problems
Website Screenshot: Full Page or Mobile, with Blank-Page Checks
Website screenshots of the URLs you list (first screen or full page, desktop or mobile, PNG/JPEG), each checked for blank page, HTTP error, bot-check page and height cut. Cookie banners hidden, never accepted. Honours robots.txt by default; blocked pages are reported, not bypassed.
Pricing
from $1.50 / 1,000 screenshot without problems
Rating
0.0
(0)
Developer

Jack Valmadre
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
17 days ago
Last modified
Categories
Security
Limited permissionsShare
Website Screenshots with Checks
Screenshots of the web pages you list (first screen, full page, the top N pixels or one element, desktop, mobile or your own window size, PNG or JPEG) and a machine check on every image to flag likely blank images, HTTP errors and common bot-check pages. For developers and automation workflows capturing batches of public pages. Made by Madrasco.
See real results before running
These are saved results from build 0.3.7, run on 3 October 2026. Open the images, inputs and JSON results without signing in or starting a run. They are snapshots of the Python documentation, so a new run may look different.
Desktop: first screen
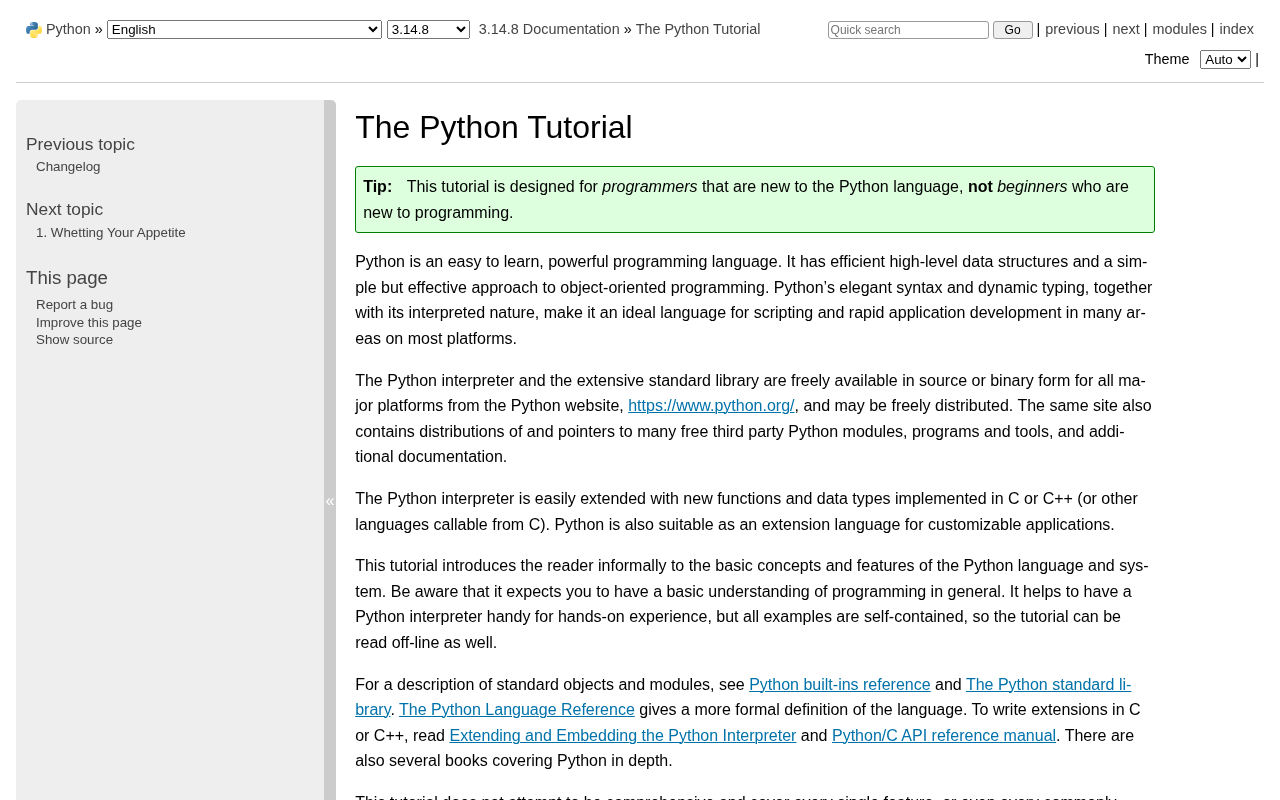
The returned image is 1280 × 800 pixels. Click it to open the full-size PNG.
The result row reports ok: true, problems: [] and httpStatus: 200.
This input captures the tutorial and a missing page (the flagged result is below).
Saved input · Actual dataset JSON
Mobile: first screen
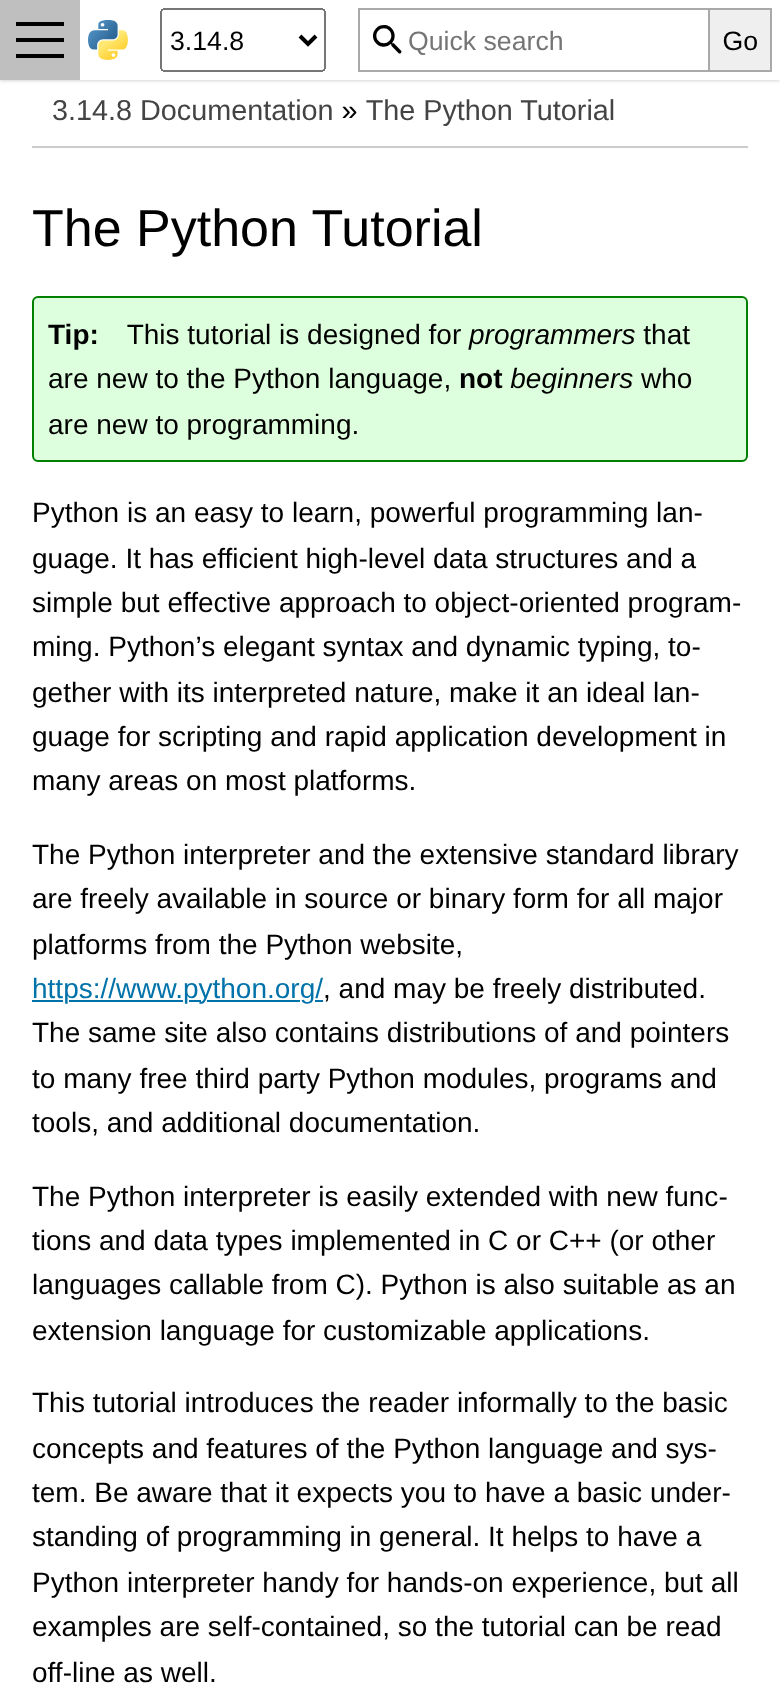
The returned image is 780 × 1688 pixels. Click it to open the full-size PNG.
The result row reports ok: true, problems: [] and httpStatus: 200.
Saved input · Actual dataset JSON
Mobile uses a 390 × 844 CSS-pixel viewport at 2× pixel density.
Desktop: full page
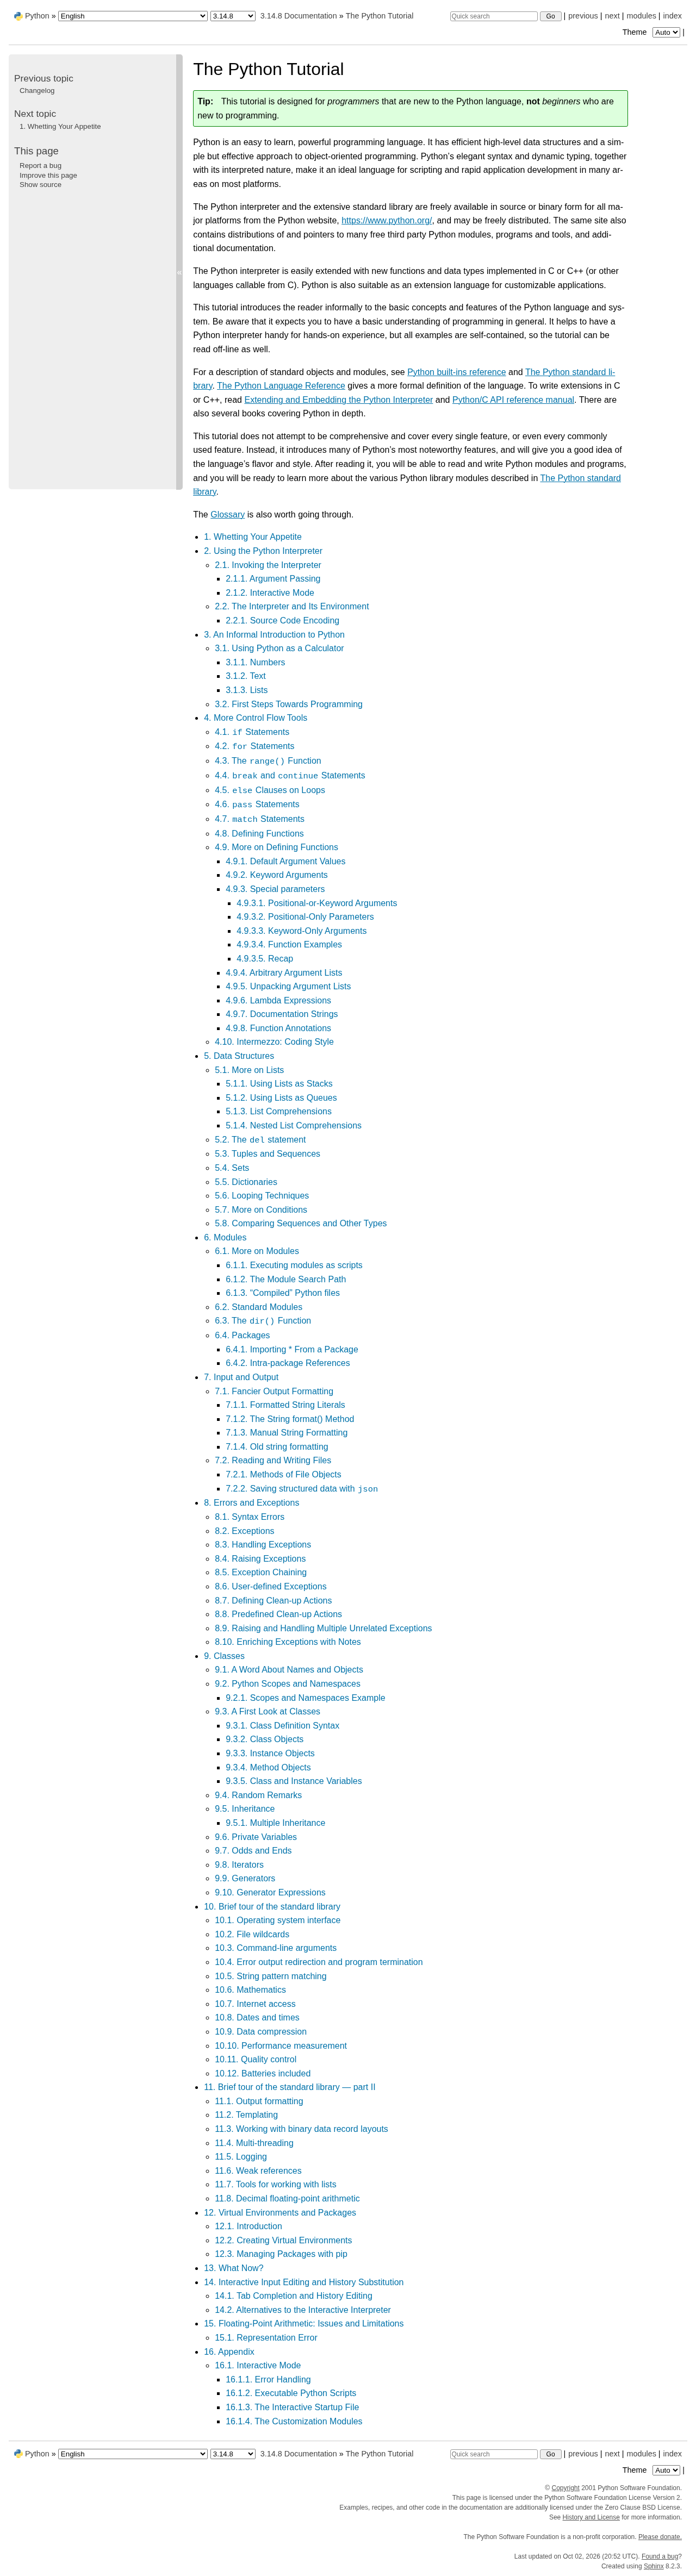
The returned image is 1280 × 4739 pixels. Click it to open the full-size PNG.
The result row reports ok: true, problems: [] and httpStatus: 200.
Saved input · Actual dataset JSON
A missing page is flagged
The second URL in the desktop input returns HTTP 404. The actor still saves its image
and returns a row with ok: false. These fields are copied from that row:
Open the 404 screenshot · Read the complete row in the dataset
Python documentation © Python Software Foundation, under the PSF License. These captures do not imply endorsement by the Python Software Foundation.
What it does
For each URL you give it, the actor loads the page once in a headless Chromium browser, optionally hides cookie banners, takes the screenshot, saves it in the run's key-value store and writes one dataset row with the result of these checks:
http_error
The page answered with an HTTP status of 400 or more (404, 429, 500 …).
blank_image
The image is almost one colour (a white or still-loading page).
bot_check_page
The page shows a bot check or challenge ("Just a moment…", "Verify you are human", captcha). It is reported, never bypassed.
height_cut
The image may be missing the bottom of what you asked for. In full-page or element mode the image is shorter than the page (or element): it is taller than your maximum height, or the capture timed out and the top half was kept instead. Capture-height images (clipHeight 2,000 or more, on a page at least that tall) get the same flag when that timeout retry cuts them short.
selector_not_found
Element mode: no shown element matched your CSS selector within the wait. No image is saved. Elements smaller than 4×4 px are skipped, so a heading that exists only as a 1-pixel screen-reader-only copy counts as not found.
load_timeout_partial
The page had not finished loading after 30 s; the screenshot shows what was there.
load_error
The page could not be loaded at all (DNS error, refused connection, TLS error …).
network_request_refused
The page itself was not loaded: its host kept answering 429/503 or failing to connect, or the visit reached its 500-request allowance first. No screenshot is saved and the row is free.
robots_txt_disallowed
The site's robots.txt disallows the page (or the page it redirected to), so no screenshot was taken.
robots_txt_unreachable
The site's robots.txt could not be fetched (timeout, network error or server error), so the page was treated as disallowed and not loaded.
Optional resources beyond the 500-request allowance, or from a failing host, are blocked while the screenshot continues. The row’s blockedResources count shows how many were refused; images, embedded frames or other content may be missing even when ok is true.
A row with ok: true has no problems detected by these checks. Rows with problems are still
returned. URLs skipped after the run reaches its maximum cost do not get a row.
Full page that is really full. In full-page mode the actor scrolls down the page one screen at a
time so lazy-loaded images and sections appear, returns to the top, then captures the whole height up
to your maximum (default 15,000 px, up to 30,000 px). Longer pages are cut and flagged height_cut.
A tall capture is given more time than a first screen (up to 90 seconds); if it still times out, the
actor keeps the top half of the page and flags the row height_cut, so you get an image rather than
nothing.
Just the part you need. Set a capture height (clipHeight) to get the top N pixels of the page,
more than one screen if you like; give a CSS selector (selector) to get one element, such as a
pricing table, a chart or the footer (the first matching element that is shown and at least 4×4
pixels); list CSS selectors in hideSelectors to hide chat widgets, promo bars or ads first. Headers
that stay fixed or sticky while you scroll appear once, at the top, in full-page and tall captures.
Cookie banners hidden, never accepted. With "Hide common cookie banners" on (the default), the
actor hides the banners of common consent tools (OneTrust, Cookiebot, Usercentrics, Didomi, Quantcast
and others) and banners it recognises by their text: a banner-like element that mentions cookies or
consent and has an accept/reject-style button. Nothing is clicked, accepted or rejected. It does not
catch every banner; cookieBannersHidden in each row says how many elements were hidden.
Input
| Field | Default | |
|---|---|---|
urls | - | Pages to capture, one per line. Also accepted: startUrls (strings or {"url": …} objects), url, domains. A missing https:// is added. |
fullPage | false | Whole scrollable page instead of the first screen. |
maxHeight | 15000 | Full-page cut-off in pixels (500–30,000). |
device | desktop | desktop (1280×800) or mobile (390×844 at 2× pixel density, iPhone user agent). |
viewportWidth, viewportHeight | device size | Optional window size in CSS pixels (width 240–3,840, height 240–4,320); overrides the device's. Mobile images are twice this in pixels. width is accepted for the width. |
clipHeight | - | Optional: capture only the top N CSS pixels (100–30,000). Shorter pages give a shorter image. Overrides fullPage. |
selector | - | Optional CSS selector: capture only the first shown element that matches (at least 4×4 px). Overrides fullPage and clipHeight. An invalid selector stops the run before any page is loaded. |
selectorTimeoutSecs | 10 | How long to wait for that element after the page has loaded (1–60 s). |
hideSelectors | - | Optional list of CSS selectors; matching elements are hidden (display: none) before capturing. Also accepted: selectorsToHide. |
format | png | png or jpeg (quality 80). |
delaySecs | 1 | Extra wait after the page's load event, for late content (0–30 s). |
hideCookieBanners | true | Hide cookie banners as described above. |
respectRobotsTxt | true | Skip pages the site's robots.txt disallows (also checked after redirects; an unreachable robots.txt counts as disallowed). |
concurrency | 3 | Pages loaded at once in one browser (1–8). |
Example:
Output
One dataset row per attempted URL. Here are fields from the successful desktop result shown above (the linked dataset contains the complete row):
New runs also include blockedResources (an integer, zero when none were refused) and
disabledTransports (the names of disabled transports the page attempted to use, or an empty list).
The saved example above is from build 0.3.7 and predates these fields. blockedResources counts
optional HTTP requests refused by the visit allowance or host distress guard, not every browser
load failure. A positive count warns that the image may be incomplete; it does not by itself
change ok or charging. disabledTransports is information only and does not change ok or charging.
Content that needs a worker, WebSocket, WebRTC connection, WebTransport connection or popup
may be missing. This field lists attempted disabled JavaScript APIs, including window.open;
anchor and form popups are also blocked, but are not listed in this field.
The capture field is "viewport" (first-screen, the default), "fullPage", "clip" (clipHeight
was set), or "element" (selector was set), identifying which mode was used.
The screenshot files are in the run's key-value store, and a run summary (counts per problem) is in
its OUTPUT record. The dataset's "Screenshots" view shows the images inline.
Measured on our test runs (2026-09-26, 1 GB memory)
- 20 well-known public sites, first screen: 17 OK; the 3 others were correctly flagged (an HTTP 429 blank page, a 30 s load timeout, a deliberate 404). Median page time 4.2 s.
- 5 public sites, full page (2,078 to 4,550 px tall): 5 OK in 13 s of work; the GOV.UK cookie banner was hidden.
- 1 URL: 2.5 s of work, 5.5 s run time.
These are our runs, not a guarantee: speed depends on the sites you capture.
Pricing
Pay per event: US$0.0015 per screenshot without problems (screenshot, rows with ok true), plus a
start fee of US$0.00005 per GB of run memory, charged once per run (US$0.00005 at the default 1 GB).
Rows with problems (ok false) are not charged. There is no extra charge for Apify platform usage.
Apify shows the price before you run, and you can set a maximum cost per run: once it is reached,
the remaining URLs are skipped and get no row.
Limitations
- No proxies, logins or cookies you supply: pages are captured as an anonymous visitor from Apify's
servers. Sites that block data-centre traffic show up as
http_errororbot_check_page. - Bot checks and captchas are never solved or bypassed, and robots.txt is respected by default.
- The checks are heuristics: a page that is mostly one colour on purpose may be flagged
blank_image, and an unusual bot-check page may not be recognised. - The text-based pass may occasionally hide a page element that isn't a banner but mentions cookies; turn the option off if something is missing.
- Cookie banners are hidden, not dismissed: some sites also dim or lock the page behind the banner, and some banners are not recognised.
- Hidden elements (
hideSelectors, cookie banners) change the page: the image is then not an exact record of what a visitor sees. - Element capture uses CSS selectors only (no XPath or text matching) and does not look inside iframes. Elements under 4×4 px are skipped, so text that is only there for screen readers is not captured.
- Only Chromium. Pages are loaded once each. If a screenshot of a very tall page times out, the actor
retries it once at half the height and flags the row
height_cut.
Use with AI agents
Call it with just a list of URLs: {"urls": ["https://example.com/"]}. Read the dataset items; use
ok and problems to decide which screenshots to trust, and screenshotUrl to fetch each image.
Your responsibility
You choose which pages are captured. Make sure your use of the screenshots respects the sites' terms and any rights in their content; screenshots can contain personal data shown on the page. The actor itself collects nothing beyond what the run stores in your own Apify storage.
Changes
-
0.5: malformed URLs return a free
load_errorrow and the batch continues. Capture slots reserve the remaining screenshot event budget before fetching, including concurrent captures. -
0.4: browser startup uses a fresh full-Chromium profile with network prediction disabled. Popup targets are paused before they are closed.
-
0.3.6: a very tall, heavy full-page capture that used to time out at a flat 30 seconds (losing the row entirely) now gets a budget that scales with the capture height, up to 90 seconds, and is retried once at half the height (flagged
height_cut) if it still times out. Element capture now correctly reportsselector_not_foundfor an element that exists only as a screen-reader-only copy under 4x4 px. -
0.3.4: first public release of region capture (clip height, element selectors, elements to hide, custom viewport).
Built and maintained with AI agents by Madrasco.
Support
Open an issue in the actor's Issues tab. Replies are written with AI assistance; the human owner can be reached on request.


