
PanoramaFirm.pl Scraper
Pricing
from $5.00 / 1,000 listings
PanoramaFirm.pl Scraper
Scrape panoramafirm.pl (Poland business directory) into structured company rows: name, phone, email when listed, website, address, NIP, hours, rating. Keyword plus city, nationwide category, or a Panorama Firm search or profile URL. HTTP only. JSON or CSV out. $5 per 1,000 listings.
Pricing
from $5.00 / 1,000 listings
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Turn a Panorama Firm search into structured Polish company rows: name, phone, email when listed, website, address, NIP, hours, rating, and profile link.
Keyword + city, nationwide category, or a panoramafirm.pl URL. JSON or CSV out.
This is panoramafirm.pl (WeNet / Panorama Firm). It is not PagineGialle, PaginasAmarillas.es, or Herold.at.
Why Use This Scraper?
- Phone and email on many search cards (JSON-LD)
- Profile pass for NIP, weekday hours, website, and reviews
- Pagination via
?page=2on/szukaj - HTTP only. No browser
Overview
Built for sales teams, agencies, and researchers who need Polish company leads from Panorama Firm.
Every start type becomes one dataset row per listing. A keyword search and a profile URL emit the same flat shape. Rows are de-duplicated by profile slug.
Supported Inputs
Search terms and locations
| Field | Example |
|---|---|
searchTerms | ["restauracja"], ["hydraulik", "fryzjer"] |
locations | ["Warszawa"], ["Kraków"], ["pomorskie"] |
Every term is searched in every location. Leave locations empty for a nationwide category search.
URL types
| URL type | Pattern | Example |
|---|---|---|
| Search | /szukaj?what=&where= | https://panoramafirm.pl/szukaj?what=restauracja&where=Warszawa |
| Pretty search | /{what}/{region},,{city} | https://panoramafirm.pl/restauracja/mazowieckie,,warszawa |
| Search page | /szukaj?...&page=N or /firmy,N.html | https://panoramafirm.pl/restauracja/mazowieckie,,warszawa/firmy,2.html |
| Profile | /{address-slug}/{company-slug}.html | https://panoramafirm.pl/mazowieckie,,warszawa,mokotów,postępu,14/wenet_sp._z_o.o.-sjdkw_aka.html |
Search URLs paginate automatically.
Unsupported: firma.panoramafirm.pl account pages, Panorama Danych data-sales pages, article URLs under /artykuly/.
Use Cases
| Audience | What they take from a run |
|---|---|
| Sales and outreach | Phone + email (when listed) + website by trade and city |
| Agencies | Cross-joined term × city lists in one dataset |
| Local SEO | Category, rating, and the Panorama Firm profile URL |
| Researchers | NIP, hours, and reviews for a trade in a city |
How It Works
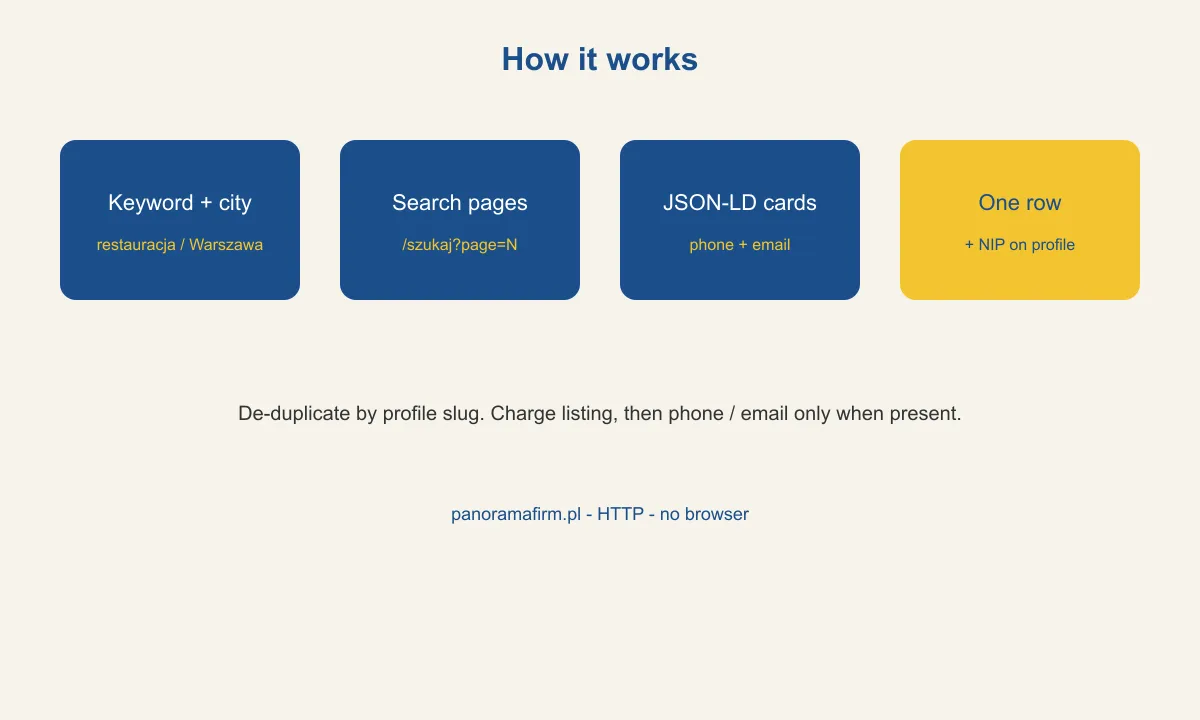
- Cross-join
searchTerms×locations(or nationwide if no city), plus any panoramafirm.pl URLs. - Fetch the search page.
- Page with
?page=Nin parallel, stopping atmaxItemsormaxPages. - Read name, phone, email, and address from the search JSON-LD.
- Optionally open the profile for NIP, hours, website, and reviews.
- De-duplicate by listing id and push one row per company.
Input Configuration
| Field | Type | Required | Notes |
|---|---|---|---|
searchTerms | array | one of the start types | What you would type into Panorama Firm |
locations | array | no | Polish city / region. Empty = nationwide |
startUrls | array | one of the start types | Search or profile URL |
maxItems | integer | no | Default 50. Free users capped at 50. |
scrapeDetails | boolean | no | Default true. NIP, hours, website, reviews. |
maxPages | integer | no | Default 20. |
maxConcurrency | integer | no | Default 5. |
proxy | object | no | Default is Apify datacenter. |
Example input
Output Overview
One flat row per company. Contact and address fields sit at the top level. searchTerm tells you which input produced the row. Email is present when Panorama Firm publishes one on the card or the profile.
Output Samples
Search: restauracja in Warszawa, with profile enrich.
Key Output Fields
Identity: listingId, slug, name, panoramaFirmUrl
Contact: phone, phones, email, website, social
Place: address, street, postalCode, city, region, country, latitude, longitude
Company: taxId (NIP)
Directory: category, categories, rating, reviewCount, hours, description, images, logo, reviews
Provenance: searchTerm, scrapedAt
Pricing
| Event | When | Rate |
|---|---|---|
| Actor start | Once per run, per GB of memory | $0.005 |
| Listing | Each unique company in the dataset | $0.005 ($5 / 1k) |
| Contact phone | Row has a phone | $0.002 |
| Contact email | Row has an email | $0.05 |
Phone and email are billed only when Panorama Firm publishes that field. A miss is free. Many cards already include both, so scrapeDetails is for NIP, hours, and website.
FAQ
Will every row have an email? No. Phone is common. Inbox is on a large share of search cards, not all. Phone and email are billed as extra events only when the field is present.
What does scrapeDetails add? NIP, weekday hours, website, and reviews. Phone and email are already on many search cards.
Do I need a proxy? Datacenter is the default and is enough on a normal day. Switch to residential if a run comes back empty.
Is there an official Android app? No live Play listing. Leads come from the website.
Support
- Issues: Actor Issues
- Author site: https://muhamed-didovic.github.io/
- Email: muhamed.didovic@gmail.com
Additional Services
Bulk województwo sweeps, scheduled refreshes, or a private API wrapper: muhamed.didovic@gmail.com
Explore More Scrapers
Directory cousins: PaginasAmarillas.es, Herold.at, PagineGialle, local.ch, Gelbe Seiten, Yellow Pages US, Yellow Pages Canada, Canada411, and PagesJaunes.fr. More actors on memo23 and didovic.
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/panoramafirm-scraper).
Purpose: Extract PanoramaFirm.pl company listings (name, phone, email when listed, website, NIP, split address, hours) by keyword + city or URL.
Minimal input:
Output: one dataset row per company — listingId, slug, name, phone, phones, email, website, taxId, social, address, street, postalCode, city, region, country, latitude, longitude, category, categories, rating, reviewCount, hours, description, images, logo, reviews, panoramaFirmUrl, searchTerm, scrapedAt.
Behaviors an agent should know:
- Always set
maxItems. Free users are capped at 50. searchTermswithoutlocationsruns a nationwide category search.startUrlswork on their own (panoramafirm.pl only).- Email is often already on the search card. Keep
scrapeDetailstrue for NIP and hours. - Each listing is $0.005. A phone on the row is $0.002. An email is $0.05. Start is $0.005 per GB.
- Poland company directory only.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Panorama Firm Sp. z o.o., WeNet, or panoramafirm.pl. All trademarks mentioned are the property of their respective owners.
The scraper reads publicly listed Polish company data from panoramafirm.pl. Users are responsible for ensuring their use complies with Panorama Firm Terms of Service, applicable data-protection law (GDPR / RODO), and any contractual obligations of their own organization.
SEO Keywords
panoramafirm scraper, panoramafirm.pl scraper, scrape panoramafirm.pl, Polish business directory scraper, Poland yellow pages scraper, panorama firm API, Polish company listings scraper, Poland phone email scraper, Warszawa leads scraper, Apify panoramafirm, Polish restaurant leads, Kraków business scraper, NIP scraper, Polish directory scraper


