
Semrush Scraper — Traffic, Backlinks, Keyword Ideas & Top Sites
Pricing
from $5.00 / 1,000 results
Semrush Scraper — Traffic, Backlinks, Keyword Ideas & Top Sites
Turn any domain into structured Semrush SEO data — Authority Score, traffic, global/country/category ranks, backlinks, referring domains, top keywords and AI-search traffic. Also: top websites by country + industry, and keyword ideas from any seed. No Semrush seat or API key.
Pricing
from $5.00 / 1,000 results
Rating
3.6
(5)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
104
Total users
24
Monthly active users
5 days ago
Last modified
Share
Semrush Scraper
Turn any domain into structured Semrush website-overview data — Authority Score, traffic estimates, global/country/category ranks, backlinks, referring domains, top competitors, top organic keywords, and even AI/LLM traffic. Paste one domain or a thousand; each returns a single clean, export-ready row.
Two modes in one Actor: Domain overview (look up any list of domains) and Top websites (the ranked leaders for a country + industry, with traffic and month/year growth).
No Semrush seat, no API key, no login. This Actor reads Semrush's own public website-overview pages and hands you the numbers as JSON, CSV, or Excel.
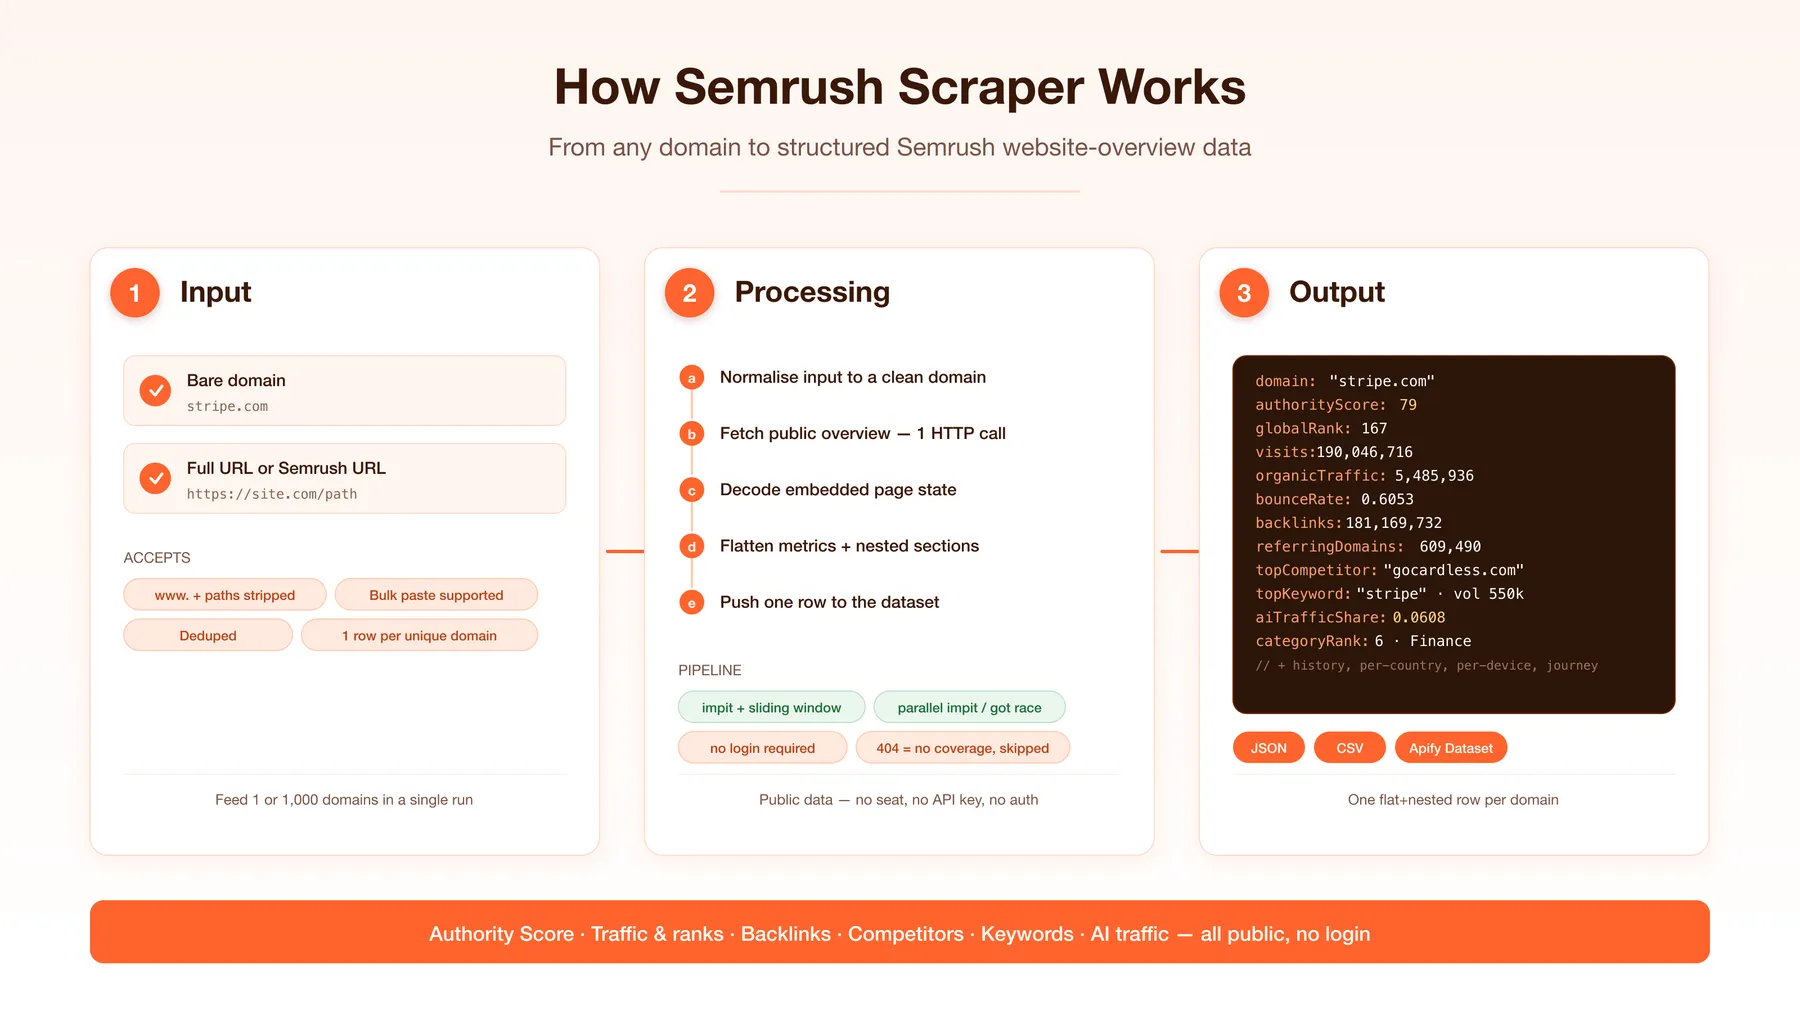
How it works
✨ Why use this scraper?
- Full domain overview in one row — Authority Score, traffic, ranks, backlinks, engagement, competitors, keywords and AI traffic, flattened into table-friendly columns plus nested detail.
- Bulk by design — feed 1 or 1,000 domains in a single run; results stream in parallel, one row per domain.
- No Semrush account needed — reads only public website-overview data, so there is no seat cost, API quota, or login to manage.
- AI-search visibility included — see how much traffic ChatGPT, Gemini, Grok and other LLMs send to a domain.
- Flexible input — bare domains, full site URLs, or Semrush overview URLs all work;
www.and paths are stripped automatically. - Export anywhere — JSON, CSV, Excel, XML or the Apify API, straight out of the dataset.
🎯 Use cases
| Audience | What they get |
|---|---|
| SEO specialists & agencies | Bulk Authority Score, traffic and backlink profiles for a whole client roster without buying extra Semrush seats. |
| Competitive analysts | Top organic + paid competitors per domain, with estimated visits and relevance, to map a market. |
| Content & keyword teams | Top organic keywords with search volume, CPC, position and decoded intent for any domain. |
| AI / LLM researchers | Per-LLM traffic share (ChatGPT, Gemini, Grok…) to track which brands AI assistants send traffic to. |
| Growth & BD teams | Traffic, rank and engagement signals to qualify prospects, partners or acquisition targets at scale. |
| Data teams & dashboards | Monthly history arrays and per-country/per-device splits to feed BI tools and trend charts. |
📥 Supported inputs
Mode 1 — Domain overview (mode: "domains"): supply a list of domains.
| Input form | Example | Result |
|---|---|---|
| Bare domain | stripe.com | Overview for stripe.com |
| Full site URL | https://stripe.com/pricing | Host extracted → stripe.com |
| Subdomain / path | blog.hubspot.com/marketing | Host extracted → blog.hubspot.com |
| Semrush overview URL | https://www.semrush.com/website/stripe.com/overview/ | Domain parsed out → stripe.com |
| Email address | sales@stripe.com | Domain after the @ → stripe.com |
Mode 2 — Top websites (mode: "top_websites"): supply a country + industry and get the ranked leaders.
| Field | Example | Result |
|---|---|---|
| Country | us or united-states | Ranking scoped to that country |
| Industry | finance, retail, all | Ranking scoped to that industry |
| Limit | 100 | Top N domains (max 100) |
| Enrich | true | Each ranked domain also gets a full overview scrape |
Mode 3 — Keyword ideas (mode: "keywords"): supply seed phrases and get related keyword suggestions.
| Field | Example | Result |
|---|---|---|
| Seeds | coffee, running shoes | Related keyword phrases per seed |
| Expansion | full | Seed + a–z suffixes + question prefixes (47 queries/seed) |
| Max per seed | 500 | Cap on unique ideas kept |
| Flatten | false | One row per seed (default) vs one row per keyword |
Keyword ideas returns phrases only. Search volume, keyword difficulty, CPC and intent are served by Semrush exclusively to logged-in accounts, so this mode omits them rather than returning empty columns. Yield depends on how broad the seed is:
coffeeexpands to ~228 ideas,running shoesto ~75, and a narrow phrase likeseo toolsto almost none.
Not supported: keyword metrics (volume/CPC/difficulty for a bare keyword), per-country keyword databases, individual backlink rows, position-tracking projects, or anything else Semrush gates behind a logged-in seat. Domains with no Semrush coverage return no row (they are logged and skipped, never billed), unless Moz metrics are on and Moz has data for them.
🔄 How it works
- Normalise each input into a clean registrable domain (strip scheme,
www., path, query; dedupe). - Fetch the domain's public Semrush overview page — a single HTTP request per domain, run in parallel with a global sliding window.
- Decode the metrics embedded in the page's rendered state.
- Flatten the headline KPIs into table columns and keep the rich sections (history, per-country, per-device, journey, competitors, keywords, AI traffic) as nested fields.
- Push exactly one row per domain to the dataset. A domain Semrush has no data for is skipped with a clear log line.
⚙️ Input parameters
| Field | Type | Default | Description |
|---|---|---|---|
mode | string | domains | domains (look up domains), top_websites (ranking by country + industry) or keywords (expand seed phrases). |
domains | array | ["stripe.com", …] | (domains mode) Domains or URLs to analyse. One row per unique domain. |
topWebsitesCountry | string | us | (top websites) 2-letter code (us, gb) or full slug (united-states). |
topWebsitesIndustry | string | all | (top websites) Industry slug (all, finance, retail, news…). |
topWebsitesLimit | integer | 100 | (top websites) How many ranked domains to return (1–100). |
enrichTopWebsites | boolean | false | (top websites) Also run a full overview scrape per ranked domain. |
seeds | array | ["coffee", …] | (keywords mode) Seed phrases to expand. Broad head terms yield far more than long-tail ones. |
keywordExpansion | string | full | (keywords) none (1 query), letters (27), questions (21) or full (47) queries per seed. |
maxKeywordsPerSeed | integer | 500 | (keywords) Cap on unique ideas kept per seed. |
flattenKeywords | boolean | false | (keywords) One row per keyword instead of one per seed. Multiplies billed results. |
includeHistory | boolean | true | Month-by-month history for visits, organic/paid, backlinks, referring domains. |
includeTrafficByCountry | boolean | true | Per-country traffic with device split and share. |
includeTrafficByDevice | boolean | true | Desktop vs mobile visit history. |
includeTrafficJourney | boolean | true | Inbound / outbound referral hosts. |
includeCompetitors | boolean | true | Top organic + paid competitor domains. |
includeKeywords | boolean | true | Top organic keywords (volume, CPC, position, intent). |
includeAiTraffic | boolean | true | AI / LLM traffic sources and share. |
includeSiteAudit | boolean | false | Crawl the homepage: title, meta description, H1s, word count, links, missing alts, robots.txt, sitemap. One extra request per domain. |
includeMoz | boolean | false | Moz Domain Authority, Spam Score, linking root domains, ranking keywords, top pages, top linking domains, 60-day links gained/lost. One extra request per domain. |
includeDomainAge | boolean | false | Registration and expiry date, age in years and registrar, from RDAP. One extra request per domain. |
minVisits / maxVisits | integer | 0 | (filter) Keep only sites inside this monthly-visits range. 0 = no limit. |
minAuthorityScore / maxAuthorityScore | integer | 0 | (filter) Keep only sites inside this Authority Score range. |
filterCountries | array | [] | (filter) 2-letter codes matched against the site's main audience country. |
filterCategories | array | [] | (filter) Words matched against the site's Semrush categories. |
onlyWithTrafficEstimate | boolean | false | (filter) Drop sites whose newest month has no visits estimate yet. |
monthsOfHistory | integer | 0 | Keep only the N most recent months in each history list. 0 = all. |
countriesPerDomain / keywordsPerDomain / competitorsPerDomain | integer | 0 | Trim those nested lists. 0 = all. |
maxItems | integer | 1000 | Hard cap on domains processed per run. |
maxConcurrency | integer | 10 | Domains fetched in parallel. |
proxy | object | Apify Proxy (default group) | Proxy used to reach Semrush. The default works — no residential add-on needed. |
The
include*toggles trim the output only — every section arrives in the same single request, so turning them off does not change the price. Use them to keep rows lean when you only need headline KPIs.
📊 Output overview
Each dataset row is one domain. The top of the row is a flat block of headline KPIs (Authority Score, ranks, visits, organic/paid traffic, engagement, backlinks, device split, top competitor, AI traffic share) that render as plain columns in the Apify table view. Below that sit the nested detail sections — monthly history, per-country and per-device breakdowns, the traffic journey, the full competitor list, top keywords, and AI-traffic sources — each gated by its include* toggle.
📦 Output sample
🗂 Key output fields
| Field | Type | Description |
|---|---|---|
| Identity | ||
domain | string | Registrable domain the row describes. |
country | string | Primary country for the traffic data. |
categories | string[] | Semrush business categories for the domain. |
dataMonth / dateModified | string | Reference month of the data / date Semrush last updated it. |
| Authority & rank | ||
authorityScore | number | Semrush Authority Score (0–100). |
googlePenaltyRisk | string | Backlink penalty-risk label (e.g. Low). |
globalRank / countryRank / categoryRank | number | Semrush traffic ranks. |
categoryRankName | string | The category the categoryRank applies to. |
| Traffic & engagement | ||
visits / visitsChange | number | Monthly visits and month-over-month change. |
organicTraffic / paidTraffic | number | Estimated organic and paid search traffic. |
bounceRate / pagesPerVisit / avgVisitDurationSec | number | Engagement metrics. |
desktopShare / mobileShare | number | Device split of visits. |
topCountry / topCountryTraffic | string / number | Largest traffic country and its volume. |
| Backlinks | ||
backlinks / referringDomains | number | Total backlinks and unique referring domains. |
| Competition & keywords | ||
competitorsCount / topCompetitor | number / string | Competitor count and the closest one. |
competitors[] | object[] | Competitor domains with relevance + estimated visits. |
topKeywords[] | object[] | Top organic keywords: volume, CPC, position, intent, traffic share. |
| AI traffic | ||
aiTrafficShare | number | Combined share of traffic from AI/LLM sources. |
hasTrafficEstimate | boolean | False when Semrush has not published a visits figure for the newest month yet (Authority Score, ranks and backlinks are still filled). |
semrushCoverage | boolean | False only on a Moz-only row: Semrush has no public page for the domain. |
mozDomainAuthority | number | Moz Domain Authority, 1-100 (includeMoz). |
mozSpamScore | number | Moz Spam Score, 0-100; empty when Moz shows none (includeMoz). |
mozLinkingRootDomains | number | Moz linking root domains, approximate (includeMoz). |
domainCreatedAt / domainAgeYears | string / number | Registration date and age from RDAP (includeDomainAge). |
domainExpiresAt / registrar | string | Expiry date and registrar from RDAP (includeDomainAge). |
trafficAi[] | object[] | Per-LLM traffic (ChatGPT, Gemini, Grok…) with share and history. |
| History & breakdowns | ||
visitsHistory / searchTrafficHistory / backlinksHistory / referringDomainsHistory | object[] | Monthly time series. |
trafficByCountry[] | object[] | Per-country traffic with device split. |
trafficByDeviceHistory[] | object[] | Desktop vs mobile visits over time. |
trafficJourney | object | Inbound and outbound referral hosts. |
scrapedAt | string | ISO timestamp of the scrape. |
🏆 Top Websites output
In top_websites mode each row is one ranked domain. With enrichTopWebsites off (default), rows are lightweight ranking records; with it on, each row is a full domain-overview (as above) plus rank, industry and rankingCountry.
| Field | Type | Description |
|---|---|---|
rank | number | Position in the country × industry ranking (1 = highest traffic). |
domain | string | The ranked domain. |
totalTraffic | number | Estimated monthly visits. |
desktopTraffic / mobileTraffic | number | Device-split visit estimates. |
desktopShare / mobileShare | number | Device split as a 0–1 fraction. |
momChange / yoyChange | number | Month-over-month and year-over-year change (0–1 fraction, can be negative). |
topSource | string | Largest traffic source (e.g. direct, search). |
❓ FAQ
Do I need a Semrush subscription or API key? No. This Actor reads Semrush's public website-overview pages, so there is nothing to log into and no API quota to manage.
How accurate are the numbers?
They are Semrush's own publicly published estimates for each domain — the same figures shown on the public overview page. They are modelled traffic estimates, not server-side analytics, and update roughly monthly (dataMonth tells you the reference period).
What happens for a domain Semrush doesn't cover?
Semrush returns a 404 for domains it has no public overview page. With default settings the Actor logs it and moves on: no row is pushed and you are not billed for it. At the end of the run you get a summary line in the run status message plus a COVERAGE_REPORT record in the key-value store listing exactly which domains had no coverage.
With includeMoz on, the Actor also asks Moz about those domains. Moz covers many sites Semrush's public pages don't (webflow.com, zapier.com and apify.com all 404 on Semrush but have Moz profiles). When Moz has data you get a row with semrushCoverage: false, the Moz columns filled in and every Semrush column empty. That row is billed as one result, because it carries real data.
Where do the Moz numbers come from?
Moz's free Domain Authority checker, the same page you can open at moz.com/domain-analysis?site=example.com. mozDomainAuthority, mozSpamScore and mozLinkingRootDomains are flat columns for spreadsheets; the full block (top pages with Page Authority, top linking domains, links gained and lost over 60 days) is in moz. Moz rounds large counts on that page ("606.4k"), so mozLinkingRootDomains is approximate. If Moz blocks a lookup three times in a row, the row is kept and its Moz fields are left empty.
How do the filters work, and do filtered domains cost anything?
Filtered-out domains are never added to the dataset, so they are never billed. They are listed with the reason in COVERAGE_REPORT. A domain with no value for a field you filter on is dropped: a site with no visits estimate can't be shown to have "at least 10,000 visits". Use maxVisits and maxAuthorityScore to find sites small enough to approach, filterCountries and filterCategories to narrow a lead list to one market.
Why is domain age empty for some domains?
Age comes from RDAP, the public registry service that replaced WHOIS. A few country domains publish no RDAP data at all (.so is one, so notion.so comes back empty). Subdomains are looked up on their registered parent: blog.hubspot.com returns the age of hubspot.com.
I ran N domains and got fewer rows (or none). Is the Actor broken?
Almost certainly not — it's Semrush coverage. Semrush publishes free overview pages for a subset of domains only, and the subset is narrower than people expect: household names are nearly always there, but plenty of well-known sites (for example webflow.com, zapier.com, apify.com) return a 404 with no public data at all. Check any domain yourself before blaming the Actor:
If that page 404s in your own browser, the data does not exist publicly and no scraper can return it. Domains that do load in the browser will scrape reliably — if one doesn't, that's a bug worth reporting on the Issues tab.
Can I get keyword volume for a keyword that isn't tied to a domain?
No, and no public scraper can. Semrush serves keyword metrics from POST /kwogw/v2/webapi, which answers an anonymous caller with Operation forbidden for user and reports a quota of zero — volume, difficulty, CPC and intent need a logged-in Semrush seat. What this Actor does give you: keywords mode returns related keyword phrases for any seed (no metrics), and every domain overview row carries that domain's top organic keywords with volume, CPC, position and intent.
How many keyword ideas will one seed produce?
It tracks how broad the seed is, because the source is Semrush's own autocomplete and it caps every response at 10 suggestions. Breadth comes from asking many prefixed variants: at full expansion the Actor sends 47 queries per seed. Measured yields: coffee → ~228 ideas, running shoes → ~75, seo tools → 1. If a seed returns nothing, the run says so explicitly and lists it in COVERAGE_REPORT.
Does keyword ideas mode charge per keyword?
No. By default one seed is one billed result no matter how many ideas come back, so a 228-idea expansion costs a single result. Turn on flattenKeywords only if you want a row per keyword, and note that it bills per row.
Why is competitors sometimes empty?
Semrush controls whether the competitors block is exposed on the public overview page, and it toggles this per data snapshot — some months it's fully populated, some months it's withheld (the page returns it hidden). When Semrush exposes it you get the full competitor list; when it doesn't, competitors is an empty array. Every other section (traffic, ranks, backlinks, keywords, AI traffic, per-country/device) is unaffected.
How do I get the top websites in my industry?
Set mode to top_websites, pick a topWebsitesCountry (e.g. us) and topWebsitesIndustry (e.g. finance, or all). You get up to 100 ranked domains with traffic, device split and month/year growth in a single request. Turn on enrichTopWebsites to also pull a full overview for each ranked domain.
Why is siteAudit empty?
The on-page SEO audit only has data when Semrush has already crawled the domain for a project. It is off by default; enable includeSiteAudit if you specifically want that block.
💬 Support
Found a domain that parses oddly or a field you'd like added? Open an issue on the Actor's Issues tab in the Apify Console and include the exact input you ran. Feature requests for extra fields are welcome.
🛠 Additional services
Need this wired into a pipeline, scheduled, or combined with other data sources? The same team builds custom scrapers and enrichment flows across job boards, marketplaces, real-estate, and SEO/analytics platforms — reach out via the Apify Store profile.
🔎 Explore more scrapers
Looking at the wider SEO/analytics stack? Compare domains across tools by pairing this with Similarweb, Ahrefs, Moz and Ubersuggest scrapers for a triangulated view of authority and traffic.
- Keyword Metrics — Google + Bing search volume, CPC, competition, top-of-page bids, keyword difficulty, search intent and ~93 months of history. 1,000 keywords per run at one flat price, or 20 seeds expanded into up to 20,000 keyword ideas across 111 countries and 46 languages. The standalone keyword research this Actor can't do.
- Ahrefs Scraper — Domain Rating, backlinks, keyword ideas and AI visibility, to cross-check Authority Score against a second vendor's model.
- Moz Scraper — Domain Authority, spam score and ranking keywords.
- Similarweb Scraper — website traffic, rank, visits and keywords, for a second traffic estimate per domain.
🤖 For AI Agents & LLM Apps
Compact reference for AI agents calling this actor via the Apify MCP server or the Apify API (actor: memo23/semrush-scraper).
Purpose: Reads public Semrush website-overview pages for any domain — one row per domain with Authority Score, ranks, traffic, backlinks, competitors, top keywords, and per-LLM AI traffic; a second mode ranks the top sites for a country + industry.
Minimal input:
Top-websites mode: { "mode": "top_websites", "topWebsitesCountry": "us", "topWebsitesIndustry": "finance", "topWebsitesLimit": 50 }
Output: one row per domain — type, domain, url, dataMonth, dateModified, country, categories, hasTrafficEstimate, semrushCoverage, authorityScore, googlePenaltyRisk, globalRank, countryRank, categoryRank, categoryRankName, visits, visitsChange, organicTraffic, paidTraffic, bounceRate, pagesPerVisit, avgVisitDurationSec, backlinks, referringDomains, desktopShare, mobileShare, topCountry, topCountryTraffic, competitorsCount, topCompetitor, aiTrafficShare, competitors[] {name, relevance, visits}, topKeywords[] {keyword, position, searchVolume, cpc, traffic}, trafficByCountry[], trafficAi[] {id, name, traffic {value, share}}, scrapedAt. Optional: mozDomainAuthority, mozSpamScore, mozLinkingRootDomains, moz {topPages[], topLinkingDomains[], linkingDomainsDiscovered60d, linkingDomainsLost60d} (includeMoz); domainCreatedAt, domainAgeYears, domainExpiresAt, registrar (includeDomainAge). Top-websites rows add rank, industry, totalTraffic, desktopTraffic, mobileTraffic, momChange, yoyChange, topSource.
Behaviors an agent should know:
- mode picks the flow: "domains" needs domains[]; "top_websites" needs topWebsitesCountry + topWebsitesIndustry (topWebsitesLimit 1-100).
- Always set maxItems — the domains-mode default cap is 1000.
- include* toggles only trim which sections appear in each row; every section is fetched in the same request, so disabling them does not change the price.
- enrichTopWebsites (default false) also runs a full overview scrape per ranked domain.
- Domains Semrush has no coverage for return a 404, are logged/skipped, and are never billed; standalone keyword research is not supported (login-gated).
- Pay-per-event billing — see the Pricing tab on the actor page.
⚠️ Disclaimer
This Actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Semrush Inc. or any of its subsidiaries or affiliates. "Semrush" and all related trademarks are the property of their respective owners.
The scraper accesses only publicly available Semrush website-overview pages — no authenticated endpoints, no paid-seat features, and no content behind a Semrush login. All metrics are Semrush's own publicly published estimates. Users are responsible for ensuring their use complies with Semrush's Terms of Service, applicable data-protection law (GDPR, CCPA, etc.), and any contractual obligations of their own organisation.
SEO Keywords
semrush scraper, scrape semrush, semrush api, semrush data export, apify semrush, website traffic scraper, domain authority score scraper, seo data scraper, backlink data scraper, referring domains scraper, competitor analysis scraper, organic keywords scraper, keyword volume cpc scraper, traffic analytics scraper, ai traffic scraper, chatgpt traffic scraper, domain overview api, bulk domain seo data, seo rank tracker data, top websites ranking scraper, trending websites scraper, top sites by industry, semrush alternative scraper, similarweb alternative scraper, marketing intelligence data


