
Twitch Scraper — Channels, Streams, Leads
Pricing
from $2.00 / 1,000 results
Twitch Scraper — Channels, Streams, Leads
Build Twitch influencer & sponsorship lists in minutes. Channel profiles with socials and contact emails, live streams by game, VODs, clips and schedules. Filter by follower band, live viewers or language, export creator leads as JSON, CSV or Excel. Keyless, no browser.
Pricing
from $2.00 / 1,000 results
Rating
0.0
(0)
Developer
Muhamed Didovic
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Twitch Scraper — Channels, Streams, Games, Clips & Leads
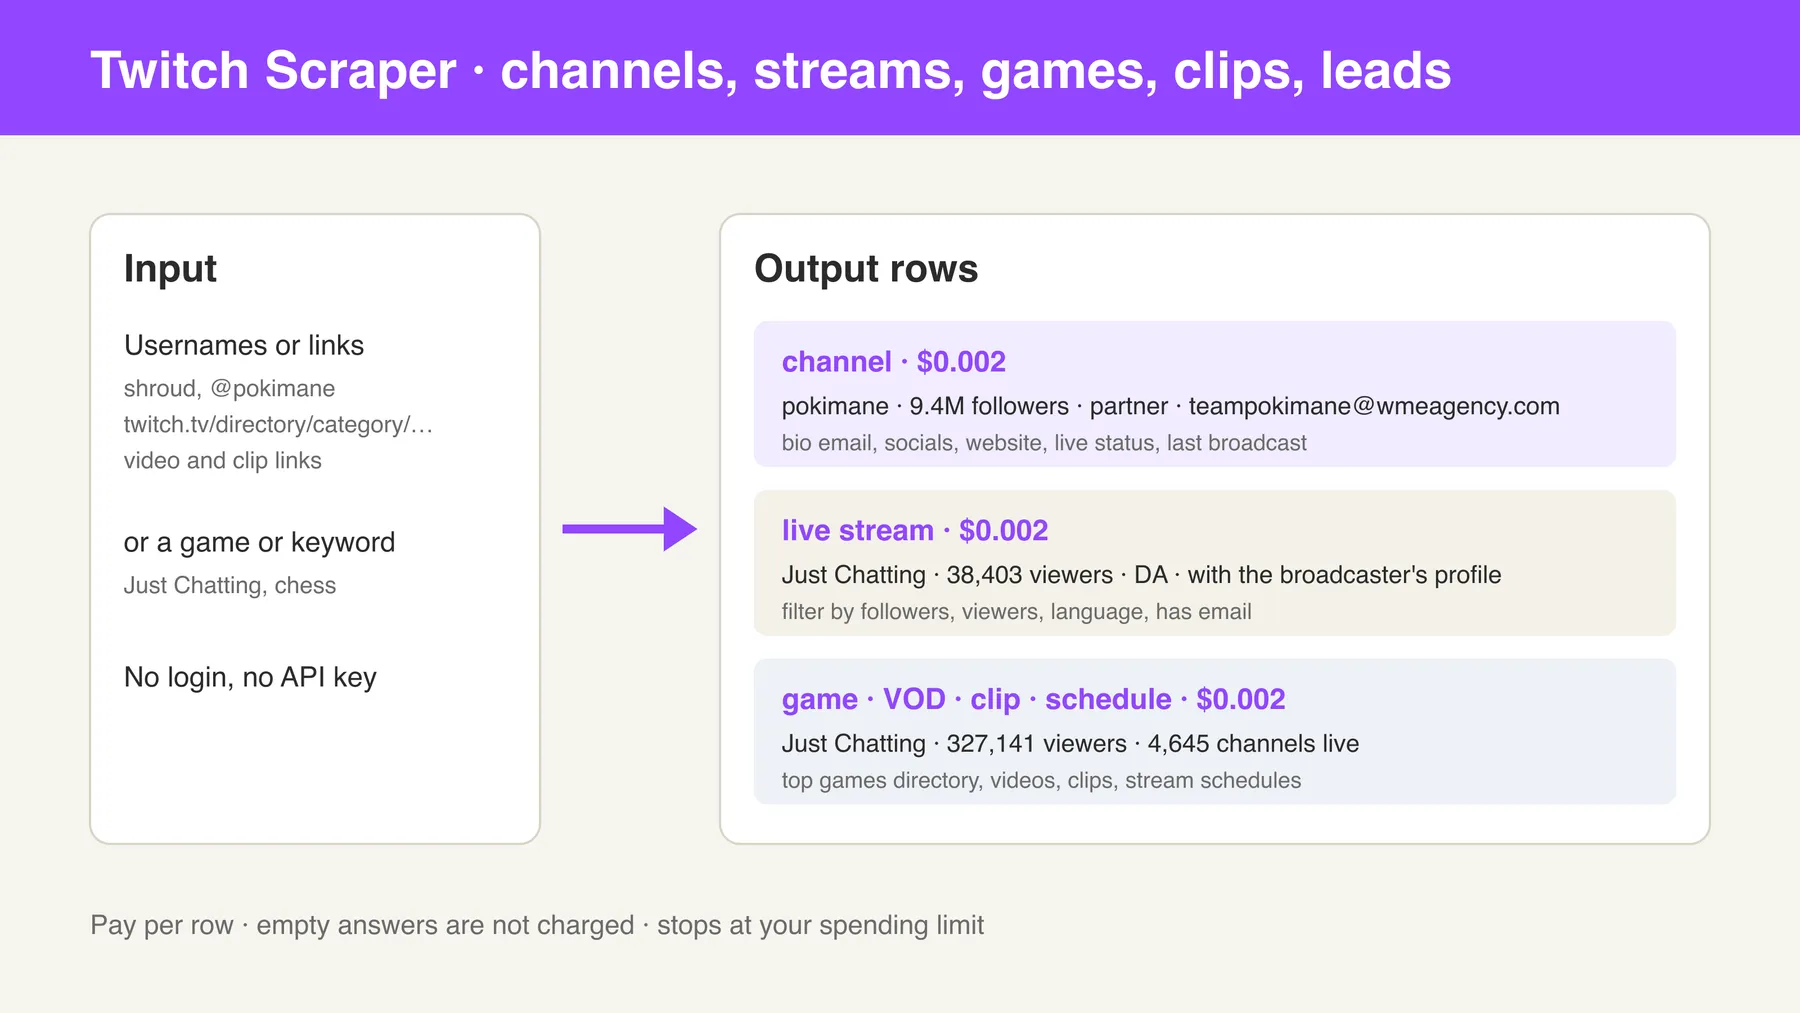
Turn any Twitch username, game, or search term into structured creator data — with socials and contact emails inline. Scrape full channel profiles, live streams by game, the top-games directory, VODs, clips, and stream schedules straight from Twitch's public GraphQL API. Every channel row carries follower counts, partner/affiliate status, live status, the streamer's social links, and the business email from their bio and panels — the lead-gen fields most Twitch scrapers skip. No browser, no login, no API key. JSON, CSV or Excel out, charged per result.
How it works
✨ Why use this scraper?
Building an influencer outreach list? Tracking who's live in your game category? Researching the streaming market, or monitoring a set of channels? Most Twitch actors give you follower counts and stop there — this one gives you the whole record and the way to reach the streamer.
- 🎯 8 modes, one actor. Channel profiles, keyword channel search, live streams by game, top streams, the top-games directory, VODs, clips, and published stream schedules — pick a mode, paste your targets.
- 📇 Socials + contact emails, built in. Every channel row includes the streamer's linked socials (YouTube, Instagram, X, TikTok, Discord…), their own website, and any business email parsed from their bio and channel panels — no separate "leads" actor needed.
- 🔍 Real lead-gen filters. Narrow discovery by follower band (min/max), live viewer band, broadcaster language, "has email", or "has socials" — find the exact tier of streamer you want to reach.
- 🌐 Keyless GraphQL, no browser. Talks to
gql.twitch.tvthe way the Twitch web app does — fast, light (runs at 256 MB), and reliable. No Playwright, no login, no cookies. - 📈 Deeper directory coverage. Game and top-stream directories fan out over sort and language partitions and dedupe broadcasters, pulling well past the 30-result ceiling most competitors admit to.
- 📥 Flexible input. Usernames,
@handles, full channel URLs,/directory/category/…links, game names or slugs, video and clip URLs — all auto-detected and merged.
Overview
Twitch Scraper extracts public data from twitch.tv via Twitch's own GraphQL endpoint. It's built for marketers building creator/influencer lists, agencies sourcing sponsorship prospects, analysts tracking category viewership, and developers who need Twitch data without touching the rate-limited official Helix API or standing up a browser farm.
Each run produces one row per result, with a _type field (channel, stream, game, video, clip, or schedule) so mixed-mode datasets stay filterable. Channel rows are the richest — a full profile plus socials, website, and emails. Stream rows embed the broadcaster's profile so a directory sweep doubles as a lead list.
The scraper is HTTP-only (impit + a global sliding-window concurrency model). Twitch's public client ID is embedded at build time and self-heals — if Twitch rotates it, the actor re-extracts the current one from twitch.tv and retries, with no redeploy needed.
Pricing
| Event | When | Price |
|---|---|---|
| Actor start | Once per run (per GB of memory, 256 MB default) | $0.005 |
| Result | Each row: channel, stream, game, video, clip or schedule entry | $0.002 |
| Contact email | Each email found by the opt-in website lookup (enrichEmails); emails in the bio and panels are included in the row price | $0.05 |
Example: 1,000 streamer profiles with socials and bio emails cost $2.00.
Supported Inputs
You can target Twitch four ways, mixed freely in one run:
| Input field | Accepts | Example |
|---|---|---|
channelUsernames | usernames, @handles, or channel URLs | shroud, @pokimane, https://www.twitch.tv/caseoh_ |
gameNames | game/category names, slugs, or directory URLs | Fortnite, just-chatting, https://www.twitch.tv/directory/category/valorant |
searchQueries | free-text keywords (searchChannels mode) | chess, speedrun, cooking |
startUrls | any twitch.tv URL — channel, directory, video, or clip | https://www.twitch.tv/videos/2820701541 |
Copy-pasteable start example:
Not supported: private/subscriber-only data, live chat messages, whispers/DMs, follower lists (Twitch gates these behind an integrity token), watch-time or revenue analytics, and anything requiring a logged-in session. See the FAQ.
Use Cases
| Audience | What they pull |
|---|---|
| Influencer marketing | Streamer shortlists filtered by follower band + language, with socials and contact emails for outreach |
| Sponsorship agencies | Live-in-category prospect lists (who's streaming your game right now, at what audience size) |
| Market research | Category viewership, top-games directory, streamer counts over time |
| Brand monitoring | Track a set of channels — live status, current game, last broadcast, schedule |
| Content / clips teams | Top clips by game or channel for a chosen period; VOD catalogs |
| Data / dev teams | Clean Twitch data feed without the Helix API's OAuth + rate limits |
How It Works
- You provide targets — usernames, game names, search terms, or twitch.tv URLs — and pick a mode.
- The actor classifies each target (user vs game vs video vs clip) and merges everything into one work list.
- It queries Twitch's public GraphQL API — batching channel lookups (35 per request), fanning directory sweeps across sort/language partitions, and paginating search and video/clip lists.
- It enriches channel rows — parsing socials and bio/panel emails, and (optionally) visiting the streamer's own website for a business email.
- It applies your filters (followers, viewers, language, has-email, has-socials) and pushes one clean row per result to the dataset — export as JSON, CSV or Excel.
Input Configuration
Only fields that exist in the actor are listed.
| Field | Type | Description |
|---|---|---|
mode | select | channels, searchChannels, gameStreams, topStreams, topGames, videos, clips, schedule. Default channels. |
channelUsernames | array | Usernames, @handles, or channel URLs (channels/videos/clips/schedule). |
gameNames | array | Game/category names, slugs, or directory URLs (gameStreams/clips). |
searchQueries | array | Keywords for searchChannels mode; paginates far past the first page. |
startUrls | array | Any twitch.tv URLs — auto-detected and merged with the above. |
maxItems | integer | Stop after this many dataset rows. Default 100. |
languages | array | Two-letter broadcaster language codes, e.g. ["EN","DE"]. |
minFollowers / maxFollowers | integer | Keep only channels/streams inside this follower band. |
minViewers / maxViewers | integer | Stream modes: keep streams inside this live-viewer band. |
onlyWithEmail | boolean | Keep only rows that surfaced a contact email. |
onlyWithSocials | boolean | Keep only rows with at least one social/website link. |
includePanels | boolean | Fetch channel panels for extra links/emails. Default true. |
includeVideos | boolean | Attach a recentVideos list to channel rows. |
includeClips | boolean | Attach a topClips list to channel rows. |
maxVideosPerChannel | integer | Cap for videos mode and nested VOD lists. Default 30. |
maxClipsPerChannel | integer | Cap for clips mode and nested clip lists. Default 30. |
videoType | select | ALL, ARCHIVE (past broadcasts), HIGHLIGHT, UPLOAD. |
videoSort | select | TIME or VIEWS. |
clipPeriod | select | LAST_DAY, LAST_WEEK, LAST_MONTH, ALL_TIME. |
clipSort | select | VIEWS_DESC, CREATED_AT_DESC, TRENDING. |
enrichEmails | boolean | Opt-in, free: crawl the streamer's own website for a business email. |
maxConcurrency | integer | Parallel requests against Twitch. Default 10. |
proxy | object | Optional. Twitch usually works with no proxy; add one only for rate-limiting. |
Example — find mid-tier English Fortnite streamers with an email, for outreach:
Example — discover channels by keyword, with contact enrichment:
Output Overview
One row per result. The _type field tells you the shape. A channel row is a full streamer profile: identity, follower count, partner/affiliate flags, live status and current stream, last broadcast, total VOD count, socials, website, and any emails found in the bio/panels. stream rows embed the broadcaster's profile (so directory sweeps double as lead lists); game, video, clip, and schedule rows carry their own natural fields.
Output Samples
Channel row (from mode: channels, username pokimane, trimmed):
Stream row (from mode: gameStreams, trimmed):
Key Output Fields
Identity — channelId, username, displayName, url, bio, accountCreatedAt, profileImageUrl, bannerImageUrl.
Audience & status — followersCount, isPartner, isAffiliate, isLive, language, team, totalVideos.
Live / recent — currentStream (title, game, viewers, startedAt, tags), lastBroadcast (title, game, startedAt).
Lead-gen — socials[] (platform + url), website, bioEmail, allEmails[], plus contactEmail / contactWebsite / emailEnrichment when enrichEmails is on.
Stream rows — streamId, viewersCount, startedAt, tags[], thumbnailUrl, game, gameId + the embedded broadcaster profile.
Game rows — name, slug, viewersCount, followersCount, broadcastersCount, boxArtUrl.
Video rows — videoId, title, viewCount, lengthSeconds, publishedAt, type, game, url.
Clip rows — clipId, slug, title, viewCount, durationSeconds, createdAt, game, curator, url.
Schedule rows — segmentId, title, startAt, endAt, categories[].
FAQ
Which URLs and inputs are supported? Channel usernames/@handles/URLs, game names/slugs/directory URLs, search keywords, and video/clip URLs — see Supported Inputs. Everything is auto-classified.
Do I need a Twitch API key or login? No. The actor uses Twitch's public web GraphQL endpoint. No OAuth, no cookies, no key.
Can it get streamer contact emails? Yes, when the streamer publishes one. Emails are parsed from the channel bio and panels. Turn on enrichEmails to also visit the streamer's own linked website and scan its contact/about pages. Emails that aren't published anywhere public can't be found.
Can it scrape live chat, whispers, or a channel's full follower list? No. Live chat, whispers, and follower/following lists are either private or gated behind Twitch's integrity token and are out of scope. The actor covers public profile, directory, video, clip, and schedule data.
Why are some directory results capped? Twitch integrity-gates deep after pagination on live-stream directories. The actor works around this by sweeping multiple sort orders and languages and deduping broadcasters — giving materially more coverage than a single 30-result page — but a single game's live streams are still bounded by what Twitch exposes keylessly.
Is schedule data always present? Only when the streamer has published a schedule. Channels without one return no schedule rows (logged, not an error).
Do I need a proxy? Usually not — Twitch's public API accepts direct connections. Add a proxy only if you hit rate-limiting on a shared IP.
Support
Found a bug or need a field that isn't captured? Open an issue on the actor's Issues tab on the Apify Store, and it'll be looked at promptly. Include your input JSON and, where relevant, an example Twitch URL so the case can be reproduced.
Additional Services
Need a tailored export (a specific schema, a scheduled daily creator feed, a bundled multi-platform dataset), or a custom Twitch workflow? Custom scraping and enrichment work is available on request — reach out through the Issues tab or the developer profile.
Explore More Scrapers
This actor is part of a broader portfolio of directory, social, and lead-generation scrapers on the Apify Store. Browse the developer's other actors — job boards, real-estate portals, review sites, and social platforms — from the profile page linked on the actor listing.
⚠️ Disclaimer
This actor is an independent tool and is not affiliated with, endorsed by, or sponsored by Twitch Interactive, Inc. or Amazon.com, Inc. "Twitch" and all related names, marks, and logos are trademarks of their respective owners and are used here only to describe the actor's function.
The actor scrapes publicly available data only — information any visitor can see on twitch.tv without logging in. It does not access private, subscriber-only, or authenticated content, and it does not bypass access controls. You are responsible for using it in compliance with Twitch's Terms of Service, applicable laws, and data-protection regulations including GDPR and CCPA. Personal data (such as contact emails published by creators) must be processed on a lawful basis and only for legitimate purposes. Use responsibly.
SEO Keywords
Twitch scraper, Twitch API scraper, scrape Twitch channels, Twitch data extractor, Twitch streamer scraper, Twitch channel scraper, Twitch live streams scraper, Twitch clips scraper, Twitch VOD scraper, Twitch game directory scraper, Twitch email scraper, Twitch influencer scraper, streamer lead generation, influencer outreach data, creator contact emails, Twitch marketing data, Twitch follower data, Twitch category viewership, streamer discovery tool, Twitch schedule scraper, social media scraping, creator economy data, gaming influencer leads, Twitch analytics export


