

Australia Super Product & Pathway Structure - APRA
Pricing
from $33.50 / 1,000 product/pathway records
Australia Super Product & Pathway Structure - APRA
Australian super product and investment-pathway structure from APRA - always the newest quarterly workbook (June 2026 quarter on 30 Sep 2026): search by fund or ABN, product, MySuper/Choice, product or pathway rows. Member accounts and assets. CC BY 4.0. $0.05 per record.
Pricing
from $33.50 / 1,000 product/pathway records
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 hours ago
Last modified
Categories
Share
Australia's superannuation product and investment-pathway structure from APRA's quarterly product-structure workbook, as clean typed records - one row per product profile or per investment pathway, with fund, product and option identifiers and the current snapshot's structural fields.
Search and current data
Question: Which AustralianSuper products does APRA list, with member accounts and assets, in the latest quarter?
Run on 30 Sep 2026 this returned 4 rows (4 × $0.05 = $0.20 on Apify's Free plan), for example:
| Period | Product | Type | Member accounts | Member assets |
|---|---|---|---|---|
| 2026-06-30 | AustralianSuper Accumulation Choice | Choice Product | 682880 | 133445247 |
| 2026-06-30 | AustralianSuper Choice Income | Choice Product | 141010 | 66375995 |
| 2026-06-30 | AustralianSuper MySuper | MySuper Product | 2993810 | 235702823 |
| 2026-06-30 | AustralianSuper TTR Income | Choice Product | 9270 | 2301835 |
Search options (all optional; a record must match every option you set, and several values in one option match any of them):
- Record types (
recordTypes) —product_profile(Table 1a, one row per product) orinvestment_pathway(Table 1b). - Funds (name or ABN) (
funds) — e.g.AustralianSuper,Hostplus,ART. - Products (name contains) (
products) — e.g.MySuper,Choice Income. - Product types (
productTypes) —MySuperorChoice.
Always the newest file. APRA publishes these files every quarter under a new name. Until 30 Sep 2026 this actor read a fixed link to the March 2026 quarter file; it now reads APRA's publication page on every run and takes the newest file (the June 2026 quarter, published September 2026). If that page cannot be read, the run uses the last known file and says so in its status and receipt. Search options are tested on every row before the record limit. With no option set the actor returns the file's rows in order, as before.
What one record represents
The source is APRA's Quarterly Superannuation Product Statistics - Product Structure workbook (XLSX) at
www.apra.gov.au, downloaded directly. The workbook holds two data tables and this Actor emits a typed record from
each, tagged by record_type: product_profile (Table 1a - one row per superannuation product, with member
accounts and assets, product type/category/phase, open-to indicators, inception/end dates and the product disclosure
statement URL) and investment_pathway (Table 1b - one row per investment pathway, with the product, investment
menu and investment option identifiers and names, member accounts and assets, proportions, option codes and
indicators).
Sample output
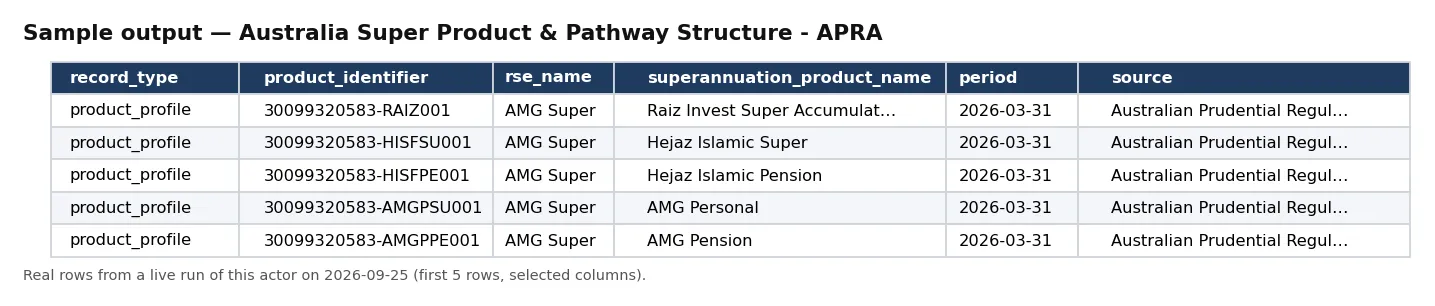
Real rows from a live run of this actor (first 5 rows, selected columns).
One full record from the same run, exactly as delivered:
Coverage and volume
Default changed on 30 Sep 2026: if you leave maxRecords out, a run now returns up to 10 records (it was 500). Set maxRecords yourself to get more — the maximum is unchanged.
The live workbook holds 830 product-profile rows and 130,288 investment-pathway rows (131,118 records total). This is stated plainly because it differs from the supply index's figure of 238,940: that figure was taken from the workbook's padded row dimension, which includes trailing empty rows; the Actor delivers only the populated data rows, and this listing quotes the live populated count. The workbook's SHA-256 is verified on the build. You raise Maximum records to pull the full set or lower it to sample.
Person data
Every identifier and name is organisation- or product-level (fund/RSE, product, investment menu and option). The workbook carries no individual-trustee or contact column.
Licence
Australian Prudential Regulation Authority (APRA). Published under the Creative Commons Attribution 4.0 International (CC BY 4.0) licence: you are free to copy, redistribute and adapt the material for any purpose, including commercially, provided you attribute APRA and do not suggest APRA endorses you. The attribution rides on every record.
Fields, scheduling and joins
Every field in the record is either a source-native identifier, a source-native attribute, or one of the six
provenance fields (source, source_dataset, licence, attribution, caveat, observed_at) the fleet attaches to
every record. Nothing is derived or inferred beyond the small, documented transforms noted above, and nothing is
dropped silently - the person-handling section spells out exactly which fields are excluded and why. The grain is one
record per the natural unit of the source, which keeps each row independently meaningful, keeps the key stable across
runs so re-running is a cheap upsert rather than a re-import, and lets you aggregate up to whatever unit you need
without unpicking a pre-joined table.
Because the source republishes on its own cadence, a scheduled run keeps a downstream table current: new and changed
records upsert over the old ones on the stable key, and the observed_at stamp on every record tells you when each was
last seen live. Set Maximum records low to sample the shape of the data cheaply, then raise it once the cell fits
your use; the Actor streams its source, so memory stays flat regardless of how many records you request, and you are
billed only for what is delivered. There is no subscription and no minimum - the per-record price and the record cap
together mean the spend on any run is known in advance and matched exactly to the data you receive.
Reconciling counts honestly
Where the live count differs from any previously published figure, the live measure is the honest one and is what this listing quotes; sources re-issue and re-version their files over time, and a workbook's declared row dimension can include trailing empty rows. The run receipt always states what was actually delivered and charged and confirms the two agree, so every run is auditable against itself regardless of what any external index expected.
Integration notes
The output is a flat table of typed records, so it drops straight into whatever you already use: load the run's dataset over the API or an export, key on the record id, and upsert. A common pattern is a light scheduled run that pulls the newest slice into a staging table, then a merge on the stable key into the table your product reads, so you never re-pay for rows you already hold and your history grows cleanly over time. Because identifiers are preserved exactly as the source publishes them, joins across the fleet's cells - and onto your own systems - work without a mapping layer: the same organisation, product, option or facility id lines up on both sides. If you only need a slice, the record cap and any partition inputs bound the run precisely, so a targeted pull costs cents rather than the price of the whole set. Nothing about the record shape assumes a particular warehouse, language or tool; it is deliberately plain so the integration work is a load and a merge, not a cleaning project.
Sibling Actors
The fleet's ETF-holdings cell is a different market and instrument; there is no row overlap. The two other APRA superannuation cells in this batch (allocation history, performance history) share this host and licence but are distinct datasets.
Provenance and compliance
Every run reads the door host's robots.txt at runtime and records the result (URL, status, byte length and, where
a policy is served, its SHA-256) in the run's RUN_RECEIPT. Where the host serves no robots policy (HTTP 404), the
gate records that as a flag and proceeds on the licence, which grants re-use. The endpoint is keyless and the Actor
reads only the public data door - never a per-record detail page, never a mirror, and it never bypasses a block.
Data quality and freshness
Numbers arrive as real numbers, booleans as real booleans, and every other value as a string or null, so the dataset
loads without a cleaning pass. Each record is keyed on a stable source identifier, so it is safe to diff, deduplicate
or upsert. Every run re-reads the live door, so the data is as fresh as the source publishes, and each record's
observed_at stamp dates the snapshot. The receipt records how many rows were delivered and charged and confirms
charge_equals_delivered.
Billing, delivery and joins
Pricing is per record: you are billed only for records the Actor actually delivers, and the charge is raised after each record is pushed (push-then-charge), so a failed or empty run costs nothing. The Maximum records cap bounds every run, so spend is known before you start - sample cheaply, then raise it. Every record is a flat, typed object keyed on a stable id, so it loads without a cleaning pass, diffs cleanly between runs, and upserts into a table you keep over time; re-running keeps that table current without re-paying for rows you already hold, and each receipt reconciles delivered against charged. Because the source's own identifiers are preserved verbatim, the dataset joins onto other sources keyed on the same identifier.
Who buys this, and how they use it
This cell is bought by teams that need the source's published set as a typed, keyed table they can hold and refresh rather than a page they scrape: market-intelligence and analytics teams sizing and tracking a market, data engineers wiring a clean upstream feed into a warehouse, and product teams building on a stable identifier. The grain and the key are chosen so the output is a building block, not a one-off export - you run it on a schedule, keep the delta, and join it to your other sources on the identifiers it preserves verbatim. The spend on any run is the per-record price times the records delivered, matched exactly to what you receive.


