
Schema Markup Extractor — JSON-LD, Microdata, Open Graph
Pricing
from $33.50 / 1,000 page reads
Schema Markup Extractor — JSON-LD, Microdata, Open Graph
Read the structured data on any pages or whole sites: JSON-LD, Microdata, RDFa, Open Graph, Twitter cards, Dublin Core. One row per page with every schema type and checks for broken JSON-LD, missing required properties and tags. Part of NexGen Signal — data tools and official-source data products
Pricing
from $33.50 / 1,000 page reads
Rating
0.0
(0)
Developer
NexGen Signal
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
🧩 Schema Markup Extractor — JSON-LD, Microdata, Open Graph
Give a list of page links (or turn on sitemaps to cover whole sites) and get every piece of structured data each page publishes, one row per page: JSON-LD, Microdata, RDFa, Open Graph, Twitter / X card tags, Microformats and Dublin Core, plus the title, meta description, canonical link and language.
Each row lists every schema type found on the page (nested types included, such as the Offer inside a Product), and checks for common mistakes: JSON-LD blocks that are broken or not strict JSON, items with no @context or @type, schema items missing a property that Google's rich-result guides list as required (Product, Offer, BreadcrumbList, FAQPage, Event, JobPosting, Recipe, HowTo, VideoObject, LocalBusiness, Review, AggregateRating, SoftwareApplication, Course, Dataset, Article), pages with no structured data at all, Open Graph missing one of its four required tags (og:title, og:type, og:image, og:url, as set out at ogp.me), and pages with no twitter:card.
Give page links, read a whole site from its sitemap, or follow links from your pages up to a chosen depth.
The unit of output is one page read. Pages that answer with an error, links that are not HTML pages, and pages robots.txt disallows are not billed.
Who buys this and for what job
- SEO teams auditing rich-result markup across a site, or checking competitors' schema types.
- E-commerce teams pulling Product, Offer and Review data that shops publish in JSON-LD.
- Developers checking social share tags and structured data before a release.
- Data teams collecting the structured facts pages publish about themselves.
Buyers usually search for this as "schema markup extractor", "JSON-LD scraper" or "structured data extractor".
📊 Sample Output
| url | schema_types | json_ld_count | opengraph_tags | checks |
|---|---|---|---|---|
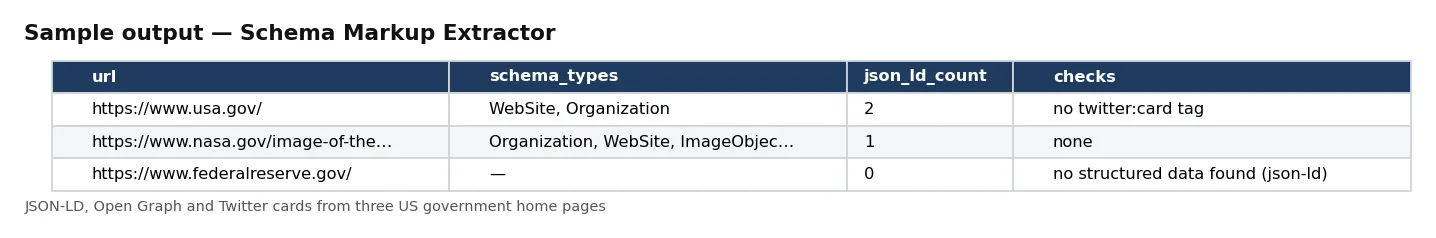
| https://www.usa.gov/ | WebSite, Organization | 2 | 7 | no twitter:card tag |
| https://www.nasa.gov/image-of-the-day/ | Organization, WebSite, ImageObject, WebPage, Person, Article | 1 | 14 | none |
| https://www.federalreserve.gov/ | — | 0 | 6 | no structured data found (json-ld) |
Rows from live run eMQIozuhXHrruMiQp on Apify (JSON-LD, Open Graph and Twitter cards only, from three US government home pages). Notice the Federal Reserve home page: it publishes Open Graph tags but no JSON-LD, which the checks report.
✅ What you get
Every field of each record:
record_id,url,final_url,status_code,found_via— the page, where it was served from, its status, and whether it came from your list or a sitemap.title,meta_description,canonical,lang— the page's basic tags.has_structured_data— true when any JSON-LD, Microdata or RDFa item was found.schema_types— every schema type found in JSON-LD, Microdata and RDFa, in page order.json_ld,microdata,rdfa— the items themselves (Microdata and RDFa in JSON-LD form), with counts injson_ld_count,microdata_count,rdfa_count.opengraph,twitter_card,microformats,dublincore— social and other meta tags as name → value (a repeated tag becomes a list).json_ld_errors,checks,check_count— problems found on the page.read_at— when the page was read (UTC).
⚙️ Sample inputs
Two pages (the Store example)
All formats.
A whole site from its sitemap
Reads the pages the sitemap lists, same host only.
Follow links from a page
Reads the pages it links to (same host), two clicks deep.
Social and JSON-LD tags only
Faster rows with only those formats and their checks.
Input fields:
| Field | Meaning |
|---|---|
urls | pages to read (up to 10,000). |
syntaxes | json-ld, microdata, rdfa, opengraph, twitter, microformat, dublincore. Empty = all. |
useSitemaps | also read the pages listed in each site's sitemap (default off). |
followLinks, maxDepth | also read same-site pages your pages link to, this many clicks deep (default off, depth 3). |
maxPages | stop after this many pages are delivered (default 1,000). Each delivered page is billed. |
🧾 JSON sample record
🔧 How it works
Pages are read 5 at a time. JSON-LD blocks are parsed one by one, so a broken block is reported instead of silently dropped; a block with a trailing comma is still read and flagged. Microdata, RDFa, Microformats and Dublin Core are read with the open extruct library. RDFa is cleaned so that only real vocabulary data is kept: Open Graph tags (which have their own field), XHTML role attributes and WordPress api.w.org links are left out.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
Delivery is pushed first and charged after. The run receipt (key-value store record RUN_RECEIPT) lists every page with its outcome, the schema types and checks found across the run with counts, the robots.txt result per host, the sitemaps read, and the delivered and charged counts.
💰 Pricing example
Per page delivered, no start fee, no monthly charge:
| Apify plan | Price per page |
|---|---|
| Free | $0.05 |
| Bronze | $0.045 |
| Silver | $0.04 |
| Gold, Platinum, Diamond | $0.0335 |
- 10 pages: $0.50 on the Free plan, $0.34 on Gold.
- 1,000 pages: $50.00 on the Free plan, $33.50 on Gold.
- 10,000 pages: $500.00 on the Free plan, $335.00 on Gold.
Coverage and size. Proof runs on 17 Oct 2026: 40 NASA pages from its sitemap in about 61 seconds (Organization, WebSite, WebPage, ImageObject, BlogPosting, Person and VideoObject found); 8 usa.gov pages by following links in 73 seconds (usa.gov asks for a 10-second gap between requests, which is respected); the two-page Store example in about 3 seconds. It reads the HTML the server sends; markup added later by JavaScript is not seen.
⚖️ Legal & ToS
Pages belong to their owners. You choose the links. Make sure you have the right to download and use the content you point it at; the actor fetches only what you give it (and, where you turn it on, what those pages link to).
The rows hold the markup each page publishes about itself; the actor adds nothing.
Every run reads each host's robots.txt first: a path it disallows is skipped, listed in the run receipt and never charged. Only public internet addresses are fetched (no private, loopback or cloud-metadata addresses, checked again on every redirect). No logins, no CAPTCHA solving, no proxies.
❓ FAQ
Does it validate against Google's rich-result rules?
It checks the properties Google's guides list as required for the common types (missing offers on a Product, missing startDate on an Event, and so on). Recommended properties and Google's eligibility rules are not checked; use Google's Rich Results Test for the final word.
Does it run JavaScript? No. Markup inserted by scripts after the page loads is not seen.
Is a page with no structured data billed? Yes, if it was read: the row (with the 'no structured data found' check) is the answer. Error pages and non-HTML links are not billed.
🆘 Troubleshooting
- A page is missing from the results — RUN_RECEIPT shows why: robots.txt, an HTTP error, not HTML, or unreachable.
- Sitemap added no pages — The site may have no sitemap in robots.txt or at /sitemap.xml, or its sitemap lists another host.
- SOURCE UNAVAILABLE — None of your links could be reached after retries. Nothing was charged.
🔗 Related Actors
- Website Performance Audit — Lighthouse scores and web vitals per page
- Website Tech Stack Detector — what a site is built with
- Website Contact Scraper — contact details from website lists
🏢 About NexGen Signal — data tools and official-source data products. Browse the catalog: apify.com/nexgensignal
⭐ Found this useful?
If this actor saved you time, a rating on its Apify Store page helps other buyers find it.
Part of NexGen Signal — data tools and official-source data products.


