
ChEMBL Source Document Index
Pricing
from $13.40 / 1,000 source document records
ChEMBL Source Document Index
One structured record per ChEMBL source document — the document id, doc type, and the bibliographic identifiers (DOI, PubMed id, patent id, journal, year, pages, volume/issue, authors) plus the ChEMBL release lineage.
Pricing
from $13.40 / 1,000 source document records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
🔔 ChEMBL Source Document Index
One structured record per ChEMBL source document — the document id, doc type, and the bibliographic
identifiers (DOI, PubMed id, patent id, journal, year, pages, volume/issue, authors) plus the ChEMBL
release lineage. A master index over ChEMBL's ~101,100 source documents, keyed and deduplicated on
document_chembl_id. Built for cheminformatics, literature, and licensing teams who need the document
provenance behind ChEMBL activities as clean citation facts.
Differentiation: generic ChEMBL wrappers return flat document pages; this index carries the DOI / PubMed / patent identifiers verbatim including nulls (a document with no DOI keeps a null DOI, never a blank or inferred one), attaches the ChEMBL release lineage (release name + creation date) per record, omits the bulk abstract, and excludes the submitter contact field. Every row stamps the CC BY-SA share-alike notice.
Output is one chembl_source_document row per result; billing is pay-per-event, the value event being one source document record (a $0.02 start fee per run, then $0.02 per source document record). Source: www.ebi.ac.uk.
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
📊 Sample Output
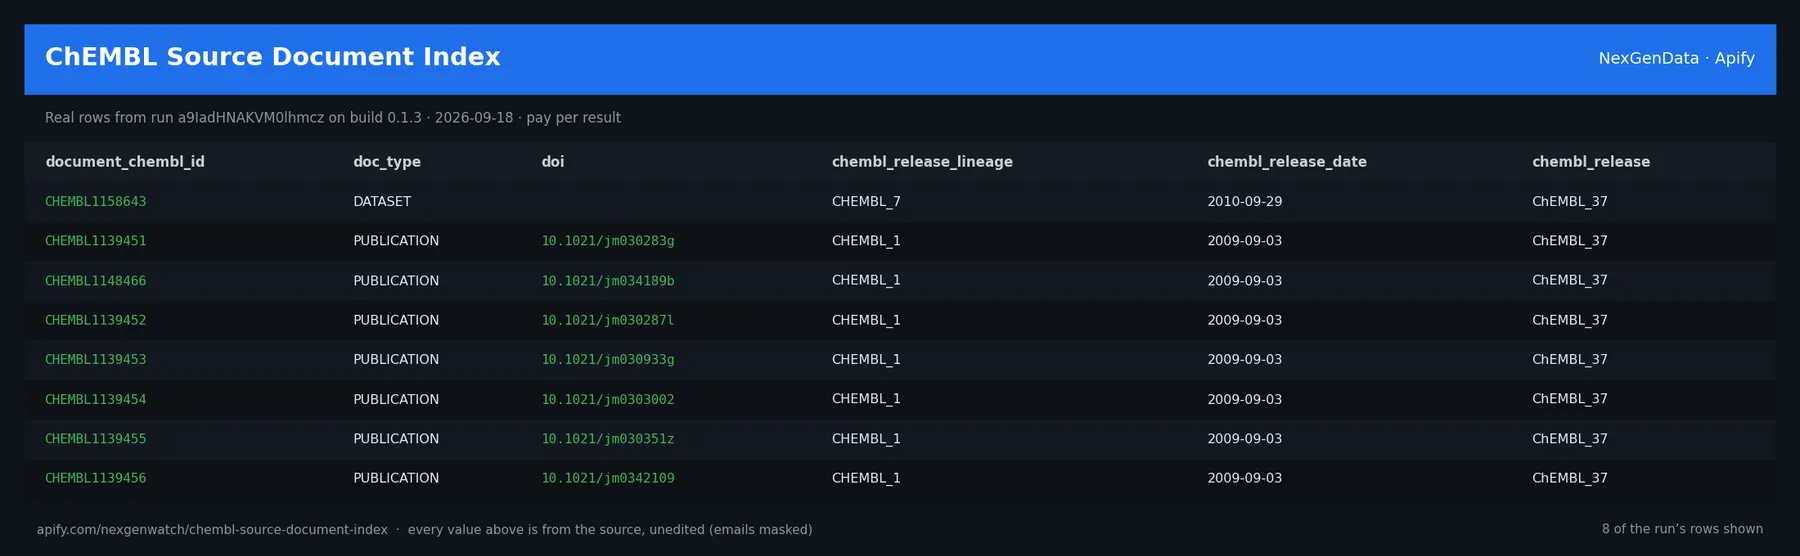
Real rows from run CsYO71aXWQ7xRTBff on build 0.1.5 (2026-09-19), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| document_chembl_id | doc_type | doi | chembl_release_lineage | chembl_release_date | chembl_release |
|---|---|---|---|---|---|
| CHEMBL1158643 | DATASET | CHEMBL_7 | 2010-09-29 | ChEMBL_37 | |
| CHEMBL1139451 | PUBLICATION | 10.1021/jm030283g | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
| CHEMBL1148466 | PUBLICATION | 10.1021/jm034189b | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
| CHEMBL1139452 | PUBLICATION | 10.1021/jm030287l | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
| CHEMBL1139453 | PUBLICATION | 10.1021/jm030933g | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
| CHEMBL1139454 | PUBLICATION | 10.1021/jm0303002 | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
| CHEMBL1139455 | PUBLICATION | 10.1021/jm030351z | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
| CHEMBL1139456 | PUBLICATION | 10.1021/jm0342109 | CHEMBL_1 | 2009-09-03 | ChEMBL_37 |
The run finished with the status message: NORMAL: 50 unique rows (0 duplicates collapsed) from ChEMBL_37. billable=50
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string/null) — e.g.chembl_source_documentdocument_chembl_id(string/null) — e.g.CHEMBL1158643doc_type(string/null) — e.g.DATASETdoi(string/null) — e.g.10.1021/jm030283gdoi_chembl(string/null) — null in every sample rowpubmed_id(string/null) — e.g.14695813patent_id(string/null) — null in every sample rowtitle(string/null) — e.g.Unpublished datasetjournal(string/null) — e.g.J Med Chemjournal_full_title(string/null) — e.g.Journal of medicinal chemistry.year(string/null) — e.g.2004volume(string/null) — e.g.47issue(string/null) — e.g.1first_page(string/null) — e.g.1last_page(string/null) — e.g.9authors(string/null) — e.g.Clader JW.src_id(string/null) — e.g.0chembl_release_lineage(string/null) — e.g.CHEMBL_7chembl_release_date(string/null) — e.g.2010-09-29chembl_release(string/null) — e.g.ChEMBL_37source(string/null) — e.g.chembl-source-document-indexrelease_date(string/null) — e.g.ChEMBL_37source_url(string/null) — e.g.https://www.ebi.ac.uk/chembl/api/data/document.jsonobserved_at(string/null) — e.g.2026-09-19T00:17:51Zlicense(string/null) — e.g.CC BY-SA 3.0attribution(string/null) — e.g.ChEMBL / EMBL-EBI (https://www.ebi.ac.uk/chembl/)terminal(string/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/null) — null in every sample rownote(string/null) — null in every sample row
✅ What you get
record_type(string/null) — e.g.chembl_source_documentdocument_chembl_id(string/null) — e.g.CHEMBL1158643doc_type(string/null) — e.g.DATASETdoi(string/null) — e.g.10.1021/jm030283gdoi_chembl(string/null) — null in every sample rowpubmed_id(string/null) — e.g.14695813patent_id(string/null) — null in every sample rowtitle(string/null) — e.g.Unpublished datasetjournal(string/null) — e.g.J Med Chemjournal_full_title(string/null) — e.g.Journal of medicinal chemistry.year(string/null) — e.g.2004volume(string/null) — e.g.47issue(string/null) — e.g.1first_page(string/null) — e.g.1last_page(string/null) — e.g.9authors(string/null) — e.g.Clader JW.src_id(string/null) — e.g.0chembl_release_lineage(string/null) — e.g.CHEMBL_7chembl_release_date(string/null) — e.g.2010-09-29chembl_release(string/null) — e.g.ChEMBL_37source(string/null) — e.g.chembl-source-document-indexrelease_date(string/null) — e.g.ChEMBL_37source_url(string/null) — e.g.https://www.ebi.ac.uk/chembl/api/data/document.jsonobserved_at(string/null) — e.g.2026-09-18T23:23:54Zlicense(string/null) — e.g.CC BY-SA 3.0attribution(string/null) — e.g.ChEMBL / EMBL-EBI (https://www.ebi.ac.uk/chembl/)terminal(string/null) — null in every sample rowreported_total(string/integer/null) — null in every sample rowraw_seen(string/integer/null) — null in every sample rowduplicates(string/integer/null) — null in every sample rowunique_found(string/integer/null) — null in every sample rowdelivered(string/integer/null) — null in every sample rowscope(string/null) — null in every sample rownote(string/null) — null in every sample row
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 2 × $0.02 apify-actor-start + 50 × $0.02 source_document_record = $1.04 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
Caps the run at 5 rows — about $0.12 on the Free tier ($0.02 start + 5 × $0.02).
3. A full-size run
Up to 101100 rows (the schema default for maxRecords) — about $2,022.02 on the Free tier ($0.02 start + 101100 × $0.02) if the source has that many.
🧾 JSON sample record
One real record from run CsYO71aXWQ7xRTBff, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Source. The actor reads www.ebi.ac.uk — endpoints: https://www.ebi.ac.uk, https://www.ebi.ac.uk/chembl/, https://www.ebi.ac.uk/chembl/api/data/document.json. Public pages and feeds only; nothing behind a login.
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent. Pacing: CRAWL_DELAY=10.0.
Charging. Each source document record is charged at the moment it is pushed (source_document_record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
🔧 How it works
Source
The public, keyless ChEMBL REST API at EMBL-EBI — https://www.ebi.ac.uk/chembl/api/data/document.json,
paginated, serialized at a 10-second crawl delay, no parallel fan-out. robots.txt on www.ebi.ac.uk
is honoured; the /chembl path is permitted.
Licence & attribution
ChEMBL is released by EMBL-EBI under Creative Commons Attribution-ShareAlike 3.0 (CC BY-SA 3.0):
- Attribution: ChEMBL / EMBL-EBI — https://www.ebi.ac.uk/chembl/
- Release: stamped per record (
chembl_release) with the per-document release lineage. - ShareAlike: redistribution or derivative works must be licensed under the same CC BY-SA 3.0.
Every record carries license = CC BY-SA 3.0 and attribution.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Source Document Record (source_document_record) | $0.02 | $0.018 | $0.016 | $0.0134 |
Worked at the live Free-tier price:
- 8 source document records: $0.02 start + 8 × $0.02 = $0.18
- 25 source document records: $0.02 start + 25 × $0.02 = $0.52
- 100 source document records: $0.02 start + 100 × $0.02 = $2.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 4096 MB.
Yield on the sample run: NORMAL: 50 unique rows (0 duplicates collapsed) from ChEMBL_37. billable=50. maxRecords is a hard ceiling on what is delivered and billed, never a target.
⚖️ Legal & ToS
This actor reads public, logged-out pages and feeds published by www.ebi.ac.uk. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. The source (www.ebi.ac.uk) is read logged-out; the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How many rows can one run return?
A: Up to maxRecords (default 101100). Raise the cap for a bigger run; you pay per delivered row.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other NexGen Watch actors actors?
A: Same output shape and billing model; this one covers www.ebi.ac.uk. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source (CRAWL_DELAY=10.0) and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Status says CAPPED → your cap (
maxRecords) was reached → raise it for a bigger run. - Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- Census Address Geography Check — A definitive check: does this business/property address resolve to an official U.S. Census geography, and which one?
- ChEMBL Biotherapeutic Sequence Master — One structured record per ChEMBL biotherapeutic — the molecule id, the HELM notation, the biocomponent array, and the description. A master index ove…
- ChEMBL Clinical-Stage Indication Screen — One structured clinical compound record per molecule at or above the clinical phase you set — max_phase, first approval year, molecule type, route fl…
- ChEMBL Target Assay Definition Screener — One structured record per assay for the ChEMBL target(s) you name — the assay id, type and description, category, organism/tissue/cell, BAO format/la…
- ChEMBL Target Bioactivity Screener — One structured bioactivity record per measured activity for the ChEMBL target(s) you name — the assay/target/molecule ids, the standard measurement (…
- ChEMBL Target Catalogue Master — One structured record per ChEMBL target — the target id, preferred name, organism, tax id, target type, species-group flag, cross-references, and the…
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of more than 300 public data actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


