

NEA Portfolio Report — Filtered VC Target Book
Pricing
from $33.50 / 1,000 portfolio company records
NEA Portfolio Report — Filtered VC Target Book
Filtered, normalized target book of New Enterprise Associates' portfolio, with coverage stated and a source link per company.
Pricing
from $33.50 / 1,000 portfolio company records
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Share
📈 NEA Portfolio Report — Filtered VC Target Book
Build a filtered, normalized target book of New Enterprise Associates' portfolio, with a link to NEA's own page behind every single company.
Built for deal sourcing, competitive mapping and BD teams who need a workable list instead of a wall of logos.
Output is one portfolio_company row per result; billing is pay-per-event, the value event being one portfolio company record (a $0.02 start fee per run, then $0.05 per portfolio company record). Source: www.nea.com.
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out.
📊 Sample Output
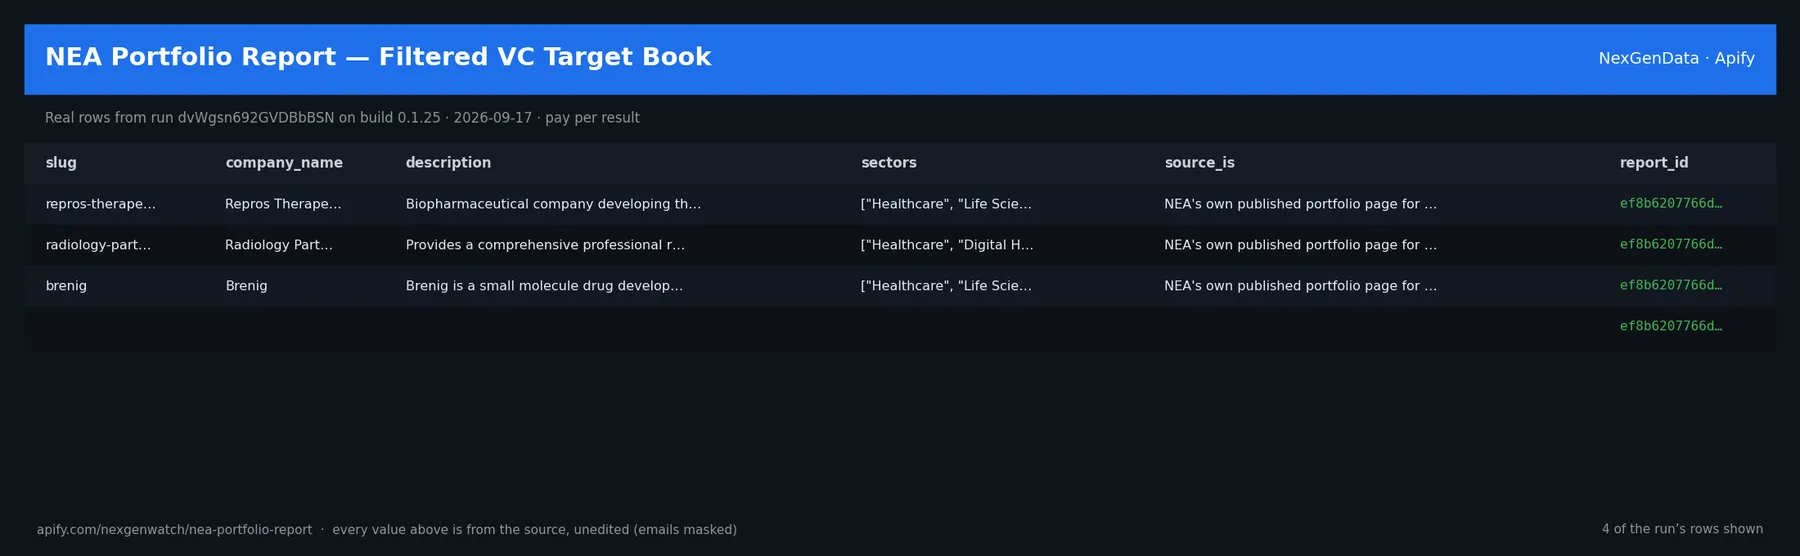
Real rows from run dvWgsn692GVDBbBSN on build 0.1.25 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| slug | company_name | description | sectors | source_is | report_id |
|---|---|---|---|---|---|
| repros-therapeutics | Repros Therapeutics | Biopharmaceutical company developing therapeutic drugs and formulation | ["Healthcare", "Life Sciences"] | NEA's own published portfolio page for this company | ef8b6207766db2a8 |
| radiology-partners | Radiology Partners | Provides a comprehensive professional radiology services solution deli | ["Healthcare", "Digital Health"] | NEA's own published portfolio page for this company | ef8b6207766db2a8 |
| brenig | Brenig | Brenig is a small molecule drug development company that utilizes an A | ["Healthcare", "Life Sciences"] | NEA's own published portfolio page for this company | ef8b6207766db2a8 |
| ef8b6207766db2a8 |
The run finished with the status message: CAPPED: parsed=10/917 (1.1%); maxCompanies=10 bounded the sweep to the first 10 of 917 companies in the order NEA's sitemap lists them | matched=3 | coverage=10/917 complete=False | portfolio-company-record: delivered=3
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
slug(string/null) — e.g.repros-therapeuticscompany_name(string/null) — e.g.Repros Therapeuticsdescription(string/null) — e.g.Biopharmaceutical company developing therapeutic drugs and formulations designedsectors(array/null) — e.g.["Healthcare", "Life Sciences"]first_invested_year(integer/null) — e.g.2009stage(string/null) — e.g.Public/PIPESstatus(string/null) — e.g.IPO/Acquiredstatus_detail(string/null) — e.g.NASDAQ: RPRX (old) Acquired by Allerganthemes(array/null) — e.g.["AI"]source_url(string/null) — e.g.https://www.nea.com/portfolio/repros-therapeuticssource_is— e.g.NEA's own published portfolio page for this companyrecord_type(string) — e.g.portfolio_companyreport_id(string) — e.g.ef8b6207766db2a8generated_at— e.g.2026-09-17T17:37:38Zfirm— e.g.New Enterprise Associates (NEA)source_of_record— e.g.https://www.nea.com/sitemap.xmlfilter— e.g.{"sectors": ["Healthcare"], "stages": [], "statuses": [], "themes": [], "first_ifilter_is_active— e.g.Trueuniverse_total(integer/null) — e.g.917companies_examined(integer/null) — e.g.10companies_unreadable— e.g.0dead_sitemap_entries— e.g.0coverage_complete(boolean/null) — e.g.Falsecoverage_pct(number/null) — e.g.1.1coverage_caveat(string/null) — e.g.maxCompanies=10 bounded the sweep to the first 10 of 917 companies in the ordermatch_count(integer/null) — e.g.3terminal(string/null) — e.g.CAPPEDrate_limit_per_sec— e.g.2requests_attempted— e.g.11requests_failed— e.g.0vocabularies_in_examined_set— e.g.{"sectors": {"Technology": 7, "Enterprise": 4, "Healthcare": 3, "Life Sciences":no_match_is_an_answer— null in every sample rownothing_is_inferred— e.g.status and stage are carried verbatim from NEA's own page for each company. Thisreport_markdown— e.g.# NEA portfolio — filtered target book **Generated** 2026-09-17T17:37:38Z **Firmreport_kv_key— e.g.PORTFOLIO_REPORT_ef8b6207766db2a8
Output
- one
portfolio_companyrecord per match — name, description, sectors, themes, first invested year, stage, status, status detail, and the NEA URL it came from - one
portfolio_reportrecord — the filter, the coverage numbers, the vocabularies - one
source_receipt— terminal, HTTP statuses, request counts, pacing - a rendered markdown brief in the key-value store
Every run also writes a RUN_RECEIPT record to its key-value store with the source checks it made and the counts it charged — diagnostics never land in the paid dataset.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 3 × $0.05 portfolio-company-record = $0.17 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
A bounded run for checking the field shape before scheduling.
3. A full-size run
The same input run on a schedule; each run is billed only for what it delivers.
🧾 JSON sample record
One real record from run dvWgsn692GVDBbBSN, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Source. The actor reads www.nea.com — endpoints: https://www.nea.com/portfolio, https://www.nea.com/portfolio/, https://www.nea.com/sitemap.xml. Public pages and feeds only; nothing behind a login.
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Pacing: RATE_PER_SEC=2.0, MIN_INTERVAL=1.0.
Terminal states. A run ends NORMAL, CAPPED (your cap was reached), PARTIAL (something was withheld and the message says what), GENUINE_EMPTY (the source was read and truly had nothing in scope) or BLOCKED (the source refused or changed shape — the run FAILS loud and bills nothing). A zero-row run is never reported as a silent success.
Charging. Each portfolio company record is charged at the moment it is pushed (portfolio-company-record); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
Coverage is the headline, not the footnote
This actor sells a filtered book, so the worst thing it can do is hand you a short list that reads like a complete one. Every report states, in the record and on the first line of the brief:
A company missing from a partial book has not been ruled out — it was never read. Raise
maxCompanies toward 914 for a complete book; budget about a minute per 120 companies.
Honouring your page budget perfectly still does not count as coverage. Coverage is measured against NEA's portfolio, not against the run's own limit.
1. nea.com/portfolio is not the portfolio
The page the phrase "scrape the portfolio" points at is a 30-logo featured carousel. It carries no company name in text, no sector, no stage and no status — nothing to filter on.
The universe comes from the site's own declared sitemap: 914 /portfolio/ URLs out of
1,333, measured 2026-07-31. Each company's detail page carries the fields that make a target
book: sectors, first-invested year, stage, company status and NEA's own one-line description.
2. Values must be sliced between labels, never by token offset
The detail page renders as a flat label/value stream:
Two traps, both measured on real pages and both closed:
- A current holding has no status detail. The token after the status is the next label.
An offset parser reports every live company as
status_detail = "Associated Team". - An exited company's block is the last one on the page.
/portfolio/polyservehas no team, theme or website section, so slicing "to the next label" ran the status detail into the site footer: "Acquired by Hewlett Packard © NEA, 2026 Follow us on social media…" — boilerplate glued onto a real field, on exactly the exited companies a buyer cares most about.
Both are asserted against verbatim excerpts of the live pages in the test suite.
Nothing is inferred
status and stage are carried verbatim from NEA's page. This actor never decides that a
company exited, failed, or is still held, and it never scores or ranks anyone. It reports what
NEA publishes and links to it.
NEA's published portfolio is the whole of this report. It is not a complete record of NEA's investments — a firm publishes what it chooses to. This is not investment advice.
Filters
| filter | what it does |
|---|---|
sectors | keep companies tagged with any of these, e.g. Healthcare, Technology |
themes | keep companies tagged with any of these, e.g. AI, Infrastructure |
stages | stage at first investment, e.g. Seed, Early, Growth |
statuses | company status as NEA publishes it, e.g. Private, Acquired |
firstInvestedFrom / firstInvestedTo | year range of NEA's first investment |
nameContains | free text across company name and NEA's description |
maxCompanies | how much of the 914 to read — default 150, a partial sweep |
Filtering runs here, over parsed fields, because the source offers no server-side filter at all. Every parameter therefore provably changes the result set, proven control-vs-test in the suite — none of them can be quietly discarded by the site.
Each report also returns vocabularies_in_examined_set: the sectors, stages and statuses
counted from the companies this run actually read, not from a hard-coded list.
Reading policy
nea.com/robots.txt reads User-agent: * / Allow: / with no crawl-delay. This actor paces
itself at 2 requests/second anyway, with a contact User-Agent. The rate is not an input
— a buyer cannot dial it up.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Portfolio company record (portfolio-company-record) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price:
- 4 portfolio company records: $0.02 start + 4 × $0.05 = $0.22
- 25 portfolio company records: $0.02 start + 25 × $0.05 = $1.27
- 100 portfolio company records: $0.02 start + 100 × $0.05 = $5.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 512 MB.
Yield on the sample run: CAPPED: parsed=10/917 (1.1%); maxCompanies=10 bounded the sweep to the first 10 of 917 companies in the order NEA's sitemap lists them | matched=3 | coverage=10/917 complete=False | portfolio-company-.
⚖️ Legal & ToS
This actor reads public, logged-out pages and feeds published by www.nea.com. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. The source (www.nea.com) is read logged-out; the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other VC portfolio reports actors?
A: Same output shape and billing model; this one covers www.nea.com. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source (RATE_PER_SEC=2.0, MIN_INTERVAL=1.0) and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Fewer rows than expected → the source had fewer items in scope → widen the input.
- Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- General Atlantic Investments Report — Target Book — Filtered, normalized target book of General Atlantic's published investments, with coverage stated and a source link per company
- USPTO Trademark Portfolio Report — One priced report that watches your whole trademark family for the two deadlines that cost clients marks: the 30-day opposition window and the §8/§9…
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


