

Website Contact Finder — Email, Phone & Social Links
Pricing
from $33.50 / 1,000 website contact checks
Website Contact Finder — Email, Phone & Social Links
Find business emails, phone numbers, and social profile links published on company websites. Submit domains or URLs and pay only when a contact-bearing result is delivered.
Pricing
from $33.50 / 1,000 website contact checks
Rating
0.0
(0)
Developer
NexGen Watch
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
🌐 Website Contact Finder — Email, Phone & Social Links
Turn company domains into business contact records for lead routing, account research, and CRM enrichment. Submit one domain or a batch and receive the contact details each company publishes on its own website:
- business email addresses
- phone numbers exposed through telephone links
- LinkedIn, X, Facebook, and Instagram profile links
- the final origin, pages fetched, and robots coverage for each check
The Actor reads only public pages on the buyer-supplied website. It does not log in, search for private individuals, or enrich contacts from third-party profiles.
Output is one website_contact_check row per result; billing is pay-per-event, the value event being one website contact check (a $0.02 start fee per run, then $0.05 per website contact check).
No login, no API key and no CAPTCHA solving are involved: the source is read logged-out with an identified contact User-Agent.
📊 Sample Output
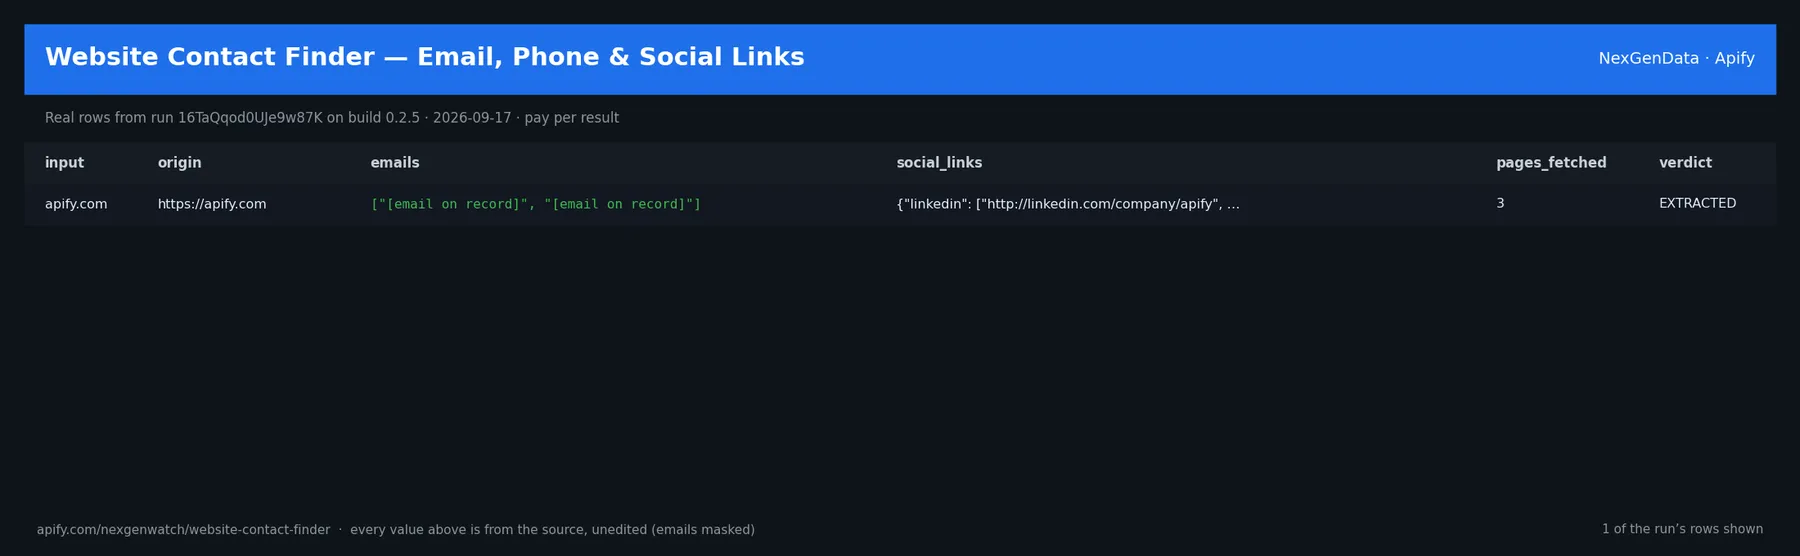
Real rows from run 16TaQqod0UJe9w87K on build 0.2.5 (2026-09-17), the same input as the Quick start below — every value is as the source published it (emails masked, long text shortened):
| input | origin | emails | social_links | pages_fetched | verdict |
|---|---|---|---|---|---|
| apify.com | https://apify.com | ["[email on record]", "[email on record]"] | {"linkedin": ["http://linkedin.com/company/apify", "https://www.linked | 3 | EXTRACTED |
The run finished with the status message: NORMAL: 1 contact-bearing, 0 no-contact (0 not-found, 0 ambiguous, 0 service-fault, 0 unparseable) of 1 | billable=1 | website_contact_check charged=1, delivered=1
✅ What you get
Each row is flat JSON with these fields (from the dataset schema and the sample run; a field the source does not publish for a given row is null):
record_type(string/null) — e.g.website_contact_checkinput(string/null) — e.g.apify.comorigin(string/null) — e.g.https://apify.comsource(string/null) — e.g.buyer-supplied website, robots-permitted pages only (own fetch; no third-party Aemails(array/null) — e.g.["[email on record]", "[email on record]"]phones(array/null) — null in every sample rowsocial_links(object/null) — e.g.{"linkedin": ["http://linkedin.com/company/apify", "https://www.linkedin.com/compages_fetched(integer/null) — e.g.3pages_blocked_by_robots(array/null) — null in every sample rowrobots_status(string/null) — e.g.loadedverdict(string/null) — e.g.EXTRACTEDcoverage_summary(string/null) — e.g.fetched 3 permitted page(s); 0 path(s) robots-blocked; robots=loadedunbilled_reason(string/null) — null in every sample row
Output
Every completed website read has an explicit verdict:
EXTRACTED— at least one email, phone number, or supported social profile was found.NO_CONTACTS— permitted pages were fetched successfully, but none of those contact details was found.ROBOTS_BLOCKED,SSRF_BLOCKED,SERVICE_FAULT, orUNPARSEABLE— the website could not be checked safely or reliably.
An EXTRACTED record includes emails, phones, social_links, pages_fetched, robots_status, and a
coverage_summary. A NO_CONTACTS record reports the completed zero honestly instead of pretending that a
contact was delivered.
⚙️ Sample inputs
1. Quick start — the Store example (this is what the sample above came from)
The sample run charged exactly: 1 × $0.02 apify-actor-start + 1 × $0.05 website_contact_check = $0.07 on the Free tier — every delivered row was billed.
2. A smaller, narrowed run
A bounded run for checking the field shape before scheduling.
3. A full-size run
The same input run on a schedule; each run is billed only for what it delivers.
🧾 JSON sample record
One real record from run 16TaQqod0UJe9w87K, exactly as it lands in the dataset (emails masked, long text shortened):
🔧 How it works
Transport. Plain HTTPS from the Apify platform, no proxy. robots.txt is read first and a disallowed path is never fetched. Every request carries an identified contact User-Agent.
Charging. Each website contact check is charged at the moment it is pushed (website_contact_check); a row that fails to charge is not delivered, so the dataset count always equals the charged count.
Responsible collection
The Actor honors robots.txt before each target-page fetch and refuses private, loopback, link-local, and
cloud-metadata addresses. It returns business or organizational details published on the company's own
site; it is not a person-discovery product. Inputs are not retained beyond the run.
What is not done. No login, no cookie or CAPTCHA bypass, no private or personal-account data, no browser automation.
💰 Pricing example
| Event | Free | Bronze | Silver | Gold |
|---|---|---|---|---|
Actor Start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Website contact check (website_contact_check) | $0.05 | $0.04 | $0.04 | $0.03 |
Worked at the live Free-tier price:
- 1 website contact checks: $0.02 start + 1 × $0.05 = $0.07
- 25 website contact checks: $0.02 start + 25 × $0.05 = $1.27
- 100 website contact checks: $0.02 start + 100 × $0.05 = $5.02
A run that delivers zero rows charges the $0.02 start fee only. A BLOCKED run (source refused) fails loud and charges no value event. The start fee is charged once per GB of run memory; the default run memory is 1024 MB.
Yield on the sample run: NORMAL: 1 contact-bearing, 0 no-contact (0 not-found, 0 ambiguous, 0 service-fault, 0 unparseable) of 1 | billable=1 | website_contact_check charged=1, delivered=1.
⚖️ Legal & ToS
This actor reads public data only. It collects only what the source publishes to any visitor, keeps to the source's robots rules (checked on every run), identifies itself with a contact User-Agent, and does not access accounts, private data or anything behind authentication. Use the output in line with the source's terms and your local law; the intended use is B2B research and monitoring.
❓ FAQ
Q: Do I need an API key or a login?
A: No. the input schema has no key field and the actor carries no secrets.
Q: Why did my run return 0 rows?
A: Read the run's status message. GENUINE_EMPTY means the source was read and had nothing in scope for your input; BLOCKED means the source refused and the run failed without billing a value event — retry later or narrow the input. A zero-row run bills the start fee only.
Q: How fresh is the data?
A: Every run reads the source live at run time; nothing is cached between runs. Put it on a schedule for a continuous feed.
Q: What formats can I export?
A: The dataset downloads as JSON, CSV, Excel, XML or RSS from the run's Dataset tab or the Apify API, and any run can push to a webhook or integration.
Q: How is this different from the other web QA and enrichment tools actors?
A: Same output shape and billing model; this one covers Website Contact Finder — Email, Phone & Social Links. The siblings under Related Actors cover the other sources or slices — run several on one schedule for a combined feed.
Q: Are there rate limits?
A: The actor paces itself against the source and honours its robots rules; there is no per-buyer limit beyond your Apify plan's concurrency.
🆘 Troubleshooting
- Run FAILED with BLOCKED → the source refused the request or changed its page shape → nothing was billed beyond the start fee; retry after a while, and if it persists open an Issue with the run id.
- Fewer rows than expected → the source had fewer items in scope → widen the input.
- Input validation error on start → a field is outside the schema's allowed values → start from the Quick start block and change one field at a time.
- Run TIMED-OUT → a very wide request on a slow day → raise the run timeout in Run options or narrow the input; what was delivered before the timeout is still in the dataset.
🔗 Related Actors
- Tech Stack Detector — Website Technology Lookup — Detect technologies used by websites across exactly 255 supported CMS, ecommerce, analytics, marketing, hosting, CDN, payment, and framework fingerpr…
- Tech Stack Enricher — Give it a list of company domains; it returns one CRM-ready record per domain describing
- Website Brand Kit API — Extracts a full brand system from a domain — logos, favicons, declared and pixel-derived colors, font declarations, theme color and social share imag…
- Website Migration Link Auditor — Audits an old→new URL migration manifest. Each source URL gets an acceptance receipt: redirect target/chain/loop, 404/410/5xx, fragment survival, can…
- Website Screenshot Evidence API — Captures a headless-Chromium screenshot of each URL as a hashed evidence bundle — the image plus its final URL, HTTP state, capture timestamp, browse…
- Website Technology Detector — Fingerprints the technologies a website exposes on the pages its robots.txt permits — web server, CDN, CMS, JavaScript frameworks, analytics and mark…
- 🏢 About NexGenData — NexGen Watch is NexGenData's fleet of 256 public monitoring and lookup actors built on official sources, pay-per-result. Browse the catalog at apify.com/nexgenwatch.
⭐ Found this useful?
If this actor saved you a manual check, a quick review on the Apify Store helps other teams find it. Feature request or a source that changed? Open it from the Issues tab — every one is read.


