
Reddit Scraper | Posts, Comments and Subreddits
Pricing
from $1.20 / 1,000 results
Reddit Scraper | Posts, Comments and Subreddits
Scrape any subreddit past the 1,000-post limit, full comment threads with hidden replies, and comments by keyword. Get posts, comments, communities and users with engagement metrics and lead signals on every row: help requests, pain points, product mentions, intent and sentiment. No login.
Pricing
from $1.20 / 1,000 results
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
1
Bookmarked
16
Total users
1
Monthly active users
7 days ago
Last modified
Categories
Share
Reddit Scraper (reddit.com) | Posts, Comments, Subreddits and Users (2026)
From SilentFlow. Creators of Pinterest Scraper and Leboncoin Scraper, with 420,000+ combined lifetime runs.
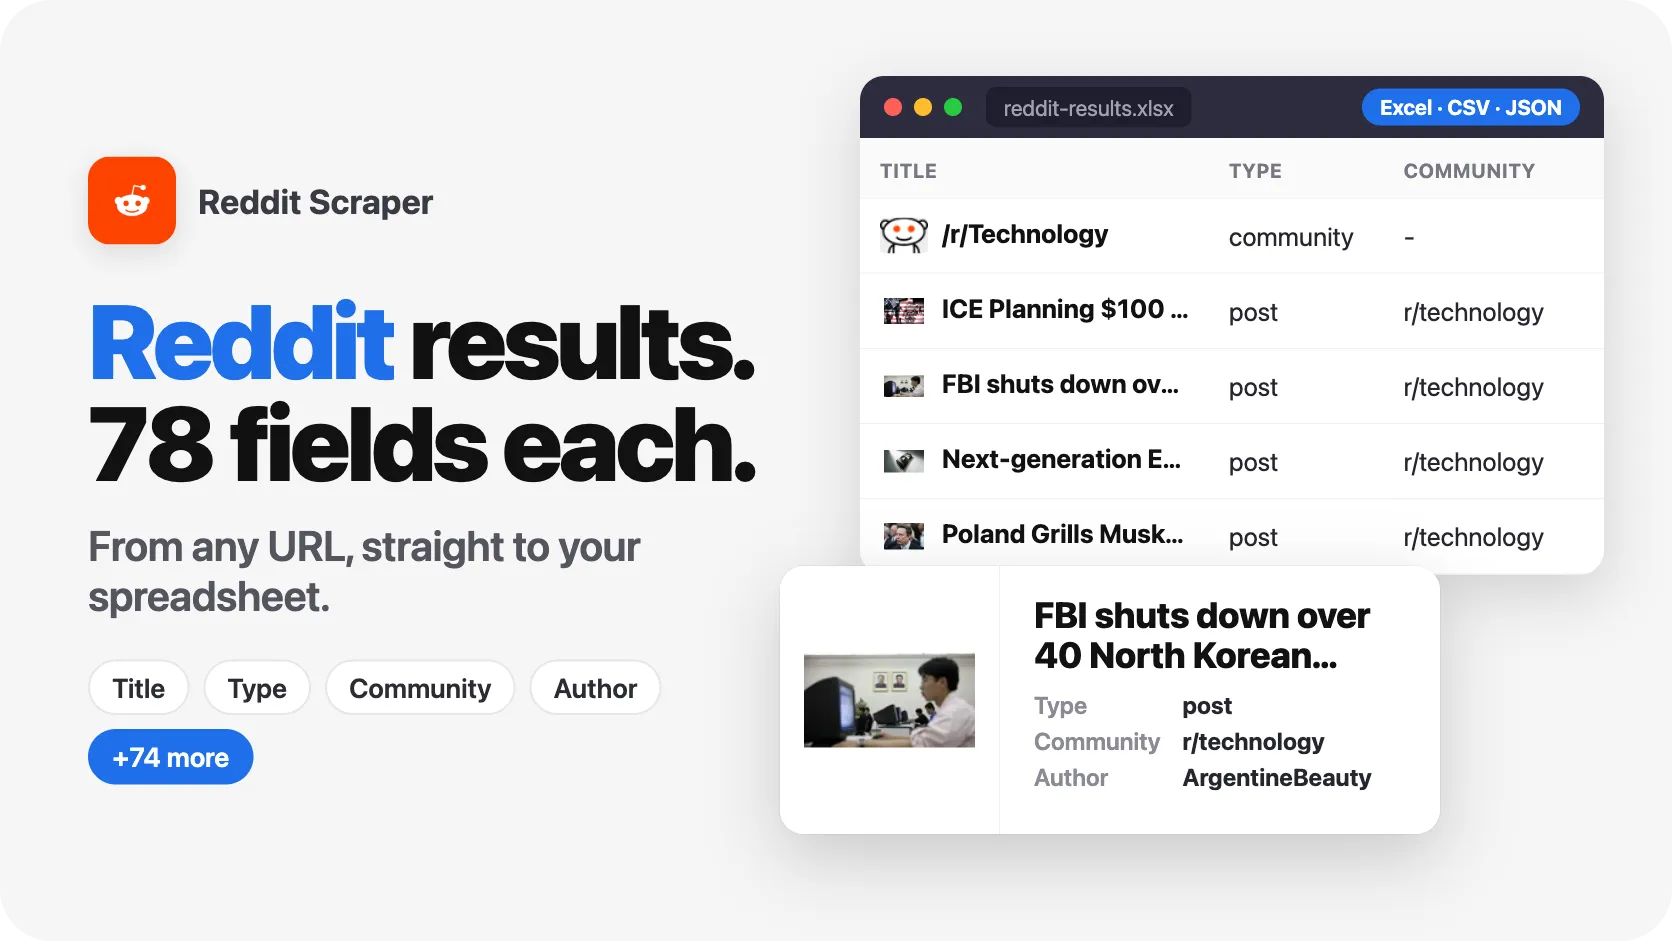
Every post, comment and community Reddit still serves, as clean rows you can sort, filter and feed to a model, with the leads already flagged. A whole subreddit, 2,568 posts, in under three minutes.
Why choose this actor?
Stuck with the first 1,000 posts of a subreddit? Copying replies one "load more" at a time? Reading threads for hours to find the three people asking for a tool like yours?
- The whole subreddit, not the first page. Reddit shows about 1,000 posts per listing. This actor merges every order and time window without duplicates: 2,568 unique posts from r/sydney, where the newest listing alone gives 977.
- Whole threads, hidden replies included. Set comments per post to 0 and you get every comment Reddit still serves: 2,146 comments from one large AskReddit thread in 44 seconds, nine reply levels deep.
- Search the comments, not just the posts. The answer is usually in a comment. Search comments by keyword and get each one with its post title, score and community: 35 comments for "vpn for travel" in 20 seconds.
- 104 fields per post, 70 per comment, 171 distinct fields in all. Media, galleries, flairs, moderation status, edit dates, community size, author flair, plus engagement metrics computed on every row.
- Leads flagged on every row. Each post and comment says whether it asks for a tool, complains, mentions a price, offers to pay, requests a feature or names a competing product, with an intent and a sentiment. Filter, then read only the rows that matter.
- No account, no API key, no cookies. Paste a URL or a keyword and run.
Try your first subreddit
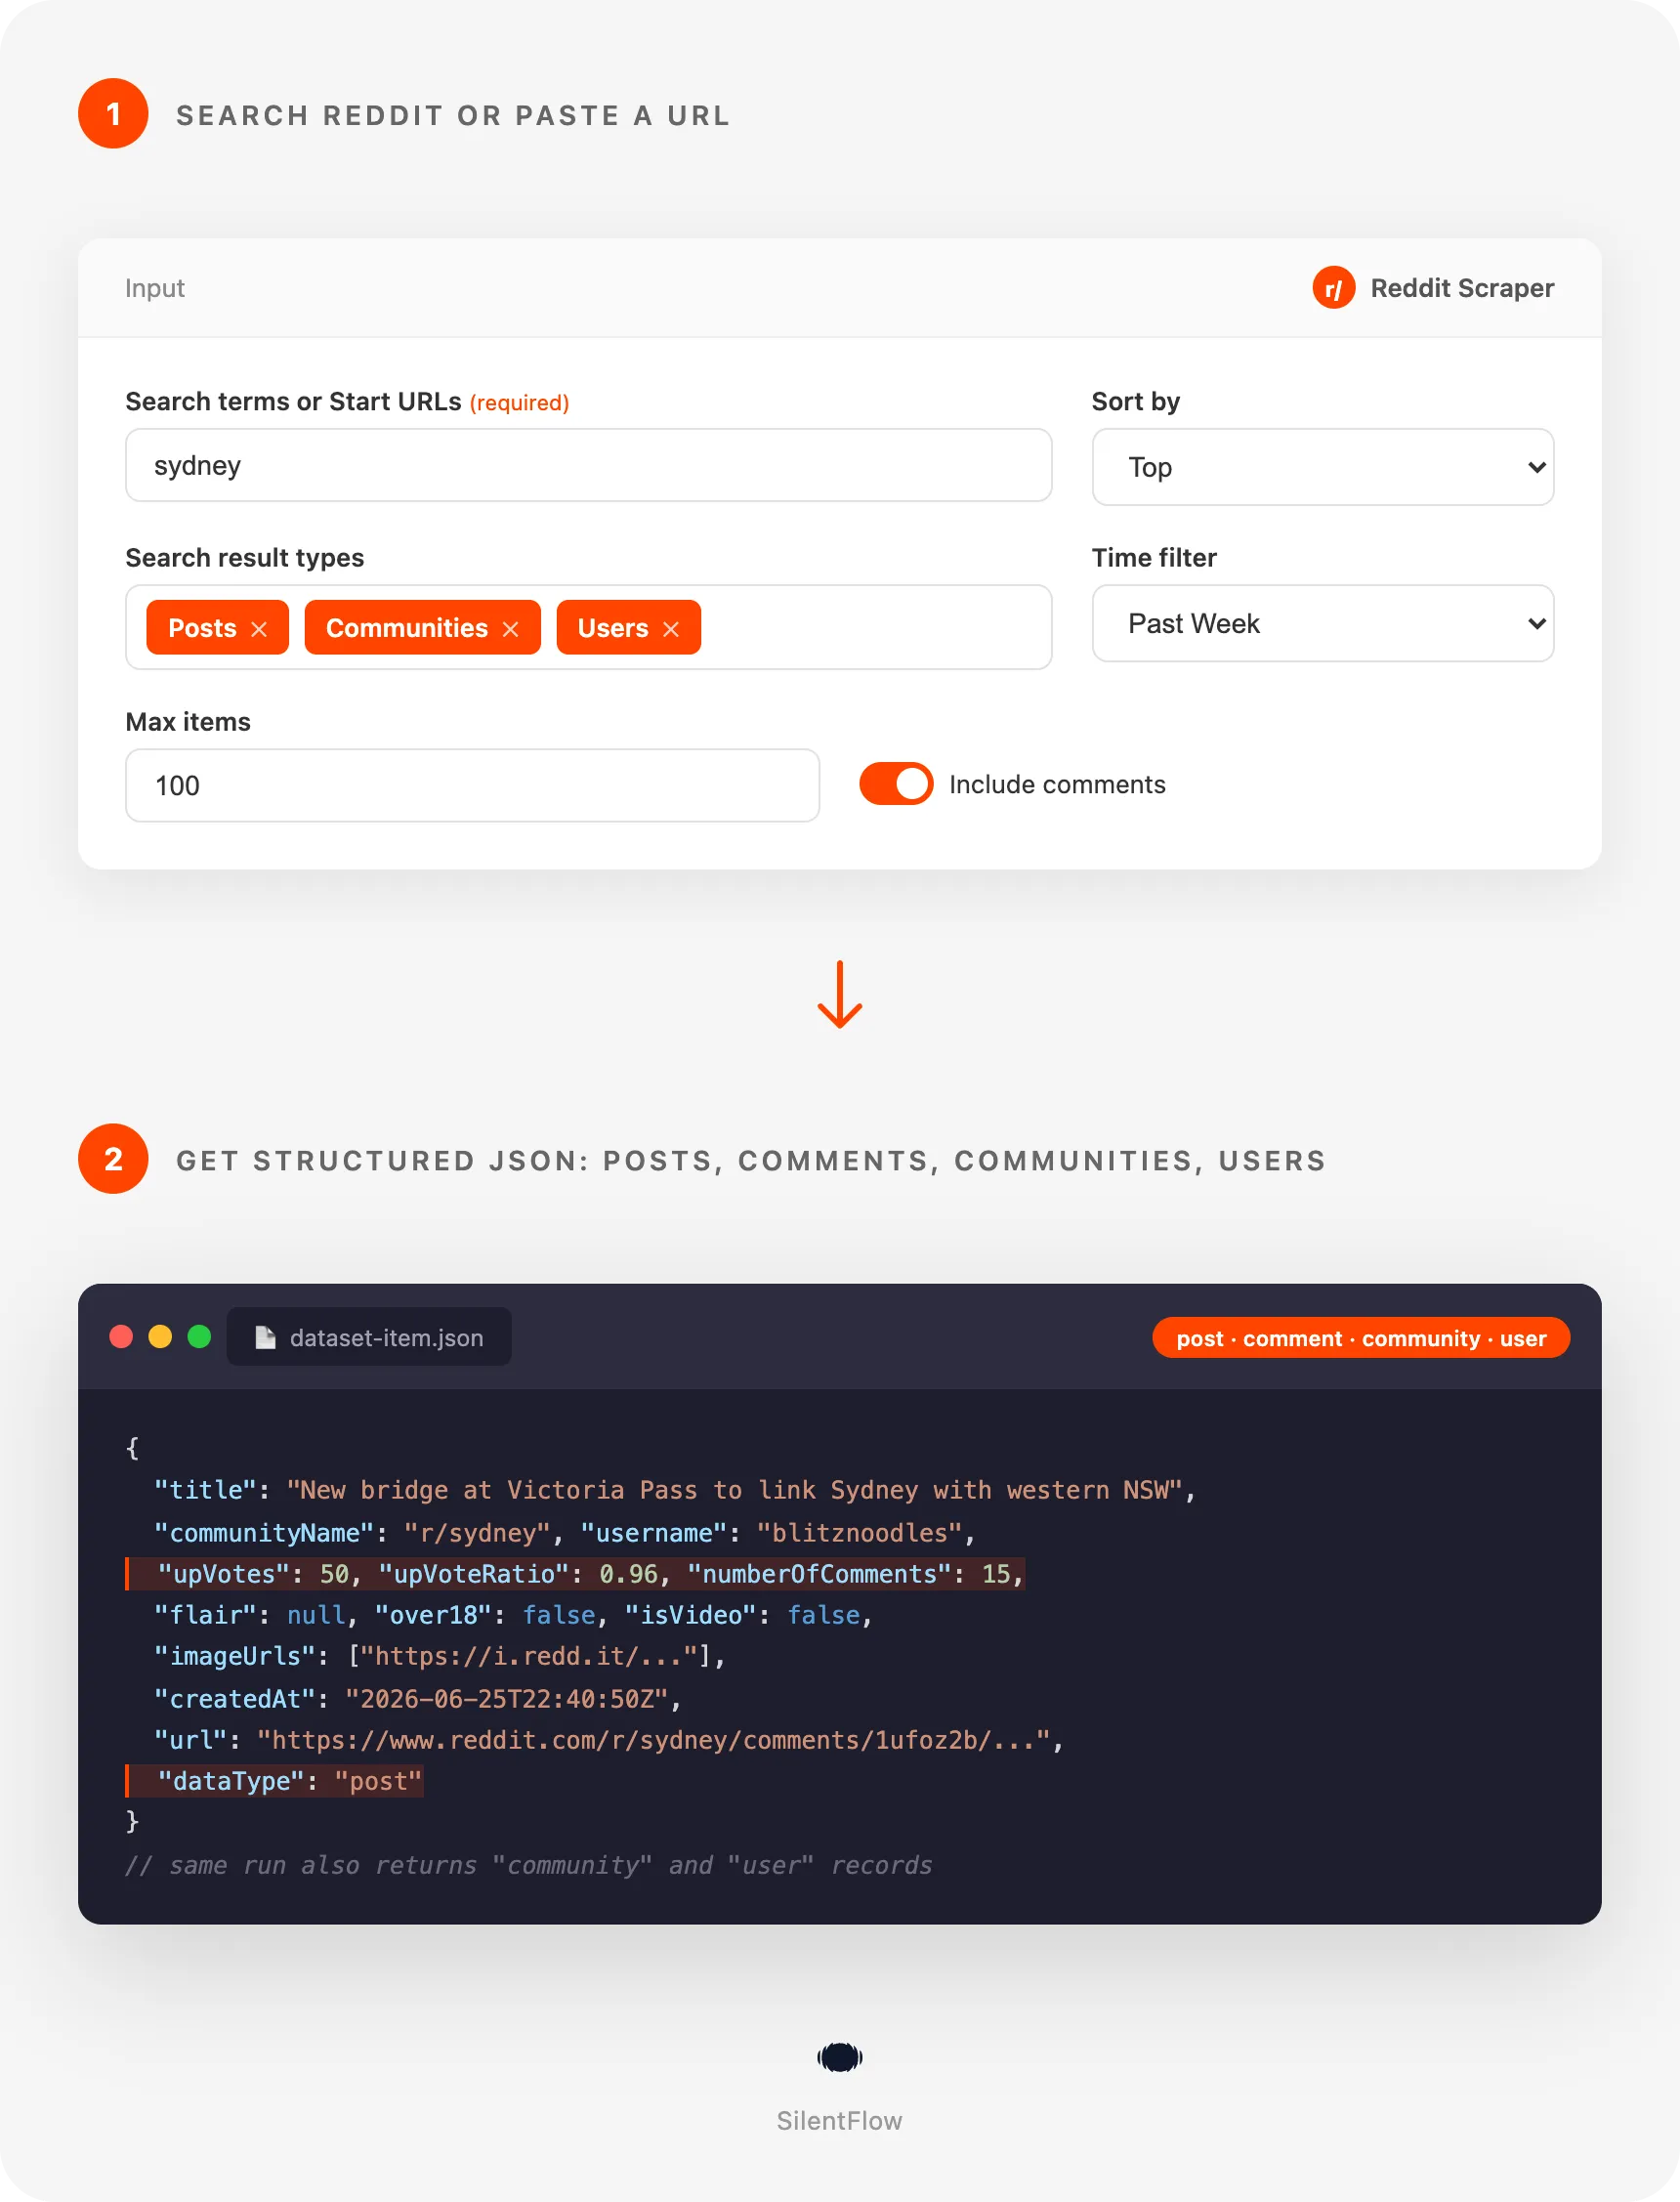
Paste this input in the Input tab, or call it from the API, and run. You get the community, its latest posts and their comments, 50 rows in all.
The free Apify plan is enough to run it: no credit card, no Reddit account.
| SilentFlow · Reddit suite | |
 Reddit Scraper You are here |  Reddit Scraper Comments, Posts and Users |
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it full context about this scraper:
How to scrape Reddit posts and comments
Get the latest posts of a subreddit with their comments
Posts and their threads arrive together: a few posts, then their comments, then the next posts, so a small run still gives you full conversations.
Find the comments that ask for a tool like yours
Then filter the dataset on wantsHelp or mentionedProducts, or open the Lead signals view.
Download a whole subreddit for a date range
Input parameters
| Parameter | Type | Default | What it does |
|---|---|---|---|
startUrls | array | Subreddits, posts, user profiles, Reddit search pages | |
searches | array | Keywords searched across Reddit | |
searchTypes | array | ["posts"] | posts, comments, communities, users |
maxItems | integer | 50 | Total rows for the run, no fixed limit |
searchCommunityName | string | Limit searches to one subreddit | |
sort | string | new | relevance, hot, top, new, rising, comments |
time | string | all | all, hour, day, week, month, year |
fullSubreddit | boolean | false | Every order and time window of a subreddit, merged without duplicates |
includeComments | boolean | true | Comments of every post found |
maxCommentsPerPost | integer | 100 | Comments kept per thread, 0 for the whole thread |
postDateLimit | string | Posted on or after (YYYY-MM-DD) | |
postedBefore | string | Posted on or before (YYYY-MM-DD) | |
flair | string | Posts with this flair (not case sensitive), * for any flair | |
includeNSFW | boolean | true | Include 18+ posts and communities |
Accepted URLs:
- Subreddit:
https://www.reddit.com/r/technology/, or a sorted listing such ashttps://www.reddit.com/r/technology/top/ - Post:
https://www.reddit.com/r/AskReddit/comments/1wzbc6m/ - User profile:
https://www.reddit.com/user/spez/(profile and submitted posts) orhttps://www.reddit.com/user/spez/comments/ - Search page:
https://www.reddit.com/search/?q=vpn - Popular:
https://www.reddit.com/r/popular/, and the community leaderboard
When a run has several search types, they are filled in this order: posts, comments, communities, users. Raise maxItems or run one type at a time to get each in full.
What data can you extract from Reddit?
Every row has a dataType. The fields are flat, named the way Reddit tools usually name them, with RFC 3339 dates and null when Reddit gives no value.
| Row | Fields | What they cover |
|---|---|---|
post | 104 | identity and links, title and text, author and author flair, community and its size, score, upvotes, estimated downvotes, upvote ratio, comments, crossposts, awards, status (locked, pinned, spoiler, archived, edited, removed), media (type, every preview resolution, gallery images, video duration, outbound link and its host) |
comment | 70 | identity and permalink, text, author, depth, parent and parent type, direct replies (loaded or hidden), whether the author wrote the post, controversiality, status, plus the title, URL, score and comment count of its post |
community | 44 | name, title, members, active users, type, language, descriptions, sidebar, submission rules (images, videos, galleries, polls), flair and spoiler settings, icons and banner, and the community rules with their descriptions |
user | 32 | post, comment, awardee, awarder and total karma, account age, gold, moderator and employee flags, verified email, avatar, profile title, bio, banner and followers, previous usernames |
Computed on every post and comment: ageHours, scorePerHour, commentsPerHour, engagementTotal (score + comments + crossposts), commentToScoreRatio, isHighEngagement (10 points an hour or 500 interactions), wordCount, titleLength, bodyLength.
Detected signals on every post and comment: wantsHelp, hasPain with the painPoint sentence, mentionsPrice, willingToPay, featureRequest, isVendor, isOwner, mentionedProducts, intent (question, recommendation_request, complaint, promotion, discussion), sentimentScore from -1 to 1 and sentimentLabel, and lang. They are keyword rules, the same result on every run; sentiment is computed for English text and left null otherwise.
Run context: searchTerm (the keyword that found the row), position (order in the run), source (listing, whole subreddit, post, thread, search, comment search, profile).
Stable and permanent: id (Reddit's own identifier, t3_ for posts, t1_ for comments) and url never change. Image links from Reddit's preview servers can expire after some weeks; download what you need to keep.
Output example
A post (long values shortened):
A comment from the same run:
Advanced usage
Build a lead list from people asking for recommendations
Keep the rows where wantsHelp is true and isVendor is false: these are buyers, not sellers.
Track complaints about a competitor
Archive a community every month
Schedule it on the first day of each month in Apify Schedules. Duplicates never appear inside a run, and the id field lets you merge months without double counting.
Measure how a subreddit feels about a topic
Send the results to Google Sheets, Slack or your CRM
Every run's dataset exports to JSON, CSV, Excel, XML and HTML from the Storage tab, or from the API:
Add the Google Sheets, Slack, Zapier, Make or n8n integration in the Integrations tab of a run or a schedule, or point a webhook at your own endpoint: new rows reach your tool after each run, no code needed.
FAQ
What does this Reddit scraper extract? Posts, comments, communities and user profiles, one row each, with up to 104 fields per post and 70 per comment, plus engagement metrics and detected lead signals.
Do I need a Reddit account or an API key? No. It reads public Reddit pages only, the way a visitor sees them. No login, no API key, no cookies.
How do I get more than 1,000 posts from a subreddit? Turn on Whole subreddit. Every listing order and time window is read and merged without duplicates. On an active community that means several thousand posts (2,568 on r/sydney). Very old posts that no listing shows any more stay out of reach.
Why do I get fewer comments than the count Reddit displays? Reddit's count includes deleted and removed comments that it no longer serves. You get every comment that is still there, hidden replies included when comments per post is 0.
Can I search comments by keyword? Yes. Add a search term and choose Comments in Search for. Each comment comes with the title, URL, score and comment count of its post. Add a community to search only there.
Are the signals made by AI? No. They are keyword rules on the title and text: free, instant and identical from one run to the next. They point you to the rows worth reading; they do not replace reading them.
Can I combine filters?
Yes, they stack. A subreddit URL with Whole subreddit, Posted after 2026-07-01, Posted before 2026-09-30 and flair Discussion returns only the discussion posts of that quarter, with their comments if you keep them on.
How fresh is the data? Every run reads Reddit live at that moment. Nothing is cached, so scores and comment counts are those of the run time.
Can I scrape several subreddits or keywords in one run?
Yes. Add as many URLs and search terms as you like; maxItems is the total for the run.
Will my existing tasks and integrations keep working? Yes. Every input and every field name from earlier versions is unchanged; new fields are added alongside them.
What is Reddit? Reddit is a network of more than 100,000 active communities (subreddits) where people post links, text and media and discuss them in threaded comments. It is one of the largest sources of first-hand opinions about products, services and markets.
More SilentFlow scrapers
🛒 E-commerce
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 Leboncoin - Leboncoin Ad Details Scraper
 Back Market - Back Market Scraper | Refurbished Prices
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 1688 Wholesale - 1688 Wholesale Scraper
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 Udemy Course - Udemy Course Scraper
 JD - JD Products Scraper | Prices, Brands and Barcodes
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Bring a Trailer - Bring a Trailer Scraper
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Store Leads - Store Leads Scraper | Shopify Data
 Avito - Avito Scraper | Listings, Prices and Sellers
 Leboncoin - Leboncoin Scraper
 Mobile.de - Mobile.de Scraper
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 Taobao - Taobao Scraper | Products, Prices and Sellers
 Udemy - Udemy Scraper
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 eBay Marketplace - eBay Marketplace Scraper
 Europages - Europages Scraper | Suppliers and B2B Companies
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Vinted Marketplace - Vinted Marketplace Scraper
 Walmart - Walmart Product Scraper
 Alibaba - Alibaba Scraper | Products, Prices and Suppliers
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 Pinterest - Pinterest Scraper
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted - Vinted Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 Dice Tech - Dice Tech Jobs Scraper
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Jora - Jora Jobs Scraper
 Malt Freelancer - Malt Freelancer Scraper
 Malt - Malt Scraper | Freelance Profiles
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Glassdoor - Glassdoor Jobs Scraper
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Zillow - Zillow Scraper
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 TikTok - TikTok Scraper
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 Instagram Engagement - Instagram Engagement Scraper
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Profile Scraper
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 OnlyFans - OnlyFans Creator Scraper
 Skool Community - Skool Community Scraper
 Bilibili - Bilibili Scraper
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 LinkedIn Event - LinkedIn Event Scraper
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Skool Group - Skool Group Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Teachable Course - Teachable Course Scraper
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
 Website Tech Stack - Website Tech Stack Scraper
✈️ Travel
 Google Maps - Google Maps Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Flight Price - Flight Price Scraper
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
🎯 Lead generation
 Northdata - Northdata Company Scraper
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 UK Companies House - UK Companies House Enricher
 Dealroom - Dealroom Scraper | Companies and Investors
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Google Ads Transparency - Google Ads Transparency Scraper
 SIRET - SIRET Company Enricher
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 SEC - SEC Scraper | EDGAR Filings and Company Data
 USPTO - USPTO Scraper | Trademark Search and Status
 ZocDoc - ZocDoc Scraper
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 Dealroom Startup Data - Dealroom Startup Data Scraper
 G2 - G2 Reviews Scraper
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 PagesJaunes - PagesJaunes Business Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Google News - Google News Scraper
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
📈 Marketing
 Pexels -
🧰 More tools
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This Actor extracts publicly available data from Reddit. It does not bypass any login, paywall or CAPTCHA, and it never reads private communities. Users are responsible for complying with Reddit's terms of service and applicable data protection laws (GDPR, CCPA and similar). The output contains usernames and the text people posted: treat it as personal data where those laws apply. The data is informational; verify it before using it in regulated decisions.
Reddit Scraper is maintained by SilentFlow and is not affiliated with Reddit, Inc.


