
Reddit Search Scraper: Keyword & Subreddit Posts
Pricing
Pay per usage
Reddit Search Scraper: Keyword & Subreddit Posts
Search Reddit by keyword, subreddit or author and get full post data: title, text, upvotes, comment count, author, flair, images and video. Run hundreds of searches in one job and tag every result with your own ID. No login or API key. Pay-per-result pricing from 17 Oct 2026.
Pricing
Pay per usage
Rating
0.0
(0)
Developer
GoFetch
Maintained by CommunityActor stats
1
Bookmarked
8
Total users
7
Monthly active users
10 hours ago
Last modified
Categories
Share
Reddit Search Scraper finds keyword & subreddit posts on Reddit, plus any author's posts, and returns full post data: title, text, upvotes, comment count, author, subreddit, flair, images and video links. Put as many searches as you need into one run and tag each one with your own ID (profileUrl). Every result comes back labelled with the brand, person or topic it belongs to, ready to export as JSON, CSV or Excel or to pull through the Apify API.
It runs Reddit's own search over plain HTTP. There's no browser, no Reddit login and no API key. Requests go through the Apify residential proxy, preconfigured, so there's nothing to set up.
Use cases
- Brand monitoring for many clients: an agency keeps one daily task with a search per client brand, each tagged with the client's CRM URL as
profileUrl. Withsort: "new"andsearchTime: "day", every new mention arrives already attached to the right client. - Product and market research: a product team runs
subreddit:searches in the communities its users read, sorted bytopover the past year, and reviews the highest-voted complaints and feature requests in a spreadsheet. - Leads and pain points: a SaaS founder searches phrases such as
"looking for a tool"or"alternative to"for their category and gets a daily list of posts where people ask for a recommendation. - Social listening and research datasets: analysts follow tickers, coins, campaigns or public figures, or collect a year of public posts on a topic, splitting busy searches per subreddit to get past Reddit's ~250-post cap.
Why use this Reddit scraper?
- Hundreds of searches in one run. Each search carries your own
profileUrl, so a single job can monitor hundreds of brands or people and send every post back to the right record. - Light. In a platform test at 512 MB, 20 searches returned 820 posts in about 3 minutes, with peak memory around 72 MB.
- Tested on the Apify residential proxy. In that test every search completed, with votes and comment counts on all 820 posts. The proxy is preconfigured.
- Pay only per result. From 17 October 2026, platform usage and proxy are included, with no start fee and no extra events.
- Clear run outcomes. A blocked run fails with a machine-readable code instead of quietly returning an empty dataset.
What data you get
Each Reddit post is one flat dataset item with these 18 fields:
| Field | Type | Description |
|---|---|---|
profileUrl | string | Your ID from the search that found this post |
id | string | Reddit post ID, t3_… |
dataType | string | Always "post" |
title | string | Post title |
url | string | Link to the post, https://www.reddit.com/r/…/comments/… |
createdAt | string | Creation time in ISO 8601, UTC |
upVotes | integer or null | Post score (upvotes), or null when unknown |
numberOfreplies | integer or null | Number of comments on the post, or null when unknown |
communityName | string | Subreddit, as r/name |
username | string | Author's username, or [deleted] when the account no longer exists |
body | string or null | Post text, or null for link, image and video posts without text |
userId | string or null | Author's ID, t2_…, or null |
flair | string or null | Post flair |
thumbnailUrl | string or null | Thumbnail image URL |
imageUrls | array | Direct and gallery image URLs, or empty. Link and video post previews aren't included. |
videoUrl | string or null | Reddit-hosted video URL (null for YouTube and other embedded videos) |
isVideo | boolean | true for Reddit-hosted video posts |
isNSFW | boolean or null | true when Reddit flags the post as adult, or null when unknown |
Only the comment count is collected, not the comments themselves.
How to use Reddit Search Scraper
In Apify Console
- Open Reddit Search Scraper in Apify Store and click Try for free.
- In Search Queries, add one
{ "profileUrl", "searchQuery" }pair per search.profileUrlis your own label, andsearchQueryis what Reddit should search for. Reddit's search operators work here (see Reddit search operators). - Pick a Time Filter and Sort Order, and set Results Per Query (25 by default). Leave the proxy settings as they are.
- Click Start. Posts are saved to the dataset as soon as they're found.
- Open the Output tab and download the posts as JSON, CSV, Excel, XML or HTML, or read them through the API.
From the API
The Actor's ID for the API, clients and agents is xmolodtsov/reddit-scraper. Run it and get the posts back in one call:
JavaScript and Python examples are under Integrations and API.
From an AI agent (MCP)
Add the Actor to any MCP client (Claude, Cursor, VS Code and others) through Apify's MCP server:
Your agent can then call it with the input below, for example "find this week's posts in r/personalfinance about credit card fees". The usual pricing and free-plan limits apply.
How much does it cost to scrape Reddit?
From 17 October 2026 (15:00 UTC), Reddit Search Scraper is priced pay per result. You pay only for posts saved to the dataset. Platform usage and the residential proxy are included, and there's no start fee and no extra events. The price per 1,000 posts depends on your Apify plan:
| Apify plan | Price per 1,000 posts |
|---|---|
| Free | $2.00 |
| Starter (Bronze) | $1.90 |
| Scale (Silver) | $1.80 |
| Business (Gold) | $1.75 |
| Platinum and Diamond | $1.75 (Gold price) |
Examples on a Starter plan:
- 1,000 posts cost $1.90.
- Monitoring 50 brands daily at 20 new posts each comes to about 30,000 posts a month, or about $57. On a Business plan, that's about $52.50.
Is it free?
Until 17 October 2026 (15:00 UTC), the Actor itself is free. You pay only the Apify platform usage of your own runs (compute and residential proxy), which is billed by Apify.
On the Apify Free plan, this Actor allows:
- up to 10 results per run, and
- 5 runs per calendar month per account.
These limits are set by the developer, not by Apify, and they apply both before and after 17 October 2026. Any paid Apify plan removes them. A run that hits a limit ends successfully, with a status message explaining the limit. The monthly count resets on the 1st.
Input
| Field | Type | Default | Description |
|---|---|---|---|
queries | array | required | The searches to run. Each item is { "profileUrl": "...", "searchQuery": "..." }. |
queries[].profileUrl | string | required | Your own ID for this search. It can be any string and is usually a URL. It's copied into every result from this search. |
queries[].searchQuery | string | required | What to search on Reddit. Supports quotes, OR, subreddit:name and author:name. |
searchTime | string | all | Time filter: hour, day, week, month, year or all. |
sort | string | new | Sort order: new, relevance, hot, top or comments. |
includeNSFW | boolean | true | Set to false to leave out posts that Reddit flags as adult. |
searchMode | string | raw | How multi-word searches are combined: raw, exact, and or or (see below). |
searchType | string | posts | posts applies Reddit's posts-only filter, while all searches without it. The output is always posts. |
maxItemsPerQuery | integer | 25 | Maximum posts per search, from 1 to 500. Reddit's search stops at about 250 posts per search. |
maxItems | integer | none | Global cap on posts across all searches. Useful for budget control. On the Apify Free plan, it's capped at 10. |
maxConcurrency | integer | 3 | How many searches run at the same time, from 1 to 5. |
proxyConfiguration | object | Apify residential | The default is preconfigured and is what the Actor is tested on. |
Search modes
| Mode | You enter | Reddit searches for | Use it for |
|---|---|---|---|
raw | Emily Miller | Emily Miller | Reddit's default behavior |
exact | Emily Miller | "Emily Miller" | Exact phrases, person names and usernames |
and | Emily Miller | Emily AND Miller | All words must appear |
or | Taylor Swift | Taylor OR Swift | Any of the words |
Field operators such as author:name and subreddit:name stay as written in every mode; only the other words are quoted or joined. In exact mode, subreddit:personalfinance credit card becomes subreddit:personalfinance "credit card" and author:example_user stays author:example_user.
If a searchQuery already contains AND, OR or NOT, or is wrapped in quotes, it's sent exactly as written, whatever the mode.
Input example
The minimal input is one search:
A fuller example with three searches, each routed to its own record:
Reddit search operators
"exact phrase"matches the words in that order, such as"Acme running shoes".ORmatches any alternative, such asacme OR globex.subreddit:namesearches one community, such assubreddit:personalfinance credit card.author:namereturns one user's posts, such asauthor:example_user.
You can combine operators, for example subreddit:investing "index fund" OR ETF.
Work around the ~250-post cap
Reddit's search stops at about 250 posts per search, so raising maxItemsPerQuery above that won't return more. For busy topics, run more often with a shorter time filter, such as day or hour instead of month. You can also split one broad search into narrower ones, for example one per subreddit.
Output
Here are 8 posts from a real run with 12 keyword searches (sort relevance, past year), shown in a table:
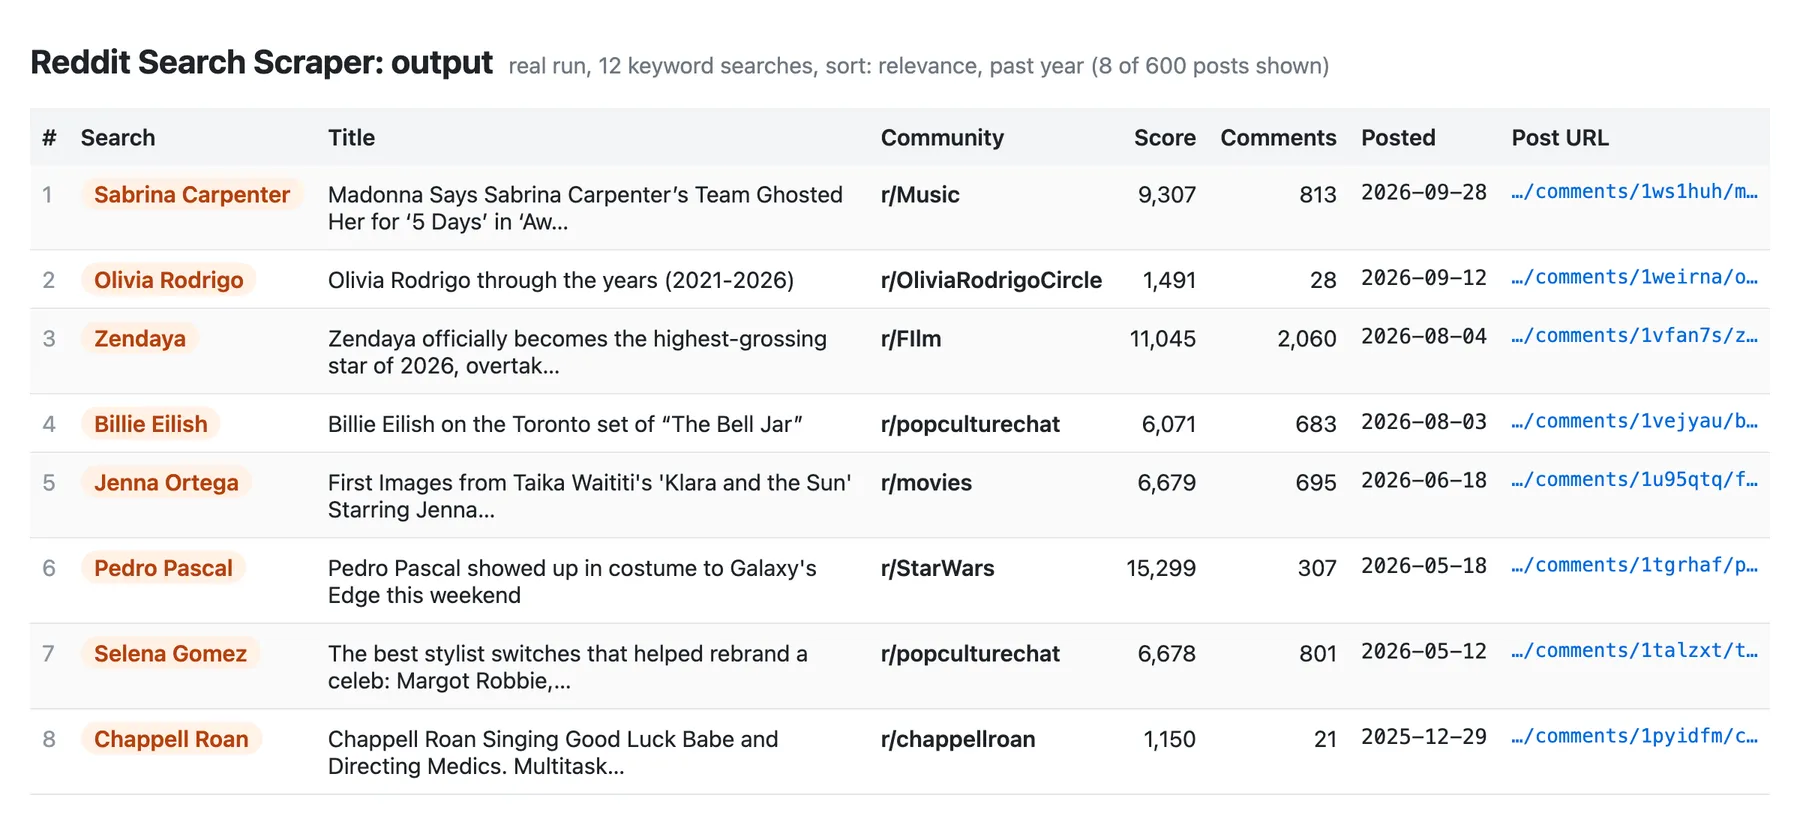
Each post is saved as one dataset item. The values below are illustrative; the field names and types are exactly what you get:
Field names are case-sensitive and stay stable, so existing pipelines don't break (see What data you get for every field). The Overview tab in Console shows profileUrl, title, url, communityName, createdAt and upVotes; the full item has every field.
When does a run succeed or fail?
- A run that saved any posts succeeds, even if some searches failed or an error happened afterwards. Posts already collected are never thrown away.
- A run that saved no posts, where every search got a valid answer from Reddit, also succeeds. Its status message starts with
empty: nothing matched. - A run that saved no posts, where at least one search never got a valid answer, ends FAILED. Its status message starts with the most common cause, such as
blocked,challenge,networkorrate_limited, so an integration can recognize the failure and retry. - Each results page gets several attempts, each on a fresh Reddit session, with growing waits between them, so a brief rejection only slows the run. If Reddit keeps blocking every request, the run fails within about 4–6 minutes.
- When Reddit's rate limit is reached, the run waits for it to reset instead of failing.
- A post never appears twice within one search. If two searches with different
profileUrlvalues match the same post, each gets its own copy. - If the platform moves a run to another server, it resumes and skips the searches that already finished.
Every run also writes two records to its default key-value store:
STATISTICSholds per-run counters: searches processed, succeeded, failed, partial and skipped, total posts saved and run duration.QUERY_RESULTSholds one entry per search with itsprofileUrl,searchQuery,status(success,partial,failedorskipped),postsFound,postsSavedand any error.
Integrations and API
JavaScript and Python clients
For large batches, start an asynchronous run and read the dataset when it finishes. With the JavaScript client:
With the Python client:
Schedules and webhooks
For ongoing monitoring, save your input as a task and give it an Apify schedule. Match the time filter to the schedule: use searchTime: "day" with sort: "new" for a daily run, or searchTime: "hour" for an hourly one on fast-moving topics. Time windows can overlap slightly between runs, so deduplicate downstream on profileUrl plus id, and keep each profileUrl stable from run to run.
Use webhooks to notify your system when a run succeeds or fails. A failed run's status message starts with a code such as blocked or rate_limited, which you can use to decide whether to retry.
Make, Zapier and n8n
Apify's integrations for Make, Zapier and n8n can start this Actor and pass the posts on to Google Sheets, Slack, a CRM or your database without any code.
More scrapers from this developer
TikTok: TikTok Search Scraper: videos and creators for any keyword, pay per result · TikTok Profile Scraper (Pay Per Result): profiles, followers and latest posts by username · TikTok Comments Scraper: comments and full reply threads from any video · TikTok Hashtag Scraper: videos for any hashtag, with views, likes and music · TikTok Sound & Music Scraper: videos that use a sound or song
Social & news: Google News Scraper: Google News results as clean full-text articles
E-commerce: Prom.ua Product Search Scraper: Prom.ua product search results, no browser needed · Amazon Product Search & Bestsellers Scraper: search results, Best Sellers and product details from Amazon
Maps & leads: Google Maps Scraper: places, leads and emails from Google Maps
Ads: Facebook Ad Library Scraper (Meta Ads Library): ads from the Meta Ad Library, with EU reach and payers
Video: YouTube Transcript Scraper: transcripts, subtitles and captions from YouTube videos
FAQ
Is it legal to scrape Reddit?
This Actor collects only posts that are publicly visible on Reddit, and it does so without logging in. It never collects private or deleted content.
Results can include Reddit usernames and user IDs, which are personal data. Laws such as the GDPR and the CCPA may therefore apply to how you store and use them. You're responsible for using the data lawfully and in line with Reddit's terms. Collect only what you need, and keep it secure.
For background, read Apify's article Is web scraping legal?. This is general information, not legal advice.
Do I need a Reddit account, login or API key?
No. The Actor uses Reddit's public search without logging in. You only need an Apify account.
Does it scrape comments?
No. You get each post's comment count in numberOfreplies, but not the comments themselves.
Why are upVotes or numberOfreplies sometimes null?
The Actor reads Reddit's public search feed, which has no votes, comment counts, author IDs, flair or adult flag, and fills those in from Reddit's public post pages. When Reddit limits access to those pages, the fields come back null instead of a made-up 0, and gallery images and video links can be missing too. Treat null as unknown, not as zero. Separately, preview images of link and video posts and videos embedded from other sites, such as YouTube, aren't available this way at all.
Why did a search return fewer posts than I asked for?
Reddit's search stops at about 250 posts per search, and a narrow time filter may hold fewer matching posts than your limit. Turning off includeNSFW, setting a global maxItems or running on the Apify Free plan also reduces the count. The QUERY_RESULTS record shows exactly how many posts each search found and saved.
My run returned no posts or failed. What should I do?
If the run succeeded with an empty status, Reddit answered but nothing matched. Try a broader search, a longer time filter or searchMode: "raw". If the run failed with a code such as blocked, network or rate_limited, no posts were saved and at least one search couldn't get through, so retry the run. Check QUERY_RESULTS to see which searches were affected.
Can I get the newest posts from one subreddit or one user?
Yes. Use subreddit:name as the whole search query with sort: "new" to list a community's newest posts, or author:name to get one user's posts.
Can I use my own proxy?
You can change proxyConfiguration, but the default Apify residential proxy is preconfigured and is what the Actor is tested on. Reddit blocks most datacenter IPs.
Is numberOfreplies a typo?
The lowercase "r" is intentional and stays stable for existing integrations. Field names are case-sensitive, so use it exactly as written.
My integration still sends fastMode. Will it break?
No. Old integrations that send fastMode keep working. The setting no longer has any effect, and every run returns full post data.
Support
Found a bug, or need a field or feature? Open an issue on the Actor's Issues tab in Apify Store. Include the run ID and, for a failed run, the code its status message starts with. That's usually enough to find the cause.


