
Website Meta Extractor
Pricing
from $2.00 / 1,000 page extracteds
Website Meta Extractor
Extract title, meta description, OpenGraph and Twitter tags, headings and canonical URL from any list of web pages.
Pricing
from $2.00 / 1,000 page extracteds
Rating
0.0
(0)
Developer

yck
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 hours ago
Last modified
Categories
Share
Get the SEO and social metadata of any list of web pages in seconds: title, meta description, canonical URL, language, robots directives, OpenGraph and Twitter Card tags, favicon and H1 headings.
What data can you get?
| 🏷️ Title | 📝 Meta description | 🔗 Canonical URL |
| 🌍 Language | 🤖 Robots directives | 🖼️ Open Graph title, description, image |
| 🐦 Twitter Card tags | ⭐ Favicon | 🔠 H1 headings and H2 count |
| ↪️ Final URL after redirects | ✅ HTTP status | 🔑 Keywords meta |
How to use it
- Click Try for free at the top of this page.
- Paste the URLs of the pages (or upload a list).
- Click Start.
- Download the metadata as JSON, CSV or Excel, or read it through the API.
What can it be used for?
- SEO audits – find missing titles, descriptions or canonical tags across a site.
- Link previews – get the title, description and image to render rich link cards.
- Lead enrichment – add a site name, description and logo to a list of company domains.
- Monitoring – schedule it to detect changes in titles or meta tags.
Input
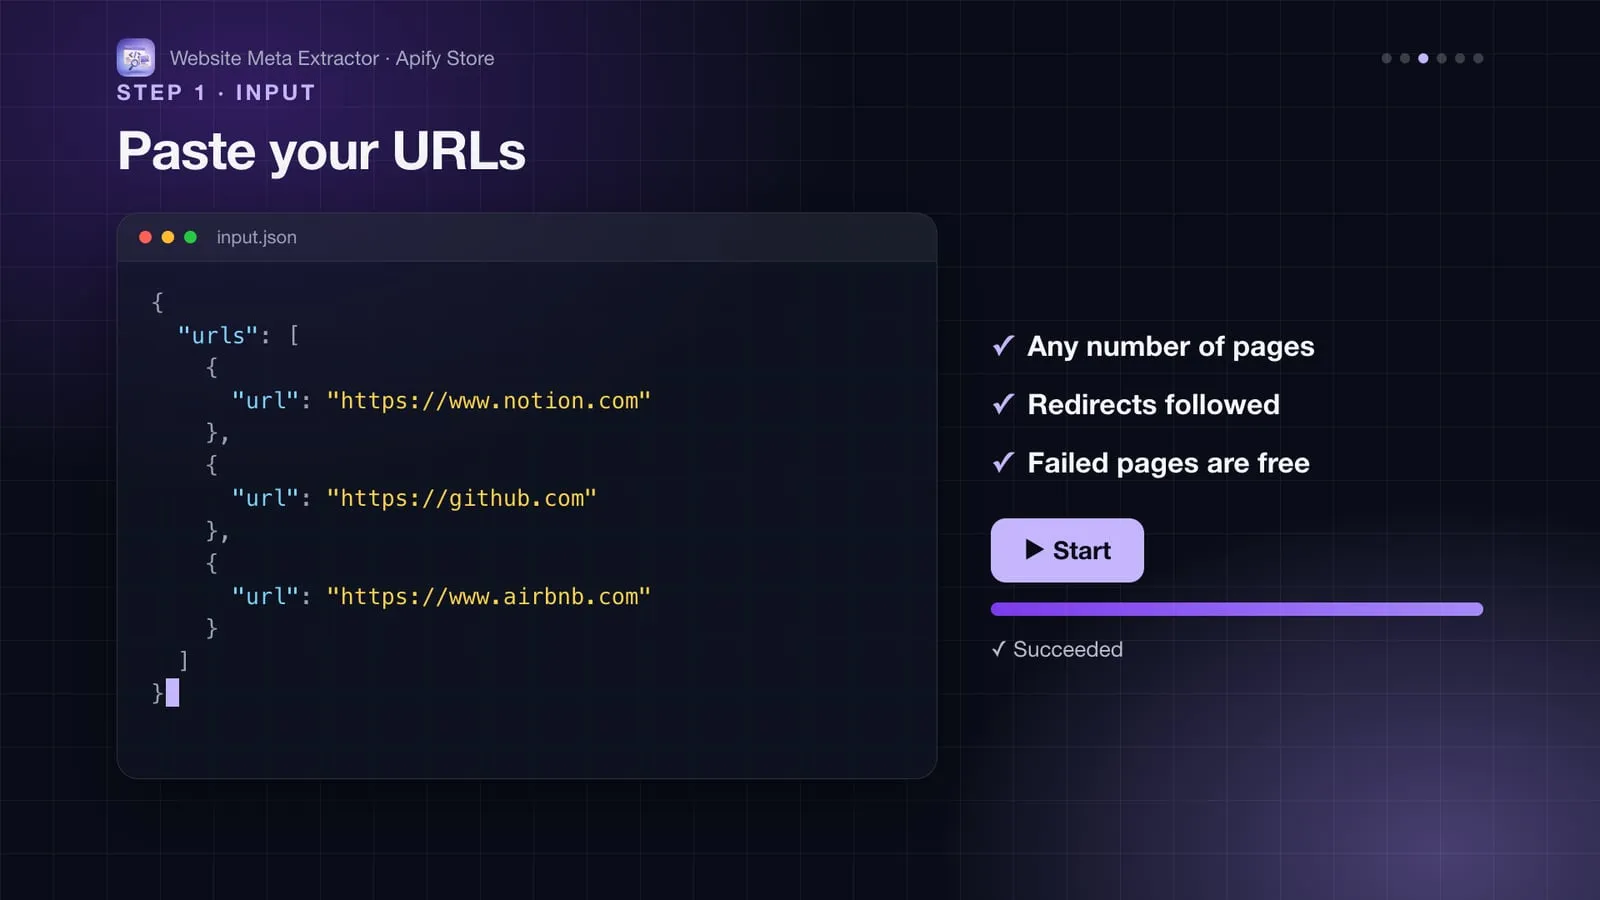
| Field | Description |
|---|---|
urls | List of pages to process (required). |
maxConcurrency | Pages fetched in parallel (default 5). |
timeoutSecs | Per-page timeout in seconds (default 20). |
Output
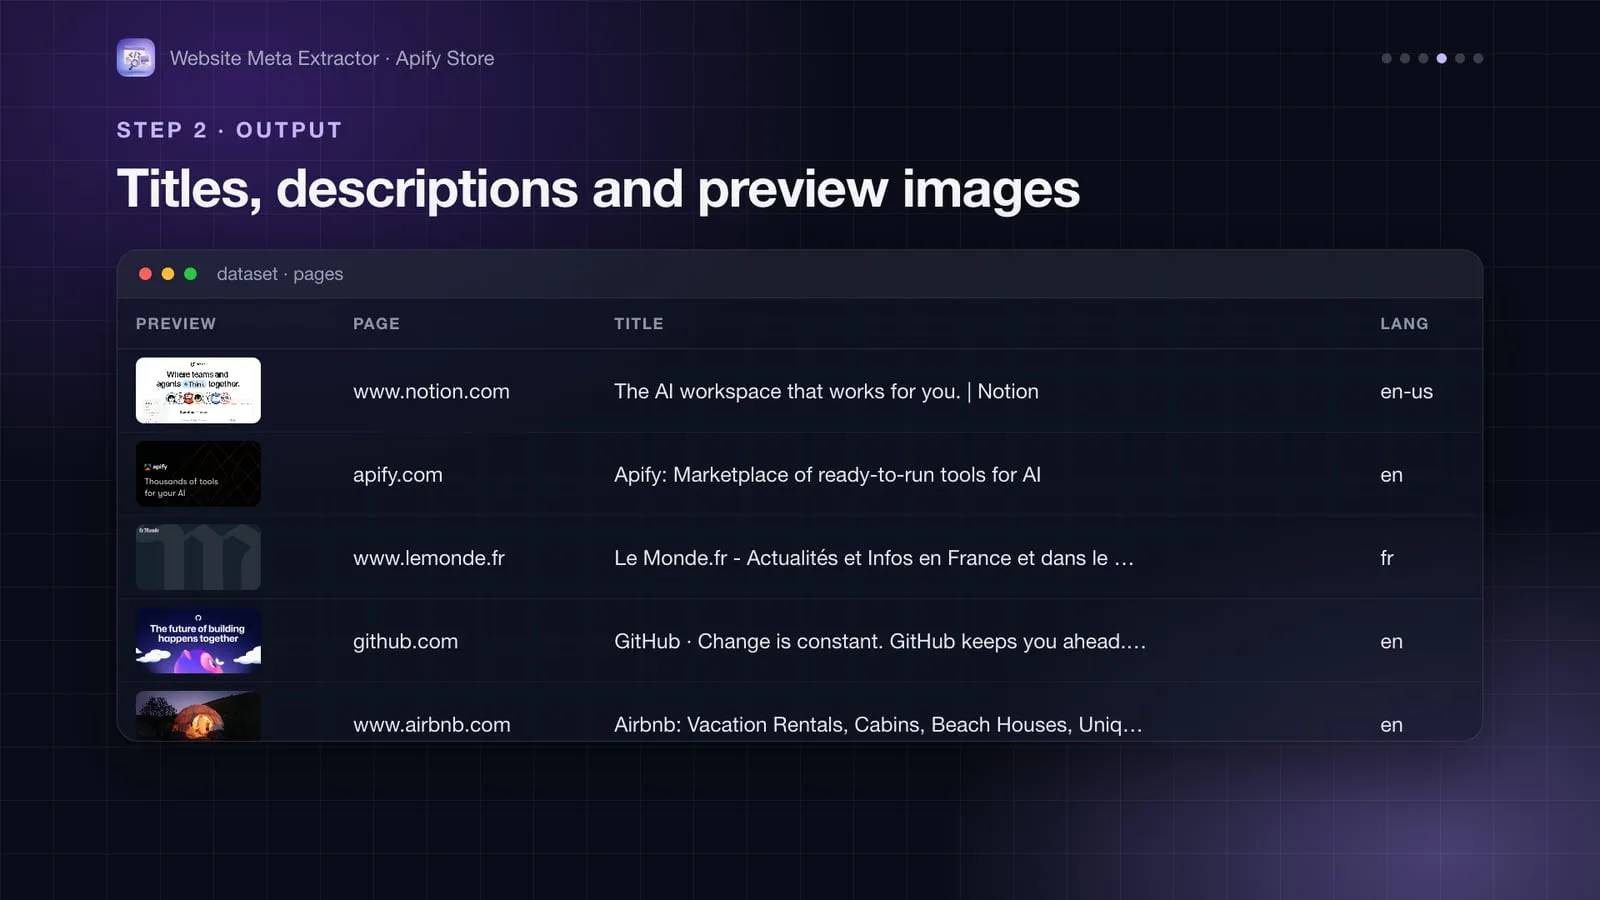
One dataset item per URL:
Export the results as JSON, CSV, Excel or HTML, or fetch them through the Apify API.
Pricing
You pay a small fee per page successfully extracted. Pages that fail to load are not charged.
Limitations
The Actor reads the raw HTML returned by the server and does not execute JavaScript, so tags injected client-side by single-page apps may be missing.
More Actors from this developer
| 🤖 AI Brand Visibility Tracker See how ChatGPT, Gemini and Perplexity rank your brand | 💬 Review Insights AI Top complaints, bugs and feature requests from reviews | 🏢 French Company Data Every French company: SIREN, address, NAF, directors |
| 🔔 Review Alerts & AI Reply Drafts Instant alerts and reply drafts for new reviews | 👗 SHEIN Catalog & New Arrivals Tracker Search SHEIN's catalogue and track new arrivals | 🚗 European Car Deal Score Fair price and deal rating for used cars in 8 countries |
FAQ
Can I use it through the API, Make, Zapier or Google Sheets?
Yes. Every run can be started and read through the Apify API (JavaScript and Python clients, CLI, MCP), and Apify integrations connect it to Make, Zapier, n8n, Google Sheets, Slack, webhooks and more.
Is it legal to use this data?
The Actor only reads public or official open data and doesn't log in anywhere. Check the source's licence and your local rules (for example GDPR when data concerns people) for your use case; if in doubt, ask a lawyer.
Something isn't working, or you need another field?
Open an issue on the Issues tab: feedback is read and answered.


