
Berlin Startup Jobs Scraper
Pricing
from $2.99 / 1,000 results
Berlin Startup Jobs Scraper
Berlin Startup Jobs Scraper collects startup job listings in Berlin, helping users discover relevant career opportunities efficiently. It extracts available job details, organizes results into structured data, and simplifies job research for developers, professionals, and job seekers.
Pricing
from $2.99 / 1,000 results
Rating
0.0
(0)
Developer
ZeroBreak
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Berlin Startup Jobs Scraper: Berlin startup jobs RSS
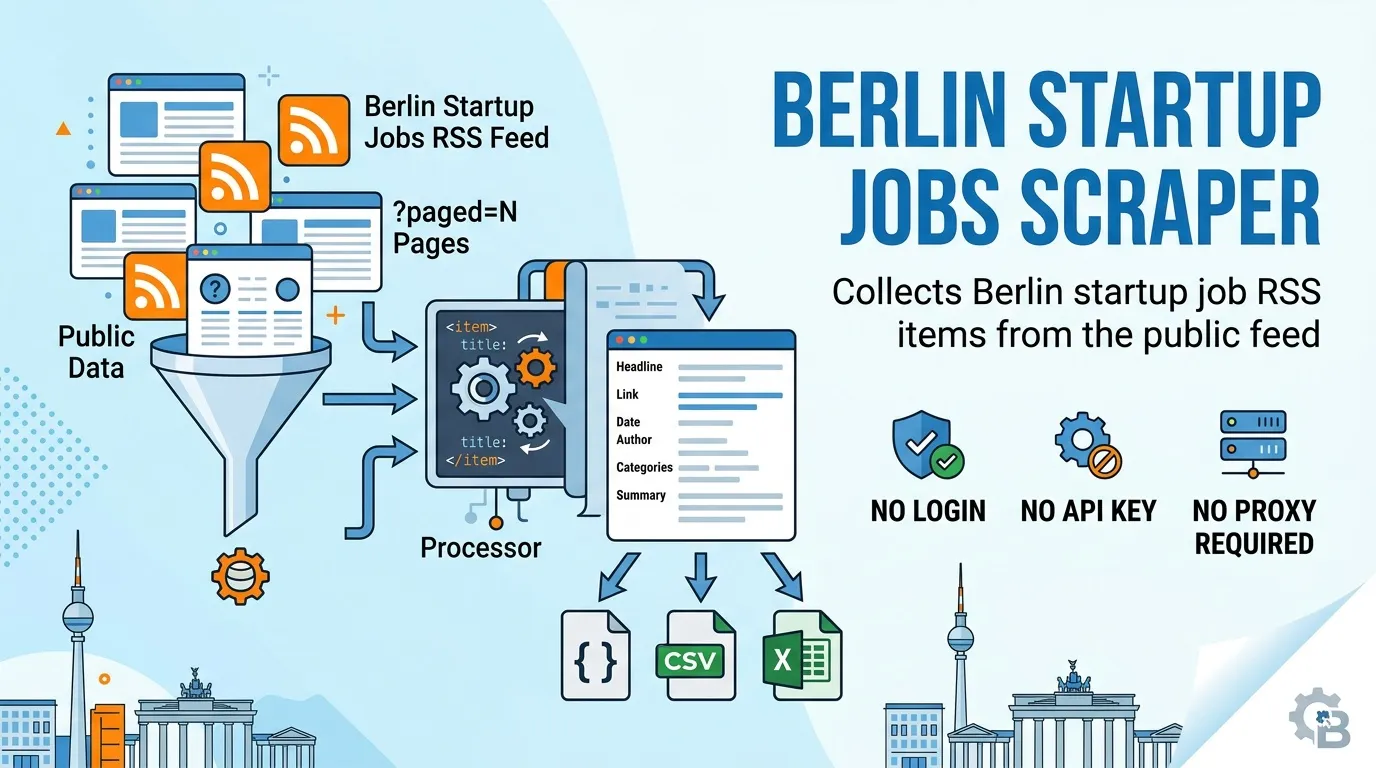
Berlin Startup Jobs Scraper collects berlin startup jobs RSS items from the public Berlin Startup Jobs feed. It needs no login, no API key, and no proxy. Each run exports a short job list as JSON, CSV, or Excel so you can refresh Berlin role lists on a schedule.
The actor reads https://berlinstartupjobs.com/feed/ and older pages with ?paged=N. It keeps the headline, link, date, author, categories, and a short summary. It does not download full job articles.
Features
- Reads the public RSS feed directly, with no account and no API key.
- Keeps headline, link, date, author, categories, and a short plain-text summary.
- Optional keyword filter on the title and summary.
- Deduplicates rows by
guidso scheduled runs do not repeat items. - Retries HTTP 429 and 5xx with backoff and honours
Retry-After. - Pushes an error row instead of crashing when a feed URL fails, so the run still finishes.
Use cases
- Berlin startup jobs RSS: pull the latest public openings into a dataset without an account
- Hiring research: filter titles and summaries for a keyword such as payroll or support
- Scheduled export: refresh the same feed on a timer and dedupe rows by guid
- CSV and JSON: download the dataset for a sheet, a CRM, or a weekly digest
- Free monitoring: stay within a 1000 row cap and a direct request, with no API key
Input
| Parameter | Type | Default | Description |
|---|---|---|---|
feedUrls | array | https://berlinstartupjobs.com/feed/ and page 2 | Berlin Startup Jobs RSS URLs. Only the /feed/ path, with an optional paged query, is accepted. |
keyword | string | empty | Optional filter. A row is kept when this text appears in the job title or the short summary. |
maxItems | integer | 100 | Maximum successful job rows. Hard max 1000. |
timeoutSecs | integer | 300 | Stop starting new feed requests after this many seconds. Maximum 3600. |
requestTimeoutSecs | integer | 30 | Seconds to wait for each RSS response. |
proxyConfiguration | object | {"useApifyProxy": false} | Optional proxy. Leave the default off. The public feed does not need a proxy. |
Example input
What data does this actor extract?
Each job row looks like this:
| Field | Type | Description |
|---|---|---|
jobTitle | string | Job headline from the RSS title. |
link | string | Public job page URL. Link back to this page when you reuse a listing. |
author | string | Feed author. Null when the item has none. |
pubDate | string | Publication date from the feed. Null when missing. |
categories | array | Category labels from the item. |
guid | string | Stable id used to drop duplicates. |
summaryText | string | Short plain-text summary. HTML is stripped. Full article text is not stored. |
sourceUrl | string | Feed URL that returned the item. |
scrapedAt | string | UTC time the row was saved. |
error | string | Present on failure rows instead of a job. |
input | string | The feed URL or other value tied to an error row. |
A bad URL, an HTML error page, or a non-RSS body becomes an error row. The run still finishes.
How it works
- Read feed URLs, an optional keyword, and the item cap.
- Request only
https://berlinstartupjobs.com/feed/and?paged=Nwith a descriptive User-Agent. - Parse RSS items, strip HTML from the short summary, and skip full article markup.
- Drop duplicates by guid, apply the keyword filter, and stop at
maxItems. - When a page still has new jobs and the cap is not filled, request the next
pagedURL. - Retry HTTP 429, 5xx, and timeouts up to three times, waiting 2, 4, then 8 seconds, and honour
Retry-After. - Wait about one second between feed requests. Schedule the actor every 5 to 15 minutes rather than polling faster.
Troubleshooting
- "Feed URL is not a verified Berlin Startup Jobs RSS endpoint": only
https://berlinstartupjobs.com/feed/and the same path with?paged=Nare accepted. Check the URL infeedUrls. - "Response was HTML, not an RSS feed": the site returned a block or error page instead of the feed. Try again later, and keep requests gentle by scheduling runs a few minutes apart.
- "No items matched the keyword filter": the keyword did not appear in any title or summary. Clear it or use a broader term.
- "Stopped because timeoutSecs was reached": raise
timeoutSecs, or lowermaxItemsso the run finishes sooner. - Empty dataset: the feed only carries recent items. Schedule regular runs and rely on guid dedupe to build history over time.
- Rate limiting (HTTP 429): the actor already retries with backoff and honours
Retry-After. Do not poll faster than every few minutes.
Limits and terms
No terms page was available on the source site. Keep the job link when you share a listing. The feed only carries recent items, so scheduling plus guid dedupe is the way to watch for new roles. Output is the headline, link, date, and a short summary. Do not treat the dataset as a copy of the full post. Requests use one at a time with a one second gap. Retries cover 429 and 5xx. The free cap is 1000 items per run.
FAQ
Does the Berlin startup jobs RSS actor need an API key? No. The public feed is read with no login, no cookie, and no API key.
How many Berlin jobs can one run export?
maxItems defaults to 100 and cannot go above 1000. Page 2 and later pages are requested only while that cap is still open.
Does it store the full job article?
No. summaryText is the short RSS summary with tags removed. Article HTML from the content module is ignored.
What happens if a feed URL is wrong?
The actor pushes an error row with error and input, then continues with any valid feeds. The run succeeds.
Is the proxy required?
No. proxyConfiguration defaults to useApifyProxy false and is optional.
Trademark Notice
Berlin Startup Jobs and related names, logos, and trademarks belong to their respective owners. Their use in this documentation is solely to identify the source of the data and does not imply affiliation, sponsorship, endorsement, or partnership.
Disclaimer
Disclaimer: This Actor is an independent tool and is not affiliated with, endorsed by, sponsored by, or otherwise officially associated with Berlin Startup Jobs or its owners. All data is collected from publicly available sources. Users are responsible for complying with the source's terms of use, rate limits, and attribution or licensing requirements.
Is web scraping legal?
This Actor only collects publicly available data from Berlin Startup Jobs, mostly through its public feed, without logging in or bypassing any access controls. Scraping public data is generally legal, but how you use it matters:
- Personal data: If the results include personal data (for example names, emails, or profile details), laws such as the GDPR in the EU and the CCPA in California may apply. Only collect and store personal data when you have a legitimate reason.
- Copyright: Some content (articles, images, descriptions) may be protected by copyright. Do not republish full copyrighted content without permission.
- Terms of use: Respect the source's terms, stated rate limits, and any attribution or non-commercial-use requirements listed in the Limits and terms section.
- Legal advice: This is general information, not legal advice. If you're unsure, consult a lawyer.
To learn more, read Apify's guide: Is web scraping legal?


