
Open Canada Dataset Scraper
Pricing
Pay per usage
Open Canada Dataset Scraper
Search the Government of Canada open data catalogue on open.canada.ca and pull dataset records or the files attached to them. Filter by topic or department, pick dataset or file-resource rows, and export to JSON, CSV, or Excel. Uses the public CKAN Data with paging, retries, and duplicate skipping.
Pricing
Pay per usage
Rating
0.0
(0)
Developer

BigiByte
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
Open Canada Dataset Scraper: open.canada.ca open data
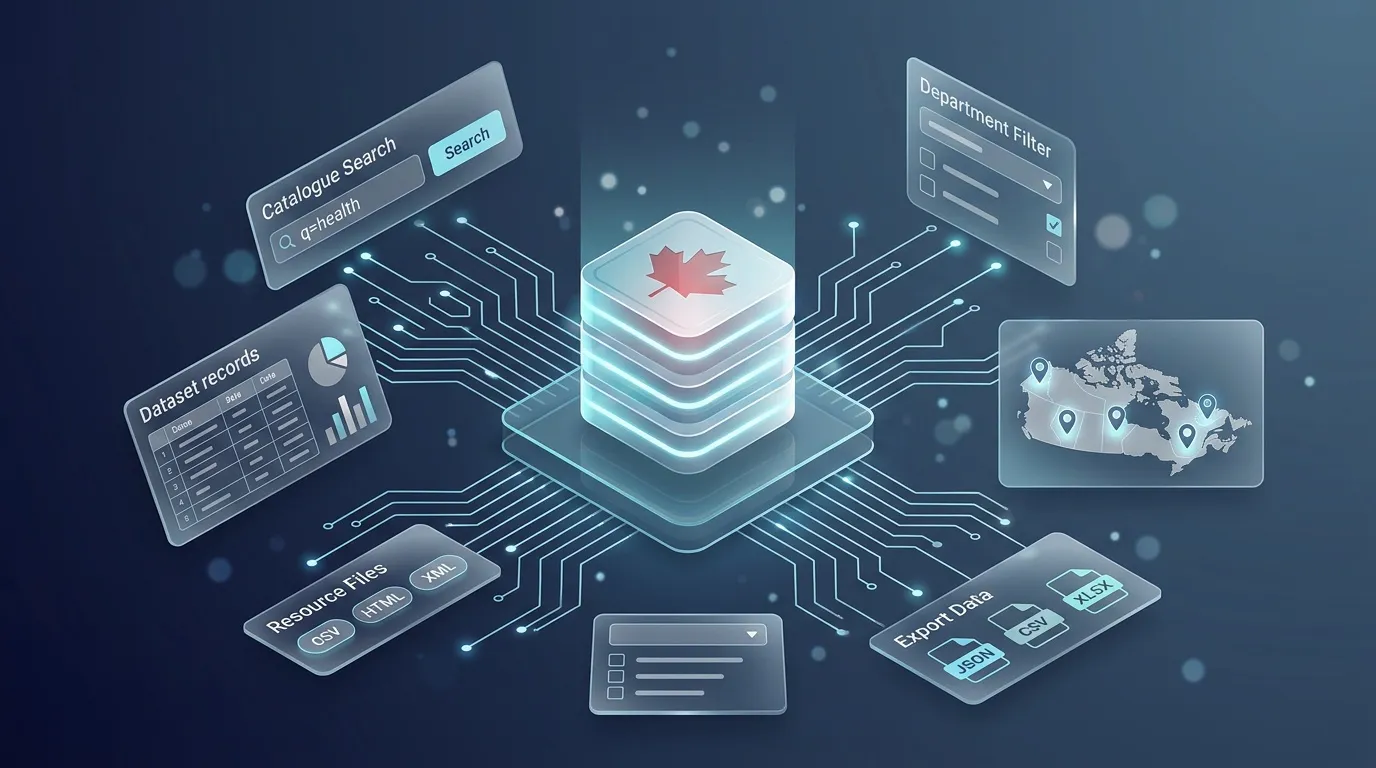
Search the Government of Canada open data catalogue and pull dataset records or the files attached to them. Results land in an Apify dataset you can export as JSON, CSV, or Excel.
Use cases
- Catalogue research: search open Canada datasets for a topic such as health and keep the metadata in one table
- File inventory: switch to resources mode and list CSV, HTML, and other files attached to each dataset
- Department filters: limit a run to one department or organization, for example phac-aspc
- Scheduled refresh: rerun the same query and export the dataset when the catalogue changes
- Licence check: read license_id, license_title, and license_url on each row before you reuse a file
What data does this actor extract?
Search mode writes one row per dataset. Resources mode writes one row per file resource and keeps the parent dataset fields on that row. Nested bilingual objects stay as returned. The dataset title is stored as itemTitle, the record kind as recordKind, and a file's format label as resourceFormat.
Input
| Parameter | Type | Default | Description |
|---|---|---|---|
mode | string | search | search for datasets, resources for one row per file |
query | string | health | Search text used to match datasets |
organization | string | empty | Organization name used to narrow results, such as phac-aspc |
includeResources | boolean | true | In search mode, attach the file list on each dataset row |
maxItems | integer | 100 | Cap on rows saved. Hard maximum 1000 |
timeoutSecs | integer | 300 | Stop the run after this many seconds |
requestTimeoutSecs | integer | 30 | How long to wait for each response, in seconds |
proxyConfiguration | object | {"useApifyProxy": false} | Optional proxy. Leave off unless a direct connection fails |
Example input
Output
| Field | Type | Description |
|---|---|---|
id | string | Dataset id in search mode, file id in resources mode. Used to skip duplicates |
itemTitle | string | Dataset title from the catalogue |
collection | string | Collection label such as publication or primary |
license_id | string | Licence id from the dataset |
license_title | string | Licence title from the dataset |
license_url | string | Link to the licence |
keywords | object | Bilingual keyword lists |
resourceUrl | string | File or page URL, resources mode only |
resourceFormat | string | Format label such as CSV or HTML, resources mode only |
scrapedAt | string | UTC time the row was saved |
error | string | Set only when a row cannot be produced. The run continues instead of crashing |
Other catalogue fields are copied when they are present: additional_notes, audience, author, author_email, contributor, creator, creator_user_id, data_series_issue_identification, data_series_name, date_modified, date_published, departmental_identification_number, digital_object_identifier, edition, frequency, gc_catalogue_number, geographic_region, imso_approval, isbn, isopen, issn, issuance, issuance_frequency, and jurisdiction.
Limits
maxItems caps how many rows a run saves and cannot exceed 1000. timeoutSecs stops the run after the set number of seconds and defaults to 300. Rows already saved stay in the dataset when the timeout is reached.
Related tools
If you plan to join or analyse these rows, a quick CSV cleanup or a de-duplication pass are the usual next steps. BigiByte also builds scrapers for other open-data catalogues when you need them as a separate job.
Need another national or provincial open-data catalogue, a scheduled monitor, or a custom pipeline? BigiByte builds custom scrapers and data tools: https://bigibyte.com
FAQ
What is the difference between search and resources?
Search saves one row per dataset. Resources saves one row per file on those datasets, with resourceUrl and resourceFormat filled in.
How many rows can one run save?
maxItems defaults to 100 and will not go past 1000. Raise it when you need a wider slice, or schedule a narrower query.
Can I export to CSV, JSON, or Excel? Yes. The default dataset export covers those formats. Schedule the actor if you want a fresh export later.
Trademark notice
Open Canada Dataset and related names, logos, and trademarks belong to their respective owners. Their use in this documentation is solely to identify the source of the data and does not imply affiliation, sponsorship, endorsement, or partnership.
Disclaimer
Disclaimer: This Actor is an independent tool and is not affiliated with, endorsed by, sponsored by, or otherwise officially associated with Open Canada Dataset or its owners. All data is collected from publicly available sources. Users are responsible for complying with the source's terms of use, rate limits, and attribution or licensing requirements.
Is web scraping legal?
This Actor only collects publicly available data from Open Canada Dataset, without bypassing any access controls. Scraping public data is generally legal, but how you use it matters:
- Personal data: If the results include personal data (for example names, emails, or profile details), laws such as the GDPR in the EU and the CCPA in California may apply. Only collect and store personal data when you have a legitimate reason.
- Copyright: Some content (articles, images, descriptions) may be protected by copyright. Do not republish full copyrighted content without permission.
- Terms of use: Respect the source terms, stated rate limits, and any attribution requirements in the Open Government Licence.
- Legal advice: This is general information, not legal advice. If you're unsure, consult a lawyer.
To learn more, read Apify's guide: Is web scraping legal?


