
Carousell Products Scraper
Pricing
from $0.20 / 1,000 results
Carousell Products Scraper
Scrape Carousell.sg product listings for prices, seller ratings, deal methods & more. Export clean JSON/CSV data from any category, search, or listing URL.
Pricing
from $0.20 / 1,000 results
Rating
0.0
(0)
Developer
ActorFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Categories
Share
Carousell (Carousell.sg) Products Scraper
Scrape product listings from Carousell (carousell.sg) — title, price, seller rating, deal method, condition, photos and likes — from any category page, search-results page or single listing URL. Export clean JSON, CSV or Excel data, or call it as an API and run it on a schedule. Paste a URL (or type a keyword), press Start, and get structured Carousell listing data in minutes.
Target website: carousell.sg
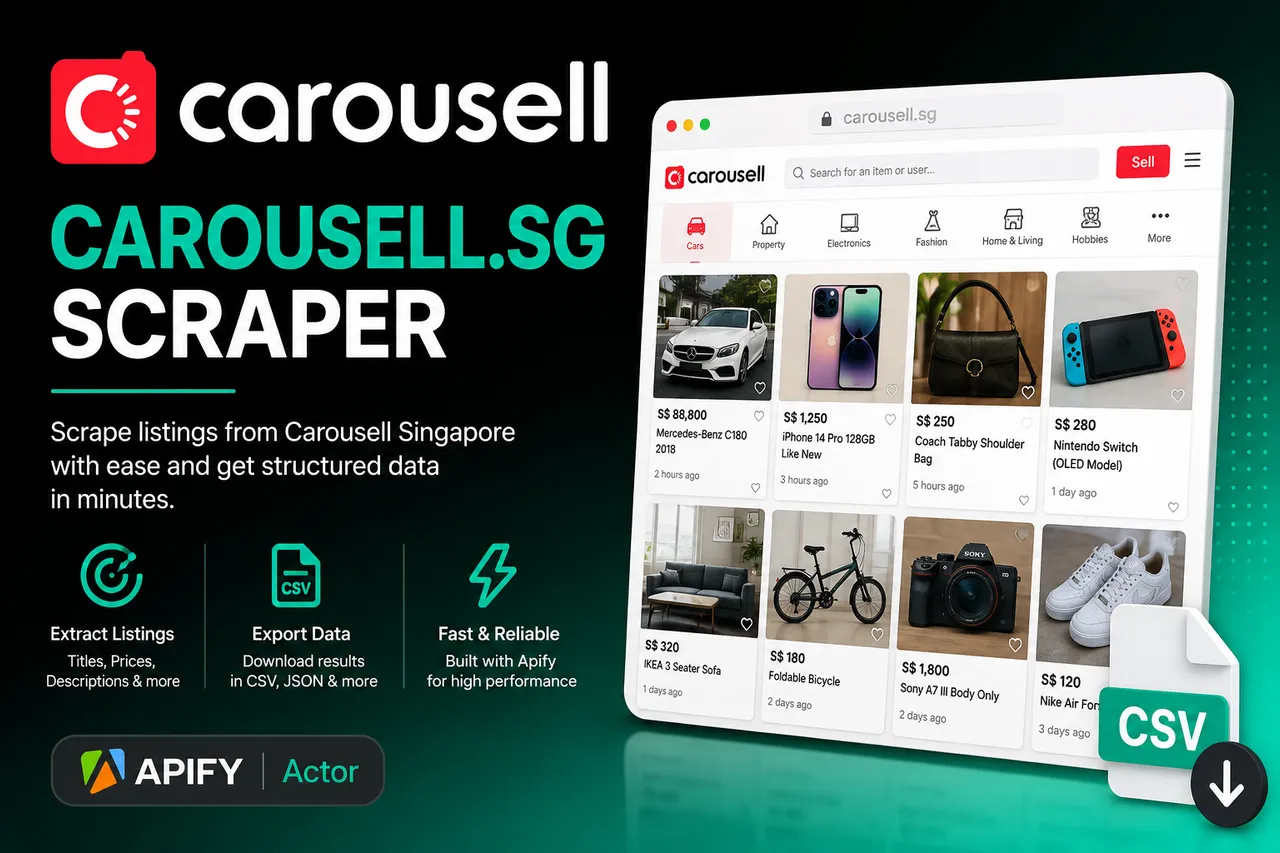
Carousell is one of Southeast Asia's largest classifieds marketplaces, and its listings change constantly as sellers post and re-list items. This scraper lets you pull up-to-date listing data on demand, so you can track pricing trends, monitor specific categories, or feed listings into your own catalog or analytics pipeline. Because it runs on the Apify platform, you also get API access, scheduling and integrations with Make, Zapier and Google Sheets out of the box.
✨ Features of this Carousell product listings scraper
- Product listing extraction — title, price, currency, description, photos, categories and detail attributes (condition, brand, model, etc.) from every listing.
- Seller and engagement data — seller handle, rating, review count, years on Carousell, deal method and accepted payment methods.
- Pagination support — automatically loads more results on category and search pages, so you can collect as many listings as
maxItemsallows. - Search or URL input — start from category URLs, search-result URLs, individual listing URLs, or just a keyword.
- Built-in anti-bot handling — Carousell's Cloudflare protection and proxying are handled for you, with no proxy setup needed.
- No browser required — runs are simple and lightweight, with no browser to manage on your side.
🚀 How to scrape Carousell product listings in 5 steps
- Sign up for a free Apify account — includes $5 monthly credit.
- Open the actor page and click Try for free.
- Fill in the Input fields (start URL or search query is required).
- Click Start and wait for the run to complete.
- Download results from the Output tab in JSON, CSV, or Excel format.
You can also run this actor via the Apify API or integrate it directly into your workflows using Zapier, Make, or n8n.
💰 Pricing
This actor uses pay-per-result billing based on the compute units a run consumes.
- New Apify accounts include $5 of free monthly credit.
- Runs use plain requests rather than a browser, so they cost significantly less than browser-based scrapers.
- Each page takes roughly 10–20 seconds to load, so keep
maxItemsmodest for quick, cheap test runs.
🔧 Carousell scraper input configuration
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
startUrls | array | — | https://www.carousell.sg/categories/beauty-personal-care-11/fragrance-deodorants-1663/?search=perfume&t-search_query_source=ss_dropdown | Carousell category, search-result or individual product page URLs to start from. |
search | string | — | — | Optional keyword search to run instead of (or in addition to) Start URLs. |
maxItems | integer | — | 1 | Maximum number of listings to extract per start URL or search query. |
proxyCountry | string | — | Singapore | Country of the proxy used to load Carousell. Carousell.sg works best with Singapore. |
Supported URL types:
- Category pages —
https://www.carousell.sg/categories/... - Search-result pages —
https://www.carousell.sg/search/... - Individual product pages —
https://www.carousell.sg/p/...
Sample input:

📦 Carousell scraper output data
Each listing is saved as one dataset item with the fields url, title, price, priceCurrency, categories, isCertified, isFreeShipping, description, primaryImage, images, paymentMethods, variants, peopleWhoWantThis, noOfLikes, detailAttributes, dealMethod and sellerDetails. The dataset has 1 view, Overview, a table of the cover photo, title, price, likes, deal method, categories, seller details and listing URL. Download it as JSON, HTML, CSV or Excel.
Output at a glance:
| Title | Price | Condition | Brand | Deal method | Seller rating | Reviews |
|---|---|---|---|---|---|---|
| Wtt wts perfume | S$20 | Like new | Khadlaj | — | 5.0 | 66 |
| French Scented Perfume 10ml | S$8.90 | Brand new | UD CLUB | Seller's custom delivery | 5.0 | 3 |
Sample output (raw JSON):

Carousell listing data fields
| Field | Description |
|---|---|
url | Direct link to the listing. |
title | Listing title. |
price | Listed price. |
priceCurrency | Currency code for the price (e.g. SGD). |
categories | Breadcrumb category path for the listing. |
isCertified | Whether the listing carries Carousell's certified badge. |
isFreeShipping | Whether free standard shipping is offered. |
description | Full listing description text. |
primaryImage | URL of the first/cover photo. |
images | URLs of the remaining listing photos. |
paymentMethods | Accepted payment methods shown in the listing's payment section. |
variants | Available variant groups (e.g. color, storage) and their options. |
peopleWhoWantThis | Number of users who marked they also want this item, when shown. |
noOfLikes | Number of likes on the listing, when shown. |
detailAttributes | Listing-specific attributes (Condition, Brand, Model, etc.) as title/value pairs. |
dealMethod | How the seller offers to complete the deal (e.g. "Meet-up"). |
sellerDetails | Object with the seller's handle, rating, review count, and years on Carousell. |
🐍 How to scrape Carousell with Python, JavaScript or the API
Run the actor programmatically with the official Apify clients. Replace <YOUR_API_TOKEN> with the token from your Apify Console.
Python (pip install apify-client):
JavaScript (npm install apify-client):
cURL — start a run and wait for the dataset:
💡 What you can use Carousell product listing data for
- Price monitoring across listings in a category (phones, electronics, fragrances, furniture, etc.)
- Market research on what is being sold, how it is described, and which conditions and delivery options sellers offer
- Lead generation by tracking new listings that match a search query for resale, sourcing or competitive analysis
- Seller reputation analysis using ratings, review counts and years active on the platform
- Catalog enrichment with product photos and detailed attributes for your own systems
Resellers, price-comparison sites, market researchers and e-commerce analysts in Southeast Asia typically use this data.
⚠️ Limitations & known issues
- Login-required pages — The actor cannot access content behind authentication (e.g. private messages, saved offers).
- Slower pages — Each page takes roughly 10–20 seconds to load, so large runs take longer.
- Likes and "people also want this" — These counts are not always present in the page data, so
noOfLikesandpeopleWhoWantThiscan benull. - Layout changes — Carousell periodically updates its page layout, which can occasionally affect specific fields until selectors are updated.
❓ Frequently asked questions
Can I scrape Carousell legally?
The actor only collects data that is already publicly visible on carousell.sg — it never logs in or accesses private content. Scraping publicly available data is generally considered lawful (see hiQ Labs v. LinkedIn), but you are responsible for complying with Carousell's Terms of Service and any applicable laws such as GDPR if you handle personal data like seller handles.
What data does the Carousell scraper return?
Each listing returns its title, price, currency, categories, description, photos, detail attributes, deal method, payment methods and seller details (handle, rating, review count, years on Carousell). Likes and "people also want this" counts are included when Carousell shows them.
How many listings can I scrape from one Carousell URL or search?
maxItems limits the number of listings per start URL or search query, not for the whole run. The scraper keeps loading more results until it reaches that number or the results run out.
Do I need a proxy to scrape carousell.sg?
No. Carousell's Cloudflare protection and proxying are handled for you, so there is nothing to set up. The optional proxyCountry field (default Singapore) only changes where requests appear to come from.
How do I scrape Carousell with Python?
Use the Python example above: call the actor with ApifyClient, then iterate over the dataset items of the finished run.
Can I run this Carousell scraper on a schedule?
Yes. Use Apify Schedules to run it hourly, daily or weekly, for example to track price changes in a category over time.
What output formats are supported?
JSON, CSV, Excel, XML and RSS, either from the Output tab or through the Apify API.
Why are likes or "people also want this" counts sometimes missing?
Carousell loads some details (such as like counts) after the page first renders, so they can be absent from the data the scraper receives. Those fields are returned as null rather than guessed.
🔗 Other actors you may find useful
| Scraper | Description |
|---|---|
| 🚗 Cheapest Cars & Bids Scraper | Scrapes the cheapest vehicle listings from Cars & Bids, making it easy to discover the best-value auction deals. |
| 🔍 Incidecoder Scraper | Extracts cosmetic ingredient and product information from Incidecoder for research and analysis. |
| 🎟️ Church Finder Scraper [💰Free] | Scrape church listings and profiles from Church Finder. Extracts church name, denomination, address, phone number, service times, ratings and reviews from city search pages or individual church URLs. |
| 🔴 BidNet Direct [Closed Links] Bid Opportunities Scraper | Scrapes closed🔴 government bid and RFP solicitations from BidNet Direct, including title, issuing organization, location, publication date, closing date, and days since closing |
| ✅ BidNet Direct [Open Links] Bid Opportunities Scraper | Scrapes open✅ government bid and RFP solicitations from BidNet Direct, including title, publication date, closing date, and days remaining until closing. |
💬 Support & contact
If you encounter any issues or have questions, please open an issue or reach out via the Apify Community Forum.
You can also find more of our actors on the Actor Flow page.


