
Dice Jobs Scraper - Search Tech Jobs by Keyword or URL
Pricing
from $0.20 / 1,000 results
Dice Jobs Scraper - Search Tech Jobs by Keyword or URL
Scrapes tech job listings from Dice (dice.com): title, company, location, employment type, salary, posted date, skills, remote status, full description and job link. Search by keyword, search URL or job URL.
Pricing
from $0.20 / 1,000 results
Rating
0.0
(0)
Developer
ActorFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
12 hours ago
Last modified
Categories
Share
Scrape tech job listings from Dice (dice.com): title, company, location, employment type, salary, posted date, skills, remote status, full job description and job link. Export the results as JSON, CSV or Excel, or call the actor as an API. Type a keyword or paste a Dice search URL, press Start, and get clean job data. Repeat runs skip jobs you already scraped, so you never pay twice for the same job, which makes this one of the cheapest Dice jobs scrapers to run on a schedule.
Target website: dice.com
✨ Features of this Dice jobs scraper
- Job listing extraction — title, company, location, employment type, salary, posted date, remote and workplace type, easy apply flag and the job summary.
- Full job details — skills, full description (HTML and plain text), valid-through date and apply type for every job.
- Pagination support — keeps paging through search results until Max items is reached.
- Keyword, URL and ID input — search by keyword, paste a Dice search URL with filters, or pass single job URLs and job IDs.
- Incremental runs, no repeat charges — with a cache project name, jobs and URLs you already scraped are skipped on every later run, so you never pay for the same job twice and scheduled runs return only new jobs.
- Proxy support — optional Apify Proxy, off by default.
- No browser required — plain HTTP requests keep runs fast and cheap.
🚀 How to scrape Dice jobs in 5 steps
- Sign up for a free Apify account — includes $5 monthly credit.
- Open the actor page and click Try for free.
- Fill in the Input fields (a keyword, search URL or job URL is required).
- Click Start and wait for the run to complete.
- Download results from the Output tab in JSON, CSV, or Excel format.
You can also run this actor via the Apify API or integrate it directly into your workflows using Zapier, Make, or n8n.
💰 Dice jobs scraper pricing
This actor uses pay-per-result billing: you pay for each job saved to the dataset.
- New Apify accounts include $5 of free monthly credit.
- The actor uses plain HTTP requests, so it costs significantly less to run than browser-based scrapers.
- The proxy is disabled by default; leaving it off keeps runs cheapest.
- Jobs skipped by the cache are not charged. Reuse the same Cache project name across runs and the same URLs are never scraped (or billed) again, so repeated and scheduled runs cost only for genuinely new jobs, which can make this the cheapest way to track Dice jobs.
🔧 Dice jobs scraper input configuration
| Field | Type | Required | Default | Description |
|---|---|---|---|---|
Search keywords (keywords) | array | — | ["typescript"] (prefill) | Job titles or skills to search for. Each keyword is searched separately. |
Search or job URLs (startUrls) | array | — | — | Dice search result URLs with filters applied, or single job URLs. A page number in a search URL is the page the search starts from. |
Job IDs (jobIds) | array | — | — | Dice job IDs to scrape directly. |
Scrape full job description (scrapeDetails) | boolean | — | true | Open every job page for the description, skills, validity date and apply type. Turn off for faster runs with the search summary only. |
Cache project name (cacheProjectName) | string | — | — | Use the same name on each run to get only new jobs. Cached jobs are skipped, not charged and not counted towards Max items. Records get changeType: new. |
Max items per search (maxItems) | integer | — | 5 | Maximum unique jobs saved for each keyword or search URL. |
Max concurrency (maxConcurrency) | integer | — | 5 | How many requests run in parallel. |
Proxy configuration (proxyConfiguration) | object | — | no proxy | Works without a proxy. Enable Apify Proxy only if you get blocked. |
Supported URL types:
- Search:
https://www.dice.com/jobs?q=typescript&radius=30&radiusUnit=mi - Search starting at a page:
https://www.dice.com/jobs?q=typescript&page=2 - Job:
https://www.dice.com/job-detail/f9b02b33-d1be-43cb-84bc-96648ee1b08c
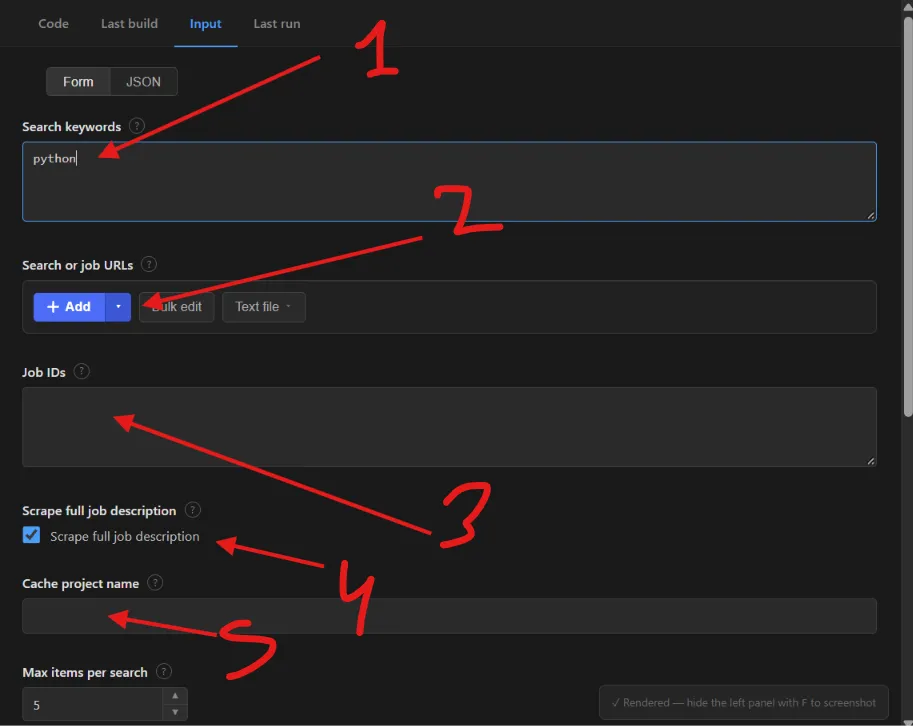
In the screenshot above:
- Search keywords — job titles or skills, such as
python. - Search or job URLs — Dice search result URLs or single job URLs.
- Job IDs — Dice job IDs to scrape directly.
- Scrape full job description — tick to open every job page for the full details.
- Cache project name — reuse the same name on each run to get only new jobs.
📦 Dice jobs scraper output data
The actor saves one JSON record per job with these fields: id, url, title, companyName, companyLogoUrl, companyProfileUrl, employerType, location, city, state, country, isRemote, workplaceTypes, employmentType, salaryText, salaryMin, salaryMax, salaryCurrency, postedAt, modifiedAt, validThrough, easyApply, applyType, skills, summary, descriptionHtml, description, scrapedAt and, when caching is on, changeType.
There is 1 output view. Overview is a compact table with the id, title, company, location, workplace type, employment type, salary, posted date, skills, change type and job link.
Output at a glance:
| Job | Company | Location | Type | Salary | Posted |
|---|---|---|---|---|---|
| Backend Software Engineer, TypeScript / Node. | Jobot | New York, New York, USA | Full-time | USD 185,000.00 - 225,000.00 per year | 2026-10-09 |
| Senior Full-Stack Software Engineer, TypeScri | Jobot | San Francisco, California, USA | Full-time | USD 190,000.00 - 250,000.00 per year | 2026-10-09 |
| Full-stack Engineer 4 (Manager, IC - Node.js, | Capital One | McLean, Virginia, USA | Full-time | USD 197,300.00 - 225,100.00 per year | 2026-09-26 |
| Full-stack Engineer 4 (Manager, IC - Python, | Capital One | McLean, Virginia, USA | Full-time | USD 197,300.00 - 225,100.00 per year | 2026-10-02 |
| Full-stack Engineer 5 (Senior Manager, IC - A | Capital One | McLean, Virginia, USA | Full-time | USD 229,900.00 - 262,400.00 per year | 2026-10-02 |
Sample output (raw JSON, long fields shortened for this page):
🐍 How to scrape Dice with Python, JavaScript or the API
Run the actor programmatically with the official Apify clients. Replace <YOUR_API_TOKEN> with the token from your Apify Console.
Python (pip install apify-client):
JavaScript (npm install apify-client):
cURL — start a run and wait for the dataset:
💡 What you can use Dice jobs data for
- Tracking demand for programming languages, frameworks and certifications
- Salary benchmarking for contract and full-time tech roles
- Feeding job boards or newsletters with fresh tech openings
- Recruiter and staffing market research by company and employer type
- Monitoring remote, hybrid and on-site hiring trends
Recruiters, staffing agencies, job aggregators, HR analysts and tech career platforms use this data to follow the IT job market.
⚠️ Limitations of the Dice jobs scraper
- Salary — many jobs show text such as "Depends on Experience"; in that case
salaryMinandsalaryMaxarenulland onlysalaryTextis filled. - Remote jobs — remote jobs often have no city, state or country, so those fields are
null. - Search depth — Dice limits how far a single search can page; use more specific keywords or filters to reach other jobs.
- Expired jobs — a job URL or ID that no longer exists is skipped with a warning.
❓ Frequently asked questions
Can I scrape Dice legally?
The actor only collects job data that is publicly visible on dice.com — no login, paywall or private content is accessed. Scraping publicly available data is generally considered lawful (see hiQ Labs v. LinkedIn), but you are responsible for complying with Dice's Terms of Service and applicable laws such as GDPR and CCPA if personal data is involved.
What data does the Dice scraper return?
Every job has its title, company, location, employment type, salary, posted date, remote and workplace type, summary and job link. With Scrape full job description on, you also get skills, the full description in HTML and text, the valid-through date and the apply type.
How many jobs can I scrape from one Dice search?
Max items per search limits the unique jobs saved for each keyword or search URL, not for the whole run. The actor pages through the results (30 jobs per page) until it reaches that number or the results end.
Do I need a proxy to scrape dice.com?
No. The input defaults to no proxy, which is the cheapest option. If you get blocked on a large run, enable Apify Proxy in the proxy configuration.
How do I scrape Dice with Python?
Use the Python example above: call the actor with apify-client and iterate over the dataset items.
Can I run this Dice scraper on a schedule, and is it the cheapest option?
Yes, use Apify Schedules. Set the same Cache project name on every scheduled run and the actor skips jobs it already saved, so each run returns only new jobs, marked with changeType: new.
It is built to be cheap. With a Cache project name set, every later run skips jobs it has already saved, so the same URLs are never scraped again and you are only charged for new jobs. Combined with plain HTTP requests and no proxy by default, repeated runs stay very cheap.
What output formats are supported?
JSON, CSV, Excel, XML and RSS, either from the Output tab or through the Apify API.
Why is the salary empty for some Dice jobs?
Many Dice employers do not publish a number and write "Depends on Experience" instead. The text is kept in salaryText, and salaryMin and salaryMax stay null.
🔗 Other actors you may find useful
| Actor | Description |
|---|---|
| 💼 HiringCafe Jobs Scraper | Scrapes job listings from HiringCafe by keyword, search URL or job URL. |
| 📧 Decision Maker Email Finder | Finds founders, executives and department heads at any company website. |
| 🏢 BBB Business Info and Emails Scraper | Scrapes Better Business Bureau businesses: contacts, rating and reviews. |
| 📰 Google News AI Scraper | Searches Google News by keyword with optional full text and AI summaries. |
| 📊 Sentiment Analysis Using Jev | Classifies text as positive, negative, neutral or mixed, or into custom labels. |
💬 Support & contact
If you encounter any issues or have questions, please open an issue or reach out via the Apify Community Forum.
You can also find more of our actors on the Actor Flow page.


