
Reddit Comments Scraper
Pricing
$1.50 / 1,000 comment results
Reddit Comments Scraper
Scrape complete public Reddit comment threads from one or many post or comment URLs. One flat row per comment with author, text, score, timestamps, parent, depth and path metadata, moderation flags and parent-post context. Control sort, reply depth and filters. No Reddit login or API key.
Pricing
$1.50 / 1,000 comment results
Rating
0.0
(0)
Developer
Delowar Munna
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
4 days ago
Last modified
Categories
Share
Paste one or many Reddit post or comment URLs and get the discussion as a clean flat dataset — one row per comment, including nested replies, with parent, depth and path metadata, scores, timestamps and moderation flags. Control sort, depth, filters and hard cost caps without providing a Reddit account, cookies or API key.
Flatten the thread without losing the tree.
What it does
- Takes post URLs, comment permalinks,
redd.itshort links,/r/<sub>/s/share links or bare post IDs — any mix, in bulk. - Returns one row per comment: ID, author, text, score, created and edited timestamps, depth, parent ID, the full path from the top-level comment, OP and moderator flags, deleted/removed status, direct reply count and compact post context.
- Follows nested replies and Reddit's collapsed "more comments" continuations.
- Six sort modes, per-thread and run-wide caps, date/score/length/author/keyword filters, a skip list for incremental runs, and a target-comment mode that returns one comment with its ancestors and replies.
- Pushes rows as it goes, so a late failure never loses what was already captured.
- Reports thread completeness honestly in
THREAD_SUMMARYrather than claiming a thread is whole when it is not.
Quick start
Several threads at once, with filters:
One comment with its context — a comment permalink in target mode:
Full thread vs. target-comment context
By default every input — even a comment permalink — scrapes the whole thread. Switch on Focus on the linked comment to collect just that comment, up to Ancestor levels in focus mode parents above it, and every reply below it. Rows still carry absolute depth and the full path from the top-level comment, so the context reads correctly next to a full-thread export.
Sort modes
best, top, new, controversial, old, qa. The sort decides which comments a per-thread cap
keeps: comments are collected breadth-first — the top-level comments Reddit ranks first, then their
replies — so a cap on a huge thread returns the highest-ranked part of it.
Nested replies and "more comments"
Replies are followed to Max reply depth (default 10; 0 = top-level only). Reddit's collapsed continuations are resolved when Expand 'more comments' placeholders is on (default). Switching replies off is the cheapest mode — one request per page of top-level comments.
Input reference
| Field | Default | Meaning |
|---|---|---|
postUrls | — | Post URLs, comment permalinks, redd.it links, share links or post IDs. Required. |
maxTotalComments | 5000 | Hard cap on comments delivered by the whole run. |
maxCommentsPerPost | 500 | Cap per thread. |
includeNestedReplies | true | Follow reply branches. |
maxDepth | 10 | Deepest reply level; 0 = top-level only. |
commentSort | best | One of the six sorts above. |
expandMoreComments | true | Resolve collapsed continuations. |
minScore / maxScore | — | Score bounds. Hidden scores are kept. |
excludeDeletedRemoved | false | Drop deleted and removed comments. |
excludeStickied | false | Drop moderator-pinned comments where the flag is observable (see Limitations). |
postedAfter / postedBefore | — | ISO dates. |
minLength / maxLength | — | Body length bounds. |
includeAuthors / excludeAuthors | — | Username allow / deny lists. |
includeKeywords / excludeKeywords | — | Case-insensitive substring filters on the text. |
focusOnTargetComment | false | Target-comment mode for comment permalinks. |
commentContextDepth | 3 | Ancestor levels in target mode. |
includePostContext | true | Post title, author and Reddit's comment count on every row. |
skipCommentIds | — | IDs already collected; skipped, never charged, replies still explored. |
maxConcurrency | 3 | Threads collected in parallel (1–5). |
requestDelayMs | — | Extra pacing between requests. |
proxyConfiguration | Apify Datacenter | See Proxy below. |
Caps and cost
Two caps bound every run: maxTotalComments across the run and maxCommentsPerPost per thread. A
comment beyond either cap is never fetched and never charged. Filters run before anything is
saved, so filtered comments cost nothing either.
Output and tree reconstruction
Every row carries commentId, parentId (null for a top-level comment), parentFullId (the
post's t3_ fullname for a top-level comment), depth and path — the list of comment IDs from
the top-level comment down to this one. Group by postId, order by capturedSequence, and the tree
rebuilds from the rows alone. directReplyCount is the number of direct replies known for the
comment; on a thread cut short by a cap it is a lower bound.
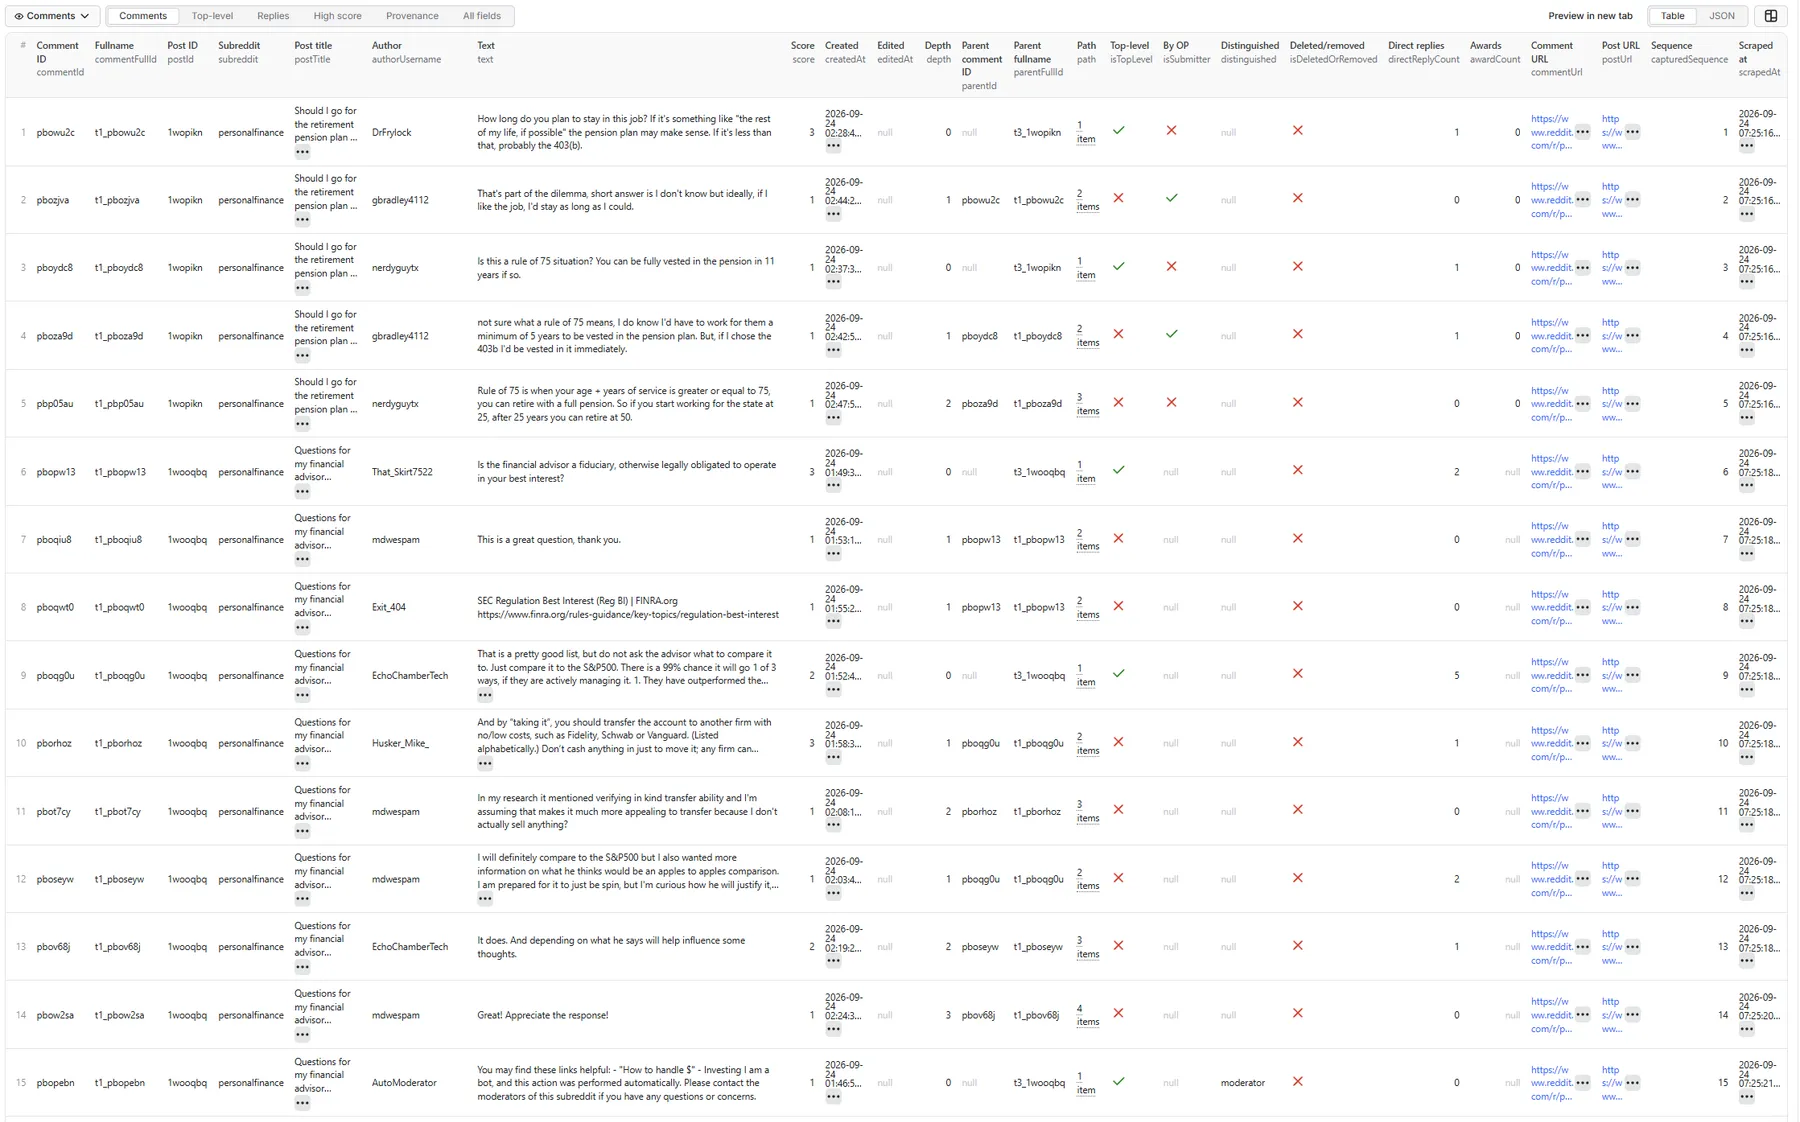
The dataset has five views. One real record from each, taken from a run over nine r/personalfinance and r/legaladvice threads:
Comments — every field
A depth-2 reply, with its ancestors in path:
Top-level
Top-level comments only, with the reply count under each:
Replies
Nested replies with their parent, depth and path:
High score
Sorted for the highest-scoring comments across the run:
Provenance
Which input produced each row, and in what order it was captured:
isStickied, isLocked, isSubmitter and awardCount are null where the surface a thread
was collected from does not publish them — see Limitations. text is plain text; a deleted or
removed comment keeps its ID and position with an empty body and a removedReason.
Completeness flags
THREAD_SUMMARY in the run's key-value store lists every thread with commentsSeen,
commentsEmitted, Reddit's own knownCommentCount, a coverageRatio, isThreadComplete and a
truncationReason — one of maxTotalComments, maxCommentsPerPost, maxDepth,
pagination-unavailable, moreRequestsCap, continuation-failed, provider-blocked or
charge-limit. RUN_SUMMARY holds the run-wide counts. Reddit's own count includes removed and
collapsed comments it never renders, so a complete thread can sit slightly below 1.0.
Incremental growing-thread runs
Pass the comment IDs you already hold as skipCommentIds (with or without the t1_ prefix).
Known comments are neither saved nor charged, but their replies are still explored, so a scheduled
run picks up only what is new. Combine with postedAfter for a cheap time window.
Pricing
Pay per result: one comment-result event per unique comment delivered to your dataset. Never charged: duplicates across overlapping inputs, comments removed by your filters, comments on your skip list, comments cut off by a cap, the parent-post context, invalid or unavailable post URLs, empty threads, and the run summaries. This README deliberately quotes no figures — the live price is on the Pricing tab and in the Console.
Proxy and reliability
Use Apify Datacenter proxy (the default) or no proxy. Requests are paced to Reddit's own public rate budget per exit address, and an address that draws Reddit's "prove your humanity" page is rested and replaced.
Apify Residential proxy is not supported. The run fails at startup if apifyProxyGroups
includes RESIDENTIAL: comment pages are large and residential bandwidth is billed to the Actor
rather than to your run, while Reddit serves the same pages to datacenter addresses. If you need
residential routing, supply your own provider under Custom proxy URLs — that traffic goes through
your account and is honoured.
Limitations
- Very large threads. Logged out, Reddit does not page top-level comments beyond the first
page, nor a comment's replies beyond its first 24. The Actor sweeps all six sorts and every
reachable reply subtree to recover as much as it can, then marks the thread
pagination-unavailableinTHREAD_SUMMARYrather than calling it complete. Large threads are collected in full through a metered provider where the Actor is configured for it; the row shape is identical. isStickiedandisLockedare not published on Reddit's public comment markup and arenullthere; they are booleans on rows collected through the metered provider.isSubmitterandawardCountare the reverse: published on the public markup,nullfrom the metered provider.- No controversiality flag. Neither surface publishes one per comment; the
controversialsort orders by it. - Private, quarantined and login-only threads are reported as unavailable, not scraped.
- Deleted and removed comments keep their IDs and tree position with an empty body and
isDeletedOrRemoved: true; their original text is not recovered. - Reddit rate-limits by exit address; a run with many threads takes minutes, not seconds.
API and integrations
Feed post URLs straight from a Reddit post-search Actor and send authorUsername values on to a
Reddit user Actor. The dataset is flat JSON, CSV-friendly, and each row is self-describing.
Responsible use
Public comments can contain personal data. Comply with applicable law and Reddit's terms; do not use this Actor to reconstruct deleted or private content or to target individuals.
Changelog
- 1.0 — Initial release: flat comment rows with tree metadata, six sorts, nested reply expansion, target-comment mode, filters, skip lists, incremental pushing, honest completeness reporting.


