
PDF OCR to Markdown - Scanned PDF & Image to Text for RAG
Pricing
from $3.97 / 1,000 ocr pages
PDF OCR to Markdown - Scanned PDF & Image to Text for RAG
Convert PDFs, scans, images, DOCX and PPTX to clean Markdown for LLMs and RAG. Text layer used when present, Tesseract OCR for scans (EN, NL, DE, FR, ES, IT, PT, German Fraktur), per-page confidence. $0.00097 per text page, $0.00397 per OCR page.
Pricing
from $3.97 / 1,000 ocr pages
Rating
0.0
(0)
Developer
DigiVibeTech
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
6 days ago
Last modified
Categories
Features
Share
What does PDF OCR to Markdown do?
It turns PDFs, scanned documents, images, Word (DOCX, with headings, lists and tables) and PowerPoint (PPTX) files into clean Markdown that you can feed to an LLM, a RAG pipeline, a search index or a spreadsheet.
- Pages with a real text layer (born-digital PDFs) are extracted directly: fast, exact and cheap.
- Scanned pages and images are read with Tesseract 5 OCR, the open-source engine, which runs entirely inside the Actor. Your files are not sent to any third-party AI service.
- Every page gets an OCR confidence score. Pages that can't be read (blank, handwriting, very poor scans) are flagged and not charged.
- RAG-ready: optional
chunks(paragraph-aware, with page numbers) at no extra cost. - German Fraktur (blackletter) is supported, alongside English, Dutch, German, French, Spanish, Italian and Portuguese.
Why this one
- Text-layer pages are extracted directly ($0.00097) and only scanned pages use OCR ($0.00397), so mixed PDFs cost less.
- Tesseract 5 OCR runs inside the Actor: your files are not sent to a third-party AI service. Every page gets an OCR confidence score.
- Blank and unreadable pages are flagged and not charged, and RAG chunks with page numbers are included at no extra cost.
- PDF, images, DOCX and PPTX in, Markdown out, including German Fraktur.
- A 10-page scan costs $0.04 here. Pdf OCR API by cspnair, a popular PDF OCR actor on Apify, charges $0.01 per PDF (checked 29 Oct 2026), so it is cheaper for long scans and we are cheaper for short or mostly digital PDFs.
Screenshots
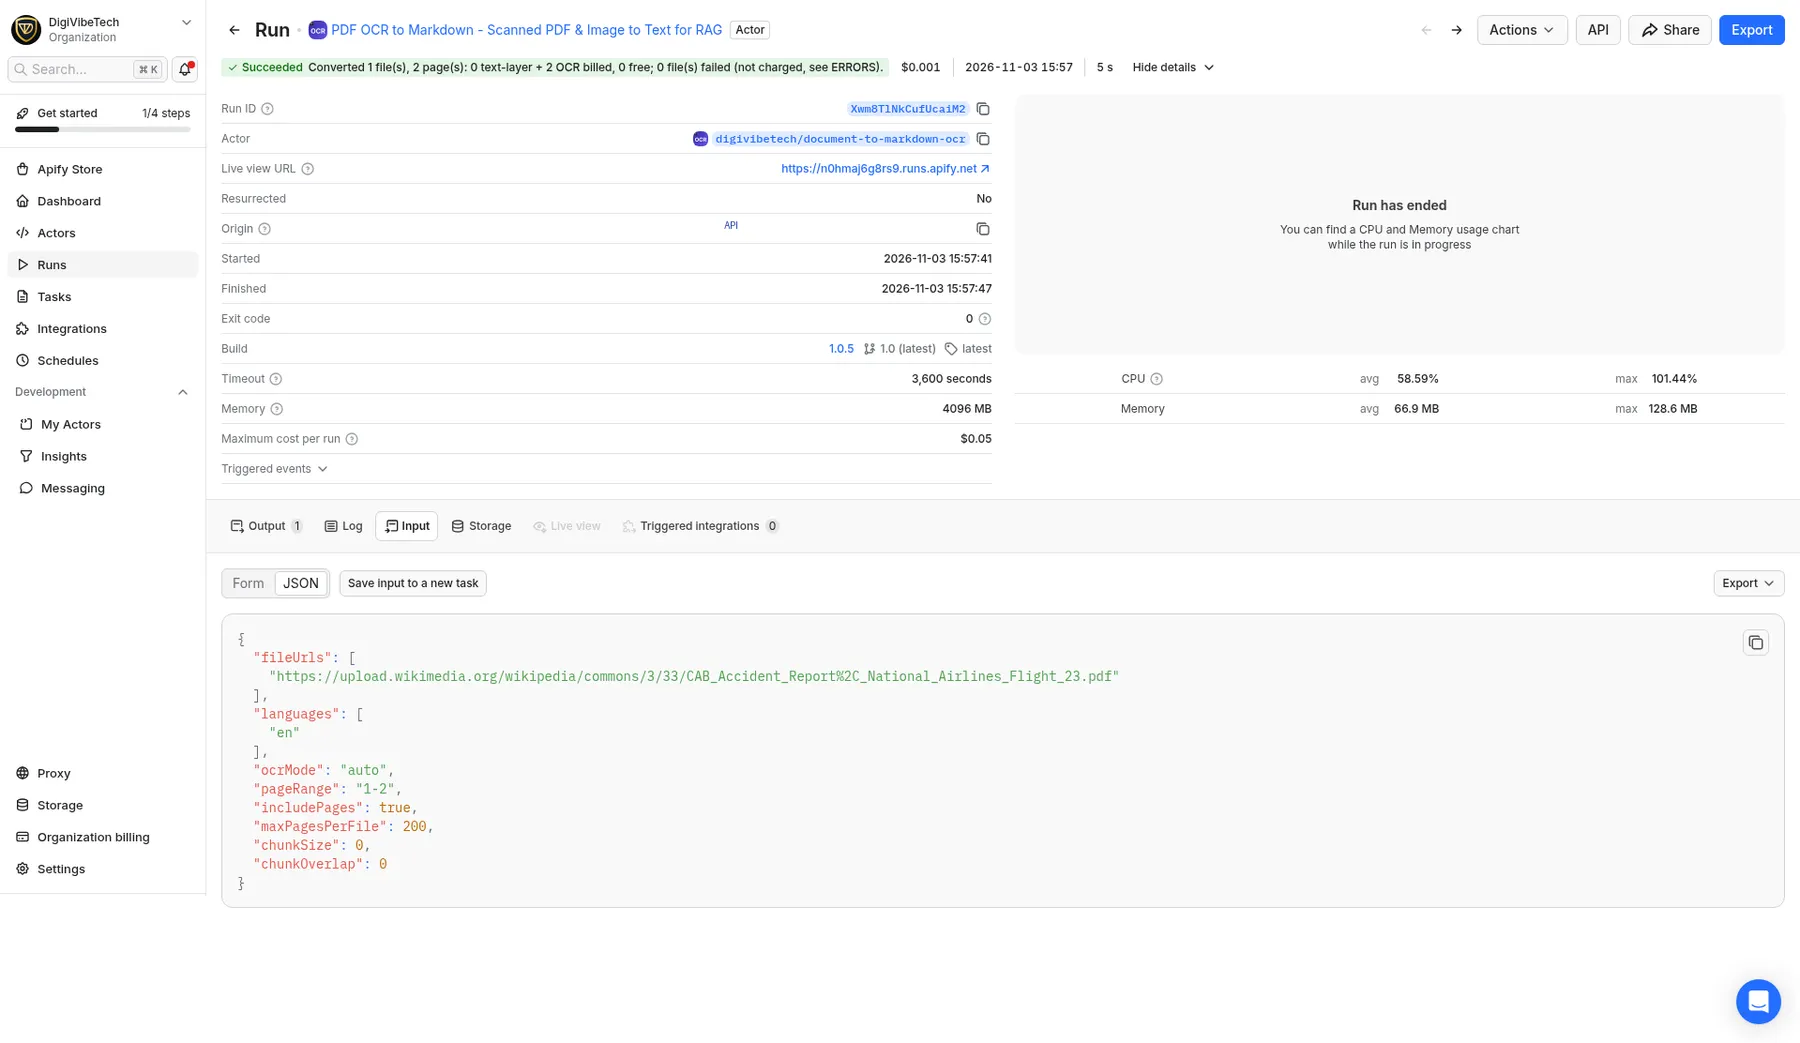
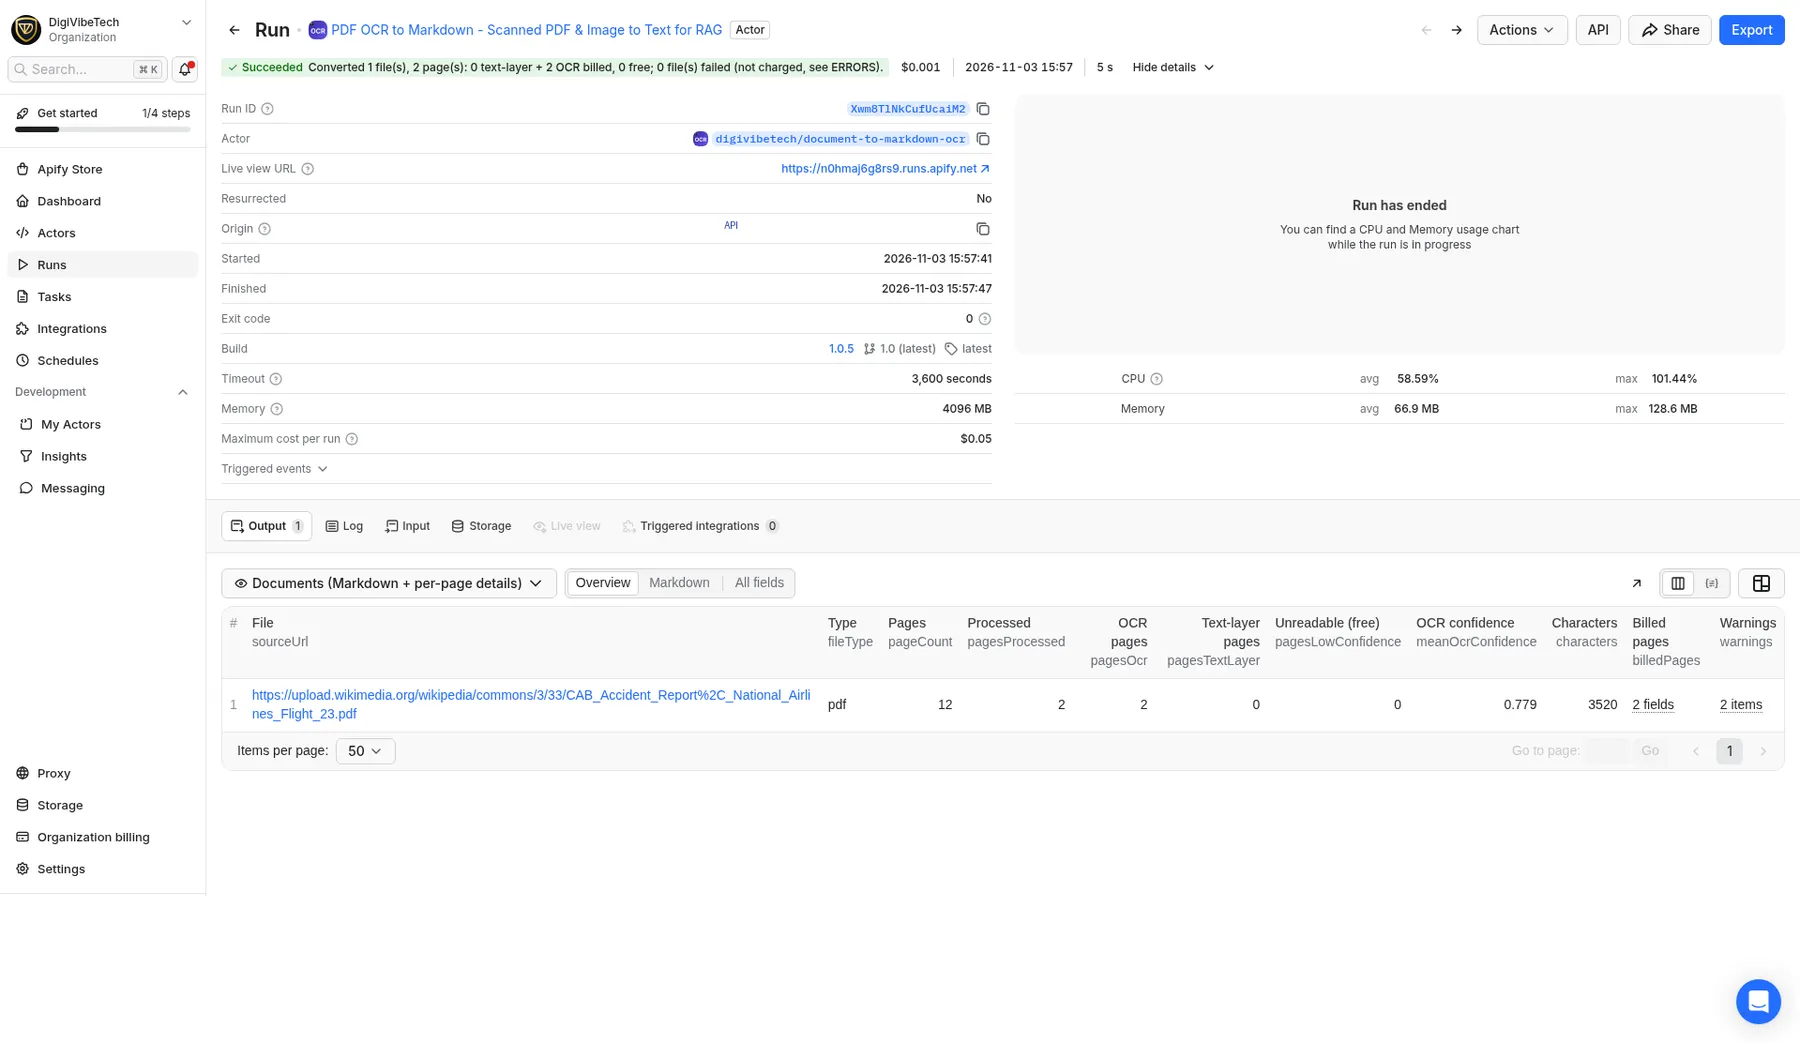
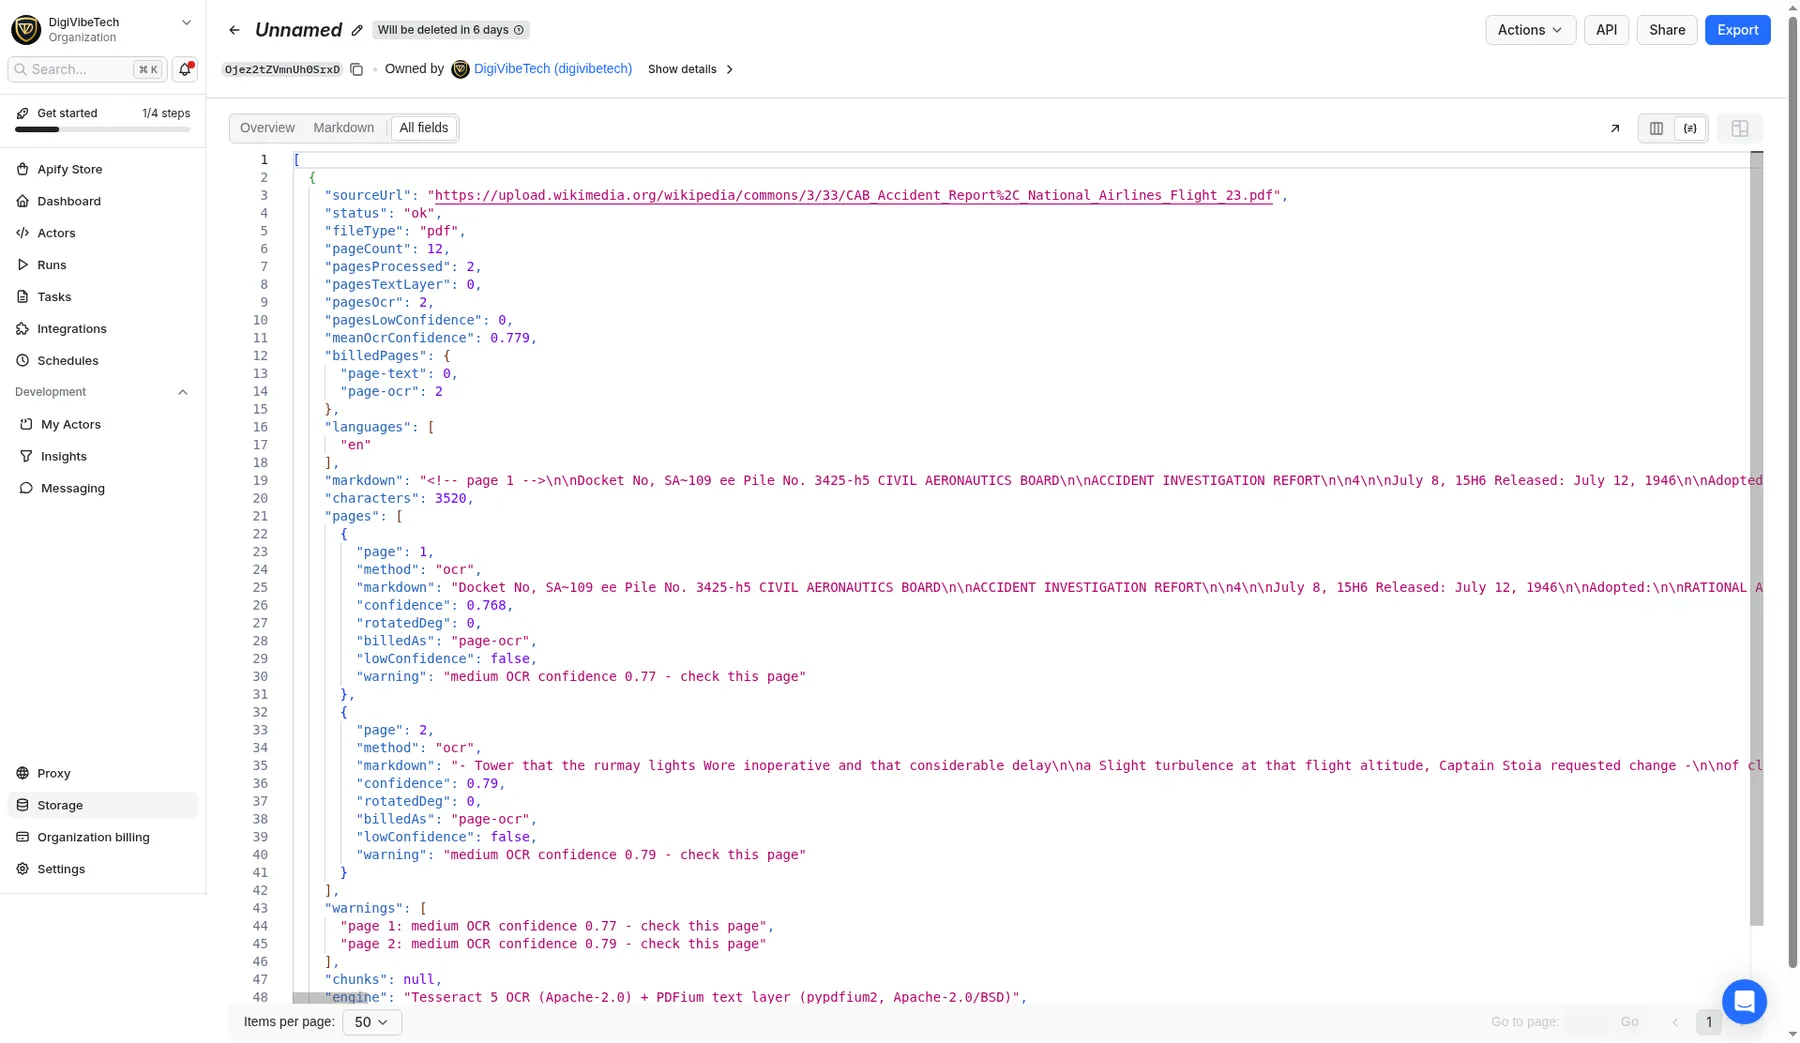
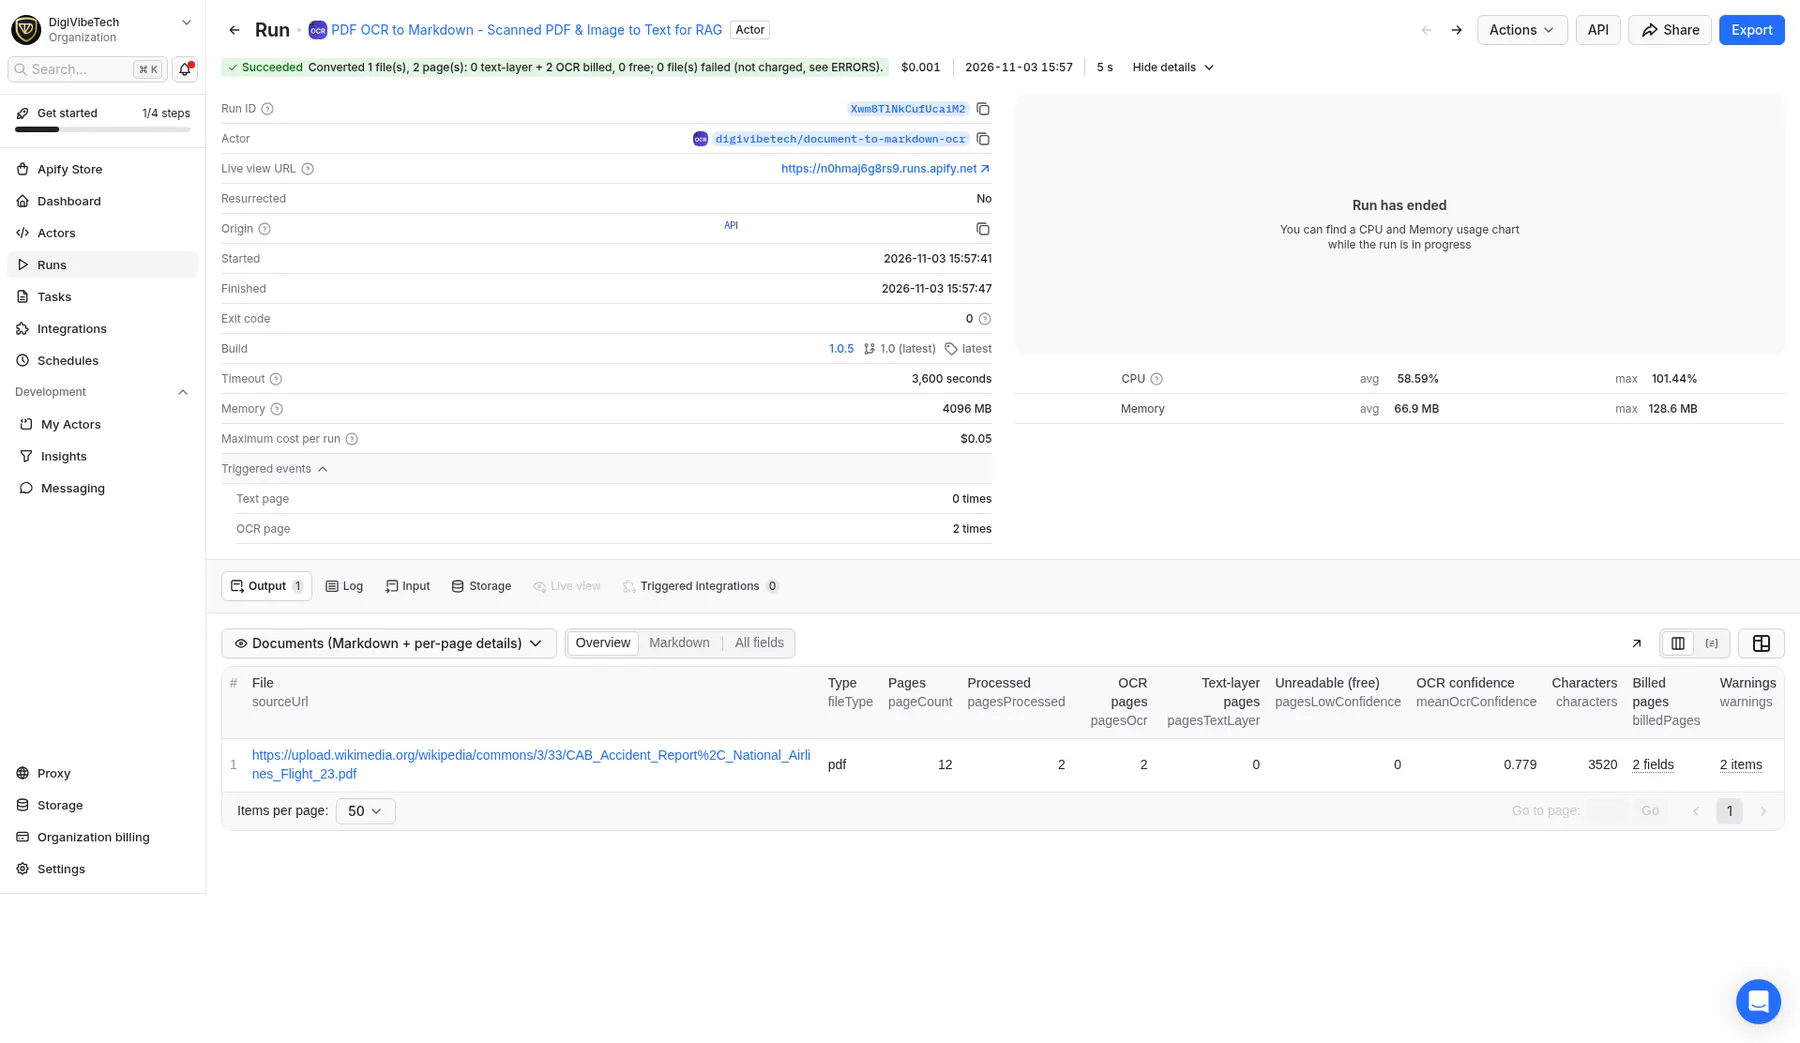
From a real run on 3 Nov 2026 (Europe/Amsterdam) on pages 1-2 of a public-domain 1946 Civil Aeronautics Board accident report scan (Wikimedia Commons): 1 document, 2 scanned pages read with OCR (mean confidence 0.78), billed as 2 OCR-page events.
Quick start: example input, output and cost
OCR for scanned PDFs and images: text and Markdown for RAG and LLMs, per-page confidence, German Fraktur. $0.00097 per text page, $0.00397 per OCR page, blank pages free.
Example input
Cost example: A 50-page scanned PDF x $0.00397 = about $0.20; a 50-page digital PDF x $0.00097 = about $0.05.
Example output (real run, 2026-11-04 UTC)
From a real run of this actor on a public-domain 1946 scanned accident report PDF from Wikimedia Commons, pages 1–3, English OCR (plus a missing file and a blocked internal address, which are not charged). One file, so the excerpt has 1 record. The scan is old, so the OCR text has typos; per-page confidence is in warnings. Markdown shortened:
Full sample from the same run (≤50 rows): JSON · CSV
Try it: run with {"fileUrls":["https://upload.wikimedia.org/wikipedia/commons/3/33/CAB_Accident_Report%2C_National_Airlines_Flight_23.pdf"],"languages":["en"],"pageRange":"1-3"}. That is 3 scanned pages × $0.00397 (page-ocr) = $0.0119 (about one cent). Pages with a text layer are $0.00097 each. Apify's free plan includes $5 of prepaid usage every month, so this run fits in it many times over.
Why use it?
| This Actor | |
|---|---|
| Price per scanned (OCR) page | $0.00397 |
| Price per text-layer page | $0.00097 |
| Start fee per run | none |
| Blank, unreadable or failed pages | free |
| Accuracy | published (see the benchmark below) |
| Per-page confidence | yes |
| Historic German Fraktur | yes |
How much does it cost?
You pay per successfully extracted page, and only after the result is saved:
| Event | Price | When |
|---|---|---|
page-text | $0.00097 | the page has a usable PDF text layer; also each PPTX slide or ~3,000 characters of DOCX text |
page-ocr | $0.00397 | the page was read with OCR |
Some examples:
- 100 born-digital PDF pages cost about $0.10 ($0.097).
- 100 scanned pages cost about $0.40 ($0.397).
- A 300-page scanned book costs about $1.19.
Set a maximum cost per run and the Actor will never go over it. Pages that don't fit are skipped and explained, not charged. Apify's free plan credit covers about 1,000+ scanned pages a month.
Input
- fileUrls: direct links to PDF, DOCX, PPTX, PNG, JPG, TIFF (including multi-page), WEBP, GIF or BMP files, up to 200 MB each. Share links to public Google Drive and Dropbox files are converted automatically.
- languages: up to 3 languages. Choose
de-frakturfor old German print. - ocrMode:
autouses the text layer when present and OCR otherwise;alwaysOCRs every page;neveruses the text layer only. - pageRange: for example
1-5,2,4,9or10-. - chunkSize / chunkOverlap: set e.g. 1500 / 150 to get a
chunksarray for embeddings. Each chunk lists its source pages.
Output
You get one dataset item per document:
- Each page starts with an invisible
<!-- page N -->marker, so you can cite or split by page. - Very large documents (over 2 million characters) store the full Markdown in the run's key-value store, and the dataset item links to it.
- Files that fail are listed in the
ERRORSkey-value record with the reason. They are never charged.
Accuracy benchmark (real scans, not generated pages)
We measured the Actor on 35 real book and archive pages from Wikisource. The scans are public domain, and the ground truth is human-proofread ("validated") text under CC BY-SA. The metric is character error rate (CER); lower is better.
| Material | Pages | Median CER | Median word error | Median confidence |
|---|---|---|---|---|
| English, 19th–20th c. print | 14 | 4.8% | 8.1% | 0.92 |
| Dutch, modern print | 5 | 1.8% | 9.0% | 0.94 |
| German, modern print | 4 | 6.3% | 13% | 0.90 |
German Fraktur, de-fraktur | 6 | 5.8% | 28% | 0.86 |
German Fraktur, plain de (for comparison) | 6 | 13.6% | 50% | 0.66 |
| Dutch, 17th–18th c. print | 2 | 13.8% | 40% | 0.81 |
| Handwriting (Kurrent) | 4 | ~71%, not supported | – | 0.33 (not charged) |
Some of the remaining error comes from page headers, footnotes and multi-column layouts that the proofread text arranges differently.
Limitations (honest list)
- Handwriting is not supported. It is detected by low confidence and not charged.
- Layout: the output is paragraphs in reading order. Tables come out as text lines rather than Markdown tables, and complex multi-column pages may mix columns.
- No images or formulas: pictures are skipped, and math is OCR'd as plain text.
- Speed: about 1.5–4 seconds per scanned page per vCPU with one language. Every extra language adds time (with 3 languages it is about 6 s per page). Give the Actor more memory (1 vCPU per 4 GB) to process pages in parallel.
- Downloads: files must be reachable by a direct link. Servers that block automated downloads (HTTP 403) are reported, not charged.
Privacy and legal
- Documents are processed inside your Apify run and are not sent to any external API.
- Only process documents you have the right to process.
- It uses Tesseract (Apache-2.0), tessdata_fast models (Apache-2.0) and PDFium via pypdfium2 (Apache-2.0/BSD).
FAQ
Does it work with photos of documents? Yes, as long as they're reasonably sharp and flat. Rotation is detected automatically.
Can I use it through the API, Make, Zapier or n8n? Yes. It works like any Apify Actor: call it with the input JSON and read the dataset.
Found a problem? Open an issue on the Issues tab. We read every one.
Maintained by DigiVibeTech. Questions or bugs: use the Issues tab or digivibetech.com/support; we reply within 2–5 business days.


