
PDF Text Extractor - PDF to Text, Per Page, Metadata, Fast
Pricing
$0.49 / 1,000 pdf page with text extracteds
PDF Text Extractor - PDF to Text, Per Page, Metadata, Fast
Extract the text of PDF files from URLs: full text, per-page text, page count, title, author, dates, producer, encryption flag and a needs-OCR hint for scanned pages. Fast, no browser. $0.00049 per page with text; empty pages free.
Pricing
$0.49 / 1,000 pdf page with text extracteds
Rating
0.0
(0)
Developer
DigiVibeTech
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
6 days ago
Last modified
Categories
Features
Share
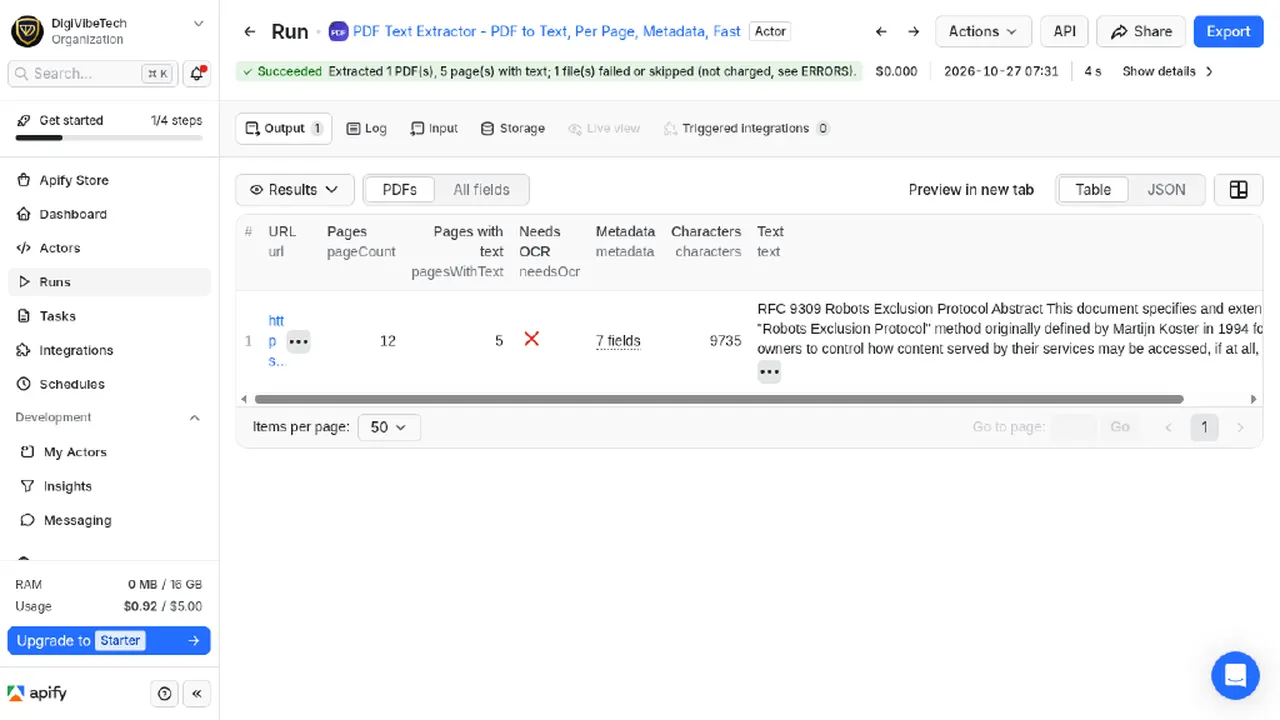
Give it PDF links, get back full text, per-page text, page count and metadata (title, author, subject, creator, producer, created/modified dates, encryption) in one dataset item per file. Fast: reads the PDF's text layer directly, no OCR, no browser.
Scanned pages (no text layer) are detected and listed in pagesWithoutText, with a needsOcr hint. For scanned documents use our OCR actor Document to Markdown OCR.
Why this one
- Full and per-page text, PDF metadata and scanned-page detection in one run.
- $0.00049 per page with text: a 40-page PDF costs $0.02. Other PDF text actors on Apify charge per PDF: PDF Text Extractor by automation-lab $0.00345 (Free plan) plus $0.005 per run, PDF Text Extractor by memo23 $0.005 plus $0.005 per run, and PDF to Text Extractor by gochujang $0.02 plus $0.001 per page (checked 28 Oct 2026).
- Empty and scanned pages without a text layer are free, and files that fail cost nothing.
Screenshots
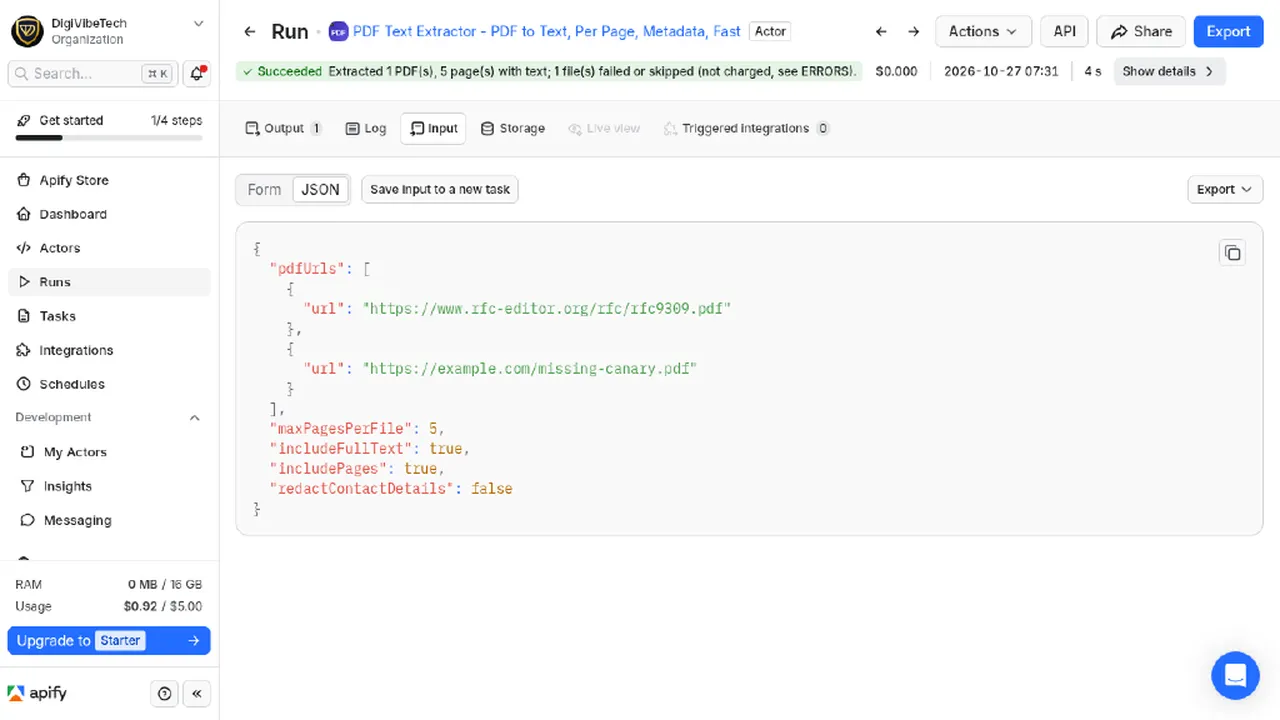
From a real Console run, 27 Oct 2026 (run fBrEu39gqejrepHCP): public RFC 9309 PDF (rfc9309.pdf, 12 pages, 9,735 chars of text), plus 1 missing file on purpose (skipped, not charged).
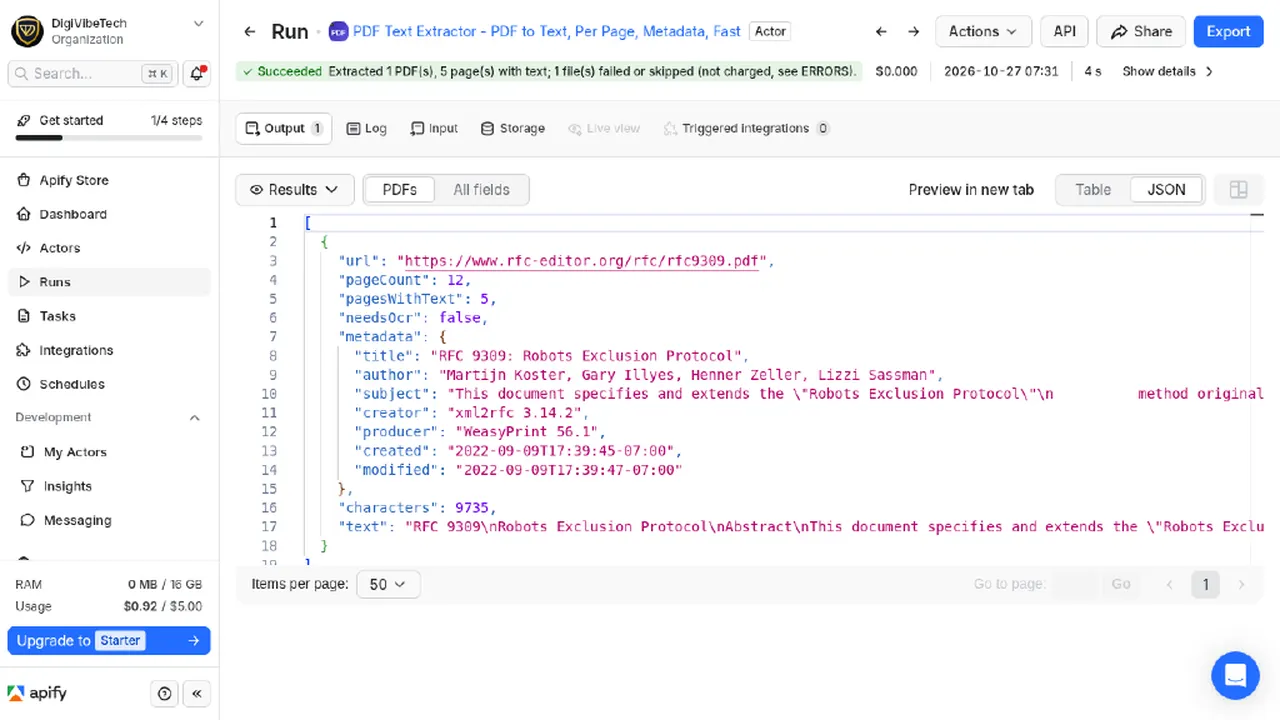
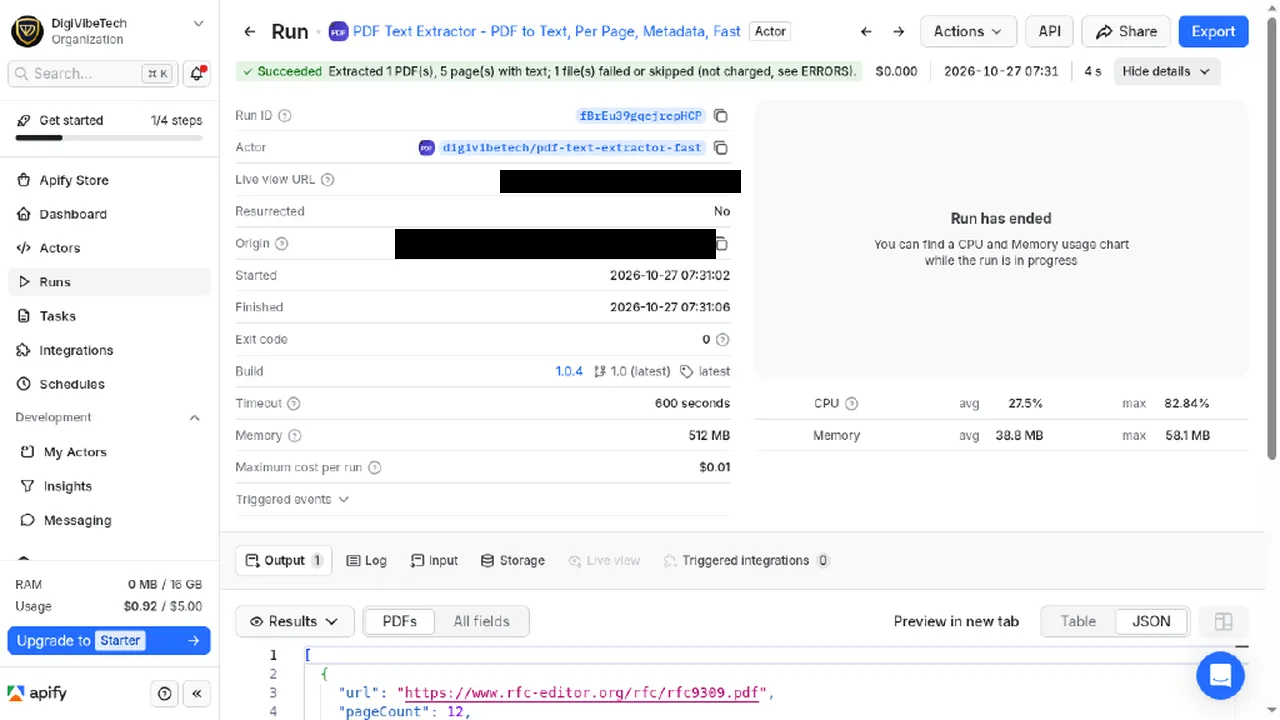
Quick start: example input, output and cost
Fast PDF text extraction from URLs: full and per-page text, metadata, scanned-page detection. Pay per page with text, empty pages free.
Example input
Cost example: A 40-page PDF x $0.00049 = $0.02; 1,000 pages = $0.49.
Limits
- No OCR: scanned pages without a text layer return no text and are free. Use our Document to Markdown OCR actor for scans.
- Tables and columns come out as plain text in reading order; the layout is not kept.
- Password-protected files need the password.
Pricing (pay per event)
- $0.00049 per page with text. No start fee, no per-file fee.
- Image-only pages, unreadable or password-protected files (without password), failed or blocked downloads are free and explained in ERRORS.
- Use
maxPagesPerFileandpageRangeto cap cost; your max cost per run is respected exactly.
Good for
RAG / LLM ingestion, search indexing, contract and report analysis, invoice/text pipelines, bulk document archives.
Responsible use
Process only files you own or may use. robots.txt is checked for every file URL (RFC 9309), max 1 request per second per site, 50 MB per file, private/internal addresses refused. Optional redaction of emails and phone numbers.
Maintained by DigiVibeTech.
Maintained by DigiVibeTech. Questions or bugs: use the Issues tab or digivibetech.com/support; we reply within 2–5 business days.


