
Sitemap Extractor - All URLs from sitemap.xml, New Pages
Pricing
from $0.44 / 1,000 url extracted from a sitemaps
Sitemap Extractor - All URLs from sitemap.xml, New Pages
Extract every URL from a website's XML sitemaps (index, .gz, robots.txt discovery) with lastmod, hreflang and images. Filter by date or regex, get only pages new since the last run, optionally check status codes. $0.00044 per URL.
Pricing
from $0.44 / 1,000 url extracted from a sitemaps
Rating
0.0
(0)
Developer
DigiVibeTech
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
Get every URL from a website's XML sitemaps in seconds, with lastmod, changefreq, priority, hreflang alternates and image counts. Give it a plain site URL: sitemaps are found via robots.txt, /sitemap.xml or /sitemap_index.xml, nested sitemap indexes and .xml.gz files are followed.
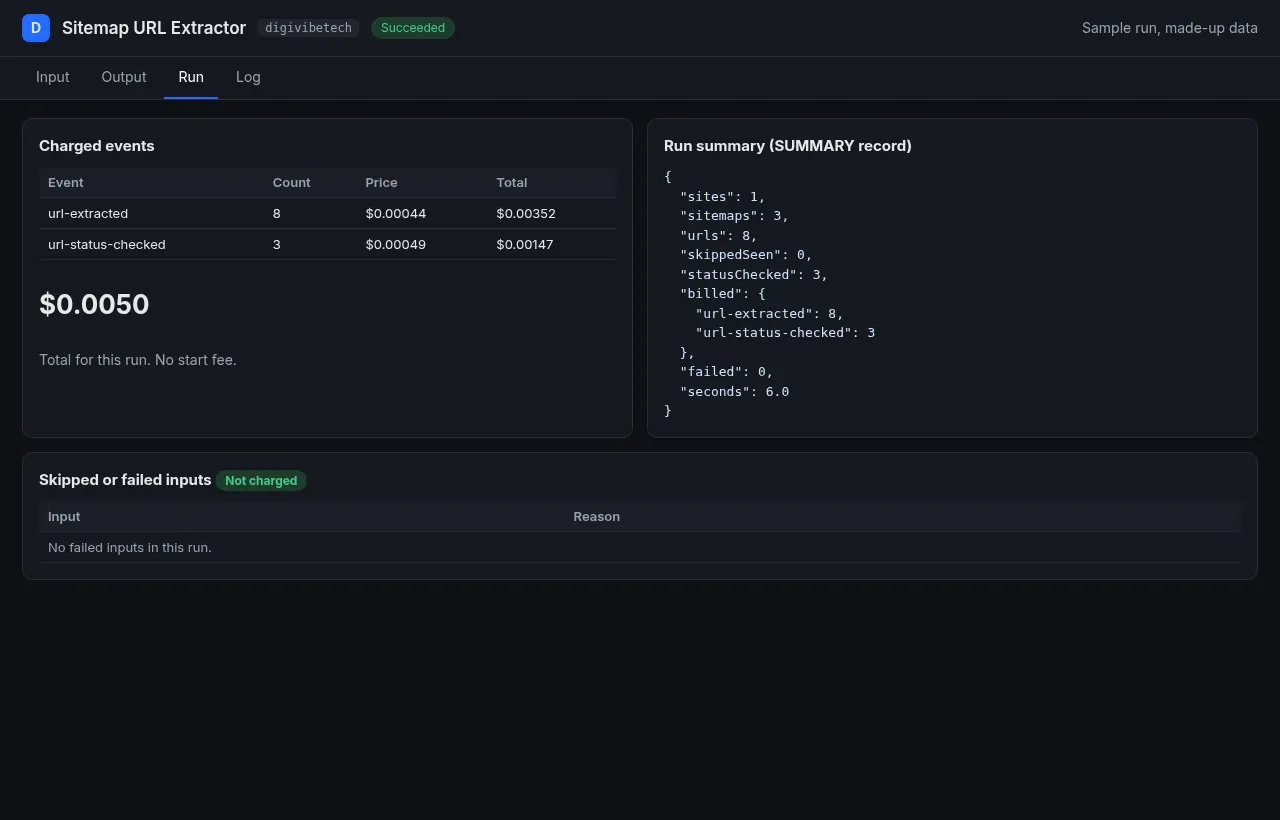
$0.00044 per URL, no start fee. Optional status checks: $0.00049 each. Failed sitemaps are free.
Why this one
- Only-new mode: schedule it and later runs return (and charge for) URLs that were not seen before. The most-used rival (Sitemap URL Extractor, 655 users, checked 27 Oct 2026) does not list this.
- $0.00044 per URL with no start fee. That rival charges $0.03 per result on Apify's Free plan and $0.001 to $0.0028 on paid plans, plus a start fee (checked 27 Oct 2026). Failed sitemaps are free.
- Extraction does not request every page, so it is fast and light on the target site. Status checks are optional, capped and polite.
- Finds sitemaps via robots.txt, /sitemap.xml and nested indexes, including .xml.gz files.
- Hard maxUrlsPerSite limit, filters (lastmodAfter, include/exclude regex) and XML bomb/XXE protection.
Screenshots
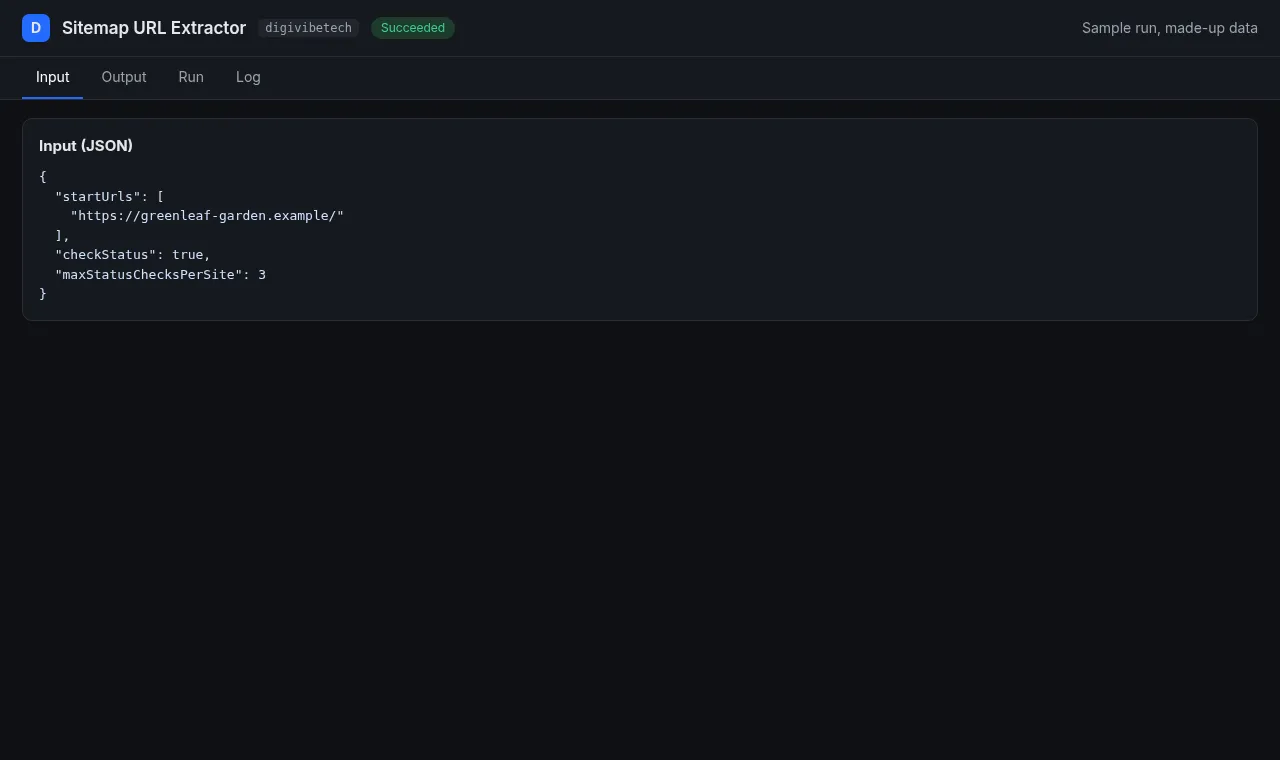
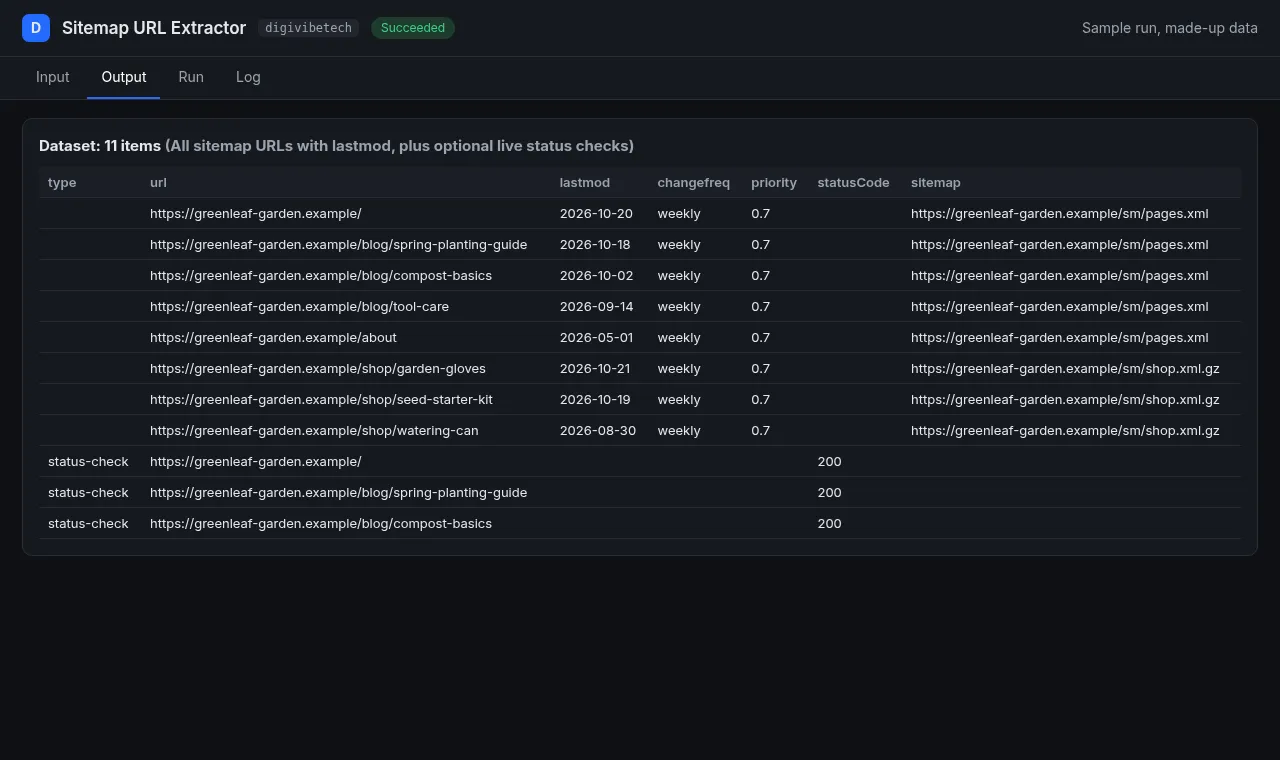
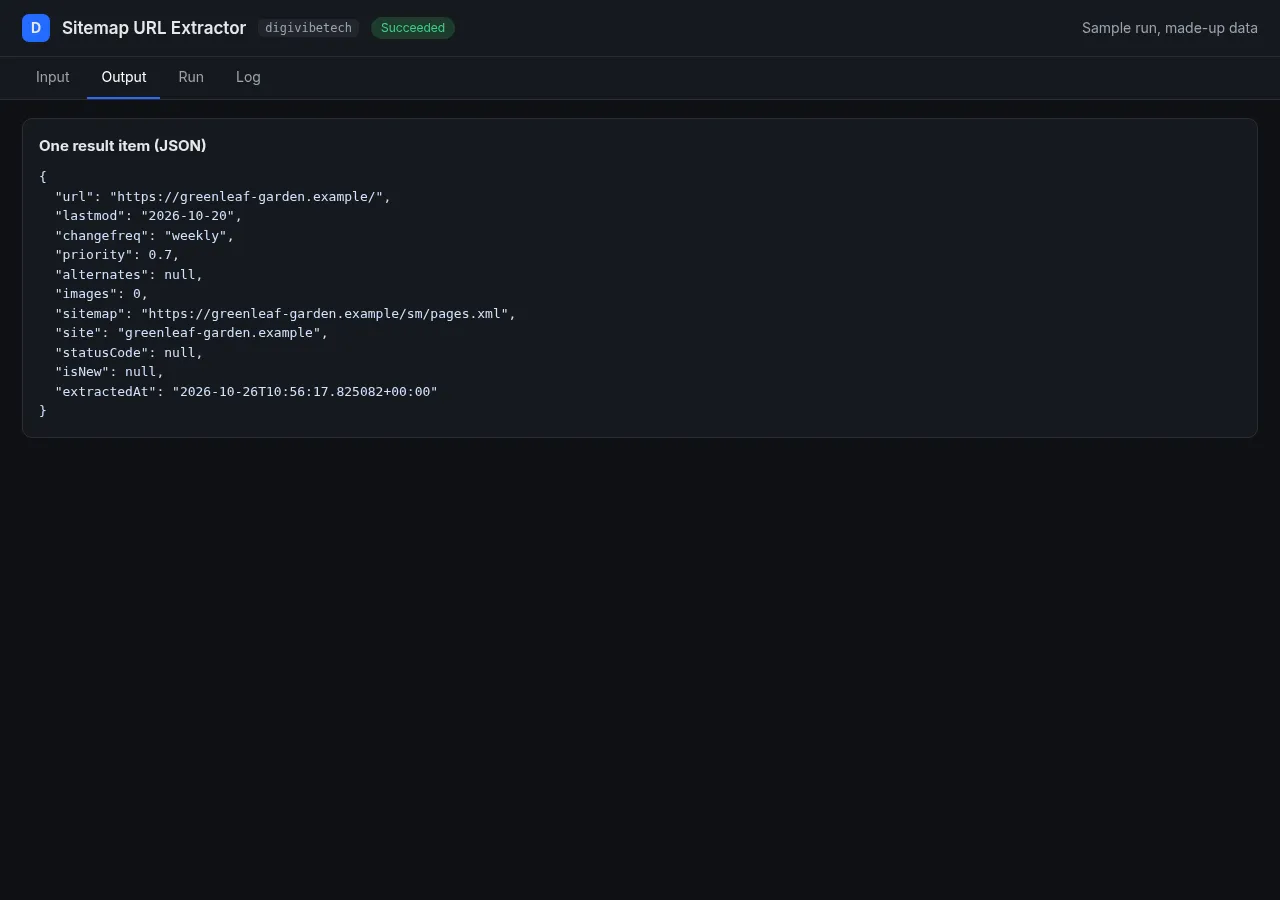
From a sample run with made-up data.
Quick start: example input, output and cost
Get all URLs from XML sitemaps with lastmod and hreflang. Monitor competitors for new pages, filter by date, optional status checks. Pay per URL.
Example input
Cost example: A 10,000-URL sitemap x $0.00044 = $4.40; with only-new mode later runs pay only for new URLs.
Use cases
- Monitor competitors for new pages (products, blog posts, landing pages): switch on
onlyNewUrls, schedule daily, and you pay only for URLs that are new since the last run. - SEO audits: list every indexed URL, find stale pages with
lastmodAfter, check hreflang coverage, spot redirects withcheckStatus. - Crawl seeding: feed the URL list to our Website to Markdown Crawler or On-Page SEO Audit actors.
Output
URL items: url, lastmod, changefreq, priority, alternates[], images, sitemap, site, isNew, extractedAt.
Status-check items (type: "status-check"): url, statusCode, finalUrl, redirected. Totals in SUMMARY, problems in ERRORS.
Limits
- Sites without a sitemap.xml (or one robots.txt does not point to) return nothing to extract.
- A sitemap lists what the site chose to publish; it can be stale or incomplete.
- Pages are only requested when you switch on the status check.
Responsible use
Sitemaps are published by site owners for crawlers. We still obey robots.txt for every request, make at most about one request per second per site, use an honest User-Agent (SitemapReader/1.0), and never log in or bypass bot protection.
| Event | Price |
|---|---|
| URL extracted | $0.00044 |
| URL status checked (optional) | $0.00049 |
Maintained by DigiVibeTech. Questions or bugs: use the Issues tab or digivibetech.com/support; we reply within 2–5 business days.


