
Patreon Scraper
Pricing
from $1.27 / 1,000 results
Patreon Scraper
Patreon Scraper collects public Patreon creator pages by search keyword or profile URL. Returns campaign name, creator, patron and paid-member counts, post count, membership tiers with prices, Discord access, social links, about text and monthly earnings when public. Export to JSON, CSV or Excel.
Pricing
from $1.27 / 1,000 results
Rating
0.0
(0)
Developer

Fast Data API
Maintained by CommunityActor stats
0
Bookmarked
3
Total users
2
Monthly active users
14 days ago
Last modified
Categories
Security
Limited permissionsShare
Patreon Scraper — Members, Tiers, Earnings and Social Links
Patreon Scraper collects public Patreon creator pages by search keyword or profile URL: campaign and creator name, member and paid-member counts, post count, membership tiers with prices and Discord access, monthly earnings when the creator publishes them, about text and social links. Every response is structured JSON — ready to pass directly to an LLM, index into a vector store, or feed a creator research or sponsorship pipeline. No Patreon account or cookies needed. Start with one keyword, then build a full list of creators in your niche.
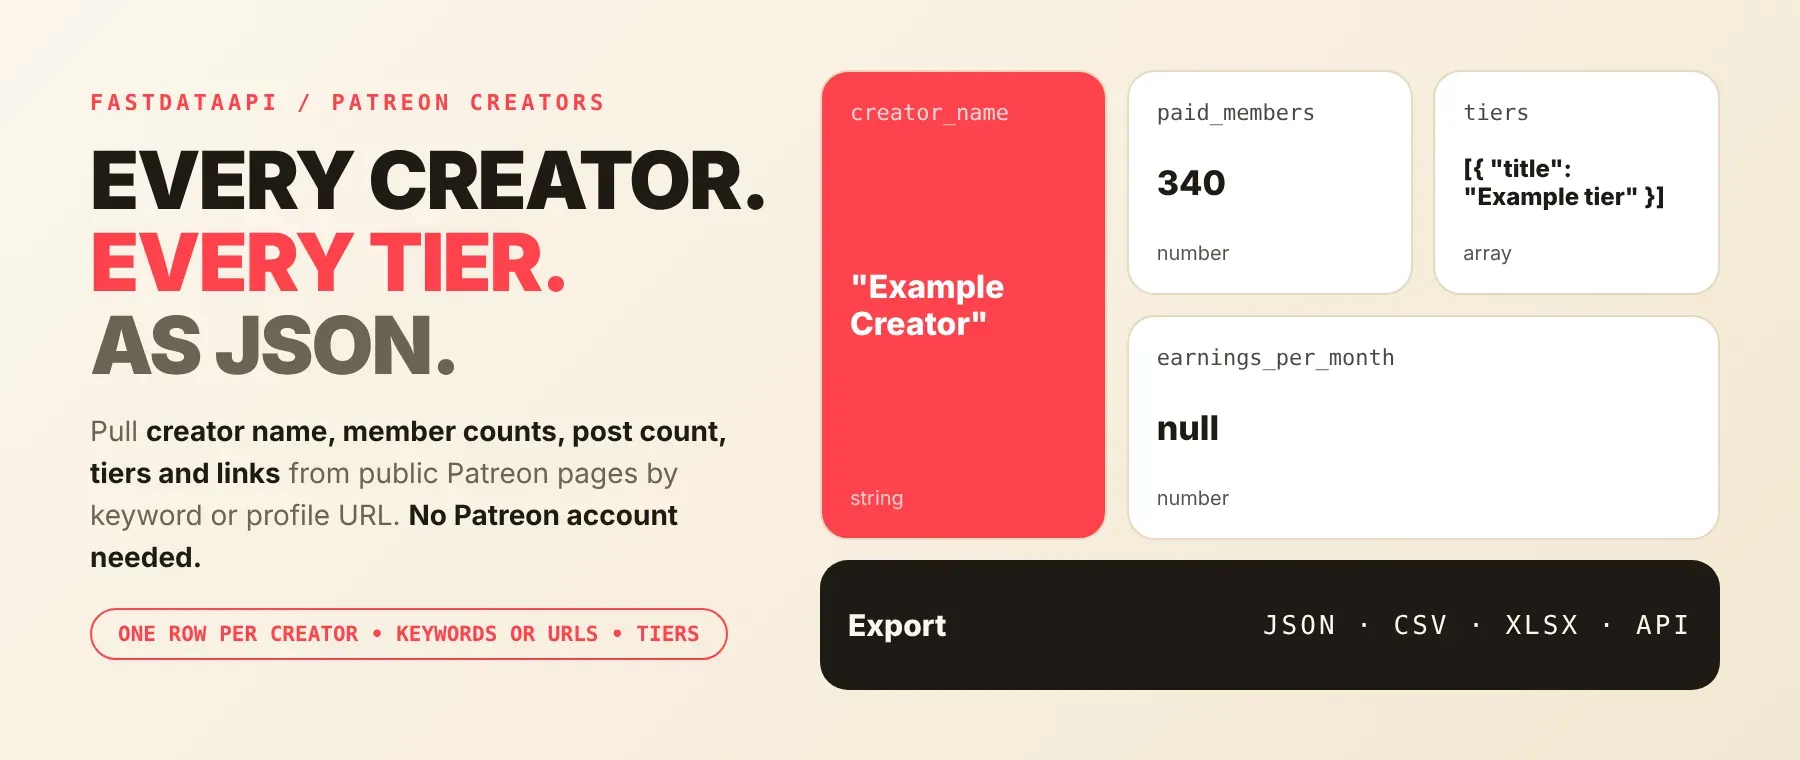
What data can I extract with Patreon Scraper?
Using this Patreon Creator API, you will be able to extract the following Patreon creator data:
| 🏷️ Campaign name | 👤 Creator name | ✍️ What the creator makes | 🔗 Creator page link |
|---|---|---|---|
| 👥 Member count (if public) | 💳 Paid member count | 📝 Post count | 🎟️ Membership tiers with prices |
| 💬 Discord access per tier | 💰 Monthly earnings (if public) | 🙈 Earnings hidden flag | 💱 Earnings currency |
| 📖 About text | 🌐 All social links | ▶️ YouTube link | 📸 Instagram link |
| 🐦 X / Twitter link | 📘 Facebook link | 🎮 Twitch link | 🎵 TikTok link |
| 🖼️ Avatar image | 🌫️ Blurred avatar | 🔍 Small thumbnail | 🎨 Page theme colour |
| 🔞 Adult content flag | 🆔 Campaign ID | 🔎 Keyword it came from | ⚠️ Reason a creator could not be loaded |
How to use Patreon Scraper
Built for creator-economy analysts, sponsorship teams and marketers: one run turns a list of keywords and profile links into a table of Patreon creators with their members, tiers and earnings.
Copy to your AI assistant:
Patreon Scraper MCP Server: use these Actors from ChatGPT, Claude or Cursor
Point your AI assistant at Apify and it can read Patreon on its own: creators by keyword or profile link, with their members, tiers, earnings and social links. No glue code, no scraping logic in your prompts.
Step by step
- Create a free Apify account.
- Open Patreon Scraper in the Apify Store.
- Type your keywords or paste Patreon creator links, one per line, and set how many creators you want per keyword.
- Click Start (or send your API request).
- Download or stream your results in JSON, CSV or Excel.
How to scale Patreon Scraper to bulk
Put any number of keywords and creator links in one run, mixed in the same list. Each keyword returns up to 500 creators, limited by what Patreon's search has for it; each link returns one row. Creators are loaded 20 at a time and saved as soon as each is ready, so you can read the dataset while the run is going. A recorded run returned 60 creators for two keywords in 9.5 seconds. To scrape Patreon creators for a whole niche, add every related keyword, then export Patreon creators to CSV or Excel when the run ends; as a Patreon tiers scraper it also keeps every tier price for side-by-side comparison. To track creators over time, schedule the same run daily or weekly in Apify Console.
✨ Features
Patreon Scraper fetches clean, structured creator pages from Patreon ⚡. It's ideal for building a Patreon creator list, sponsorship shortlists, tier price research and creator-economy market sizing — a Patreon creator scraper and Patreon search scraper in one that returns Patreon campaign data, Patreon earnings data where creators publish it, and each Patreon members count. It extracts, per creator:
- Members – member count and paid member count, when the creator shows them
- Tiers – every paid tier with name, price, description and Discord access
- Earnings – monthly earnings and currency, or a flag that the creator hides them
- Identity – campaign name, creator name and what the creator makes
- Socials – every connected social profile, plus separate YouTube, Instagram, X, Facebook, Twitch and TikTok links
- About – the creator's about text with paragraphs kept
⚡ When a creator from a keyword can't be loaded, the next search result takes its place, so you still get the number of creators you asked for; the failed creator is listed as a free row.
Use cases 💡
- Sponsorship manager — shortlist creators by paid member count and public monthly earnings.
- Creator-economy analyst — size a niche by summing member counts across a keyword.
- Creator — compare tier names and prices of similar creators before pricing your own.
- Growth marketer — collect creators' YouTube, Instagram and TikTok links for outreach.
- AI engineer — index creator about texts and tiers into a RAG store for creator questions.
Building an AI agent? Connect Patreon Scraper over MCP and let it call the actor on its own.
Why choose this actor?
- Many creators per keyword, quickly. A recorded run returned 60 creators for "python" and "web development" in 9.5 seconds, with the first row after 2.7 seconds.
- The numbers behind each creator. A recorded creator came back with 4,224 members, 617 paying members, 494 posts, four tiers from $5, and Instagram and YouTube links.
- Two kinds of input, one list. Keywords and creator links mix in the same input, and 34 fields come back for every creator.
⬇️ Input
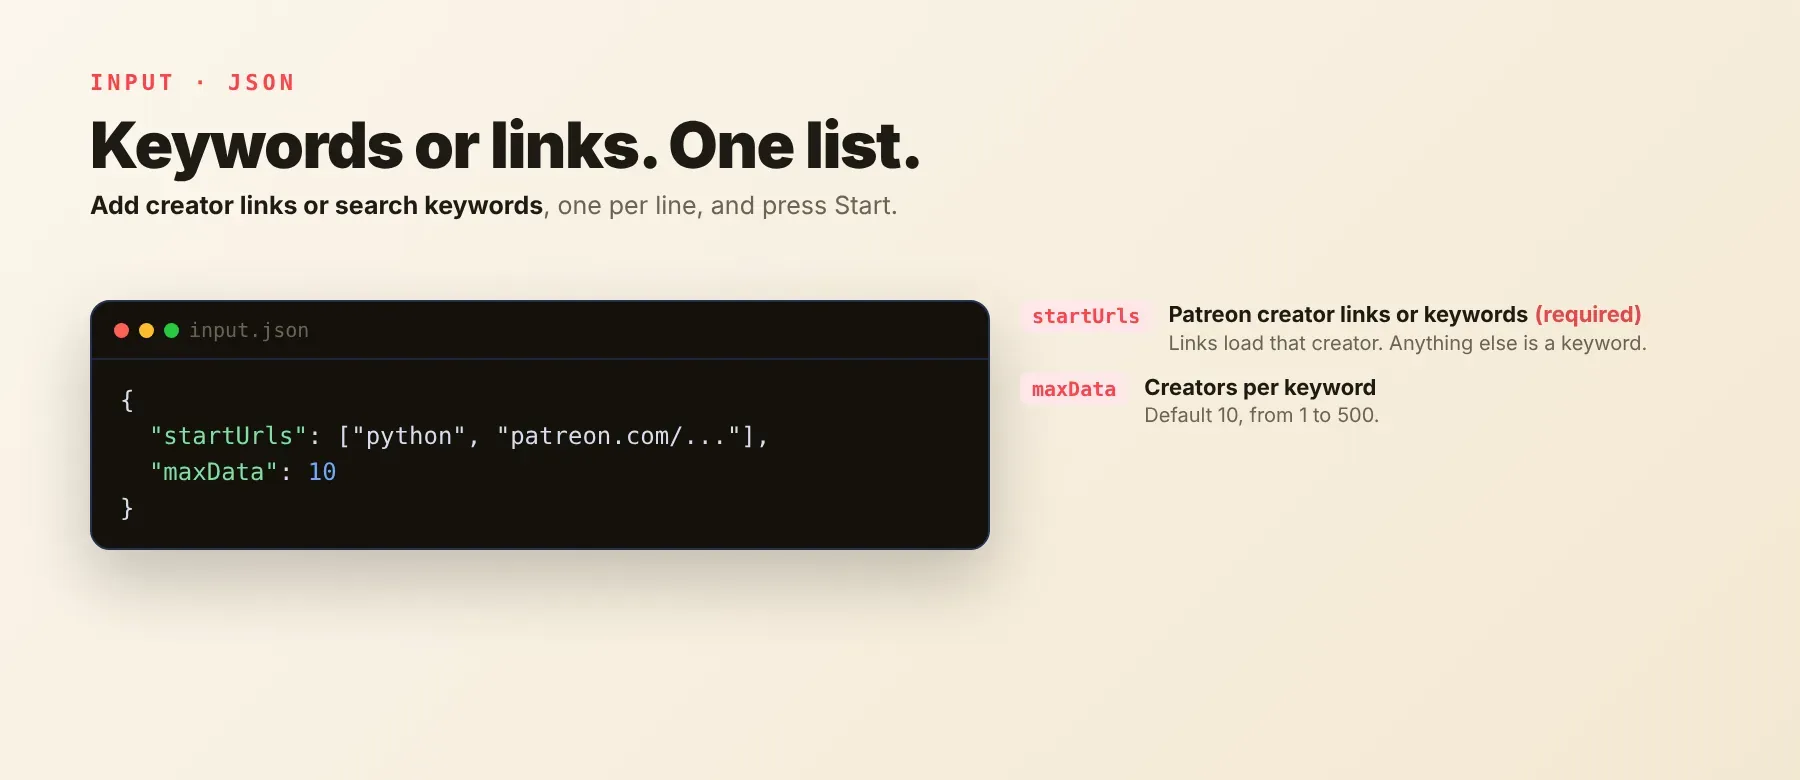
Enter Patreon creator links, search keywords, or both; the list is required.
| Parameter | Required | Type | Description | Example value |
|---|---|---|---|---|
startUrls | Yes | array | An item containing patreon.com/ is loaded as that creator (https://www.patreon.com/GreenRoomPythons or https://www.patreon.com/cw/codewithsadee). Anything else, including a bare username, is used as a Patreon search keyword. | ["python", "https://www.patreon.com/GreenRoomPythons"] |
maxData | No | integer | Creators per keyword, 1–500. Default 10. Creator links always return one row each. | 20 |
proxyConfiguration | No | object | Optional. Without it the actor connects directly and adds Apify proxies on its own when Patreon refuses requests. A proxy you select is used from the first request. | {"useApifyProxy": false} |
Patreon's own search lists 41–167 creators per keyword (measured on 2026-10-13). If you ask for more than a keyword has, you get every creator Patreon lists, and the run log says how many that is.
Free plan limits
Free plan: up to 20 creators per run (all keywords and direct profile URLs together) and 200 per month; paid plans have no limit.
Example input
⬆️ Output
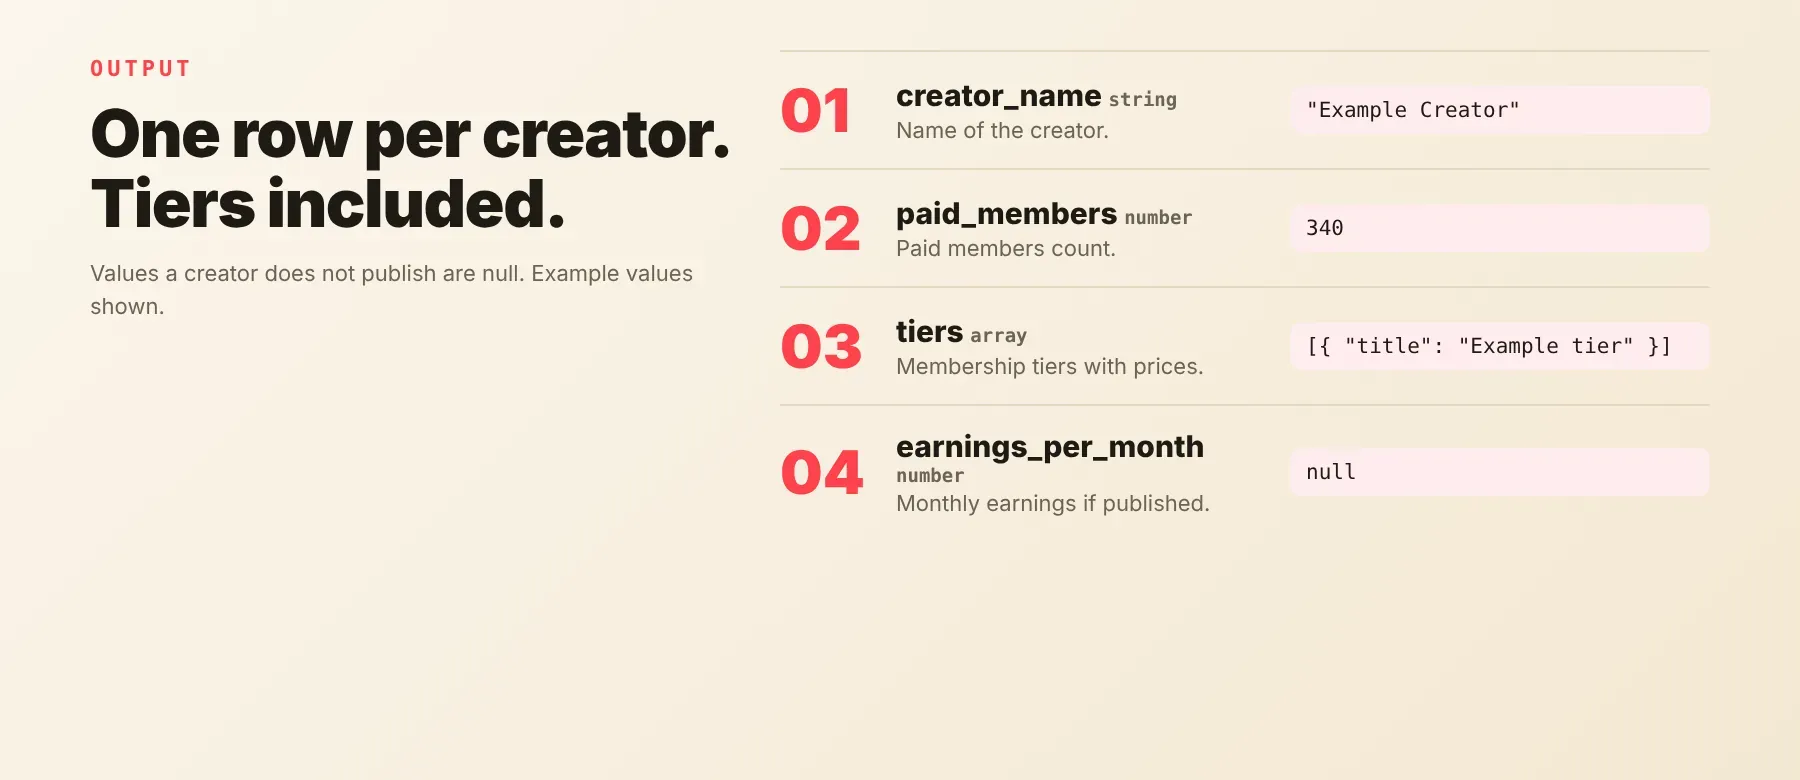
Every creator is one typed, normalized JSON item with the same fields on every run; values a creator does not publish are null. Export the dataset as JSON (default), CSV or Excel; a creator that could not be loaded gets one free row with the reason.
Example output
A recorded creator (about text and tier descriptions shortened, two of four tiers shown), followed by the row for a profile link that does not exist:
The keyword column holds the search keyword the creator came from, or direct for a creator link. The source column says which of Patreon's two public creator pages the row was read from; both give the same fields. Rows with success false are not charged.
How does it work?
The actor uses Patreon's own creator search for your keywords, then opens each creator's public page, the same pages any visitor sees without logging in. If one page for a creator does not answer, it reads Patreon's second public page for that creator, so creators don't drop out of your results. Values from the search results fill in what a page leaves out, such as the member count and the theme colour. Requests that Patreon refuses are paused and retried, and the actor adds Apify proxies on its own when needed. It returns only publicly visible data, and the output fields stay the same from run to run, so your code and spreadsheets keep working when Patreon changes its pages.
How do you integrate Patreon Scraper into your stack?
It works with what you already use: the REST API from any language, MCP for AI agents, and no-code tools.
Using Patreon Scraper with the Apify API
Works in Go, Ruby, Node.js, cURL — any language that can make an HTTP request.
MCP integration for AI agents
Add the Apify MCP server to your AI client with one command:
This registers Patreon Scraper as a tool your agent can call directly: the agent finds it through the server's search, adds it and runs it, then reads the creators back as JSON. Ask for "Patreon creators who teach Python, with their tier prices" and it does the rest. It works in Claude Code, Cursor and Windsurf.
No-code tools (n8n, Make, LangChain)
n8n: add the Apify node and choose "Run an Actor", or use the HTTP Request node pointed at the run-sync endpoint with your token. Send new creators to a Google Sheet or your CRM in the next node.
Make: use the Apify app's "Run an Actor" module, then "Get Dataset Items" to pull the creators into the rest of your scenario.
LangChain: install langchain-apify and wrap the actor with ApifyActorsTool("patreon-scraper") so your agent can look up Patreon creators by keyword.
Is it legal to scrape Patreon data?
Collecting public Patreon creator pages is generally lawful: creators publish these pages so anyone can find and join them. This actor returns only publicly available data — what any visitor sees without logging in: campaign names, member counts, tier prices, earnings the creator chose to show, and social links. It never reads member-only posts or who the members are. GDPR: scraping public data is generally permissible, but storing and using it must comply with local data-protection law. Consult legal counsel if your use case involves bulk storage of personal data.
Frequently asked questions
What fields does Patreon Scraper return?
It returns each creator's campaign name, member and paid member counts, membership tiers with prices, monthly earnings when published, and social links. See the data fields section for the full list.
Does Patreon Scraper require a Patreon account or login?
No. Only public Patreon creator data is extracted, and no credentials are needed.
How fast does Patreon Scraper run?
A recorded run returned 60 creators for two keywords in 9.5 seconds, with the first row after 2.7 seconds. Every run reads live data, not a cache.
What happens if a creator is private or doesn't exist?
You get one free row with the creator's name, success false and a message such as "Patreon has no public creator page under this name". For keywords, the next search result replaces it, so the count you asked for is still met when Patreon has enough creators. In code, keep rows where success is true. Creators who hide their member count or earnings still return a full row, with those values null.
Can I scrape multiple Patreon creators at once?
Yes. Put any number of keywords and creator links in one list; each keyword returns up to 500 creators and each link one row.
Does Patreon Scraper work with Claude, ChatGPT, and other AI agent tools?
Yes — Patreon Scraper is available as an MCP tool. Register it in Claude Code, Cursor or Windsurf with claude mcp add --transport http apify "https://mcp.apify.com?tools=fastdataapi/patreon-scraper". Any agent that can call an HTTP endpoint can use the REST API directly.
Does Patreon Scraper return data in a format LLMs can use directly?
Yes. Each creator is typed, normalized JSON with consistent field names, so there is no HTML parsing and no selectors. Pass it straight to an LLM, index it into a vector store, or feed it to an agent tool — no transformation step.
What happens when Patreon changes its layout or updates its anti-bot system?
The actor is maintained, and when Patreon changes, it is updated so your calls keep returning the same JSON fields with no changes on your end.
Can I use Patreon Scraper without managing proxies or browser infrastructure?
Yes. Retries, pauses and Apify proxies for refused requests run on the actor's side, and no browser is needed. You send one request and get structured JSON back, with no proxy accounts and no maintenance.
Which Patreon creator fields work best for AI training data and RAG indexing?
For RAG, use the about text, what the creator makes, and the tier names and descriptions. For training data and analytics, use the member count, paid member count, post count, tier prices and monthly earnings. All fields are plain strings, numbers, booleans and short lists, so no normalization is needed.
Your feedback
Found a bug or missing a field? Let us know in the actor's Issues tab. Every report is read, and fixes ship as new versions of the actor.


