
Google News Scraper & Monitor - $1 per 1,000 Articles
Pricing
from $0.80 / 1,000 news articles
Google News Scraper & Monitor - $1 per 1,000 Articles
Google News Scraper and news monitor: get headlines, publishers, publish dates, snippets and links for any keyword, country and language. Only-new mode returns just unseen articles for alerts. Date, phrase and publisher filters. $1 per 1,000 articles, no API key.
Pricing
from $0.80 / 1,000 news articles
Rating
0.0
(0)
Developer
Group Oject
Maintained by CommunityActor stats
1
Bookmarked
6
Total users
2
Monthly active users
2 days ago
Last modified
Share
Google News Scraper
Scrape Google News by keyword and get headlines, publishers, publish dates, snippets, and links as clean JSON, CSV, or Excel. Turn on only-new mode to get a news alert feed that bills you only for articles you have not seen yet. $1.00 per 1,000 articles. No Google API key, no login, no browser.
Google News has no public API. This Google News Scraper reads the public Google News search RSS feed for every query you give it, cleans the result into one row per article, removes duplicates across queries, and sorts everything newest-first. Use it as a Google News API for brand monitoring, competitor tracking, PR and crisis alerts, market research, and AI agent or RAG news feeds.
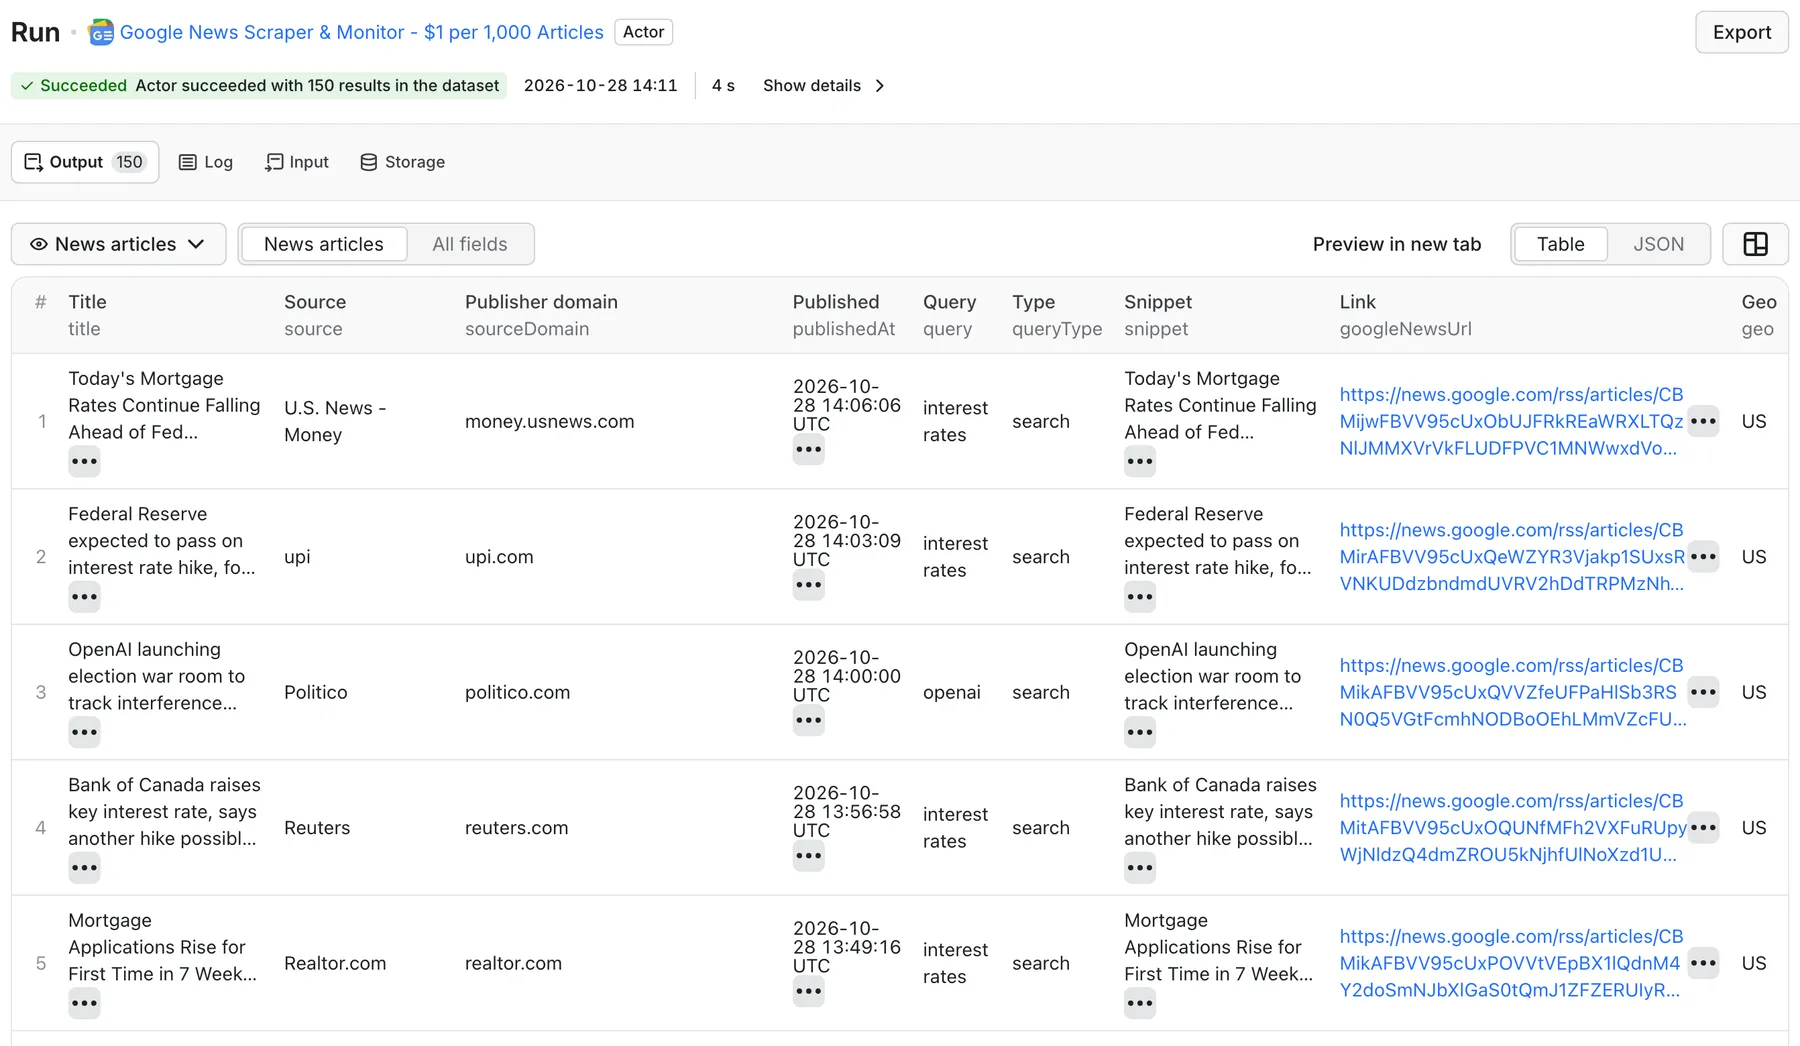
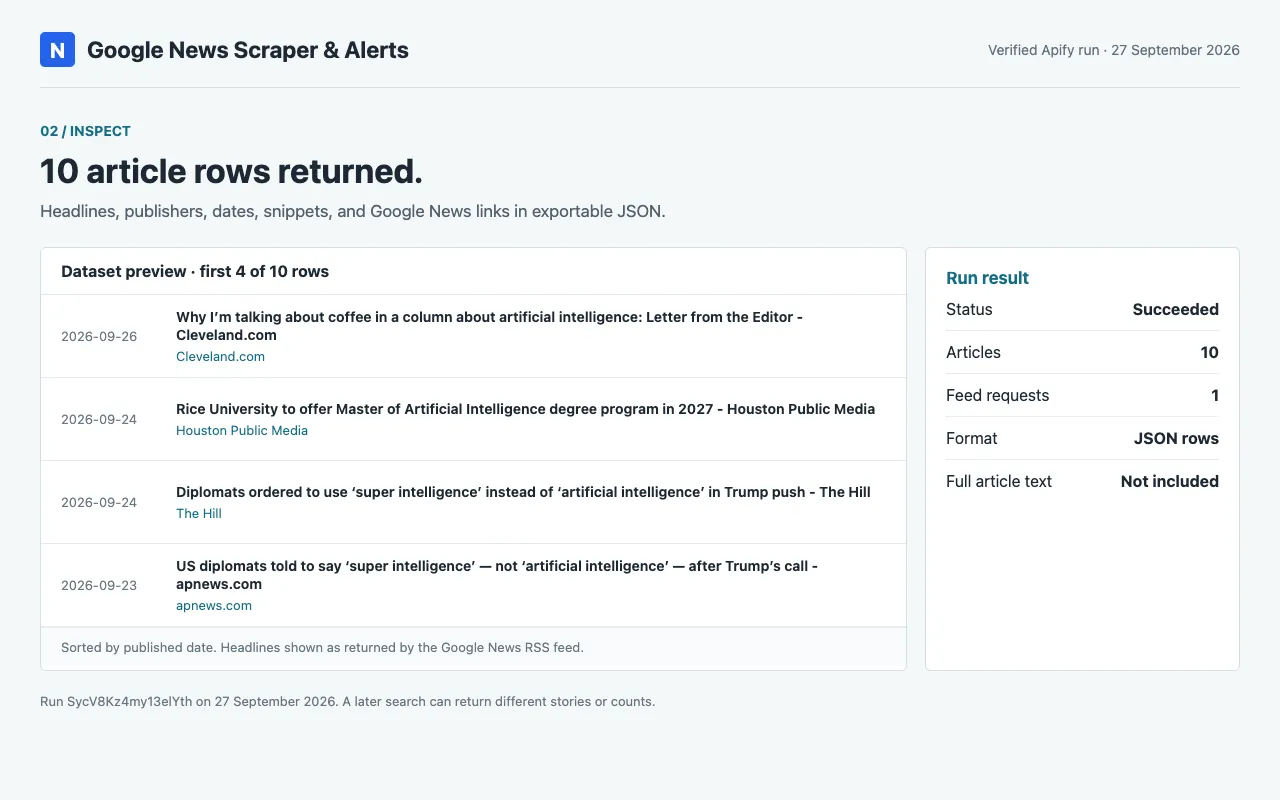
Real output from a default run of Google News Scraper in Apify Console.
What can this Google News Scraper do?
- Scrape Google News in bulk: run 1 to 1,000 search queries in one run, up to 100 articles per query.
- Monitor news and get only new articles: only-new mode remembers what it already returned and outputs only unseen articles on the next scheduled run.
- Filter by date: rolling window (
postedWithinDays, for example the last 1 or 7 days) or a fixeddateFrom/dateTorange. - Filter by publisher: keep only certain domains (
reuters.com,techcrunch.com) or exclude domains you never want. - Refine the query: require an exact phrase, exclude keywords, and use Google News operators such as
ORandsite:inside a query. - Localize results: choose the country (
geo) and language for any Google News edition, for exampleUS/en,GB/en,DE/de,FR/fr. - Optional headline analysis: add sentiment, a sentiment score, and entities extracted from each headline. Rule-based, no external AI API.
- Use it anywhere: Apify API, Python and JavaScript clients, n8n, Make, Zapier, webhooks, and MCP for AI agents.
What data can I extract from Google News?
| Field | Example | Description |
|---|---|---|
title | Advisory Group on Mathematics and Artificial Intelligence - OpenAI | Article headline |
source | OpenAI | Publisher name |
sourceDomain | openai.com | Publisher domain, normalized (good for grouping and filtering) |
sourceUrl | https://openai.com | Publisher homepage from the feed |
publishedAt | 2026-09-21T17:32:19.000Z | Publish time in ISO 8601 |
snippet | Advisory Group on Mathematics... | Short text from the feed |
googleNewsUrl | https://news.google.com/rss/articles/CBMi... | Google News link that opens the article |
guid | CBMi... | Stable article ID, use it as a deduplication key |
query / appliedQuery | artificial intelligence / artificial intelligence when:7d | Your query and the exact query sent to Google News |
position | 1 | Rank of the article in the feed |
geo / language | US / en | Edition used |
fetchedAt | 2026-09-27T16:39:03.077Z | When the row was collected |
sentiment, sentimentScore, entities | positive, numeric score, ["OpenAI"] | Only when enableAnalysis is on |
isNew | true | Only in only-new monitoring mode |
Each run also saves SUMMARY (counts, top publishers, top queries), HEADLINES_BY_SOURCE (headlines grouped by publisher), and ERRORS (any feed that failed) to the run's key-value store.
How much does it cost to scrape Google News?
You pay per article saved to the dataset. Platform usage is included.
| Apify plan | Price per 1,000 articles |
|---|---|
| Free | $1.00 |
| Bronze | $0.95 |
| Silver | $0.90 |
| Gold, Platinum, Diamond | $0.80 |
There is also a tiny start fee of $0.00005 per run per GB of memory.
Examples on the Free plan:
- One-off research: 20 queries x 50 articles = 1,000 articles = about $1.00.
- Daily brand monitor in only-new mode: you pay only for new articles. If 3 brand queries surface 40 new articles a day, that is about 1,200 articles a month = about $1.20 a month.
- Baseline run (
monitoringInitialRun: "baseline"): stores the current articles as "seen" and outputs nothing, so it costs only the start fee.
Set a maximum charge per run in the run options and the scraper stops before it goes over it. The Pricing tab always shows the current rates.
How to scrape Google News
- Click Try for free and open the input form.
- Add one or more Search queries, for example a brand, a competitor, a ticker, or a topic.
- Optional: set Published within (days), country, language, and publisher filters.
- Optional: turn on Only output new articles and give the monitor a stable Monitor key.
- Click Start. Download the results as JSON, CSV, Excel, or HTML, or read them through the API.
- For alerts, save the input as a task and add a Schedule (for example every hour or every morning).
Ready-made tasks: Brand News Monitoring, AI Industry News Feed, Competitor Launch Tracker.
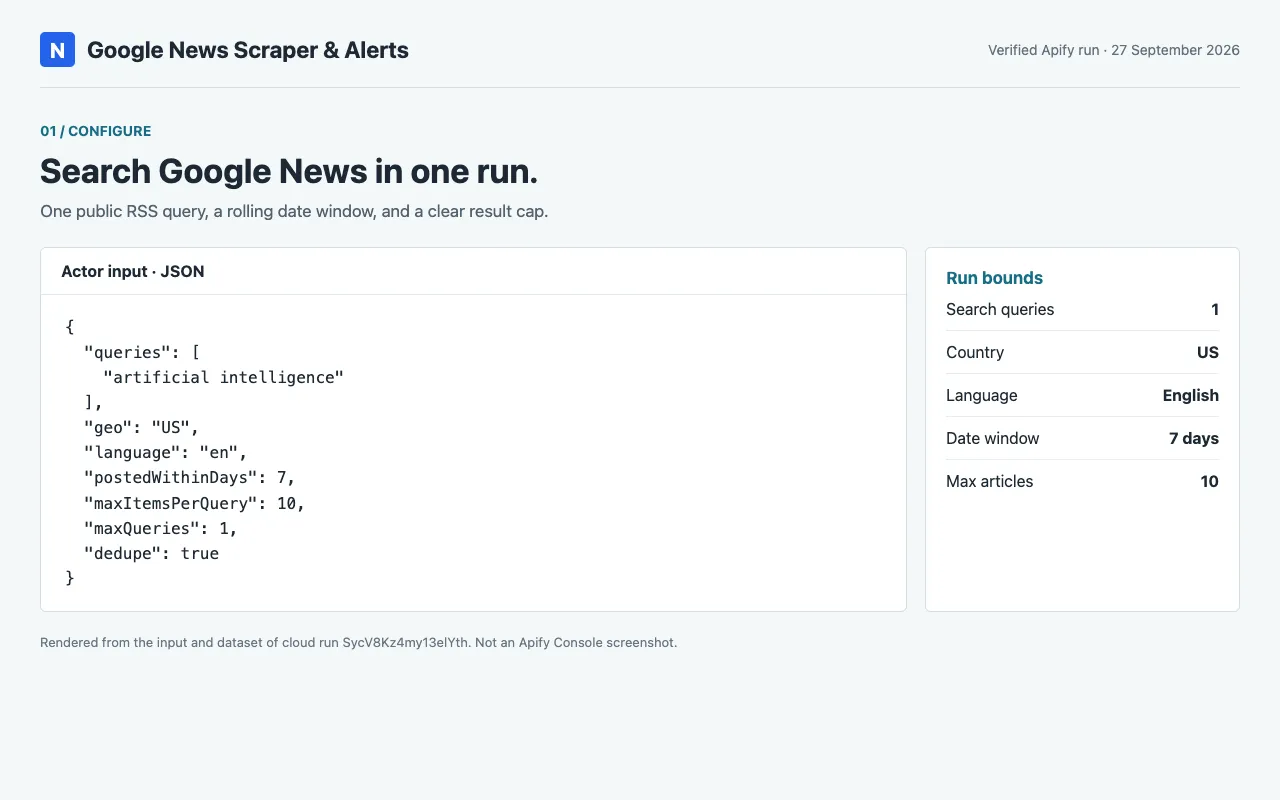
Input example
All input fields
| Field | Type | Default | What it does |
|---|---|---|---|
queries | string[] | - | Search terms. Google News operators (OR, site:, quotes) work. |
queriesText | string | - | Same, pasted one per line or comma-separated |
exactPhrase | string | "" | Phrase every result must contain (quotes added for you) |
excludeKeywords | string[] | [] | Words or phrases to exclude |
includeDomains | string[] | [] | Only keep these publisher domains |
excludeDomains | string[] | [] | Remove these publisher domains |
postedWithinDays | integer | - | Rolling window, 1 to 365 days |
dateFrom / dateTo | string | - | Fixed range, YYYY-MM-DD, inclusive. Use this or postedWithinDays, not both. |
geo | string | US | Country edition (gl) |
language | string | en | Language (hl), a two-letter code such as en, de, fr |
maxItemsPerQuery | integer | 50 | Articles per query, 1 to 100 |
maxQueries | integer | 100 | Maximum queries per run, up to 1,000 |
dedupe | boolean | true | Remove the same article returned by several queries |
enableAnalysis | boolean | false | Add headline sentiment, score, and entities |
monitoringMode | boolean | false | Only output articles not returned before |
monitorKey | string | default | Name of the monitor, one per independent alert |
monitoringInitialRun | string | emit | First run: emit current articles, or baseline to store them silently |
requestDelayMs | integer | 500 | Delay between feed requests |
maxConcurrency | integer | 3 | Parallel feed requests, 1 to 10 |
proxyConfiguration | object | - | Apify Proxy settings. Recommended for scheduled and large runs. |
Output example
This row comes from a real run on September 27, 2026 (long IDs shortened). Watch the 9-second input-to-output walkthrough.
Google News monitoring and alerts (only new articles)
Turn the scraper into a Google News alert feed:
- The first run stores the current articles (
baseline) or outputs them (emit). - Every later run with the same
monitorKey, queries, and filters outputs only articles it has not returned before, each markedisNew: true. - A run with nothing new correctly returns an empty dataset, and you are not charged for articles.
- The monitor remembers the latest 10,000 article IDs. Use a different
monitorKeyfor each independent alert, and do not run two copies of the same monitor at the same time.
Schedule the task, then send new rows to Slack, email, Google Sheets, or a webhook with an Apify integration, Make, Zapier, or n8n. The scraper produces the data; delivery is handled by the integration you choose.
Use the Google News API from code
HTTP (one call, returns the articles):
Python:
JavaScript:
No-code: use the Apify app in n8n, Make, or Zapier, or add a webhook to the saved task.
AI agents (MCP): the scraper is available as a tool through the Apify MCP server in Claude, ChatGPT, Cursor, and other MCP clients. Agents get compact JSON rows that are easy to summarize, filter, and cite.
FAQ
Is it legal to scrape Google News?
The scraper reads the public Google News RSS feed: headlines, publisher names, dates, short snippets, and links. It does not log in, does not bypass paywalls, and does not copy full articles. You are responsible for how you use the data, especially for republishing. If in doubt, ask a lawyer.
How many articles can I get per query?
Google News RSS returns up to about 100 articles per query. To collect more on one topic, split it into narrower queries (for example by company, product, or site:) or into several date ranges with dateFrom / dateTo.
Do I get the publisher's article URL?
You get googleNewsUrl, which opens the article through Google News, plus the publisher's name, homepage (sourceUrl), and domain (sourceDomain). The direct article URL on the publisher's site is not decoded.
Do I get the full article text?
No. You get the headline, snippet, publisher, date, and link. Pair the links with a web content crawler if you need full text.
Do I need a proxy?
Small runs work without one. For scheduled monitors and runs with many queries, enable Apify Proxy in the input to avoid Google rate limits.
Why is my dataset empty?
Check SUMMARY and ERRORS in the run's key-value store. In only-new mode, an empty dataset means nothing new was published. For a snapshot, try a broader query, a longer date window, or remove domain filters.
Can I scrape Google News in other countries and languages?
Yes. Set geo (for example GB, IN, DE, FR, BR, JP) and language (en, de, fr, pt, ja).
Related scrapers
- Bing News Scraper: Bing News headlines with direct publisher article URLs.
- Yahoo News Scraper + Google & Bing News Aggregator: Google, Bing, and Yahoo News in one dataset.
- Google Trends Keyword Monitor: see which topics are rising before they hit the news.
- Google AI Overview Tracker: track brand mentions in Google AI Overviews.
- Reddit Lead Finder & Sentiment Monitor: brand mentions on Reddit.
Questions or a feature request? Open an issue on the Issues tab.


