
Yahoo News Scraper + Google & Bing News Aggregator
Pricing
from $2.10 / 1,000 results
Yahoo News Scraper + Google & Bing News Aggregator
Yahoo News Scraper and news aggregator: search Yahoo News, Google News and Bing News by keyword in one run. One deduplicated dataset with headline, publisher, date, snippet, source engine and links. Pick any mix of sources. Bulk queries, JSON, CSV or Excel.
Pricing
from $2.10 / 1,000 results
Rating
0.0
(0)
Developer
Group Oject
Maintained by CommunityActor stats
2
Bookmarked
2
Total users
0
Monthly active users
21 hours ago
Last modified
Share
Scrape Yahoo News, Google News, and Bing News by keyword in one run and get one deduplicated dataset: headline, publisher, publish date, snippet, source engine, and links. Pick any mix of engines. No API key, no login, no browser.
Yahoo News has no public search API and most news scrapers cover Google only. This news aggregator searches up to three news engines for every query you give it, labels each row with the engine that found it, removes duplicates, and returns everything in one table you can export or call through the API.
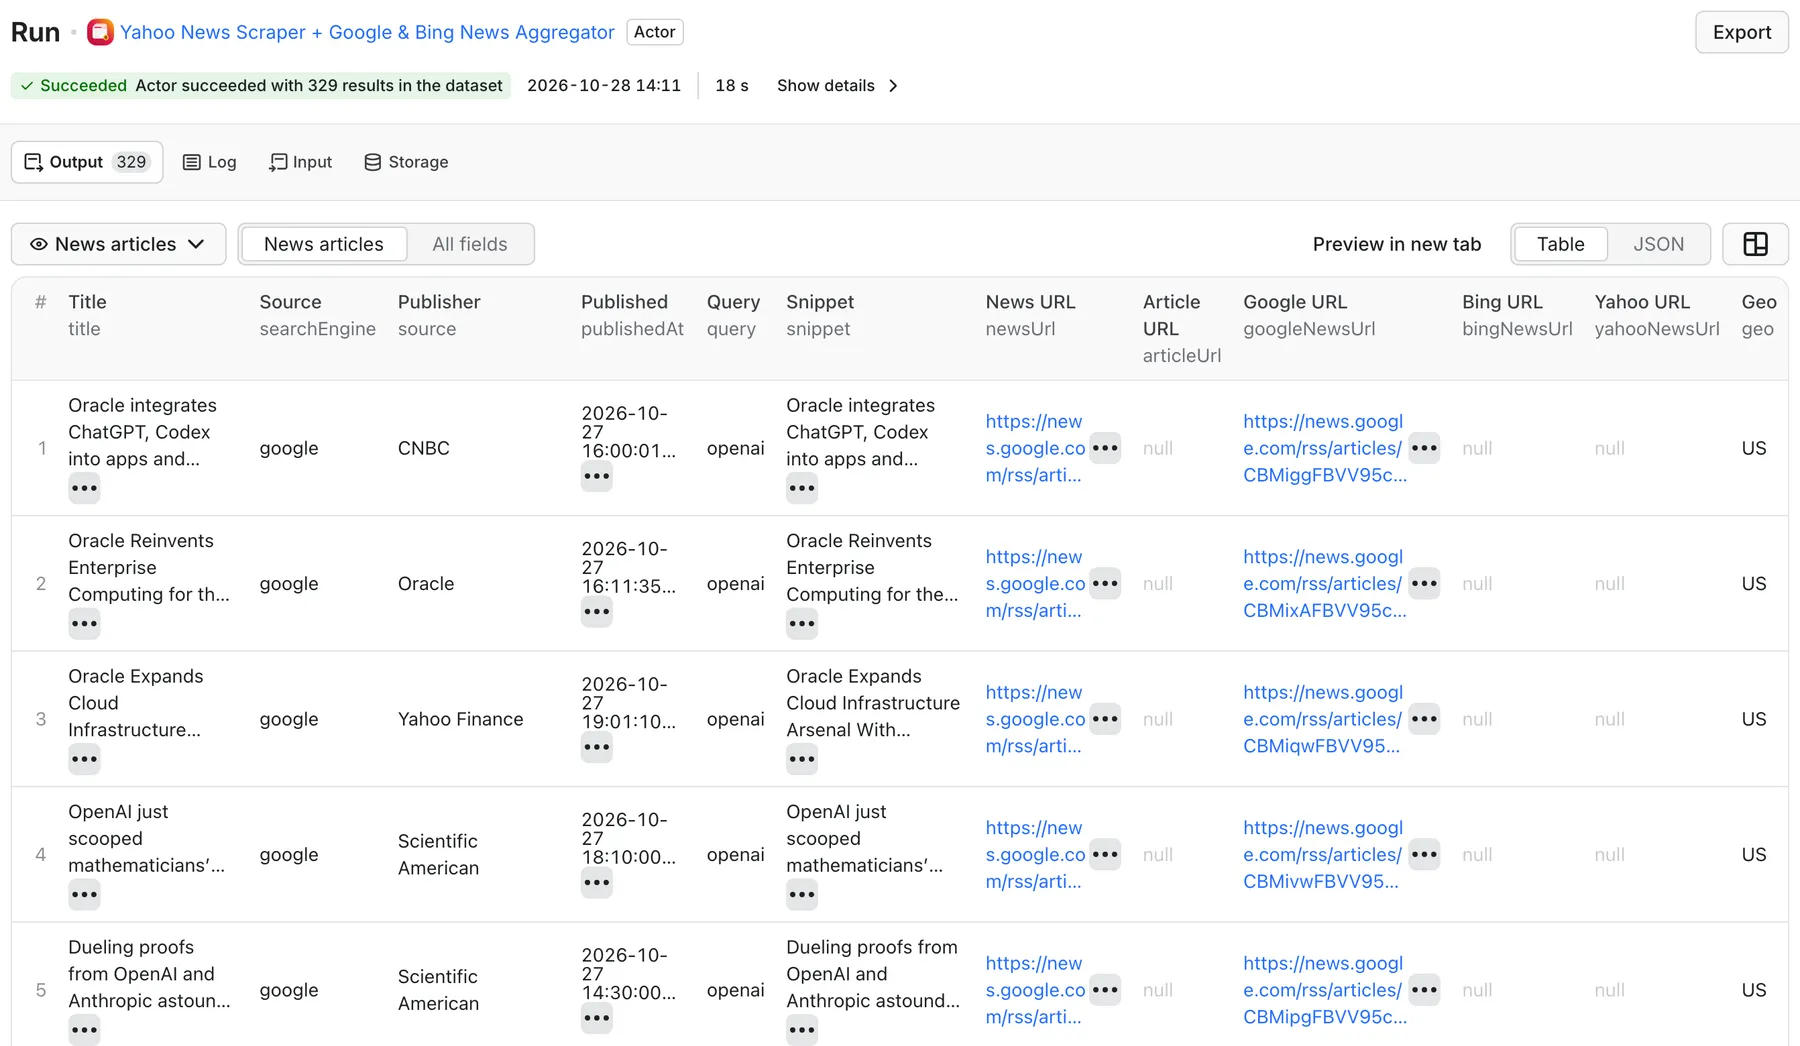
Real output from a default run of Yahoo News Scraper in Apify Console.
What can this news scraper do?
- Scrape Yahoo News search results by keyword.
- Add Google News and Bing News in the same run, or choose only the engines you need with
searchEngines. - Compare coverage: every row has
searchEngine, andSUMMARYcounts articles per engine, so you can see which engine surfaced which story. - Run many queries: 1 to 1,000 queries per run, up to 100 articles per query and engine.
- Remove duplicates: the same article found by several queries is kept once.
- Localize Google and Bing results with
geoandlanguage. - Export anywhere: JSON, CSV, Excel, the Apify API, n8n, Make, Zapier, webhooks, and MCP for AI agents.
Typical uses: brand and executive monitoring, competitor and funding news, crisis and reputation alerts, market and sector research, and feeding current news into dashboards, LLM pipelines, and RAG systems.
What data can I extract?
| Field | Example | Description |
|---|---|---|
searchEngine | yahoo | google, bing, or yahoo |
title | OpenAI funding round valuation cut... | Headline |
source | TNW | Publisher name |
publishedAt | 2026-10-25T09:00:00.000Z | Publish time in ISO 8601 |
snippet | The OpenAI funding round is an... | Summary text |
newsUrl | The news engine's link for this result | |
articleUrl | https://thenextweb.com/news/... | Direct publisher URL when the engine provides it (Bing, Yahoo); empty for Google News |
googleNewsUrl / bingNewsUrl / yahooNewsUrl | Engine-specific link, filled for the engine that found the row | |
query, position, geo, language, guid, fetchedAt | Query, rank, edition, ID, collection time |
Each run also saves SUMMARY (articles per engine, top publishers, top queries), HEADLINES_BY_SOURCE, and ERRORS to the run's key-value store.
How much does it cost?
$3.00 per 1,000 results ($0.003 per article saved to the dataset), plus a start fee of $0.00005 per run per GB of memory. Platform usage is included.
Example: 10 queries on all three engines that return 600 articles in total cost about $1.80.
If you need only one engine, the single-engine scrapers cost less: Google News Scraper and Bing News Scraper are $1.00 per 1,000 results. The Pricing tab always shows the current rate.
How to use it
- Click Try for free.
- Add your Search queries.
- Choose the News sources: Yahoo News, Google News, Bing News, or any combination.
- Optional: set
geo,language, andmaxItemsPerQuery. - Click Start, then download the dataset or read it through the API. Save the input as a task and add a Schedule for recurring monitoring.
Input example
| Field | Type | Default | What it does |
|---|---|---|---|
queries | string[] | - | Search terms |
queriesText | string | - | Same, pasted one per line or comma-separated |
searchEngines | string[] | ["google","bing","yahoo"] | Engines to search |
geo | string | US | Country for Google and Bing |
language | string | en | Language for Google and Bing |
maxItemsPerQuery | integer | 50 | Upper limit per query and engine (1 to 100) |
maxQueries | integer | 100 | Maximum queries per run, up to 1,000 |
dedupe | boolean | true | Remove duplicate articles |
requestDelayMs | integer | 500 | Delay between requests |
maxConcurrency | integer | 3 | Parallel requests, 1 to 10 |
proxyConfiguration | object | - | Apify Proxy settings, recommended for large or scheduled runs |
Output example
Use it from code
Or call https://api.apify.com/v2/acts/groupoject~multi-news-scraper/run-sync-get-dataset-items with your input as the JSON body. The Actor also works in n8n, Make, Zapier, and as a tool through the Apify MCP server.
FAQ
Can I scrape only Yahoo News?
Yes. Set "searchEngines": ["yahoo"].
Why do some rows have no articleUrl?
Google News only exposes its own redirect link, so Google rows have googleNewsUrl and no articleUrl. Bing and Yahoo rows include the publisher URL.
Are duplicates removed across engines?
Duplicates are removed by link. The same story found by Bing and Yahoo with the same publisher URL is kept once. Google rows use Google's redirect link, so the same story can appear once from Google and once from another engine, which is useful for coverage comparison.
Is this legal?
The scraper reads publicly available news search results: headlines, publishers, dates, snippets, and links. It does not log in, bypass paywalls, or copy full articles. You are responsible for how you use and republish the data.
Do I get the full article text?
No. Send articleUrl to a web content crawler if you need full text.
Why did one engine return nothing?
Check ERRORS and SUMMARY in the run's key-value store. One engine failing does not stop the others.
Related scrapers
- Google News Scraper & Monitor: Google News with date and publisher filters and only-new alerts.
- Bing News Scraper: Bing News with direct publisher URLs.
- Google Trends Keyword Monitor: rising topics before they hit the news.
Questions or a feature request? Open an issue on the Issues tab.


