
Reddit Scraper - No API Key, Posts, Comments & Search
Pricing
from $1.40 / 1,000 results
Reddit Scraper - No API Key, Posts, Comments & Search
Reddit scraper with no API key or login. Scrape posts and comments from subreddits, post URLs, user profiles and keyword search. Sort and time filters, date cutoff, NSFW filter, comment depth and parent ids. JSON, CSV, Excel.
Pricing
from $1.40 / 1,000 results
Rating
0.0
(0)
Developer
Group Oject
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
5 hours ago
Last modified
Categories
Share
Reddit Scraper extracts public Reddit posts and comments without an API key, a Reddit app or a login. Point it at subreddits, post links, user profiles or search keywords and get clean rows with scores, upvote ratios, comment counts, flair, media links and full comment threads.
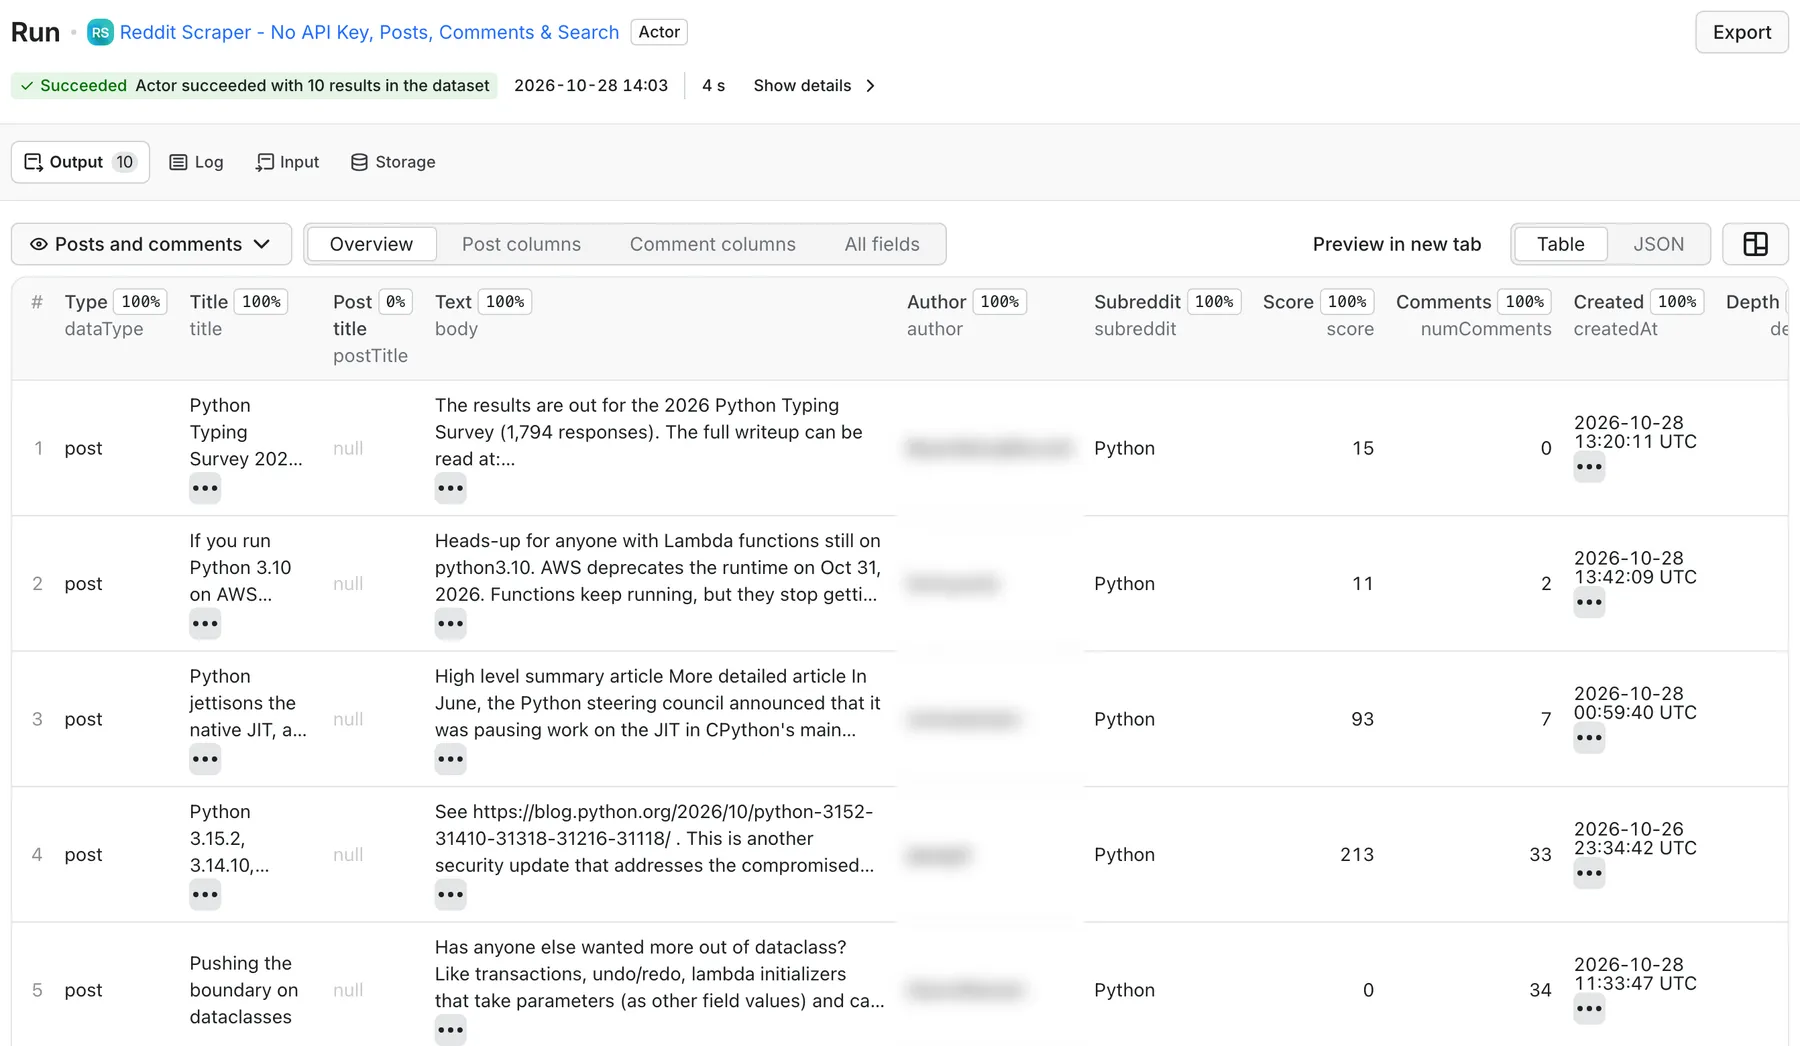
Real output from a default run of Reddit Scraper in Apify Console.
What can it do?
- Scrape subreddits: Hot, New, Top (hour to all time) or Rising posts from any public subreddit.
- Scrape single posts: a post link or a
redd.itshort link returns the post and, if you want, its comments. - Search Reddit: search all of Reddit or one subreddit by keyword, sorted by relevance, new, top, hot or most comments, with a time filter.
- Scrape user profiles: the posts a public user has submitted.
- Collect comments: every comment is its own row with
parentIdanddepth, so you can rebuild the thread. Set how many comments per post and how deep into replies. - Filter by date: keep only posts newer than a date or a period like
24 hours. With sort New, paging stops at the cutoff, so scheduled monitoring runs stay small. - Monitor for new posts only: turn on
onlyNewand schedule the Actor. Each run skips posts and comments that earlier runs already saved, so you get and pay for only what is new. - Keyword filter:
keywordsMustMatchkeeps only posts whose title or text mentions your brand, product or competitor. - Skip NSFW: posts marked 18+ are skipped unless you turn them on.
- No Reddit credentials: no client ID, no secret, no OAuth app, no cookies.
- Export anywhere: JSON, CSV, Excel, XML or HTML, or read the data through the API, webhooks and integrations.
What data do you get?
Posts and comments share one set of columns. dataType tells you which is which.
| Field | Posts | Comments | Description |
|---|---|---|---|
dataType | post | comment | Row type |
id, fullname | yes | yes | Reddit id (1abc234) and fullname (t3_1abc234, t1_...) |
url | yes | yes | Permalink on reddit.com |
title / postTitle | title | post title | Post title (on comments: the title of their post) |
body | yes | yes | Post text or comment text, plain text with paragraph breaks |
author, authorId | yes | author | Username and account id |
subreddit, subredditId | yes | yes | Subreddit name and id |
score | yes | yes | Net upvotes when scraped |
upvoteRatio | listings | - | Share of upvotes (0-1) |
numComments | yes | - | Comment count |
createdAt | yes | yes | ISO 8601 UTC timestamp |
flair | listings | - | Post flair text |
postType, domain, linkUrl | yes | - | text / link / image / gallery / video, link domain and outbound URL |
mediaUrls, thumbnailUrl | yes | - | Full-size images, gallery images, video playlist and embed URLs, preview image |
parentId, depth | - | yes | Parent fullname (t3_ = the post, t1_ = another comment) and reply level (0 = top level) |
isNsfw, isSpoiler, isStickied | yes | NSFW | Flags |
isSubmitter | - | yes | The commenter wrote the post (OP) |
searchQuery, sourceType, sourceUrl, scrapedAt | yes | yes | Where the row came from and when |
"Listings" means posts collected from subreddit and user pages. Reddit's search cards and single-post cards do not show the upvote ratio or flair, so those two fields are empty for posts found through search or a post link.
How much does it cost?
You pay per row saved: $1.00 per 1,000 results (posts and comments count the same, $0.001 each). There is no monthly fee and proxy costs are included.
- 500 posts from five subreddits, no comments: 500 rows = $0.50.
- 100 search results with up to 20 comments each (2,000 comments): 2,100 rows = $2.10.
Set "Max total rows" or a maximum charge per run in the run options and the scraper stops there.
How to use Reddit Scraper
- Open the Actor and add Reddit URLs (for example
https://www.reddit.com/r/Python/), search keywords, or both. - Pick the sort order and time filter. A sort inside a URL, such as
/top/?t=week, wins over the setting. - Set Max posts per source. Turn on Include comments if you want threads.
- Optional: set Only posts newer than (for example
7 days) and leave Include NSFW posts off. - Click Start. Rows appear in the Output tab as they are scraped. Download them or connect an integration.
Monitor Reddit for new posts
Use this for brand mentions, competitor tracking, product feedback or a market research feed.
- Add your sources: a subreddit's New page (
https://www.reddit.com/r/SaaS/new/), search keywords with Sort search results by = New, or both. - Turn on Only new posts and comments (
onlyNew: true) and give the monitor a name in Monitoring state key (stateKey, for exampleacme-mentions). Use a different key for each monitor. If you leave it empty, a key is derived from your URLs and search keywords. - Optional: add Keep only posts mentioning (
keywordsMustMatch) to drop posts that do not name your brand or competitors. Matching is case-insensitive and whole-word, on the title and post text. - Save the input as a task and add a schedule in Apify Console (Schedules, for example every hour or every morning).
- Send new rows where you need them: Slack or email through the task's Integrations tab, a webhook on run success, Google Sheets, Make, Zapier or n8n.
How it works: the first run saves everything it finds and remembers each post and comment id in a named key-value store (reddit-monitor-<stateKey>). Later runs skip those ids before they reach the dataset, so known items are never charged again. On a New listing the scraper stops paging at the first post it already knows. With Include comments on, a known post is re-opened only when Reddit shows more comments than last time, and only the comments you have not received are saved. To start over, use a new state key.
The run's SUMMARY record shows how many already-seen posts and comments were skipped (onlyNew.alreadySeenPostsSkipped). A run with nothing new finishes with zero rows and a "No new posts" status, which costs nothing per row.
Input example
Output example
A post row and one of its comments (values are illustrative):
Comment rows contain every column too; unused post fields are null. Each run also writes a SUMMARY record (counts per source, skipped posts, request statistics) and, if something failed, an ERRORS record to the key-value store.
Use with the API
cURL (run and get the rows in one call):
Python (pip install apify-client):
JavaScript (npm install apify-client):
Use with AI agents and MCP
Connect Claude, Cursor or any MCP client to the Apify MCP server with this Actor enabled:
Then ask, for example: "Use the Reddit scraper to get this week's top 30 posts in r/smallbusiness with their top 10 comments, and summarise the main complaints."
Integrations
Send results to Google Sheets, Make, Zapier, n8n, Slack, Airtable or your own endpoint with webhooks. Typical setup: schedule the Actor every hour with sort: "new" and onlyNew: true, then push each new row to a sheet or a chat channel. In n8n and Make, use the Apify app's "Run Actor" and "Get dataset items" steps.
FAQ
Do I need a Reddit API key or a Reddit account?
No. The scraper reads the same public pages your browser loads when you are logged out. You do not create a Reddit app, enter a client ID or secret, or log in.
Is it legal to scrape Reddit?
The scraper only collects publicly visible content and never logs in. Usernames and comment text can still be personal data, so make sure your use (for example research, monitoring or analytics) has a legal basis under laws such as GDPR, and respect Reddit's terms where they apply to you. If unsure, ask a lawyer.
How many posts and comments can I get?
Up to 10,000 posts per source and up to 2,000 comments per post. Reddit itself stops serving older items deep into a listing (in our tests about 1,000 posts per subreddit and sort), so for more history combine sorts and time filters, or several search keywords.
Why are my results empty?
The usual causes: the subreddit is private, banned or quarantined; every post was NSFW while "Include NSFW posts" was off; the "Only posts newer than" cutoff is stricter than the posts available; the search keyword has no matches for the chosen time filter; no post contained a "Keep only posts mentioning" word; or, with "Only new" on, nothing new appeared since the last run. The run's status message and the SUMMARY record say how many posts were skipped and why.
Do I need proxies?
No setup needed. The Actor uses Apify Proxy by default and retries blocked requests with a fresh IP. If Reddit blocks a request on every datacenter attempt, it retries that request through residential proxy (included in the price).
How fast is it?
In our tests: about 25 posts per second without comments, and about 14 rows per second with comments, because each thread needs extra requests. A 10-post run finishes in a few seconds.
Can I monitor a subreddit or keyword on a schedule?
Yes. Create a task with sort: "new" (or searchSort: "new" for keywords), turn on onlyNew and set a stateKey, then add a schedule in Apify Console. Each run returns only posts and comments that earlier runs have not saved, so you pay only for new rows. See Monitor Reddit for new posts. postedAfter (for example "1 hour") still works as a simple time cutoff if you prefer it.
Why do some posts have no upvote ratio or flair?
Reddit does not show those values on search result cards or single-post cards. Posts collected from subreddit and user listings include them.
Related actors
- Reddit Lead Finder - Buying Intent & Competitor Mentions: scores Reddit posts and comments for buying intent and brand mentions.
- YouTube Comments Scraper - No API Key: comments from YouTube videos and Shorts.
- X (Twitter) Account Monitor: new posts and profile changes from X accounts.
- Facebook Page Posts Monitor: public Facebook page posts without login.
- Trustpilot Reviews Scraper: customer reviews for any company on Trustpilot.


