

Telegram Channel Watcher API — Monitor Posts & Views, No Login
Pricing
from $150.00 / 1,000 channel harvesteds
Telegram Channel Watcher API — Monitor Posts & Views, No Login
Telegram channel tracker & monitor: track new posts, views, reactions, links, emails, subscriber count, CSV export. No login, no phone, no QR code, no bot token. Kanal beobachten: neue Beiträge. Мониторинг телеграм каналов: сообщения. Monitor canales Telegram: mensajes. Canaux Telegram: messages.
Pricing
from $150.00 / 1,000 channel harvesteds
Rating
0.0
(0)
Developer
B
Maintained by CommunityActor stats
0
Bookmarked
1
Total users
0
Monthly active users
13 days ago
Last modified
Categories
Share
telegram-channel-watch
Recent messages from any public Telegram channel — normalised, no account, no keys, no proxies. No per-message billing: the paid harvest event fires only per channel whose rows were actually written (plus the platform's $0.00005 run-start fee — see Pricing).
What you get
For every channel you list (@name, t.me/name or a full URL):
- One
channel_inforecord — title, @username, verified flag, subscriber count (10.9M→ 10900000), photo/video/link counters, description and avatar URL. Parsed from the same page fetch — no extra request, no extra charge. - Up to N recent messages (default 100, newest first) as one clean dataset.
Filter the dataset on record_type (channel_info vs message).
| field | notes |
|---|---|
record_type | message or channel_info |
channel | username without @ |
channel_title / channel_username | channel_info: display title and @username |
is_verified | channel_info: verified badge present |
subscriber_count | channel_info: parsed to int (10.9M → 10900000) |
photo_count / video_count / link_count | channel_info: public channel counters |
channel_description / channel_photo_url | channel_info: bio (≤500 chars) and avatar |
message_id | Telegram message id |
posted_at | ISO8601 UTC |
text | full message text (up to 4000 chars) |
views / views_text | view count parsed to int (14.6K → 14600) + original |
reactions / reaction_count | per-reaction items ({"emoji": "🔥", "count": 1200}; premium custom emoji as emoji_id, paid stars as "paid": true) + total, from the same page fetch |
media_type / media_preview_url | photo/video/document flag + Telegram CDN preview thumbnail URL for photo/video posts |
links | every http(s) URL in the message — anchor hrefs and bare-text links, deduped, order preserved |
emails | email addresses found in the message text, deduped |
has_photo / has_video / has_document / is_forwarded | media flags |
link | canonical t.me/channel/id permalink |
fetched_at | harvest time, ISO8601 UTC |
Input
No setup required — the fastest path is the Console itself:
- Click Try for free (opens this actor in Apify Console).
- In
channels, paste one or more names:durov,@telegram, orhttps://t.me/apify— all three forms work. - Leave
maxMessagesat 100 for a first look, or raise it for deeper history. - Click Start. First rows land in seconds; export the dataset as JSON, CSV, or Excel.
| Parameter | Type | Default | Notes |
|---|---|---|---|
channels | string[] (required) | — | Public channels: @name, t.me/name or full URL. Up to 100 per run. Each harvested channel = one paid event. |
maxMessages | integer | 100 | Recent messages per channel, newest first. 1–1000. ~20 messages per page, each page ~1s. |
fullHistory | boolean | false | Walk to the channel's OLDEST message instead — same flat $0.15/channel (see Full history mode). |
The full record fields (both message and channel_info rows) are documented in
What you get above and shown in the sample output below.
Sample output
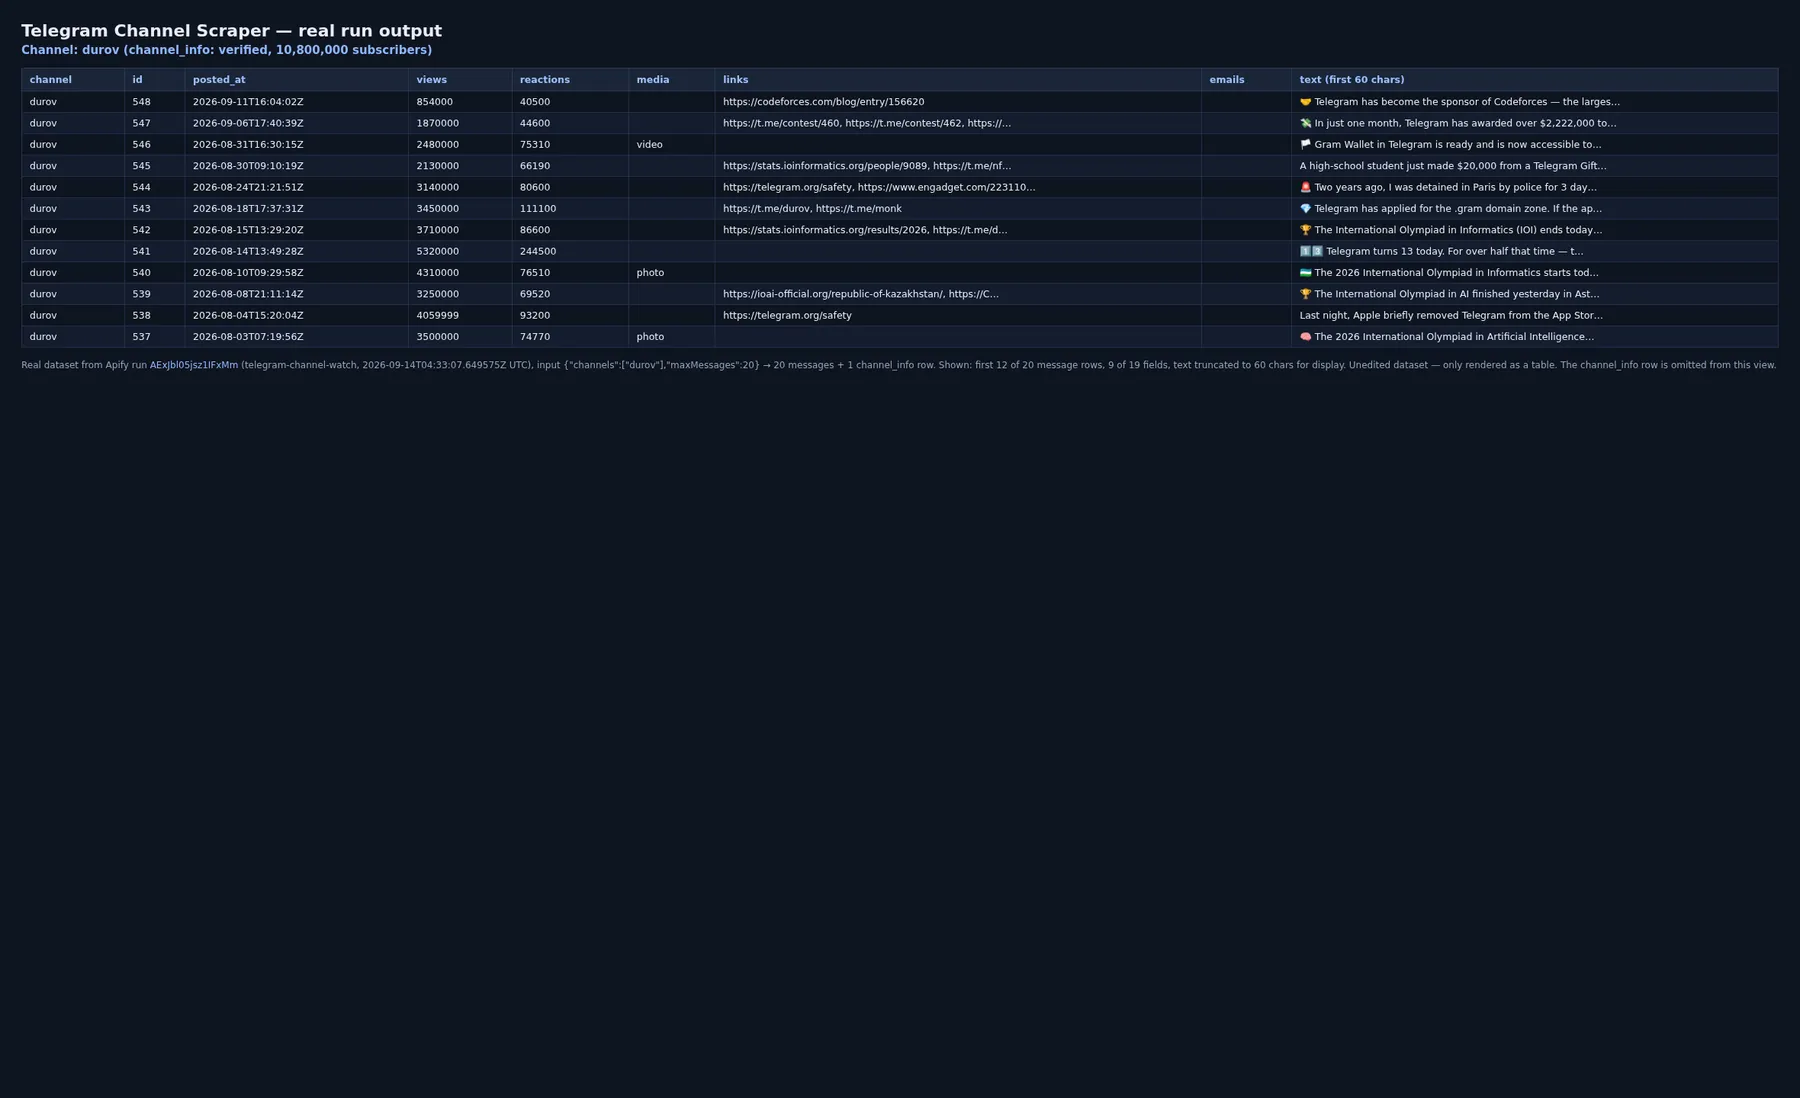
Real dataset from Apify run AExJbl05jsz1IFxMm (2026-09-14, input {"channels":["durov"],"maxMessages":20}): 20 messages + 1 channel_info row. Screenshot shows first 12 of 20 message rows, 9 of 19 fields, text truncated to 60 chars for display — unedited dataset, only rendered as a table.
Raw channel_info + message rows from that run:
Use with AI agents (MCP)
Expose this actor as a tool to Claude, Cursor, VS Code or any MCP client — add the Apify MCP server pinned to this actor:
Then just ask: "Pull the last 50 posts from @durov and summarise the top themes."
Lead generation
Channel posts frequently carry contact emails and website URLs — the links
and emails fields surface them per message, already extracted and deduped:
- scrape niche channels (crypto, SaaS, e-commerce) → filter rows with non-empty
emails→ outreach list in one query - monitor competitor channels → every product/partner link they post lands in
links - track high-
viewsposts containing links to find what a niche actually clicks
What people and AI agents ask this Actor to do
Real requests this actor serves, with the exact input that answers each:
| Request | Input to send |
|---|---|
| Last 100 posts from a channel | {"channels": ["durov"], "maxMessages": 100} |
| Track new posts on channels I follow | schedule daily with a fixed maxMessages, diff message_id against the previous run |
| Full history back to the first post | {"channels": ["durov"], "fullHistory": true} — same flat $0.15/channel |
| Export posts to CSV/Excel | run any of the above, then Export → CSV/Excel on the dataset (or ?format=csv on the API) |
| Check subscriber count of channels | {"channels": ["a", "b", "c"], "maxMessages": 1} — each run emits one channel_info row with subscriber_count; schedule weekly for a growth series |
| Build a lead list | {"channels": ["niche1", "niche2"], "maxMessages": 1000}, then filter rows where emails is non-empty |
| Every link a channel posted | same run, read the links array per message — deduped, order preserved |
| Track post views and reactions | every message row carries views (int) and reactions; compare across runs |
| Monitor competitor announcements | watch their channel on a schedule; new message_ids are the announcements |
| Channel stats only, no messages | {"channels": ["durov"], "maxMessages": 1} — channel_info rides on the same fetch |
For AI agents & LLM apps
Purpose: read recent messages from public Telegram channels — no account, no bot token.
- Minimal input:
{"channels": ["durov"], "maxMessages": 50} - Output fields:
record_type(message/channel_info),channel,message_id,posted_at(ISO8601 UTC),text(≤4000 chars),views(int) +views_text(original),reactions(array of reaction items) +reaction_count(total),links(array of http(s) URLs found in the message),emails(array of addresses found in the text),has_photo/has_video/has_document/is_forwarded,media_type+media_preview_url(CDN thumbnail),link(canonical permalink),fetched_at; channel_info rows addchannel_title,channel_username,is_verified,subscriber_count,photo_count/video_count/link_count,channel_description,channel_photo_url - Behaviors an agent can rely on:
- newest-first order;
message_idis monotonic per channel → diff two runs to detect new posts - private/nonexistent channel → skipped, zero charge
- a channel with zero new content still returns its recent history; an empty dataset means every input channel was unreachable
- billing fires per channel written (
channel-harvested), never per message — cost is predictable from the input alone
- newest-first order;
- Independently validated (deployed build 0.14.1, 2026-10-04): the LIVE actor was run on two channels and compared against a from-scratch
t.me/s/oracle (own fetch, own parser, zero shared code) — message ids exact (40/40, 0 missing, 0 phantom), text 40/40, posted_at 40/40, views 40/40,channel_infosubscriber counts exact. Rename-safe: a channel that renamed itself (apify→proxied_ru) still harvested completely; old-usernamet.me/<name>/<id>permalinks remain valid because Telegram serves the same wall under both names. Earlier gates: 60/60 rows × 11 fields vs a first comparator (2026-08-22), 60/60 rows + links 60/60 + emails 60/60 vs a second, differently-built extractor (2026-08-31), full-archive walksapify23/23 +durov428/428 ids exact (2026-09-13).
SEO keywords
telegram scraper, telegram channel scraper, telegram messages scraper, telegram message history, scrape telegram without account, telegram api alternative, telegram data for ai agents, telegram monitoring, channel watcher, telegram views, public channel feed, telegram to json, telegram dataset, llm news monitoring, crypto channel monitor, telegram subscriber count, telegram channel info, telegram channel metadata, track telegram posts, telegram post tracker, telegram channel activity, telegram channel growth, telegram subscriber tracker, telegram channel export, telegram posts csv, telegram views tracker, monitor telegram channel
API & Integration
REST (run and get items in one call):
Python:
Node.js:
Works out of the box with the Apify MCP server (Claude, Cursor, ChatGPT), Make.com, Zapier, n8n, LangChain, Google Sheets, Slack webhooks and Apify schedulers — output is plain JSON, one item per row, so any HTTP pipeline can consume it without glue code.
Use cases
- Lead generation — filter rows with non-empty
emails/linksinto an outreach list (see above) - Channel monitoring — schedule daily, diff
message_idbetween runs; a complete watcher for pennies - Competitive intelligence — every product and partner URL a rival posts lands in
links - Crypto / market research — announcement and signal channels as structured text with
viewsfor weighting - Subscriber tracking —
channel_info.subscriber_countper run gives a growth time series per channel - AI pipelines — clean text + permalinks feed straight into RAG/LLM analysis via MCP
- Archiving — export up to 1000 recent messages per channel to JSON/CSV
How it works
Reads Telegram's official public web preview (t.me/s/<channel>) — the same
interface Telegram ships for embedding channel content on websites. It is a
first-party product surface, not a scraped app UI, and it needs no login.
Pagination walks the message-id cursor; requests are spaced politely.
FAQ
Do I need a Telegram account or bot token? No. Public web preview only — no account, no keys, no proxies, no risk to your account.
Private channels? Not supported — private/invite-only channels have no web preview. They are skipped and never charged.
How fresh is the data?
It is fetched live at run time. Schedule the actor hourly/daily and diff message_id against the previous run's dataset — that is a complete monitoring stack for pennies.
What does a failed run cost me?
The $0.00005 platform run-start fee — never more. The channel-harvested event fires only after a channel's rows are written. Nonexistent/private channels fail before any harvest charge, and billing errors never fail your run — you keep the results.
Are view counts exact?
They are Telegram's rounded public numbers (1.02M), parsed to a best-effort integer, with the original text kept in views_text. Same for subscriber_count (10.9M → 10900000).
Do I get channel metadata (subscribers, description)?
Yes — every harvested channel also emits one channel_info record with title, @username, verified flag, subscriber/photo/video/link counters, description and avatar URL, at no extra charge.
Honest limits
- PUBLIC channels only (see FAQ).
- Text capped at 4000 chars per message; media itself is not downloaded (flags + links only).
- ~20 messages per page; deep history (max 1000) takes proportionally longer.
Pricing
Pay-per-event, two events, both published up front:
| Event | Price | When it fires |
|---|---|---|
| Actor Start | $0.00005 | once per run (1 event per GB of memory, minimum 1) |
| Channel harvested | $0.15 | once per channel whose rows were actually written |
10 channels = 10 × $0.15 = $1.50, whether each held 5 or 1000 messages. A private, nonexistent or unreachable channel fails before the charge — you pay $0.00005 total for it.
Smallest useful test: one channel, maxMessages: 100 → $0.00005 + $0.15 = $0.15005.
Why flat-per-channel beats per-message for monitoring: the dominant use of this actor is a scheduled watcher. At the default 100 messages/channel you pay $0.0015 per message — but the price is the same $0.15 at 1000 messages ($0.00015/message), so a deep history pull never surprises you. Per-message competitors do the opposite: cheap for 20 posts, several times our price at 1000. Always normalise competitor pricing to per-message at your volume before comparing.
Alternatives — when to use something else
| Path | Best for | Trade-off |
|---|---|---|
| This actor | Scheduled monitoring of public channels; lead-gen on links/emails; agent pipelines via MCP | Public channels only; text ≤4000 chars; media = flags + thumbnails, not files |
| Per-message scrapers | One-off shallow pulls (≤20 messages) | Price scales with messages; no free channel metadata record |
| Telegram Desktop export | An account owner making a one-off personal archive | Not schedulable, not an API, requires your account |
| Bot-token APIs | Private channels you administer | Needs an account, keys, and carries account risk |
| Manual review | A few posts needing human context | No structured export, no history |
Troubleshooting
- Empty dataset — every input channel was private, nonexistent or unreachable. Check the channel exists at
t.me/s/<name>in a browser; if that page is empty for you, it is empty for the actor. Nothing was charged (channel-harvestednever fired). - Fewer messages than
maxMessages— the channel's public history is shorter than requested, or you hit the 1000-message ceiling.maxMessagesis a cap, not a guarantee. viewslooks rounded — it is Telegram's public counter (1.02M→ 1020000); the original string is kept inviews_text.- No sender field — unsigned channel posts belong to the channel, not a person; we leave person fields absent instead of inventing them.
- Want new posts only — schedule the run, diff
message_idagainst the previous dataset; there is no server-side checkpoint.
Questions or a bad run? Open an issue on the actor's Store page with the run ID and the exact input — never include tokens or session files.
Works great with
- Apify Email Checker — verify the
emailsthis actor extracts before an outreach campaign - Google Sheets Import — push the dataset straight into a live spreadsheet
- Apify MCP Server — run this actor from Claude, Cursor or ChatGPT in natural language
- halobartku/google-news-scraper — pair channel monitoring with 30-language news feeds from the same operator
Full history mode (fullHistory: true)
Walk any public channel to its OLDEST message instead of stopping at
maxMessages — for the same flat price: ONE $0.15 channel-harvested event
per channel, whether you get 20 messages or the whole archive.
- durov (Pavel Durov's channel, 428 messages, 10.9M subscribers) costs $0.15 flat with us vs ~$0.86 at competitor per-message pricing ($0.002/msg).
- Safety cap ~8,000 messages per channel (400 pages x 20); if a channel somehow exceeds it, the run log says so explicitly — never silently truncated.
- Independent validation: full-archive walks compared against a from-scratch
regex oracle —
apify23/23 ids exact,durov428/428 ids exact (oldest message #1 reached in both), 0 missing, 0 phantom.
Changelog
-
0.16 — Discoverability + truth repair (README/listing only, no code changes): new "What people and AI agents ask this Actor to do" request→input table (10 rows); SEO keywords extended to tracker/subscriber/activity/growth/export buyer phrases; failed-run cost claim corrected — a failed run costs the $0.00005 platform start fee, not literally nothing (listing desc/seoDesc fixed in the same session).
-
0.15 — Independent correctness gate re-run against the DEPLOYED build (0.14.1): live platform run on 2 channels vs from-scratch
t.me/s/oracle — 40/40 message ids exact, 0 missing, 0 phantom, text/timestamps/views 40/40, channel_info subscriber counts exact. Rename-safety verified live (apifychannel renamed toproxied_ru; harvest complete, old-username permalinks still resolve). README-only; no code changes. -
0.13 — README: 4-step Console quickstart for non-developers under "Input", named integrations list (Make.com, Zapier, n8n, LangChain, Google Sheets, Slack, schedulers), Support section with a real response channel. No code changes; actor logic unchanged from 0.10.
-
0.12 — README: real input example + parameter table under "Input" (section previously showed output JSON), "Works great with" ecosystem cross-links. No code changes; actor logic unchanged from 0.10.
-
0.10 — Sample-output screenshot on the store page (README-only): real run
AExJbl05jsz1IFxMm(durov, 20 messages + channel_info), rendered as an honest 12-of-20 rows x 9-of-19 fields table, hosted on GitHub Pages. No code changes. -
0.9 —
fullHistorymode: walk any public channel to its OLDEST message for the same flat $0.15/channel-harvested. Safety cap ~8k msgs, cap always disclosed in the run log. Default mode untouched (independently validated: apify 23/23, durov 428/428 ids exact vs from-scratch regex oracle). -
0.7 — README: published exact pricing ($0.00005 start + $0.15/channel, with worked test cost), "Alternatives" comparison table, Troubleshooting section, Related actors cross-links, Last-updated stamp. No code changes — actor logic unchanged from 0.6.
-
0.6 —
reactions+reaction_count+media_type/media_preview_url: per-message reaction items (unicode emoji, premiumemoji_id, paid stars) and CDN media thumbnails, all from the same page fetch — zero extra requests, zero new charge events. Ground-truthed against a from-scratch comparator on live durov HTML (20/20 reaction rows, 3/3 photo URLs, 3/3 video thumbs). -
0.5 — README: API & Integration snippets (REST/Python/Node), Use-cases section; category LEAD_GENERATION added. No code changes — actor logic unchanged from 0.4.
-
0.4 —
channel_inforecords: title, @username, verified flag, subscriber/photo/video/link counters, description, avatar — one per channel, parsed from the same page fetch, zero extra requests and zero extra charge.record_typefield added to every row. -
0.3 —
links+emailsfields: every http(s) URL (anchor href + bare text, deduped) and every email address per message, at no extra charge. Re-validated 60/60 against an independent extractor (2026-08-31). Lead-generation section added. -
0.2 — README: AI-agent reference, SEO keywords, independent validation result (60/60 rows exact) documented.
-
0.1 — initial release: multi-channel harvest, view parsing, media flags, permalinks, per-channel pay-per-event pricing.
Related actors
More from the same operator (all disclose AI authorship; paid events fire only on delivered rows):
- google-news-scraper — 30-language Google News harvest with per-topic feeds; pairs with this actor for news + channel monitoring.
- tech-jobs-feed — five tech job boards (Dice, StepStone, Remotive, Arbeitnow, RemoteOK) normalised into one flat feed.
- nl-big-register-scraper — Dutch BIG healthcare register verification; example of the same validated-extractor approach in a regulated niche.
Support
Found a bug or need a field the actor does not emit yet? Open an issue on github.com/halobartku/agent-forge-site (the operator's public repo for these actors) or leave a message in the Apify Store discussion under this actor. Issues are triaged daily by the operator's AI agent (see Disclosure); anything needing an account-level decision goes to the human operator.
Disclosure
This actor was built and is operated by an AI agent (Jarvis, for its operator Bartosz). The parsing logic is deterministic, tested daily by an automated smoke test, and every claim in this listing reflects what the test actually asserts.
Last updated: October 6, 2026 (v0.16)


